P.S. JPTestKingがGoogle Driveで共有している無料かつ新しいProfessional-Machine-Learning-Engineerダンプ:https://drive.google.com/open?id=1j3SY6vYUycphUn54lvAYmPBI3iZpSo6n
明日ではなく、今日が大事と良く知られるから、そんなにぐずぐずしないで早く我々社のGoogle Professional-Machine-Learning-Engineer日本語対策問題集を勉強し、自身を充実させます。我々社の練習問題は長年でProfessional-Machine-Learning-Engineer全真模擬試験トレーニング資料に研究している専業化チームによって編集されます。Google Professional-Machine-Learning-Engineer資格問題集はPDF版、ソフト版、オンライン版を含まれ、この三つバージョンから自分の愛用することを選んでいます。他の人に先立ってGoogle Professional-Machine-Learning-Engineer認定資格を得るために、今から勉強しましょう。
| Section | Objectives |
|---|---|
| Topic 1: Scaling prototypes into ML models | - Hyperparameter tuning - Frameworks (TensorFlow, PyTorch, JAX, Scikit-learn) - Training at scale (Distributed training, TPUs) |
| Topic 2: Automating and orchestrating ML pipelines | - CI/CD for ML systems - Triggering and scheduling pipelines - Vertex AI Pipelines (Kubeflow Pipelines) |
| Topic 3: Collaborating within and across teams to manage data and models | - Collaboration between Data Scientists, Data Engineers, and ML Engineers - Data management and governance - Version control and reproducibility (e.g., DVC, MLOps) |
| Topic 4: Serving and scaling models | - Online prediction (Vertex AI Prediction) - Hardware accelerators (GPU/TPU) in serving - Model optimization (Quantization, Distillation) - Batch prediction |
| Topic 5: Architecting low-code ML solutions | - AutoML capabilities and implementation - Leveraging pre-built ML models as a service (e.g., Vision AI, Speech-to-Text, Recommendations AI) - Implementing BigQuery ML for basic models |
| Topic 6: Monitoring ML solutions | - Logging and alerting (Cloud Monitoring) - Performance monitoring and drift detection - Model retraining strategies |
>> Professional-Machine-Learning-Engineer試験問題解説集 <<
Professional-Machine-Learning-Engineer模擬試験を購入すると、当社のウェブサイトはプロの技術を使用してすべてのユーザーのプライバシーを暗号化し、ハッカーの盗用を防ぎます。私たちは、ビジネスがお客様のために十分に考慮された場合にのみ継続できると考えているため、当社の評判を損なうような行為は一切行いません。 Professional-Machine-Learning-Engineer試験問題に完全な信頼を寄せていただければ幸いです。失望することはありません。
質問 # 112
You are deploying a new version of a model to a production Vertex Al endpoint that is serving traffic You plan to direct all user traffic to the new model You need to deploy the model with minimal disruption to your application What should you do?
正解:C
解説:
The best option for deploying a new version of a model to a production Vertex AI endpoint that is serving traffic, directing all user traffic to the new model, and deploying the model with minimal disruption to your application, is to create a new model, set the parentModel parameter to the model ID of the currently deployed model, upload the model to Vertex AI Model Registry, deploy the new model to the existing endpoint, and set the new model to 100% of the traffic. This option allows you to leverage the power and simplicity of Vertex AI to update your model version and serve online predictions with low latency. Vertex AI is a unified platform for building and deploying machine learning solutions on Google Cloud. Vertex AI can deploy a trained model to an online prediction endpoint, which can provide low-latency predictions for individual instances. A model is a resource that represents a machine learning model that you can use for prediction. A model can have one or more versions, which are different implementations of the same model. A model version can have different parameters, code, or data than another version of the same model. A model version can help you experiment and iterate on your model, and improve the model performance and accuracy. A parentModel parameter is a parameter that specifies the model ID of the model that the new model version is based on. A parentModel parameter can help you inherit the settings and metadata of the existing model, and avoid duplicating the model configuration. Vertex AI Model Registry is a service that can store and manage your machine learning models on Google Cloud. Vertex AI Model Registry can help you upload and organize your models, and track the model versions and metadata. An endpoint is a resource that provides the service endpoint (URL) you use to request the prediction. An endpoint can have one or more deployed models, which are instances of model versions that are associated with physical resources. A deployed model can help you serve online predictions with low latency, and scale up or down based on the traffic. By creating a new model, setting the parentModel parameter to the model ID of the currently deployed model, uploading the model to Vertex AI Model Registry, deploying the new model to the existing endpoint, and setting the new model to 100% of the traffic, you can deploy a new version of a model to a production Vertex AI endpoint that is serving traffic, direct all user traffic to the new model, and deploy the model with minimal disruption to your application1.
The other options are not as good as option C, for the following reasons:
Option A: Creating a new endpoint, creating a new model, setting it as the default version, uploading the model to Vertex AI Model Registry, deploying the new model to the new endpoint, and updating Cloud DNS to point to the new endpoint would require more skills and steps than creating a new model, setting the parentModel parameter to the model ID of the currently deployed model, uploading the model to Vertex AI Model Registry, deploying the new model to the existing endpoint, and setting the new model to 100% of the traffic. Cloud DNS is a service that can provide reliable and scalable Domain Name System (DNS) services on Google Cloud. Cloud DNS can help you manage your DNS records, and resolve domain names to IP addresses. By updating Cloud DNS to point to the new endpoint, you can redirect the user traffic to the new endpoint, and avoid breaking the existing application. However, creating a new endpoint, creating a new model, setting it as the default version, uploading the model to Vertex AI Model Registry, deploying the new model to the new endpoint, and updating Cloud DNS to point to the new endpoint would require more skills and steps than creating a new model, setting the parentModel parameter to the model ID of the currently deployed model, uploading the model to Vertex AI Model Registry, deploying the new model to the existing endpoint, and setting the new model to 100% of the traffic. You would need to write code, create and configure the new endpoint, create and configure the new model, upload the model to Vertex AI Model Registry, deploy the model to the new endpoint, and update Cloud DNS to point to the new endpoint. Moreover, this option would create a new endpoint, which can increase the maintenance and management costs2.
Option B: Creating a new endpoint, creating a new model, setting the parentModel parameter to the model ID of the currently deployed model and setting it as the default version, uploading the model to Vertex AI Model Registry, and deploying the new model to the new endpoint and setting the new model to 100% of the traffic would require more skills and steps than creating a new model, setting the parentModel parameter to the model ID of the currently deployed model, uploading the model to Vertex AI Model Registry, deploying the new model to the existing endpoint, and setting the new model to 100% of the traffic. A parentModel parameter is a parameter that specifies the model ID of the model that the new model version is based on. A parentModel parameter can help you inherit the settings and metadata of the existing model, and avoid duplicating the model configuration. A default version is a model version that is used for prediction when no other version is specified. A default version can help you simplify the prediction request, and avoid specifying the model version every time. By setting the parentModel parameter to the model ID of the currently deployed model and setting it as the default version, you can create a new model that is based on the existing model, and use it for prediction without specifying the model version. However, creating a new endpoint, creating a new model, setting the parentModel parameter to the model ID of the currently deployed model and setting it as the default version, uploading the model to Vertex AI Model Registry, and deploying the new model to the new endpoint and setting the new model to 100% of the traffic would require more skills and steps than creating a new model, setting the parentModel parameter to the model ID of the currently deployed model, uploading the model to Vertex AI Model Registry, deploying the new model to the existing endpoint, and setting the new model to 100% of the traffic. You would need to write code, create and configure the new endpoint, create and configure the new model, upload the model to Vertex AI Model Registry, and deploy the model to the new endpoint. Moreover, this option would create a new endpoint, which can increase the maintenance and management costs2.
Option D: Creating a new model, setting it as the default version, uploading the model to Vertex AI Model Registry, and deploying the new model to the existing endpoint would not allow you to inherit the settings and metadata of the existing model, and could cause errors or poor performance. A default version is a model version that is used for prediction when no other version is specified. A default version can help you simplify the prediction request, and avoid specifying the model version every time. By setting the new model as the default version, you can use the new model for prediction without specifying the model version. However, creating a new model, setting it as the default version, uploading the model to Vertex AI Model Registry, and deploying the new model to the existing endpoint would not allow you to inherit the settings and metadata of the existing model, and could cause errors or poor performance. You would need to write code, create and configure the new model, upload the model to Vertex AI Model Registry, and deploy the model to the existing endpoint. Moreover, this option would not set the parentModel parameter to the model ID of the currently deployed model, which could prevent you from inheriting the settings and metadata of the existing model, and cause inconsistencies or conflicts between the model versions2.
Reference:
Preparing for Google Cloud Certification: Machine Learning Engineer, Course 3: Production ML Systems, Week 2: Serving ML Predictions Google Cloud Professional Machine Learning Engineer Exam Guide, Section 3: Scaling ML models in production, 3.1 Deploying ML models to production Official Google Cloud Certified Professional Machine Learning Engineer Study Guide, Chapter 6: Production ML Systems, Section 6.2: Serving ML Predictions Vertex AI Cloud DNS
質問 # 113
You are collaborating on a model prototype with your team. You need to create a Vertex AI Workbench environment for the members of your team and also limit access to other employees in your project. What should you do?
正解:D
質問 # 114
You work for a public transportation company and need to build a model to estimate delay times for multiple transportation routes. Predictions are served directly to users in an app in real time. Because different seasons and population increases impact the data relevance, you will retrain the model every month. You want to follow Google-recommended best practices. How should you configure the end-to-end architecture of the predictive model?
正解:D
質問 # 115
You are developing a model to predict whether a failure will occur in a critical machine part.
You have a dataset consisting of a multivariate time series and labels indicating whether the machine part failed.
You recently started experimenting with a few different preprocessing and modeling approaches in a Vertex Al Workbench notebook.
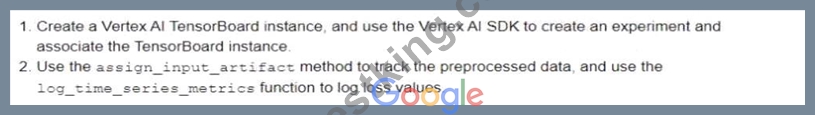
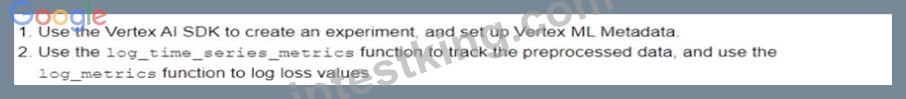
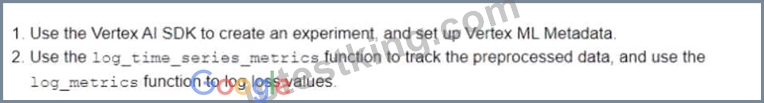
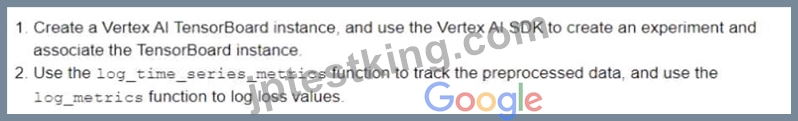
You want to log data and track artifacts from each run. How should you set up your experiments?
正解:C
解説:
The option A is the most suitable solution for logging data and tracking artifacts from each run of a model development experiment in a Vertex AI Workbench notebook. Vertex AI Workbench is a service that allows you to create and run interactive notebooks on Google Cloud. You can use Vertex AI Workbench to experiment with different preprocessing and modeling approaches for your time series prediction problem.
You can also use the Vertex AI TensorBoard instance and the Vertex AI SDK to create an experiment and associate the TensorBoard instance. TensorBoard is a tool that allows you to visualize and monitor the metrics and artifacts of your ML experiments. You can use the Vertex AI SDK to create an experiment object, which is a logical grouping of runs that share a common objective. You can also use the Vertex AI SDK to associate the experiment object with a TensorBoard instance, which is a managed service that hosts a TensorBoard web app. By using the Vertex AI TensorBoard instance and the Vertex AI SDK, you can easily set up and manage your experiments, and access the TensorBoard web app from the Vertex AI console. You can also use the log_time_series_metrics function and the log_metrics function to log data and track artifacts from each run.
The log_time_series_metrics function is a function that allows you to log the time series data, such as the multivariate time series and the labels, to the TensorBoard instance. The log_metrics function is a function that allows you to log the scalar metrics, such as the loss values, to the TensorBoard instance. By using these functions, you can record the data and artifacts from each run of your experiment, and compare them in the TensorBoard web app. You can also use the TensorBoard web app to visualize the data and artifacts, such as the time series plots, the scalar charts, the histograms, and the distributions. By using the Vertex AI TensorBoard instance, the Vertex AI SDK, and the log functions, you can log data and track artifacts from each run of your experiment in a Vertex AI Workbench notebook. References:
* Vertex AI Workbench documentation
* Vertex AI TensorBoard documentation
* Vertex AI SDK documentation
* log_time_series_metrics function documentation
* log_metrics function documentation
* [Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate]
質問 # 116
You are an ML engineer in the contact center of a large enterprise. You need to build a sentiment analysis tool that predicts customer sentiment from recorded phone conversations. You need to identify the best approach to building a model while ensuring that the gender, age, and cultural differences of the customers who called the contact center do not impact any stage of the model development pipeline and results. What should you do?
正解:B
解説:
Sentiment analysis is the process of identifying and extracting the emotions, opinions, and attitudes expressed in a text or speech. Sentiment analysis can help businesses understand their customers' feedback, satisfaction, and preferences. There are different approaches to building a sentiment analysis tool, depending on the input data and the output format. Some of the common approaches are:
* Extracting sentiment directly from the voice recordings: This approach involves using acoustic features, such as pitch, intensity, and prosody, to infer the sentiment of the speaker. This approach can capture the
* nuances and subtleties of the vocal expression, but it also requires a large and diverse dataset of labeled voice recordings, which may not be easily available or accessible. Moreover, this approach may not account for the semantic and contextual information of the speech, which can also affect the sentiment.
* Converting the speech to text and building a model based on the words: This approach involves using automatic speech recognition (ASR) to transcribe the voice recordings into text, and then using lexical features, such as word frequency, polarity, and valence, to infer the sentiment of the text. This approach can leverage the existing text-based sentiment analysis models and tools, but it also introduces some challenges, such as the accuracy and reliability of the ASR system, the ambiguity and variability of the natural language, and the loss of the acoustic information of the speech.
* Converting the speech to text and extracting sentiments based on the sentences: This approach involves using ASR to transcribe the voice recordings into text, and then using syntactic and semantic features, such as sentence structure, word order, and meaning, to infer the sentiment of the text. This approach can capture the higher-level and complex aspects of the natural language, such as negation, sarcasm, and irony, which can affect the sentiment. However, this approach also requires more sophisticated and advanced natural language processing techniques, such as parsing, dependency analysis, and semantic role labeling, which may not be readily available or easy to implement.
* Converting the speech to text and extracting sentiment using syntactical analysis: This approach involves using ASR to transcribe the voice recordings into text, and then using syntactical analysis, such as part-of-speech tagging, phrase chunking, and constituency parsing, to infer the sentiment of the text.
This approach can identify the grammatical and structural elements of the natural language, such as nouns, verbs, adjectives, and clauses, which can indicate the sentiment. However, this approach may not account for the pragmatic and contextual information of the speech, such as the speaker's intention, tone, and situation, which can also influence the sentiment.
For the use case of building a sentiment analysis tool that predicts customer sentiment from recorded phone conversations, the best approach is to convert the speech to text and extract sentiments based on the sentences.
This approach can balance the trade-offs between the accuracy, complexity, and feasibility of the sentiment analysis tool, while ensuring that the gender, age, and cultural differences of the customers who called the contact center do not impact any stage of the model development pipeline and results. This approach can also handle different types and levels of sentiment, such as polarity (positive, negative, or neutral), intensity (strong or weak), and emotion (anger, joy, sadness, etc.). Therefore, converting the speech to text and extracting sentiments based on the sentences is the best approach for this use case.
質問 # 117
......
お客様の時間が大切だということが了解します。私たちのProfessional-Machine-Learning-Engineer試験問題集の一つの特徴は時間を節約できることです。お客様は支払いに成功した後、自分のメールアドレスで直接にProfessional-Machine-Learning-Engineer試験問題集をダウンロードできます。勉強するとき、Professional-Machine-Learning-Engineer試験問題集の問題の答えを覚えると、Professional-Machine-Learning-Engineer試験に参加できます。
Professional-Machine-Learning-Engineer入門知識: https://www.jptestking.com/Professional-Machine-Learning-Engineer-exam.html
P.S. JPTestKingがGoogle Driveで共有している無料かつ新しいProfessional-Machine-Learning-Engineerダンプ:https://drive.google.com/open?id=1j3SY6vYUycphUn54lvAYmPBI3iZpSo6n