Generally speaking, Microsoft certification has become one of the most authoritative voices speaking to us today. Let us make our life easier by learning to choose the proper DP-750 test answers, pass the DP-750 exam, obtain the certification, and be the master of your own life, not its salve. Our DP-750 Exam Questions are exactly what you are looking for. With three different versions of DP-750 exam study materials are shown on our website, so you will be glad to know you have so many different ways to study.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Topic 2: Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Topic 3: Prepare and process data | 30–35% | - Ingest and transform data
|
| Topic 4: Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
>> Microsoft DP-750 Download <<
One of the biggest highlights of the Implementing Data Engineering Solutions Using Azure Databricks prep torrent is the availability of three versions: PDF, app/online, and software/pc, each with its own advantages: The PDF version of DP-750 Exam Torrent has a free demo available for download. You can print exam materials out and read it just like you read a paper. The online version of DP-750 test guide is based on web browser usage design and can be used by any browser device. At the same time, the first time it is opened on the Internet, it can be used offline next time. You can practice anytime, anywhere. The Implementing Data Engineering Solutions Using Azure Databricks software supports the MS operating system and can simulate the real test environment. The contents of the three versions are the same. Each of them neither limits the number of devices used or the number of users at the same time. You can choose according to your needs.
NEW QUESTION # 53
Which Azure service is best integrated with Databricks Unity Catalog for centralized data governance?
Answer: D
Explanation:
Microsoft Purview integrates with Unity Catalog to provide centralized data governance, classification, and lineage tracking. It helps organizations manage data compliance and discovery. Key Vault handles secrets, not governance. DevTest Labs is for testing environments.
Azure Automation is for workflow automation.
NEW QUESTION # 54
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out of- memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior. What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.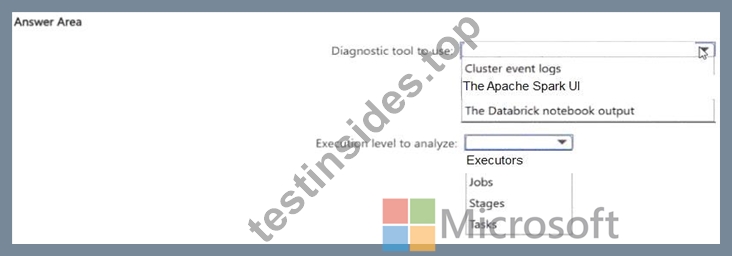
Answer:
Explanation: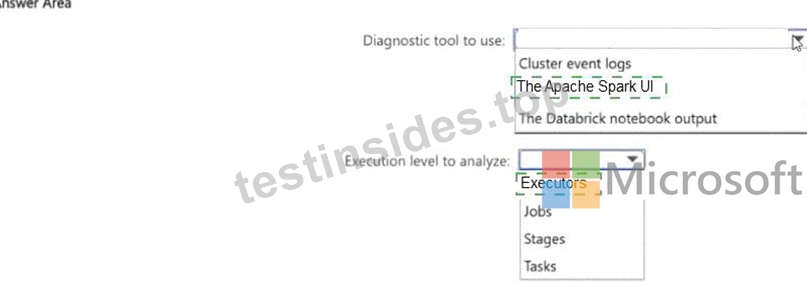
Explanation:
Diagnosing OOM errors requires analysing actual runtime execution behaviour. The Spark UI is the primary tool - it ' s accessible from the cluster detail page and captures rich per-stage and per-task metrics without any extra setup.
In the Executors tab, look at storage memory used, execution memory used, memory spill to disk, and GC time per executor. An executor showing high memory spill is a strong indicator that it ' s processing more data than it can hold in memory - often caused by data skew, where one partition is far larger than the others.
The Stages tab shows task distribution - if one task in a stage is processing 10x more data than its peers, that
' s data skew causing memory pressure on that specific executor. Ganglia (available on older runtimes) provides node-level OS metrics like heap usage over time, which can confirm whether memory pressure is sustained or spiky.
These built-in tools give a complete picture of the root cause before making any configuration changes.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/monitor-cluster
NEW QUESTION # 55
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named Catalog1. Catalog1 contains a table named Transactions. Transactions contains the following columns:
- transaction_id
- customer_name
- email_address
- credit_card_number
- transaction_amount
You need to ensure that business analysts can query all the rows in the Transactions table. The solution must meet the following requirements:
- Prevent the analysts from seeing the full values in the email_address and credit_card_number columns.
- Ensure that the analysts can see only the values after the @
character in each email address.
- Ensure that the analysts can see only the last four digits of each
credit card number.
- Enable the analysts to query the table without errors.
- Follow the principle of least privilege.
What should you do?
Answer: B
Explanation:
To protect sensitive customer information while allowing a specific group to run queries, use Unity Catalog's Dynamic Column Masking. This grants the group table access while applying User- Defined Functions (UDFs) to redact the email addresses and credit card numbers dynamically.
Here is the exact SQL implementation to apply:
1. Create the masking SQL UDFs
Define functions to apply the exact partial masking rules requested.
2. Apply the column masks to the tableAlter the transaction table to attach these UDFs to the respective columns.
3. Grant least privilege permissionsGrant the group the SELECT permission on the table, along with the foundational permissions to access the catalog and schema.
Reference:
https://docs.databricks.com/aws/en/data-governance/unity-catalog/filters-and-masks
NEW QUESTION # 56
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You need to configure Cluster1 to meet the following requirements:
- The cluster must scale up automatically when workloads increase.
- The cluster must scale down automatically when workloads decrease.
The solution must minimize costs.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: C,D
Explanation:
Enabling autoscaling and setting a 30-minute auto-termination timeout is the correct configuration to meet the goals.
Autoscaling handles fluctuating workloads, while auto-termination prevents you from paying for idle compute resources.
Dynamic Scaling: Autoscaling automatically adds workers during high loads and removes them when demand drops.
Cost Control: The 30-minute termination window ensures the cluster shuts down completely if no jobs are running, stopping all compute charges.
Reference:
https://community.databricks.com/t5/get-started-discussions/cluster-auto-termination-best- practices/td-p/75826
NEW QUESTION # 57
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a foreign catalog in Catalog Explorer.
Does this meet the goal?
Answer: A
Explanation:
The correct answer is A - Yes.
A foreign catalog created through Lakehouse Federation in Catalog Explorer is the correct solution for all three requirements. Here's why it works:
The schemas and tables of DB1 can be queried in Databricks - Lakehouse Federation pushes the query down to the external SQL Server and returns results, so analysts write normal SQL in Databricks.
They appear alongside other Unity Catalog objects - the foreign catalog sits in the same three-tier hierarchy as native catalogs, schemas, and tables, visible in Catalog Explorer alongside all other Unity Catalog assets.
The data is NOT copied into Databricks-managed storage - foreign catalogs query data in place at the source; nothing is replicated or materialised in Databricks storage.
This is exactly the scenario Lakehouse Federation was built for.
Reference: https://learn.microsoft.com/en-us/azure/databricks/query-federation/lakehouse-federation
NEW QUESTION # 58
......
There are three formats of the DP-750 practice training material for your preparation. You can choose as your needs. The first one is the pdf files: DP-750 pdf dumps can be printed into papers which is very suitable for making notes. The DP-750 PC test engine & DP-750 online test engine are all VCE format and can simulate the actual test environment. The DP-750 PC test engine is suitable for any windows system, while the DP-750 online test engine can be installed on any electronic device. All the DP-750 exam content are the same and valid for different formats.
DP-750 Reliable Exam Test: https://www.testinsides.top/DP-750-dumps-review.html