DOWNLOAD the newest BraindumpsPrep Data-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1ocNJv9QrHOwWBKk-WdheAGaCihoZo7Mq
With the rapid development of the world economy and frequent contacts between different countries, looking for a good job has become more and more difficult for all the people. So it is very necessary for you to get the Data-Engineer-Associate certification, you have to increase your competitive advantage in the labor market and make yourself distinguished from other job-seekers. Our Data-Engineer-Associate Exam Questions can help you make it. As the most professional Data-Engineer-Associate study guide, we have helped numerous of our customer get a better career and live a better life now.
| Section | Weight | Objectives |
|---|---|---|
| Data Operations and Support | 22% | - Monitor data pipelines
|
| Data Store Management | 26% | - Choose a data store
|
| Data Ingestion and Transformation | 34% | - Apply programming concepts
|
| Data Security and Governance | 18% | - Apply authentication and authorization
|
>> Data-Engineer-Associate Reliable Test Review <<
There are more opportunities for possessing with a certification, and our Data-Engineer-Associate study tool is the greatest resource to get a leg up on your competition, and stage yourself for promotion. When it comes to our time-tested Data-Engineer-Associate latest practice dumps, for one thing, we have a professional team contains a lot of experts who have devoted themselves to the research and development of our Data-Engineer-Associate Exam Guide, thus we feel confident enough under the intensely competitive market. For another thing, conforming to the real exam our Data-Engineer-Associate study tool has the ability to catch the core knowledge. So our customers can pass the exam with ease.
NEW QUESTION # 73
A company has a frontend ReactJS website that uses Amazon API Gateway to invoke REST APIs. The APIs perform the functionality of the website. A data engineer needs to write a Python script that can be occasionally invoked through API Gateway. The code must return results to API Gateway.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: B
Explanation:
AWS Lambda is a serverless compute service that lets you run code without provisioning or managing servers. You can use Lambda to create functions that perform custom logic and integrate with other AWS services, such as API Gateway. Lambda automatically scales your application by running code in response to each trigger. You pay only for the compute time you consume1.
Amazon ECS is a fully managed container orchestration service that allows you to run and scale containerized applications on AWS. You can use ECS to deploy, manage, and scale Docker containers using either Amazon EC2 instances or AWS Fargate, a serverless compute engine for containers2.
Amazon EKS is a fully managed Kubernetes service that allows you to run Kubernetes clusters on AWS without needing to install, operate, or maintain your own Kubernetes control plane. You can use EKS to deploy, manage, and scale containerized applications using Kubernetes on AWS3.
The solution that meets the requirements with the least operational overhead is to create an AWS Lambda Python function with provisioned concurrency. This solution has the following advantages:
It does not require you to provision, manage, or scale any servers or clusters, as Lambda handles all the infrastructure for you. This reduces the operational complexity and cost of running your code.
It allows you to write your Python script as a Lambda function and integrate it with API Gateway using a simple configuration. API Gateway can invoke your Lambda function synchronously or asynchronously, and return the results to the frontend website.
It ensures that your Lambda function is ready to respond to API requests without any cold start delays, by using provisioned concurrency. Provisioned concurrency is a feature that keeps your function initialized and hyper-ready to respond in double-digit milliseconds. You can specify the number of concurrent executions that you want to provision for your function.
Option A is incorrect because it requires you to deploy a custom Python script on an Amazon ECS cluster.
This solution has the following disadvantages:
It requires you to provision, manage, and scale your own ECS cluster, either using EC2 instances or Fargate.
This increases the operational complexity and cost of running your code.
It requires you to package your Python script as a Docker container image and store it in a container registry, such as Amazon ECR or Docker Hub. This adds an extra step to your deployment process.
It requires you to configure your ECS cluster to integrate with API Gateway, either using an Application Load Balancer or a Network Load Balancer. This adds another layer of complexity to your architecture.
Option C is incorrect because it requires you to deploy a custom Python script that can integrate with API Gateway on Amazon EKS. This solution has the following disadvantages:
It requires you to provision, manage, and scale your own EKS cluster, either using EC2 instances or Fargate.
This increases the operational complexity and cost of running your code.
It requires you to package your Python script as a Docker container image and store it in a container registry, such as Amazon ECR or Docker Hub. This adds an extra step to your deployment process.
It requires you to configure your EKS cluster to integrate with API Gateway, either using an Application Load Balancer, a Network Load Balancer, or a service of type LoadBalancer. This adds another layer of complexity to your architecture.
Option D is incorrect because it requires you to create an AWS Lambda function and ensure that the function is warm by scheduling an Amazon EventBridge rule to invoke the Lambda function every 5 minutes by using mock events. This solution has the following disadvantages:
It does not guarantee that your Lambda function will always be warm, as Lambda may scale down your function if it does not receive any requests for a long period of time. This may cause cold start delays when your function is invoked by API Gateway.
It incurs unnecessary costs, as you pay for the compute time of your Lambda function every time it is invoked by the EventBridge rule, even if it does not perform any useful work1.
1: AWS Lambda - Features
2: Amazon Elastic Container Service - Features
3: Amazon Elastic Kubernetes Service - Features
[4]: Building API Gateway REST API with Lambda integration - Amazon API Gateway
[5]: Improving latency with Provisioned Concurrency - AWS Lambda
[6]: Integrating Amazon ECS with Amazon API Gateway - Amazon Elastic Container Service
[7]: Integrating Amazon EKS with Amazon API Gateway - Amazon Elastic Kubernetes Service
[8]: Managing concurrency for a Lambda function - AWS Lambda
NEW QUESTION # 74
A data engineer is using Amazon Athena to analyze sales data that is in Amazon S3. The data engineer writes a query to retrieve sales amounts for 2023 for several products from a table named sales_dat a. However, the query does not return results for all of the products that are in the sales_data table. The data engineer needs to troubleshoot the query to resolve the issue.
The data engineer's original query is as follows:
SELECT product_name, sum(sales_amount)
FROM sales_data
WHERE year = 2023
GROUP BY product_name
How should the data engineer modify the Athena query to meet these requirements?
Answer: C
Explanation:
The original query does not return results for all of the products because the year column in the sales_data table is not an integer, but a timestamp. Therefore, the WHERE clause does not filter the data correctly, and only returns the products that have a null value for the year column. To fix this, the data engineer should use the extract function to extract the year from the timestamp and compare it with 2023. This way, the query will return the correct results for all of the products in the sales_data table. The other options are either incorrect or irrelevant, as they do not address the root cause of the issue. Replacing sum with count does not change the filtering condition, adding HAVING clause does not affect the grouping logic, and removing the GROUP BY clause does not solve the problem of missing products. Reference:
Troubleshooting JSON queries - Amazon Athena (Section: JSON related errors) When I query a table in Amazon Athena, the TIMESTAMP result is empty (Section: Resolution) AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide (Chapter 7, page 197)
NEW QUESTION # 75
A company wants to migrate a data warehouse from Teradata to Amazon Redshift. Which solution will meet this requirement with the LEAST operational effort?
Answer: C
NEW QUESTION # 76
A data engineer is configuring an AWS Glue job to read data from an Amazon S3 bucket. The data engineer has set up the necessary AWS Glue connection details and an associated IAM role. However, when the data engineer attempts to run the AWS Glue job, the data engineer receives an error message that indicates that there are problems with the Amazon S3 VPC gateway endpoint.
The data engineer must resolve the error and connect the AWS Glue job to the S3 bucket.
Which solution will meet this requirement?
Answer: B
Explanation:
The error message indicates that the AWS Glue job cannot access the Amazon S3 bucket through the VPC endpoint. This could be because the VPC's route table does not have the necessary routes to direct the traffic to the endpoint. To fix this, the data engineer must verify that the route table has an entry for the Amazon S3 service prefix (com.amazonaws.region.s3) with the target as the VPC endpoint ID. This will allow the AWS Glue job to use the VPC endpoint to access the S3 bucket without going through the internet or a NAT gateway. For more information, see Gateway endpoints. References:
Troubleshoot the AWS Glue error "VPC S3 endpoint validation failed"
Amazon VPC endpoints for Amazon S3
[AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide]
NEW QUESTION # 77
A data engineer maintains a materialized view that is based on an Amazon Redshift database. The view has a column named load_date that stores the date when each row was loaded.
The data engineer needs to reclaim database storage space by deleting all the rows from the materialized view.
Which command will reclaim the MOST database storage space?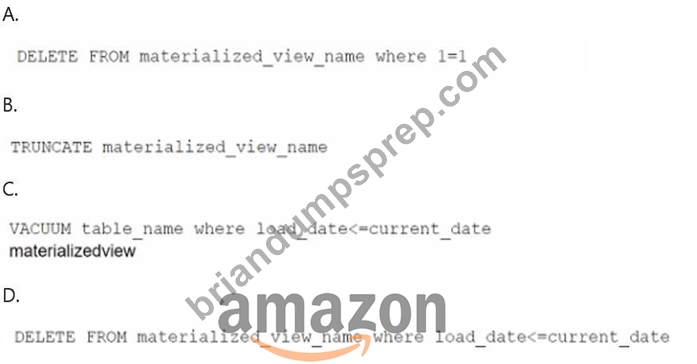
Answer: B
Explanation:
To reclaim the most storage space from a materialized view in Amazon Redshift, you should use aDELETE operation that removes all rows from the view. The most efficient way to remove all rows is to use a condition that always evaluates to true, such as1=1.This will delete all rows without needing to evaluate each row individually based on specific column values like load_date.
* Option A: DELETE FROM materialized_view_name WHERE 1=1;This statement will delete all rows in the materialized view and free up the space. Since materialized views in Redshift store precomputed data, performing a DELETE operation will remove all stored rows.
Other options either involve inappropriate SQL statements (e.g., VACUUM in option C is used for reclaiming storage space in tables, not materialized views), or they don't remove data effectively in the context of a materialized view (e.g., TRUNCATE cannot be used directly on a materialized view).
References:
Amazon Redshift Materialized Views Documentation
Deleting Data from Redshift
NEW QUESTION # 78
......
In the past ten years, our company has never stopped improving the AWS Certified Data Engineer - Associate (DEA-C01) exam cram. For a long time, we have invested much money to perfect our products. At the same time, we have introduced the most advanced technology and researchers to perfect our AWS Certified Data Engineer - Associate (DEA-C01) exam questions. At present, the overall strength of our company is much stronger than before. We are the leader in the market and master the most advanced technology. In fact, our Data-Engineer-Associate Test Guide has occupied large market shares because of our consistent renovating. We have built a powerful research center and owned a strong team. Up to now, we have got a lot of patents about the Data-Engineer-Associate test guide. In the future, we will continuously invest more money on researching.
Data-Engineer-Associate Dumps Free: https://www.briandumpsprep.com/Data-Engineer-Associate-prep-exam-braindumps.html
P.S. Free 2026 Amazon Data-Engineer-Associate dumps are available on Google Drive shared by BraindumpsPrep: https://drive.google.com/open?id=1ocNJv9QrHOwWBKk-WdheAGaCihoZo7Mq