BONUS!!! Laden Sie die vollständige Version der Zertpruefung ARA-C01 Prüfungsfragen kostenlos herunter: https://drive.google.com/open?id=1KitMpURAIGdsXzIJCfE8yFXmzoSXYjsN
Wünschen Sie jetzt die früheren Prüfungsfragen und Nachschlagebücher von Snowflake ARA-C01 Zertifizierungsprüfungen? Sie haben nicht genug Zeit, die Snowflake ARA-C01 Zertifizierungsprüfung vorzubereiten, wenn Sie sich mit der Arbeit beschäftigt sind. Deshalb ist es sehr wichtig für Sie, hocheffektive Prüfungsunterlagen auszuwählen. Deshalb ist es sehr wichtig, ein richtiges Lerngerät zu wählen. Wählen Sie bitte Snowflake ARA-C01 Dumps von Zertpruefung.
| Section | Weight | Objectives |
|---|---|---|
| Snowflake Architecture | 30% | - Platform Architecture Design
|
| Data Engineering | 25% | - Data Loading and Pipelines
|
| Performance Optimization | 20% | - Cost and Resource Optimization
|
| Accounts and Security | 25% | - Access Control and Authentication
|
>> Snowflake ARA-C01 Testfagen <<
Sie brauchen nicht die komplizierte Ordnungsarbeit machen. Sie brauchen nicht für eine lange Zeit warten. Auf unserer Webseite können Sie die neueste und zuverlässigste Prüfungsunterlagen für Snowflake ARA-C01 erhalten. Unterschiedliche Versionen bieten Ihnen unterschiedliche Emfindungen. Was zweifellos ist, dass alle Versionen von Snowflake ARA-C01 sind effektiv. Bezahlen Sie mit gesichertem Zahlungsmittel Paypal! Dann können Sie gleich die Snowflake ARA-C01 Prüfungsunterlagen herunterlagen und benutzen!
133. Frage
What Snowflake features should be leveraged when modeling using Data Vault?
Antwort: C
Begründung:
These two features are relevant for modeling using Data Vault on Snowflake. Data Vault is a data modeling approach that organizes data into hubs, links, and satellites. Data Vault is designed to enable high scalability, flexibility, and performance for data integration and analytics. Snowflake is a cloud data platform that supports various data modeling techniques, including Data Vault. Snowflake provides some features that can enhance the Data Vault modeling, such as:
* Snowflake's support of multi-table inserts into the data model's Data Vault tables. Multi-table inserts (MTI) are a feature that allows inserting data from a single query into multiple tables in a single DML statement. MTI can improve the performance and efficiency of loading data into Data Vault tables, especially for real-time or near-real-time data integration. MTI can also reduce the complexity and maintenance of the loading code, as well as the data duplication and latency12.
* Scaling up the virtual warehouses will support parallel processing of new source loads. Virtual warehouses are a feature that allows provisioning compute resources on demand for data processing.
Virtual warehouses can be scaled up or down by changing the size of the warehouse, which determines the number of servers in the warehouse. Scaling up the virtual warehouses can improve the performance and concurrency of processing new source loads into Data Vault tables, especially for large or complex data sets. Scaling up the virtual warehouses can also leverage the parallelism and distribution of Snowflake's architecture, which can optimize the data loading and querying34.
Snowflake Documentation: Multi-table Inserts
Snowflake Blog: Tips for Optimizing the Data Vault Architecture on Snowflake Snowflake Documentation: Virtual Warehouses Snowflake Blog: Building a Real-Time Data Vault in Snowflake
134. Frage
What is a characteristic of loading data into Snowflake using the Snowflake Connector for Kafka?
Antwort: C
Begründung:
Explanation
According to the SnowPro Advanced: Architect documents and learning resources, a characteristic of loading data into Snowflake using the Snowflake Connector for Kafka is that the Connector creates and manages its own stage, file format, and pipe objects. The stage is an internal stage that is used to store the data files from the Kafka topics. The file format is a JSON or Avro file format that is used to parse the data files. The pipe is a Snowpipe object that is used to load the data files into the Snowflake table. The Connector automatically creates and configures these objects based on the Kafka configuration properties, and handles the cleanup and maintenance of these objects1.
The other options are incorrect because they are not characteristics of loading data into Snowflake using the Snowflake Connector for Kafka. Option A is incorrect because the Connector works in Snowflake regions that use any cloud infrastructure, not just AWS. The Connector supports AWS, Azure, and Google Cloud platforms, and can load data across different regions and cloud platforms using data replication2. Option B is incorrect because the Connector does not work with all file formats, only JSON and Avro. The Connector expects the data in the Kafka topics to be in JSON or Avro format, and parses the data accordingly. Other file formats, such as text, ORC, Parquet, or XML, are not supported by the Connector3. Option D is incorrect because loads using the Connector do not have lower latency than Snowpipe, and do not ingest data in real time. The Connector uses Snowpipe to load data into Snowflake, and inherits the same latency and performance characteristics of Snowpipe. The Connector does not provide real-time ingestion, but near real-time ingestion, depending on the frequency and size of the data files4. References: Installing and Configuring the Kafka Connector | Snowflake Documentation, Sharing Data Across Regions and Cloud Platforms | Snowflake Documentation, Overview of the Kafka Connector | Snowflake Documentation, Using Snowflake Connector for Kafka With Snowpipe Streaming | Snowflake Documentation
135. Frage
Consider the following scenario where a masking policy is applied on the CREDICARDND column of the CREDITCARDINFO table. The masking policy definition Is as follows: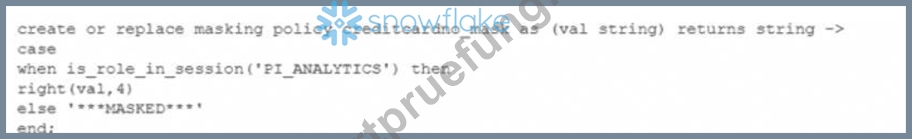
Sample data for the CREDITCARDINFO table is as follows:
NAME EXPIRYDATE CREDITCARDNO
JOHN DOE 2022-07-23 4321 5678 9012 1234
if the Snowflake system rotes have not been granted any additional roles, what will be the result?
Antwort: A
Begründung:
The masking policy defined in the image indicates that if a user has the PI_ANALYTICS role, they will be able to see the last 4 characters of the CREDITCARDNO column data in clear text. Otherwise, they will see
'MASKED'. Since Snowflake system roles have not been granted any additional roles, they won't have the PI_ANALYTICS role and therefore cannot view the last 4 characters of credit card numbers.
To apply a masking policy on a column in Snowflake, you need to use the ALTER TABLE ... ALTER COLUMN command or the ALTER VIEW command and specify the policy name. For example, to apply the creditcardno_mask policy on the CREDITCARDNO column of the CREDITCARDINFO table, you can use the following command:
ALTER TABLE CREDITCARDINFO ALTER COLUMN CREDITCARDNO SET MASKING POLICY creditcardno_mask; For more information on how to create and use masking policies in Snowflake, you can refer to the following resources:
CREATE MASKING POLICY: This document explains the syntax and usage of the CREATE MASKING POLICY command, which allows you to create a new masking policy or replace an existing one.
Using Dynamic Data Masking: This guide provides instructions on how to configure and use dynamic data masking in Snowflake, which is a feature that allows you to mask sensitive data based on the execution context of the user.
ALTER MASKING POLICY: This document explains the syntax and usage of the ALTER MASKING POLICY command, which allows you to modify the properties of an existing masking policy.
References: 1: https://docs.snowflake.com/en/sql-reference/sql/create-masking-policy 2: https://docs.
snowflake.com/en/user-guide/security-column-ddm-use 3: https://docs.snowflake.com/en/sql-reference/sql
/alter-masking-policy
136. Frage
You have written a procedure and a function in snowflake.
How do you find your procedures and functions in snowflake?
Antwort: D
137. Frage
A company's Architect needs to find an efficient way to get data from an external partner, who is also a Snowflake user. The current solution is based on daily JSON extracts that are placed on an FTP server and uploaded to Snowflake manually. The files are changed several times each month, and the ingestion process needs to be adapted to accommodate these changes.
What would be the MOST efficient solution?
Antwort: A
Begründung:
The most efficient solution is to ask the partner to create a share and add the company's account (Option A).
This way, the company can access the live data from the partner without any data movement or manual intervention. Snowflake's secure data sharing feature allows data providers to share selected objects in a database with other Snowflake accounts. The shared data is read-only and does not incur any storage or compute costs for the data consumers. The data consumers can query the shared data directly or create local copies of the shared objects in their own databases. Option B is not efficient because it involves using the data lake export feature, which is intended for exporting data from Snowflake to an external data lake, not for importing data from another Snowflake account. The data lake export feature also requires the data provider to create an external stage on cloud storage and use the COPY INTO <location> command to export the data into parquet files. The data consumer then needs to create an external table or a file format to load the data from the cloud storage into Snowflake. This process can be complex and costly, especially if the data changes frequently. Option C is not efficient because it does not solve the problem of manual data ingestion and adaptation. Keeping the current structure of daily JSON extracts on an FTP server and requesting the partner to stop changing files, instead only appending new files, does not improve the efficiency or reliability of the data ingestion process. The company still needs to upload the data to Snowflake manually and deal with any schema changes or data quality issues. Option D is not efficient because it requires the partner to set up a Snowflake reader account and use that account to get the data for ingestion. A reader account is a special type of account that can only consume data from the provider account that created it. It is intended for data consumers who are not Snowflake customers and do not have a licensing agreement with Snowflake. A reader account is not suitable for data ingestion from another Snowflake account, as it does not allow uploading, modifying, or unloading data. The company would need to use external tools or interfaces to access the data from the reader account and load it into their own account, which can be slow and expensive. References: The answer can be verified from Snowflake's official documentation on secure data sharing, data lake export, and reader accounts available on their website. Here are some relevant links:
* Introduction to Secure Data Sharing | Snowflake Documentation
* Data Lake Export Public Preview Is Now Available on Snowflake | Snowflake Blog
* Managing Reader Accounts | Snowflake Documentation
138. Frage
......
ARA-C01 ist eine der Snowflake Zertifizierungsprüfungen. IT-Fachmann mit Snowflake Zertifikat sind sehr beliebt in der IT-Branche. Deshalb legen imme mehr Leute die ARA-C01 Zertifizierungsprüfung. Jedoch ist es nicht so einfach, die Snowflake ARA-C01 Zertifizierungsprüfung zu bestehen. Wenn Sie nicht an den entprechenden Kursen teilnehmen, brauchen Sie viel Zeit und Energie, sich auf die Prüfung vorzubereiten. Nun kann Zertpruefung Ihnen viel Zeit und Energie ersparen.
ARA-C01 Prüfungs-Guide: https://www.zertpruefung.de/ARA-C01_exam.html
2026 Die neuesten Zertpruefung ARA-C01 PDF-Versionen Prüfungsfragen und ARA-C01 Fragen und Antworten sind kostenlos verfügbar: https://drive.google.com/open?id=1KitMpURAIGdsXzIJCfE8yFXmzoSXYjsN