TestSimulate real Databricks Databricks-Certified-Professional-Data-Engineer Exam Dumps are ideal for applicants who are busy in their routines and want to do quick preparation for the Databricks Databricks-Certified-Professional-Data-Engineer certification test. We guarantee that our actual Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) questions will be enough for you to prepare successfully for the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) examination.
| Section | Weight | Objectives |
|---|---|---|
| Data Modelling | 6% | - Medallion Architecture implementation - Schema design and management - Delta Lake table design |
| Cost & Performance Optimisation | 13% | - Cluster configuration and scaling - Storage optimization (partitioning, Z-order, indexing) - Query optimization and caching |
| Data Sharing and Federation | 5% | - Unity Catalog data sharing - Cross-workspace and cross-cloud access |
| Data Governance | 7% | - Data lineage and metadata tracking - Unity Catalog management - Policy enforcement |
| Debugging and Deploying | 10% | - Deployment using bundles, CLI, and APIs - CI/CD and DevOps practices - Troubleshooting pipelines and errors |
| Data Ingestion & Acquisition | 7% | - Connecting to diverse data sources - Schema inference and evolution - Auto Loader and streaming ingestion |
| Monitoring and Alerting | 10% | - Setting up alerts and notifications - Performance and health monitoring - Pipeline observability and logging |
| Data Transformation, Cleansing, and Quality | 10% | - Handling missing or inconsistent data - Data validation and quality checks - Standardization and normalization |
| Developing Code for Data Processing using Python and SQL | 22% | - Batch and incremental processing logic - Data transformation and aggregation - Integration with Databricks APIs and tools |
| Ensuring Data Security and Compliance | 10% | - Compliance standards implementation - Data encryption and masking - Access control and permissions |
>> Latest Databricks-Certified-Professional-Data-Engineer Guide Files <<
If you want to take Databricks Databricks-Certified-Professional-Data-Engineer exam, TestSimulate Databricks Databricks-Certified-Professional-Data-Engineer exam dumps are your best tools. The dumps can help you pass Databricks-Certified-Professional-Data-Engineer test easily. And the dumps are very highly regarded. With our test questions and test answers, you don't need to worry about Databricks-Certified-Professional-Data-Engineer Certification. Because our dumps can solve all difficult problems you encounter in the process of preparing for the exam. Before you make a decision, you can download our free demo. For this, you will know whether our questions and answers fit to you or not.
NEW QUESTION # 127
A data engineer is running a groupBy aggregation on a massive user activity log grouped by user_id. A few users have millions of records, causing task skew and long runtimes.
Which technique will fix the skew in this aggregation?
Answer: A
Explanation:
Task skew occurs when a small subset of keys holds a disproportionate amount of data, causing certain tasks to process significantly more records than others. Databricks documentation recommends salting as an effective mitigation technique.
Salting introduces a random or calculated prefix to skewed keys, distributing records across multiple partitions and balancing the workload during the shuffle stage. After aggregation, a second pass re-aggregates results by removing the prefix to restore key integrity.
Increasing memory (B) does not resolve distribution imbalance; reduceByKey (C) still triggers shuffles; and filtering (D) would remove valid business data. Hence, salting is the correct and officially recommended approach to address skew in Spark aggregations.
NEW QUESTION # 128
A Delta Lake table with Change Data Feed (CDF) enabled in the Lakehouse named customer_churn_params is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources. The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours. Which approach would simplify the identification of these changed records?
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
* Exact extract: "Change data feed (CDF) provides row-level change information for Delta tables."
* Exact extract: "Use table_changes to query the set of rows that were inserted, updated, or deleted between two versions (or timestamps)." References: Delta Lake Change Data Feed; Delta Lake MERGE INTO.
NEW QUESTION # 129
You noticed that a team member started using an all-purpose cluster to develop a notebook and used the same all-purpose cluster to set up a job that can run every 30 mins so they can update un-derlying tables which are used in a dashboard. What would you recommend for reducing the overall cost of this approach?
Answer: E
Explanation:
Explanation
While using an all-purpose cluster is ok during development but anytime you don't need to interact with a notebook, especially for a scheduled job it is less expensive to use a job cluster. Using an all-purpose cluster can be twice as expensive as a job cluster.
Please note: The compute cost you pay the cloud provider for the same cluster type and size be-tween an all-purpose cluster and job cluster is the same the only difference is the DBU cost.
The total cost of cluster = Total cost of VM compute(Azure or AWS or GCP) + Cost per DBU The per DBU cost varies between all-purpose and Job Cluster Here is the recent cost estimate from AWS between Jobs Cluster and all-purpose Cluster, for jobs compute its
$0.15 cents per DBU v$0.55 cents per DBU for all-purpose
Graphical user interface Description automatically generated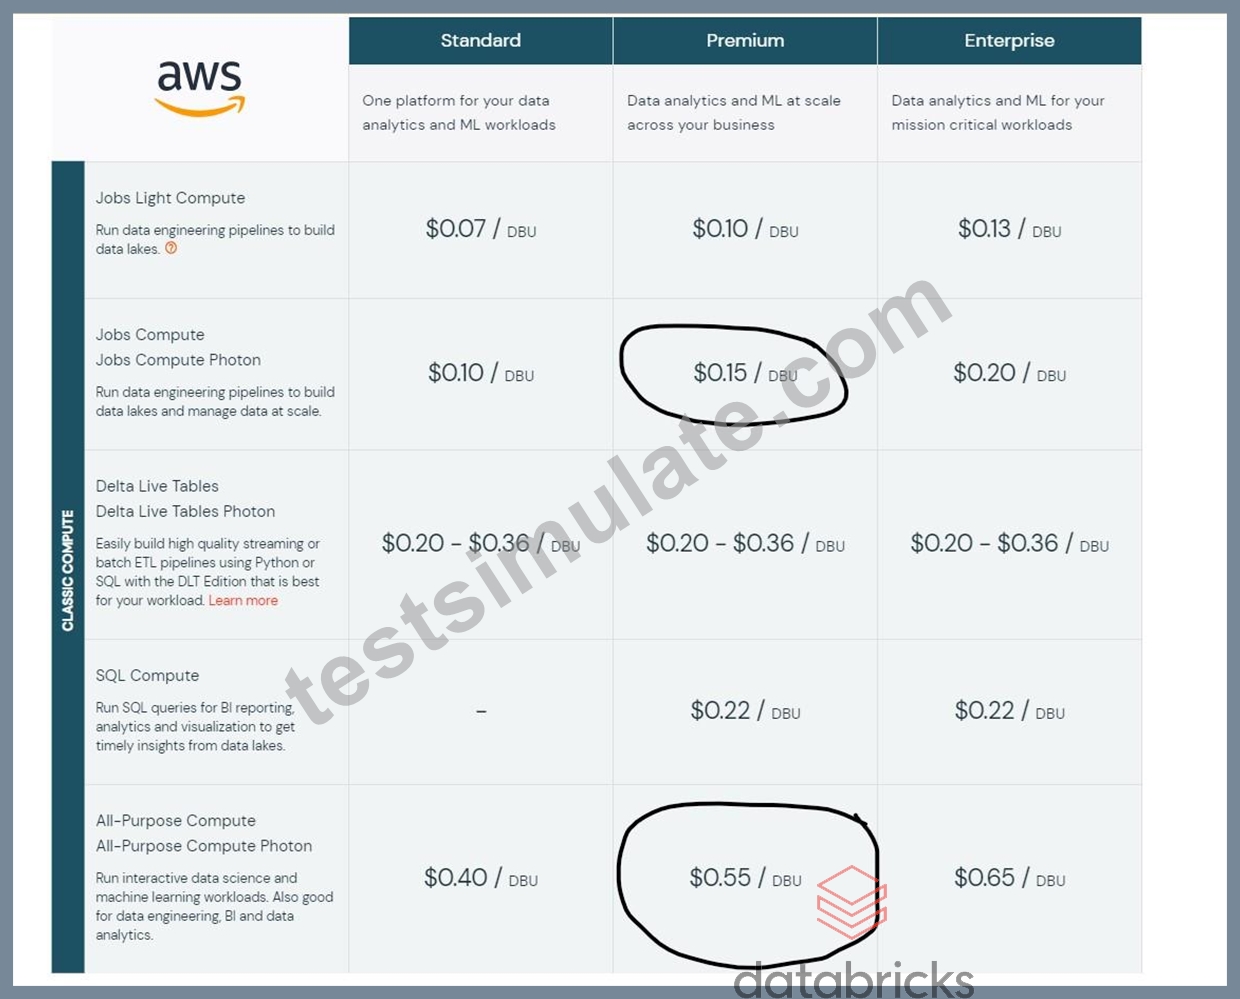
How do I check how much the DBU cost for my cluster?
When you click on an exister cluster or when you look at the cluster details you will see this in the top right corner Graphical user interface, text, application, email Description automatically generated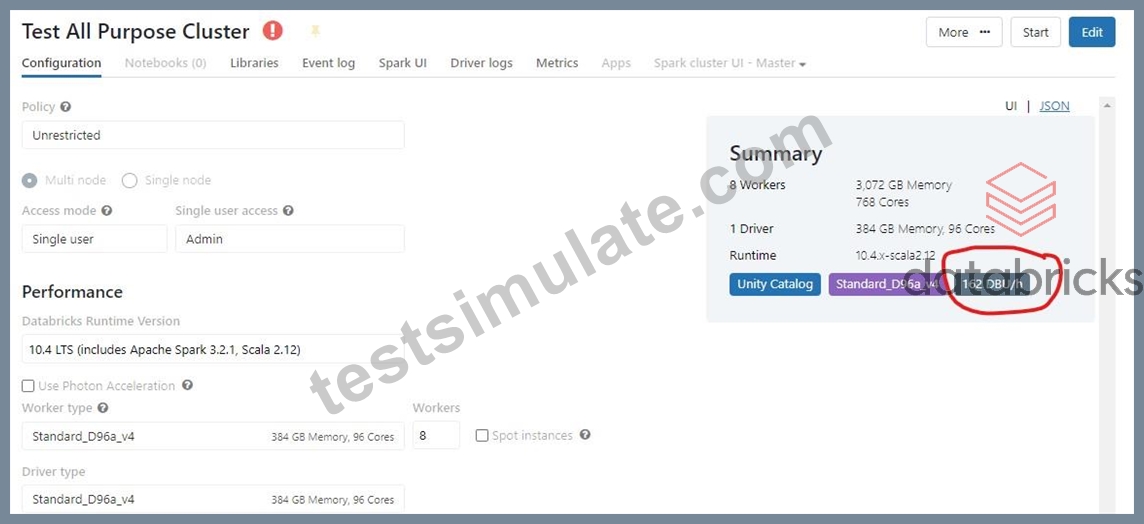
NEW QUESTION # 130
A Delta Lake table was created with the below query: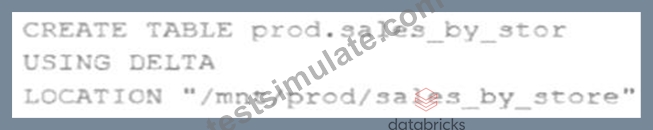
Realizing that the original query had a typographical error, the below code was executed:
ALTER TABLE prod.sales_by_stor RENAME TO prod.sales_by_store
Which result will occur after running the second command?
Answer: C
Explanation:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An externaltable can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The result that will occur after running the second command is that the table reference in the metastore is updated and no data is changed. The metastore is a service that stores metadata about tables, such as their schema, location, properties, and partitions. The metastore allows users to access tables using SQL commands or Spark APIs without knowing their physical location or format. When renaming an external table using the ALTER TABLE RENAME TO command, only the table reference in the metastore is updated with the new name; no data files or directories are moved or changed in the storage system. The table will still point to the same location and use the same format as before. However, if renaming a managed table, which is a table whose metadata and data are both managed by Databricks, both the table reference in the metastore and the data files in the default warehouse directory are moved and renamed accordingly. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "ALTER TABLE RENAME TO" section; Databricks Documentation, under "Metastore" section; Databricks Documentation, under "Managed and external tables" section.
NEW QUESTION # 131
The business reporting team requires that data for their dashboards be updated every hour. The total processing time for the pipeline that extracts, transforms, and loads the data for their pipeline runs in 10 minutes. Assuming normal operating conditions, which configuration will meet their service-level agreement requirements with the lowest cost?
Answer: B
Explanation:
* Exact extract: "Job clusters are created for a job run and terminate when the job completes." References: Cluster types (job vs all-purpose); Databricks Jobs scheduling.
NEW QUESTION # 132
......
Another thing you will get from using the Databricks-Certified-Professional-Data-Engineer Exam study material is free to support. If you encounter any problem while using the Databricks-Certified-Professional-Data-Engineer material, you have nothing to worry about. The solution is closer to you than you can imagine, just contact the support team and continue enjoying your study with the Databricks Certified Professional Data Engineer Exam preparation material.
Databricks-Certified-Professional-Data-Engineer Braindump Free: https://www.testsimulate.com/Databricks-Certified-Professional-Data-Engineer-study-materials.html