まだAI-200試験に昼夜を問わず滞在していますか? 答えが「はい」の場合は、GoShikenのAI-200試験資料を試してください。 私たちMicrosoftは、最も正確で有用な情報を含むコンテンツだけでなく、最も迅速で最も効率的なアシスタントを提供するアフターサービスについても専門的です。 当社のAI-200練習トレントを20〜30時間使用すると、AI-200試験に参加する準備が整い、期待されるDeveloping AI Cloud Solutions on Azureスコアを達成できると主張できます。
| Section | Objectives |
|---|---|
| Implement Azure AI solutions | - Implement natural language processing solutions - Implement computer vision solutions - Implement knowledge mining with Azure AI Search - Implement generative AI solutions using Azure OpenAI |
| Implement and monitor AI workloads | - Deploy AI models and services - Monitor performance and troubleshoot issues |
| Plan and manage Azure AI solutions | - Monitor and optimize AI solutions - Plan security and compliance requirements - Select appropriate Azure AI services |
AI-200学習教材があれば、あなたは自分の夢を叶えます。AI-200学習教材はすごく人気があります。全世界のお客様からいい評価をもらいました。なんといっても、自分はAI-200学習教材を利用したら、その資料のよさを感じることができます。大切なのは、AI-200学習教材の合格率が高いので、多くのお客様はAI-200認定試験資格証明書を取得したということです。
質問 # 54
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
You need to configure Azure Functions to generate vector embeddings according to planned environment application architecture.
Which trigger type should you use?
正解:A
解説:
The most appropriate trigger type for this architecture is the Azure Cosmos DB Trigger.
This trigger monitors your NoSQL container's underlying change feed. When a document is created or modified, the function fires automatically, processes the data, generates the embedding, and places a message in Azure Service Bus.
Scenario, Planned Application Architecture
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Reference:
https://learn.microsoft.com/en-us/azure/cosmos-db/integrated-embeddings
質問 # 55
An Azure Storage Blob upload must trigger backend processing.
The solution must:
* Avoid polling.
* Minimize latency.
* Trigger automatically when the upload occurs.
You need to ensure that processing starts as soon as a file is uploaded.
Which trigger should you implement?
正解:B
解説:
Use an Azure Event Grid trigger for event-driven processing of new blob uploads. Azure Blob Storage can publish events such as Microsoft.Storage.BlobCreated to Event Grid, which then pushes the event to the subscribed Azure Function or other event handler. This eliminates the need for the application to periodically scan the storage container for changes.
Microsoft distinguishes traditional polling-based Blob triggers from event-driven Blob/Event Grid processing . Event Grid-based processing provides low-latency, near-real-time delivery and supports high- scale workloads. Microsoft specifically notes that the Event Grid source eliminates polling delays and can process newly created blobs within seconds of upload.
A Timer trigger would explicitly introduce polling on a schedule. A Queue Storage trigger requires another component to place a message in a queue when the blob arrives, so it is not the direct event source described.
An HTTP trigger requires an external caller to invoke the function and therefore does not automatically react to a Blob Storage creation event.
Therefore, Event Grid is the correct trigger for automatic, low-latency, non-polling blob processing.
Study Guide references: Azure Functions # Event Grid triggers; Azure Blob Storage events; event-driven Blob processing; BlobCreated events; near-real-time processing.
質問 # 56
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You are using Azure Monitor Application Insights to investigate a production API. You open the Logs blade and set the time range to Last 24 hours.
An engineer recommends the following query to count requests by result code and sort the results from most frequent to least frequent:
requests
| summarize request_count = count() by resultCode
| order by request_count desc
You need to determine whether the query returns the number of requests grouped by result code and sorted from most to least frequent.
Solution: The query returns one row per unique resultCode value with the number of requests in each group.
Does the solution meet the goal?
正解:A
解説:
Correct:
* The query returns one row per unique resultCode value with the number of requests in each group.
The Kusto Query Language (KQL) query uses the summarize operator, which acts as a grouping and aggregation mechanism.
summarize request_count = count() by resultCode
This groups all the individual rows in the requests table by their unique resultCode. It then counts the total number of logs within each group and places that value into a new column called request_count.
order by request_count desc: This sorts those aggregated rows so that the resultCode with the highest number of requests appears at the top.
Incorrect:
* The result codes are sorted alphabetically.
* The query lists every individual request along with its result code.
Reference:
https://learn.microsoft.com/en-us/azure/azure-monitor/reference/tables/apprequests
質問 # 57
Drag and Drop Question
You are developing a .NET application that uses Azure Cosmos DB for NoSQL to store application data.
The application uses the Azure Cosmos DB for NoSQL SDK to interact with the database account.
The application must perform the following tasks:
- Initialize the connection by using the account endpoint and key.
- Define shared throughput.
- Perform create, read, update, and delete (CRUD) operations on items
stored in a container.
You need to implement the SDK components required for the application to access and manage data in Azure Cosmos DB for NoSQL.
Which SDK components should you use? To answer, move the appropriate components to the correct requirements. You may use each component once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.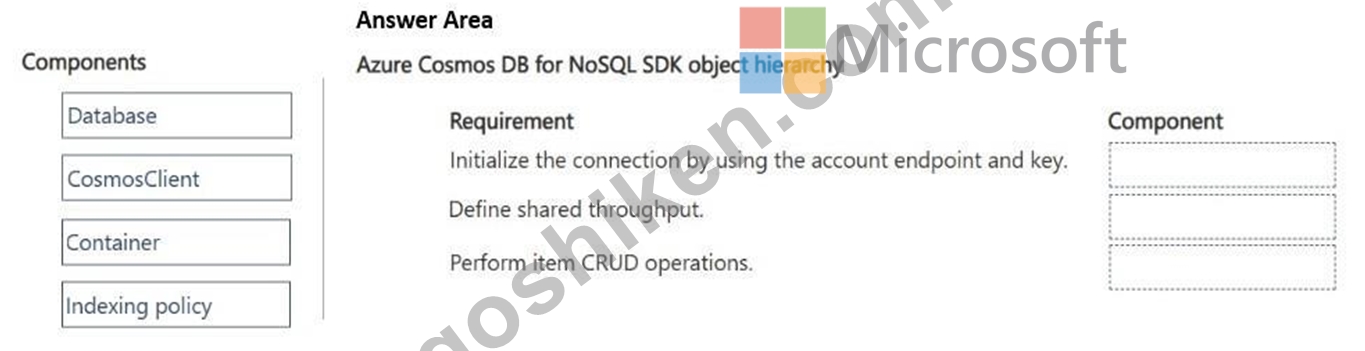
正解:
解説: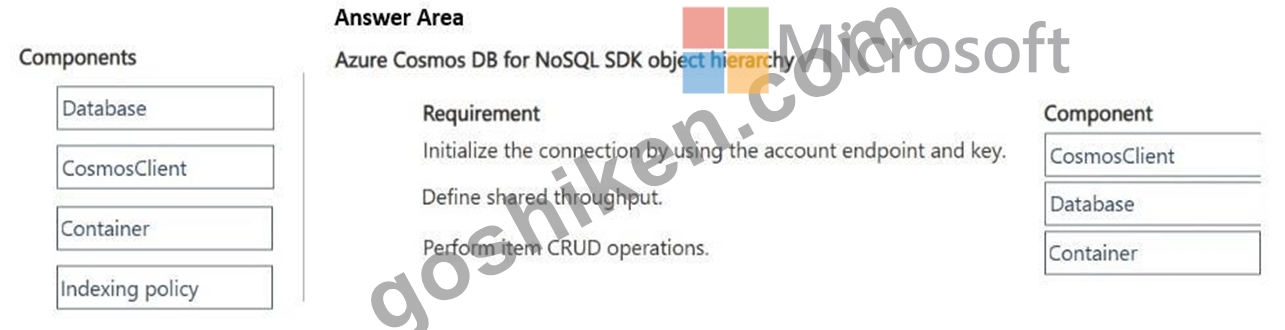
Explanation:
Box 1: CosmosClient
To initialize the connection to an Azure Cosmos DB for NoSQL account using the account endpoint and key, you must use the CosmosClient class.
Box 2: Database
The database SDK component should be used to define shared throughput.
In Azure Cosmos DB, shared throughput (provisioned Request Units per second or RU/s) is configured at the database level. When throughput is provisioned on a database, that capacity is shared among all the containers created within that specific database.
Box 3: Container
To perform item create, read, update, and delete (CRUD) operations, you should use the Container SDK component In the Azure Cosmos DB for NoSQL SDK for .NET, individual JSON documents (items) live inside a container. The Container class exposes the specific methods required to execute CRUD operations on these items.
Reference:
https://learn.microsoft.com/en-us/azure/cosmos-db/how-to-dotnet-get-started
質問 # 58
You deploy multiple instances of a change feed processor to handle a high ingestion rate within Azure Cosmos DB for NoSQL.
Each processor instance must process a different subset of partitions.
You need to ensure the workload is load-balanced across all processor instances.
What should you configure?
正解:B
質問 # 59
......
まず、3つの異なるバージョン(PDF、PC、APPオンラインバージョンのAI-200トレーニングガイド)を使用して、AI-200スタディトレントを最大限に活用できます。各バージョンについて、学習資料をダウンロードする場合、制限とアクセス許可はありません。同時に、人数は制限されていません。 AI-200学習教材を購入した後、AI-200学習教材がオーダーメイドであることを保証します。最後になりましたが、AI-200試験問題の無料試用サービスを提供できます。
AI-200日本語参考: https://www.goshiken.com/Microsoft/AI-200-mondaishu.html