TorrentValid provides you not only with the best materials and also with excellent service. If you buy TorrentValid questions and answers, free update for one year is guaranteed. So, you can always have the latest test materials. You fail, after you use our Microsoft AI-200 Dumps, 100% guarantee to FULL REFUND. With it, what do you worry about? TorrentValid has a lot of confidence in our dumps and you also faith in our TorrentValid. In order to success, don't miss TorrentValid. If you miss TorrentValid, you will miss a chance to embrace the success.
| Section | Weight | Objectives |
|---|---|---|
| Secure, monitor, and optimize AI solutions | 20% | - Implement observability and reliability
|
| Develop containerized AI solutions on Azure | 25% | - Monitor and troubleshoot containerized workloads
|
| Develop AI solutions using Azure data services | 30% | - Implement vector-enabled databases
|
| Integrate backend services and build event-driven architectures | 25% | - Implement messaging and event systems
|
>> Latest Microsoft AI-200 Test Questions <<
About the oncoming AI-200 exam, every exam candidates are wishing to utilize all intellectual and technical skills to solve the obstacles ahead of them to go as well as it possibly could. So the pending exam causes a panic among the exam candidates. The AI-200 exam prepare of our website is completed by experts who has a good understanding of real exams and have many years of experience writing AI-200 Study Materials. They know very well what candidates really need most when they prepare for the exam. They also understand the real exam situation very well. So they compiled AI-200 exam prepare that they hope to do their utmost to help candidates pass the exam and get what job they want.
NEW QUESTION # 114
You are implementing semantic retrieval in Redis.
The solution must support low-latency, approximate nearest neighbor (ANN) vector similarity search for large-scale AI retrieval workloads.
You need to select the appropriate vector schema settings.
Which configuration values should you select? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.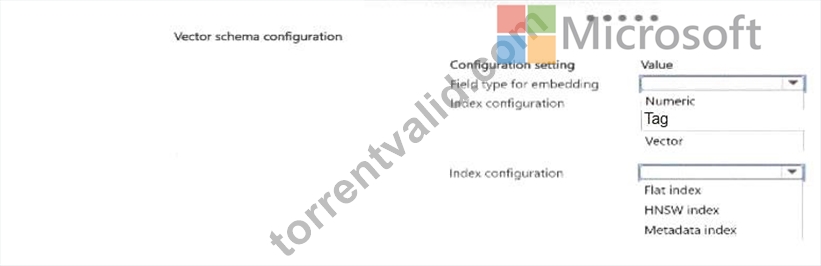
Answer:
Explanation: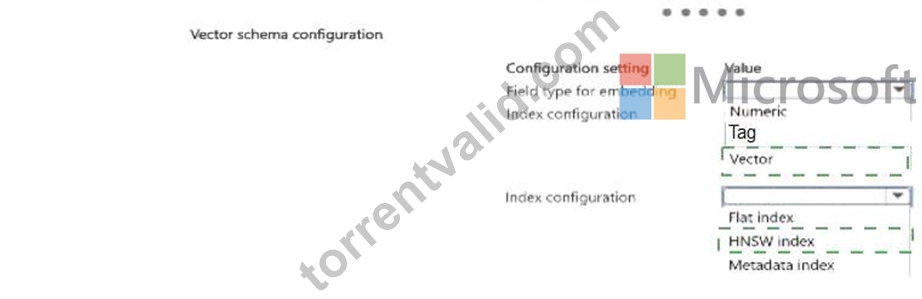
Explanation: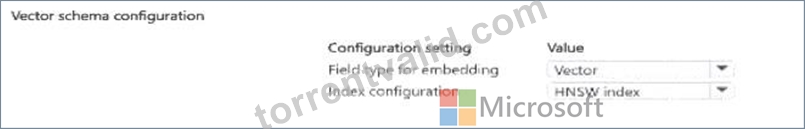
NEW QUESTION # 115
You plan to deploy a container to an Azure App Service API app named api1. You host the source code for api1 in a GitHub repository. The container uses the API key at runtime to connect to a backend service.
The container must be able to retrieve the API key at runtime without exposing it in the source repository or Git commit history. The API key must not be stored in application configuration directly. The API key must be accessed securely from Azure Key Vault.
You need to ensure that the API key is stored securely in Azure Key Vault and is available to the container at runtime without being exposed in source control or Git commit history.
Solution: Store the API key as an App Service application setting configured through the Azure Portal.
Does the solution meet the goal?
Answer: B
NEW QUESTION # 116
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
Hotspot Question
You need to optimize secure database connectivity from the containerized Recommendation API.
How should you configure the application? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.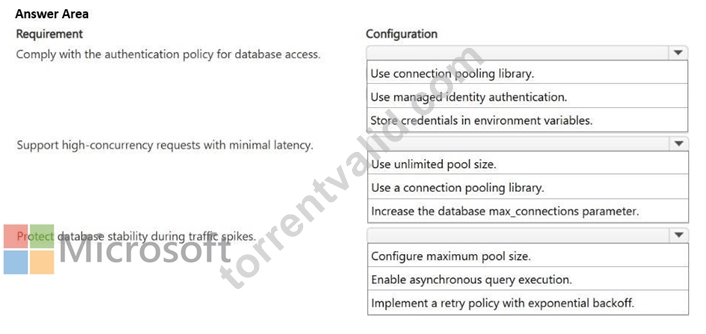
Answer:
Explanation: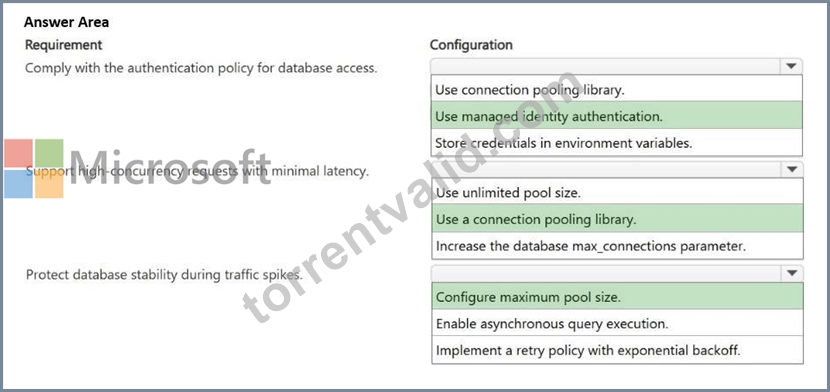
Explanation:
Box 1: Use managed identity authentication.
Scenario: Identity: Use managed identities for all service-to-service and service-to-database authentication. Plain-text credentials in configuration files are strictly prohibited.' Box 2: Use a connection pooling library Scenario: Environment: Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
To support high-concurrency requests with minimal latency on Azure Database for PostgreSQL, the best action is to use a connection pooling library (or leverage Azure's built-in PgBouncer feature).
Eliminates Connection Overhead:
PostgreSQL utilizes a process-per-connection model. Forking a new backend process for every incoming request introduces substantial CPU and memory overhead, severely degrading latency under high concurrency. A connection pool keeps a warm set of reusable database sessions active.
Optimized for Azure: Microsoft provides a built-in managed PgBouncer integration for Azure Database for PostgreSQL. Enabling it in transaction mode allows the database to accept thousands of concurrent client connections while keeping actual backend processes lean and stable Box 3: Configure a maximum pool size Configure a maximum pool size is the best action to directly protect database stability during sudden traffic spikes.
Prevents Resource Exhaustion: Traffic spikes naturally lead to a surge in connection requests.
Unchecked connections consume substantial RAM and CPU overhead, which can crash the database or trigger severe latency. Limiting the pool size stops the "thundering herd" problem Acts as a Shock Absorber: When the pool hits its maximum limit, extra client requests are safely queued at the application or connection pooling layer (like Azure's built-in PgBouncer proxy) rather than overwhelming the database backend Reference:
https://docs.azure.cn/en-us/postgresql/connectivity/concepts-pgbouncer
https://learn.microsoft.com/en-au/answers/questions/5884412/best-practise-azure-postgresql-flexible-server-max
NEW QUESTION # 117
Hotspot Question
You are creating an Azure Functions app project in your local development environment by using Azure Functions Core Tools.
You must create the project in either Python or C# without using a template.
You need to specify the command and its parameter required to create the Azure Functions app project.
Which command and parameter should you specify? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.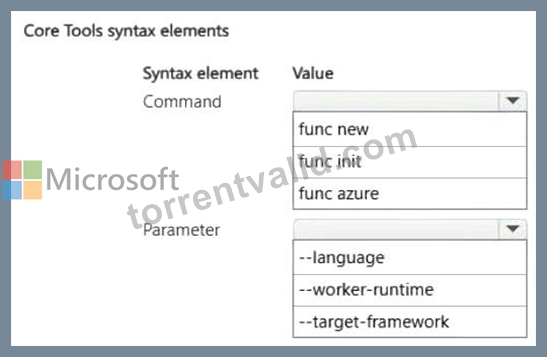
Answer:
Explanation: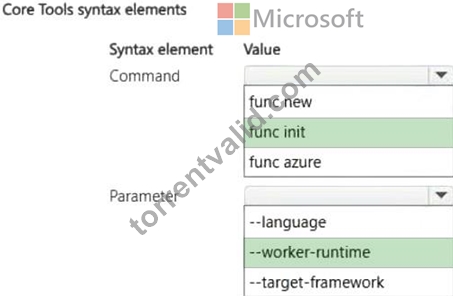
Explanation:
Box 1: func init
To initialize a new Azure Functions app project from the command line using Azure Functions Core Tools without using a specific code template, use the func init command combined with the -
-worker-runtime parameter.
Box 2: --worker-runtime
Reference:
https://r-vm.com/python-on-azure-functions
NEW QUESTION # 118
You are developing an AI application. The application configuration will depend on a dynamically retrieved value of a designated key stored in an Azure App Configuration resource.
You must deploy the application to the test, staging, and production environments.
You need to be able to set the value differently in each environment.
Which feature of Azure App Configuration resource should you use?
Answer: B
Explanation:
You should use the Label feature of the Azure App Configuration resource.
In Azure App Configuration, keys can optionally include a label, which acts as a dimension or tag to create distinct variants of the same key. This allows you to store environment-specific values (such as test, staging, and production) under a single key name and load the appropriate configuration dynamically based on the current deployment environment.
References:
https://learn.microsoft.com/en-us/answers/questions/2108879/azure-app-configuration-resource-manager-api-is-de
NEW QUESTION # 119
......
Our AI-200 exam torrent has a high quality that you can’t expect. I think our Developing AI Cloud Solutions on Azure prep torrent will help you save much time, and you will have more free time to do what you like to do. I can guarantee that you will have no regrets about using our AI-200 Test Braindumps When the time for action arrives, stop thinking and go in, try our AI-200 exam torrent, you will find our products will be a very good choice for you.
Reliable AI-200 Braindumps: https://www.torrentvalid.com/AI-200-valid-braindumps-torrent.html