P.S. JPNTestがGoogle Driveで共有している無料かつ新しいSPS-C01ダンプ:https://drive.google.com/open?id=11NX8jn0-MeEi5aFs1KAzdR87JD4DmTYN
現在、どの領域にでも勉強して努力する必要があります。IT業界でも同じです。Snowflakeに関する仕事をしている人たちはさまざまな認証試験に参加して自分の知識を補充し、よく働く必要があります。SPS-C01試験に合格するのはあなたの能力を証明して、質素を高めることができます。
| Section | Weight | Objectives |
|---|---|---|
| Snowpark API for Python | 30% | - Reading and writing data - User-Defined Functions (UDFs) and Stored Procedures - Working with Semi-structured data - Establishing connections and session management - DataFrame creation and manipulation |
| Snowpark Concepts | 15% | - Stored procedures and conditional logic - Transformations vs. Actions - Client-side vs. Server-side execution - Snowpark DataFrames and query plans - Snowpark architecture and core concepts - Snowpark Sessions and connection management |
| Data Transformations and DataFrame Operations | 35% | - Complex data pipelines - Window functions - Persisting transformed data - Using built-in functions - Filtering, Aggregating, and Joining DataFrames |
| Performance Optimization and Best Practices | 20% | - Caching strategies - Query pushdown and optimization - Warehouse sizing for Snowpark - Minimizing data transfer - Debugging and explain plans - Vectorized UDFs |
より多くの時間を節約できるように、お支払い後10分以内にSPS-C01テストガイドをオンラインでお送りします。時間の無駄を避けるため、できるだけ早くこれらのSPS-C01トレーニング資料を学習できることを保証いたします。私たちSnowflakeは、時間は世界で最も貴重なものだと信じています。これが、Snowflake Certified SnowPro Specialty - Snowpark学習効率と生産性の向上に専念する理由です。 SPS-C01調査の質問の利点をいくつかご紹介します。SPS-C01の質問をご覧ください。
質問 # 364
You have a Snowpark DataFrame with columns 'sale_date', 'product_id', and 'revenue'. You need to calculate the cumulative revenue for each product over time. Which of the following approaches will accomplish this in Snowpark using window functions?





正解:A、D
解説:
Options A and E both achieve the desired result of calculating cumulative revenue for each product. Option A utilizes 'rowsBetween' specifying that the window frame should include all rows from the beginning ('Window.unboundedPreceding') up to the current row ('Window.currentRow'). This calculates a running sum of revenue for each product over time. Option E uses 'rangeBetween' , which is equivalent to when the order-by expression is of a numeric or date type. Option B does not partition by product_id, so the cumulative revenue is calculated over the entire dataset. Option C does not include frame specification 'rowsBetween()' or 'rangeBetween(Y , therefore defaults to 'RANGE BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW, which is valid for this question. While it's functionally correct, it's implicit, so 'A' is preferrable if one option is to be selected. Option D partitions incorrectly by sale_date.
質問 # 365
You have a Snowpark DataFrame named 'transactions' containing transaction data'. You need to create a UDTF using Python to categorize transactions into 'High Value', 'Medium Value', and 'Low Value' based on the transaction amount and the customer's region. The categorization logic requires access to a dynamically updated lookup table stored in a Snowflake stage. Which approach would be MOST efficient and scalable, minimizing data transfer and maximizing Snowpark's vectorized operations?
正解:B
解説:
A vectorized UDF is the most efficient approach. It allows processing data in batches using pandas DataFrames, leveraging vectorized operations for faster execution. Loading the lookup table once during initialization and reusing it avoids repeated data transfer. While option E sounds appealing, caching mechanisms can get complex to manage for data recency. Snowflake stages are generally more suitable as temporary lookup tables rather than permanent caching solution as they're design for data loading operations.
質問 # 366
You are developing a Snowpark application to process large datasets. You want to leverage asynchronous jobs to improve performance and prevent blocking the main thread. You have the following code snippet: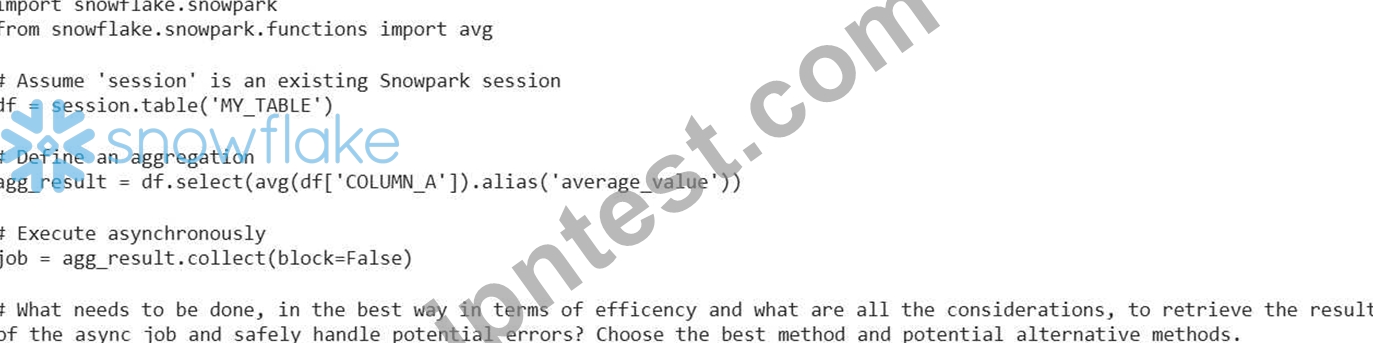
正解:B
解説:
Option D is the most robust and recommended approach for handling asynchronous Snowpark jobs. Using callback functions allows for non-blocking execution and proper error handling. ensures that the main thread doesn't proceed until the asynchronous job has completed. Option B, while functionally correct, introduces inefficient polling. Options A and C lack comprehensive error handling or assume error handling behavior that Snowflake doesn't provide directly. Option E bypasses the Snowpark API and introduces unnecessary complexity.
質問 # 367
You are working with a Snowpark DataFrame containing website traffic data'. The DataFrame has columns like 'date' , 'page_url', and 'visit_count'. You need to calculate the cumulative sum of visit counts for each 'page_url' over time (i.e., ordered by 'date'). However, you only want to consider data from the last 30 days for each calculation. Which of the following Snowpark code snippets will correctly achieve this using window functions with a frame specification?





正解:B
解説:
Option B is correct because it uses 'rangeBetween(-30, 0)' which specifies a frame that includes all rows within a range of 30 days preceding the current row, based on the ordering defined by the "date" column. Since 'date' column is used for ordering, we need to use rangeBetween' and NOT 'rowsBetween' . Also, we need to use 'sf.sum()' for Snowflake functions'. If the column is of Timestamp type, 'rangeBetween' represents days only, and in case it's numeric type represents numeric interval. Option A calculates the cumulative sum from the beginning of time for each page URL. Option C doesn't correctly specify the end of the frame. Option D has incorrect syntax and may not work. Option E uses incorrect sum function as well, as it misses sf prefix.
質問 # 368
You are building a Snowpark application that requires you to connect to Snowflake from an environment where directly specifying credentials in the code is not permitted for security reasons. Which of the following are valid and recommended ways to securely pass authentication information to the Snowpark Session?
正解:A、B、C
解説:
Options A, C, and D represent valid ways to handle credentials securely. Environment variables (A) are a standard practice for configurations. Using a secret management service (C) provides the best security posture for production environments. Using the Snowflake CLI (D) is acceptable for development. Storing credentials in a Snowflake stage (B) adds unnecessary complexity and doesn't inherently improve security over other options. Base64 encoding (E) is not a secure method; it's easily decoded and provides a false sense of security. Hardcoding and obfuscating credentials is not recommended.
質問 # 369
......
当社のSPS-C01学習教材を購入したこれらの人々を支援するために、当社が提供するSPS-C01学習教材の更新と更新を担当する当社の専門家チームがあります。弊社からSPS-C01学習教材を購入したいお客様と永続的かつ持続可能な協力関係を築くことをお約束します。 SPS-C01学習教材を購入する場合、重要な情報を見逃すことはありません。さらに、更新システムが無料であることをお約束します。
SPS-C01最新試験情報: https://www.jpntest.com/shiken/SPS-C01-mondaishu
BONUS!!! JPNTest SPS-C01ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=11NX8jn0-MeEi5aFs1KAzdR87JD4DmTYN