Do you like to practice study materials on paper? If you do, you can try our Databricks-Certified-Professional-Data-Engineer exam dumps. Databricks-Certified-Professional-Data-Engineer PDF version is printable, and you can study anywhere and anytime. We offer you free demo for you to have a try before buying, so that you can have a better understanding of Databricks-Certified-Professional-Data-Engineer Exam Dumps what you are going to buy. Free update for 365 days is available, and you can get the latest information about the Databricks-Certified-Professional-Data-Engineer exam dumps timely. The update version will be sent to your email automatically.
| Section | Weight | Objectives |
|---|---|---|
| Data Ingestion | 15-20% | - Batch ingestion methods
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
| Data Processing with Spark | 25-30% | - Python and SQL for data engineering
|
| Delta Lake | 20-25% | - Delta Lake operations
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
>> Valid Exam Databricks-Certified-Professional-Data-Engineer Preparation <<
Once you decide to pass the Databricks Certified Professional Data Engineer Exam exam and get the certification, you may encounter many handicaps that you don’t know how to deal with, so, you may think that it is difficult to pass the exam and get the certification. In order to help you solve these problem and help you pass the exam easy, we complied such a Databricks-Certified-Professional-Data-Engineer exam torrent. We can promise that you will have no regret buying our Databricks Certified Professional Data Engineer Exam exam dumps. If you are hesitating to buy our Databricks-Certified-Professional-Data-Engineer Test Quiz, if you are anxious about whether our product is suitable for you or not, we think you can download the trail version. We believe our Databricks Certified Professional Data Engineer Exam exam dumps will help you make progress and improve yourself.
NEW QUESTION # 65
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed: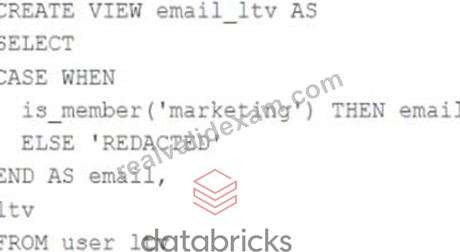
An analyst who is not a member of the marketing group executes the following query:
SELECT * FROM email_ltv
Which statement describes the results returned by this query?
Answer: E
Explanation:
The code creates a view called email_ltv that selects the email and ltv columns from a table called user_ltv, which has the following schema: email STRING, age INT, ltv INT. The code also uses the CASE WHEN expression to replace the email values with the string "REDACTED" if the user is not a member of the marketing group. The user who executes the query is not a member of the marketing group, so they will only see the email and ltv columns, and the email column will contain the string "REDACTED" in each row. Verified Reference: [Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under "CASE expression" section.
NEW QUESTION # 66
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non- overlapping five-minute interval. Events are recorded once per minute per device.
df has the following schema: device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT Code block:
df.withWatermark("event_time", "10 minutes")
.groupBy(
________,
"device_id"
)
.agg(
avg("temp").alias("avg_temp"),
avg("humidity").alias("avg_humidity")
)
.writeStream
.format("delta")
.saveAsTable("sensor_avg")
Which line of code correctly fills in the blank within the code block to complete this task?
Answer: C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
* Exact extract: "window(timeColumn, windowDuration[, slideDuration]) returns a time window for grouping on event-time."
* Exact extract: "If slideDuration is not specified the windows are non-overlapping (tumbling) with length windowDuration." References: Structured Streaming window aggregations; Watermarking.
NEW QUESTION # 67
A data engineer wants to create a cluster using the Databricks CLI for a big ETL pipeline. The cluster should have five workers, one driver of type i3.xlarge, and should use the '14.3.x-scala2.12' runtime.
Which command should the data engineer use?
Answer: B
Explanation:
The Databricks CLI allows users to manage clusters using command-line commands. The correct command for creating a cluster follows a specific format.
Key Components in the Command:
Command Type: databricks compute create is the correct syntax for creating a new compute resource (cluster).
Runtime Version: '14.3.x-scala2.12' specifies the Databricks runtime to use.
Workers: --num-workers 5 sets the number of worker nodes to 5.
Node Type: --node-type-id i3.xlarge defines the hardware configuration.
Cluster Name: --cluster-name DataEngineer_cluster assigns a recognizable name to the cluster.
Evaluation of Options:
Option A (databricks clusters create ...)
Incorrect: databricks clusters create is not a valid command in the Databricks CLI v0.205.
The correct CLI command for cluster creation is databricks compute create.
Option B (databricks clusters add ...)
Incorrect: databricks clusters add is not a valid CLI command.
Option C (databricks compute add ...)
Incorrect: databricks compute add is not a valid CLI command.
Option D (databricks compute create ...)
Correct: databricks compute create is the correct command for creating a cluster.
Conclusion:
The correct command to create a cluster with five workers, an i3.xlarge node type, and Databricks runtime 14.3.x-scala2.12 is:
databricks compute create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster Thus, the correct answer is D.
Reference:
Databricks CLI Documentation
NEW QUESTION # 68
The Databricks CLI is used to trigger a run of an existing job by passing the job_id parameter. The response indicating the job run request was submitted successfully includes a field run_id. Which statement describes what the number alongside this field represents?
Answer: C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
Exact extract: "run_id: The canonical identifier of a run."
Exact extract: "Each job run has a unique run_id."
NEW QUESTION # 69
A Delta Lake table representing metadata about content posts from users has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE This table is partitioned by the date column. A query is run with the following filter:
longitude < 20 & longitude > -20
Which statement describes how data will be filtered?
Answer: A
Explanation:
This is the correct answer because it describes how data will be filtered when a query is run with the following filter: longitude < 20 & longitude > -20. The query is run on a Delta Lake table that has the following schema: user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE. This table is partitioned by the date column. When a query is run on a partitioned Delta Lake table, Delta Lake uses statistics in the Delta Log to identify data files that might include records in the filtered range. The statistics include information such as min and max values for each column in each data file. By using these statistics, Delta Lake can skip reading data files that do not match the filter condition, which can improve query performance and reduce I/O costs. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Data skipping" section.
NEW QUESTION # 70
......
Differ as a result the Databricks-Certified-Professional-Data-Engineer questions torrent geared to the needs of the user level, cultural level is uneven, have a plenty of college students in school, have a plenty of work for workers, and even some low education level of people laid off, so in order to adapt to different level differences in users, the Databricks-Certified-Professional-Data-Engineer exam questions at the time of writing teaching materials with a special focus on the text information expression, as little as possible the use of crude esoteric jargon, as much as possible by everyone can understand popular words to express some seem esoteric knowledge, so that more users through the Databricks-Certified-Professional-Data-Engineer Prep Guide to know that the main content of qualification examination, stimulate the learning enthusiasm of the user, arouse their interest in learning.
Vce Databricks-Certified-Professional-Data-Engineer Free: https://www.realvalidexam.com/Databricks-Certified-Professional-Data-Engineer-real-exam-dumps.html