Everyone has the right to pursue happiness and wealth. You can rely on the Databricks-Certified-Professional-Data-Engineer certificate to support yourself. If you do not own one or two kinds of skills, it is difficult for you to make ends meet in the modern society. After all, you can rely on no one but yourself. At present, our Databricks-Certified-Professional-Data-Engineer Study Materials can give you a ray of hope. Even you have no basic knowledge about the Databricks-Certified-Professional-Data-Engineer study materials. You still can pass the Databricks-Certified-Professional-Data-Engineer with the help of our Databricks-Certified-Professional-Data-Engineer learning guide.
Databricks Certified Professional Data Engineer certification is a valuable credential for data engineers who work with Databricks. It demonstrates that the candidate has a deep understanding of Databricks and can use it effectively to solve complex data engineering problems. Databricks Certified Professional Data Engineer Exam certification can help data engineers advance their careers, increase their earning potential, and gain recognition as experts in the field of big data and machine learning.
>> Reliable Databricks-Certified-Professional-Data-Engineer Dumps Questions <<
We promise that you can get through the challenge winning the Databricks-Certified-Professional-Data-Engineer exam within a week. There is no life of bliss but bravely challenging yourself to do better. So there is no matter of course. Among a multitude of Databricks-Certified-Professional-Data-Engineer practice materials in the market, you can find that our Databricks-Certified-Professional-Data-Engineer Exam Questions are the best with its high-quality and get a whole package of help as well as the best quality Databricks-Certified-Professional-Data-Engineer study materials from our services.
Databricks Certified Professional Data Engineer certification exam is designed to test the knowledge and skills of data engineers who work with Databricks. Databricks is a cloud-based platform that provides a unified analytics engine for big data processing and machine learning. It is used by data engineers to manage data pipelines, extract insights from data, and build machine learning models. Databricks Certified Professional Data Engineer Exam certification exam is a comprehensive assessment of the candidate's ability to use Databricks effectively for data engineering tasks.
Databricks, a unified analytics platform provider that helps organizations process and analyze large data sets, offers a certification exam for data engineers called the Databricks Certified Professional Data Engineer. Databricks-Certified-Professional-Data-Engineer Exam is designed to test the skills and knowledge of data engineers in building and managing data pipelines, ETL processes, and data architectures within the Databricks platform. Databricks Certified Professional Data Engineer Exam certification is intended to validate the expertise of data engineers in implementing and managing data projects, and to demonstrate their competency in using the Databricks platform.
NEW QUESTION # 101
Which of the following SQL statements can replace a python variable, when the notebook is set in SQL mode
1.table_name = "sales"
2.schema_name = "bronze"
Answer: E
Explanation:
Explanation
The answer is spark.sql(f"SELECT * FROM {schema_name}.{table_name}")
NEW QUESTION # 102
You are asked to create a model to predict the total number of monthly subscribers for a specific magazine.
You are provided with 1 year's worth of subscription and payment data, user demographic data, and 10 years
worth of content of the magazine (articles and pictures). Which algorithm is the most appropriate for building
a predictive model for subscribers?
Answer: D
NEW QUESTION # 103
The data science team has requested assistance in accelerating queries on free form text from user reviews.
The data is currently stored in Parquet with the below schema:
item_id INT, user_id INT, review_id INT, rating FLOAT, review STRING
The review column contains the full text of the review left by the user. Specifically, the data science team is looking to identify if any of 30 key words exist in this field.
A junior data engineer suggests converting this data to Delta Lake will improve query performance.
Which response to the junior data engineer s suggestion is correct?
Answer: D
Explanation:
Explanation
Converting the data to Delta Lake may not improve query performance on free text fields with high cardinality, such as the review column. This is because Delta Lakecollects statistics on the minimum and maximum values of each column, which are not very useful for filtering or skipping data on free text fields.
Moreover, Delta Lake collects statistics on the first 32 columns by default, which may not include the review column if the table has more columns. Therefore, the junior data engineer's suggestion is not correct. A better approach would be to use a full-text search engine, such as Elasticsearch, to index and query the review column. Alternatively, you can use natural language processing techniques, such as tokenization, stemming, and lemmatization, to preprocess the review column and create a new column with normalized terms that can be used for filtering or skipping data. References:
Optimizations: https://docs.delta.io/latest/optimizations-oss.html
Full-text search with Elasticsearch: https://docs.databricks.com/data/data-sources/elasticsearch.html Natural language processing: https://docs.databricks.com/applications/nlp/index.html
NEW QUESTION # 104
A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.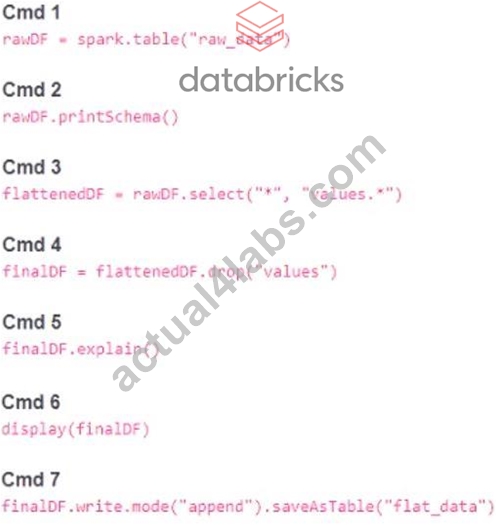
Which command should be removed from the notebook before scheduling it as a job?
Answer: D
Explanation:
Cmd 6 is the command that should be removed from the notebook before scheduling it as a job. This command is selecting all the columns from the finalDF dataframe and displaying them in the notebook. This is not necessary for the job, as the finalDF dataframe is already written to a table in Cmd 7. Displaying the dataframe in the notebook will only consume resources and time, and it will not affect the output of the job.
Therefore, Cmd 6 is redundant and should be removed.
The other commands are essential for the job, as they perform the following tasks:
* Cmd 1: Reads the raw_data table into a Spark dataframe called rawDF.
* Cmd 2: Prints the schema of the rawDF dataframe, which is useful for debugging and understanding the data structure.
* Cmd 3: Selects all the columns from the rawDF dataframe, as well as the nested columns from the values struct column, and creates a new dataframe called flattenedDF.
* Cmd 4: Drops the values column from the flattenedDF dataframe, as it is no longer needed after flattening, and creates a new dataframe called finalDF.
* Cmd 5: Explains the physical plan of the finalDF dataframe, which is useful for optimizing and tuning the performance of the job.
* Cmd 7: Writes the finalDF dataframe to a table called flat_data, using the append mode to add new data to the existing table.
NEW QUESTION # 105
The team has decided to take advantage of table properties to identify a business owner for each table, which of the following table DDL syntax allows you to populate a table property identifying the business owner of a table CREATE TABLE inventory (id INT, units FLOAT)
Answer: C
Explanation:
Explanation
CREATE TABLE inventory (id INT, units FLOAT) TBLPROPERTIES (business_owner = 'supply chain') Table properties and table options (Databricks SQL) | Databricks on AWS Alter table command can used to update the TBLPROPERTIES ALTER TABLE inventory SET TBLPROPERTIES(business_owner , 'operations')
NEW QUESTION # 106
......
Exam Databricks-Certified-Professional-Data-Engineer Duration: https://www.actual4labs.com/Databricks/Databricks-Certified-Professional-Data-Engineer-actual-exam-dumps.html