By focusing on how to help you more effectively, we encourage exam candidates to buy our Databricks-Certified-Data-Engineer-Associate study braindumps with high passing rate up to 98 to 100 percent all these years. Our experts designed three versions for you rather than simply congregate points of questions into Databricks-Certified-Data-Engineer-Associate real questions. Efforts conducted in an effort to relieve you of any losses or stress. So our activities are not just about profitable transactions to occur but enable exam candidates win this exam with the least time and get the most useful contents. We develop many reliable customers with our high quality Databricks-Certified-Data-Engineer-Associate Prep Guide. When they need the similar exam materials and they place the second even the third order because they are inclining to our Databricks-Certified-Data-Engineer-Associate study braindumps in preference to almost any other.
| Section | Objectives |
|---|---|
| Databricks Lakehouse Platform Fundamentals | - Clusters, notebooks, and basic Databricks environment usage - Workspace, architecture, and core platform concepts |
| Data Ingestion and ELT Development | - ETL patterns and transformations - Handling structured and semi-structured data - Data ingestion using Spark SQL and PySpark |
| Productionizing Data Pipelines | - Pipeline deployment and operationalization - Databricks Workflows / Jobs orchestration - Scheduling and monitoring jobs |
| Data Governance and Quality | - Unity Catalog basics - Data quality concepts and management - Data access control and governance |
| Data Processing and Transformations | - Delta Lake fundamentals (tables, transactions, optimization) - User-defined functions (UDFs) - PySpark DataFrame transformations - Apache Spark SQL operations (joins, aggregations, filtering) |
>> New Databricks-Certified-Data-Engineer-Associate Dumps <<
Choose Databricks-Certified-Data-Engineer-Associate exam Topics Pdf to prepare for your coming test, and you will get unexpected results. Databricks-Certified-Data-Engineer-Associate pdf version is very convenient to read and review. If you like to choose the paper file for study, the Databricks-Certified-Data-Engineer-Associate pdf file will be your best choice. The Databricks Databricks-Certified-Data-Engineer-Associate Pdf Dumps can be printed into papers, so that you can read and do marks as you like. Thus when you open your dumps, you will soon find the highlights in the Databricks-Certified-Data-Engineer-Associate papers. What's more, the 99% pass rate can help you achieve your goals.
NEW QUESTION # 23
A data engineer needs to create a table in Databricks using data from their organization's existing SQLite database.
They run the following command: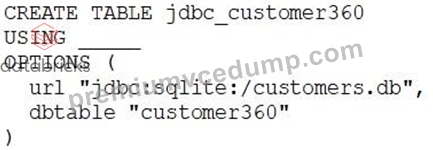
Which of the following lines of code fills in the above blank to successfully complete the task?
Answer: B
NEW QUESTION # 24
A data engineer wants to create a relational object by pulling data from two tables. The relational object does not need to be used by other data engineers in other sessions. In order to save on storage costs, the data engineer wants to avoid copying and storing physical data.
Which of the following relational objects should the data engineer create?
Answer: B
Explanation:
A temporary view is a relational object that is defined in the metastore and points to an existing DataFrame. It does not copy or store any physical data, but only saves the query that defines the view. The lifetime of a temporary view is tied to the SparkSession that was used to create it, so it does not persist across different sessions or applications. A temporary view is useful for accessing the same data multiple times within the same notebook or session, without incurring additional storage costs. The other options are either materialized (A, E), persistent (B, C), or not relational objects . Reference: Databricks Documentation - Temporary View, Databricks Community - How do temp views actually work?, Databricks Community - What's the difference between a Global view and a Temp view?, Big Data Programmers - Temporary View in Databricks.
NEW QUESTION # 25
A data engineer is onboarding a new Bronze ingestion pipeline in Databricks with Unity Catalog. The team wants Databricks to handle storage layout, apply platform optimizations over time, and simplify lifecycle management so that when a table is dropped, its underlying data is also cleaned up according to Databricks- managed retention policies.
Which table type should the data engineer create for these ingestion tables?
Answer: D
Explanation:
Databricks recommends managed tables when you want the platform to control both the table metadata and the underlying storage lifecycle. For Unity Catalog managed tables, Databricks manages storage layout and applies platform-managed optimization features over time. Databricks also documents that when you drop a managed table , the underlying cloud data is deleted automatically after the managed retention period, which simplifies cleanup and reduces storage administration. That behavior matches the requirement exactly.
External tables, by contrast, are used when you want to retain direct control over the storage path and lifecycle. Databricks explicitly states that dropping an external table removes only the metadata and does not delete the underlying files . Foreign tables are for federation scenarios against external systems, not for Bronze ingestion storage managed by Databricks. Temporary views also do not provide the desired governed lifecycle. Because the team wants Databricks-managed storage, managed retention, and simplified lifecycle handling, managed tables are the correct choice for these Bronze ingestion tables.
=========
NEW QUESTION # 26
A Databricks workflow fails at the last stage due to an error in a notebook. This workflow runs daily. The data engineer fixes the mistake and wants to rerun the pipeline. This workflow is very costly and time- intensive to run.
Which action should the data engineer do in order to minimise downtime and cost?
Answer: D
NEW QUESTION # 27
A data engineer has a Python variable table_name that they would like to use in a SQL query. They want to construct a Python code block that will run the query using table_name.
They have the following incomplete code block:
____(f"SELECT customer_id, spend FROM {table_name}")
Which of the following can be used to fill in the blank to successfully complete the task?
Answer: C
NEW QUESTION # 28
......
Though there are three different versions of our Databricks-Certified-Data-Engineer-Associate practice guide to cater to all needs of our worthy customers: the PDF, Software and APP online. I love the Software version the most. The software version of our Databricks-Certified-Data-Engineer-Associate exam questions can be used in the Windows system, which is designed by the experts from our company. The functions of the software version are very special. For example, the software version of our Databricks-Certified-Data-Engineer-Associate Learning Engine can simulate the real exam environment.
Databricks-Certified-Data-Engineer-Associate Interactive Course: https://www.premiumvcedump.com/Databricks/valid-Databricks-Certified-Data-Engineer-Associate-premium-vce-exam-dumps.html