Databricks-Certified-Professional-Data-Engineer Certification Materials & Databricks Free Databricks-Certified-Professional-Data-Engineer Study Material: Databricks Certified Professional Data Engineer Exam Pass for Sure

If you decide to buy our Databricks-Certified-Professional-Data-Engineer study questions, you can get the chance that you will pass your exam and get the certification successfully in a short time. we can claim that if you study with our Databricks-Certified-Professional-Data-Engineer exam questions for 20 to 30 hours, then you will be easy to pass the exam. In a word, if you want to achieve your dream and become the excellent people in the near future, please buy our Databricks-Certified-Professional-Data-Engineer Actual Exam, it will help you get all you want!
| Section | Weight | Objectives |
|---|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Jobs and job scheduling
- 2. Monitoring and alerting
- 3. Task dependencies and orchestration
|
| Data Ingestion | 15-20% | - Batch ingestion methods
- 1. Spark APIs for ingestion
- 2. Integration with external systems
- 3. DBR autoloader
- Streaming ingestion
- 1. Structured streaming fundamentals
- 2. Kafka integration
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Bronze, silver, gold data layers
- 2. Data governance fundamentals
- 3. Differences between data lake, data warehouse, and lakehouse
|
| Data Processing with Spark | 25-30% | - Python and SQL for data engineering
- 1. Spark APIs in Python
- 2. Built-in and user-defined functions
- 3. Performance optimization techniques
- Spark DataFrames and Spark SQL
- 1. Window functions
- 2. DataFrame operations and transformations
- 3. Spark SQL queries and functions
|
| Delta Lake | 20-25% | - Delta Lake fundamentals
- 1. Optimize and Z-order
- 2. ACID transactions
- 3. Time travel and data versioning
- Delta Lake operations
- 1. Merge, update, delete operations
- 2. Schema evolution and enforcement
- 3. Delta Live Tables
|
>> Databricks-Certified-Professional-Data-Engineer Certification Materials <<
Free Databricks Databricks-Certified-Professional-Data-Engineer Study Material | Test Databricks-Certified-Professional-Data-Engineer Simulator
Our Databricks-Certified-Professional-Data-Engineer Study Guide is famous for its instant download, we will send you the downloading link to you once we receive your payment, and you can down right now. Besides the Databricks-Certified-Professional-Data-Engineer study guide is verified by the professionals, so we can ensure that the quality of it. We also have free update, you just need to receive the latest version in your email address. If you don’t have it, you can check in your junk mail or you can contact us.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q191-Q196):
NEW QUESTION # 191
A junior data engineer has configured a workload that posts the following JSON to the Databricks REST API endpoint 2.0/jobs/create.
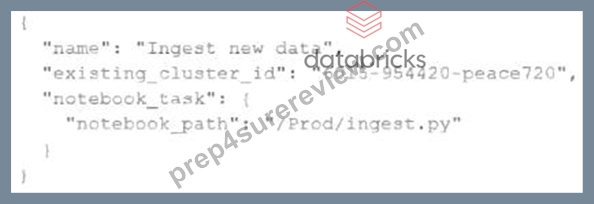
Assuming that all configurations and referenced resources are available, which statement describes the result of executing this workload three times?
- A. Three new jobs named "Ingest new data" will be defined in the workspace, but no jobs will be executed.
- B. Three new jobs named "Ingest new data" will be defined in the workspace, and they will each run once daily.
- C. The logic defined in the referenced notebook will be executed three times on new clusters with the configurations of the provided cluster ID.
- D. The logic defined in the referenced notebook will be executed three times on the referenced existing all purpose cluster.
- E. One new job named "Ingest new data" will be defined in the workspace, but it will not be executed.
Answer: D
Explanation:
This is the correct answer because the JSON posted to the Databricks REST API endpoint 2.0/jobs/create defines a new job with a name, an existing cluster id, and a notebook task. However, it does not specify any schedule or trigger for the job execution. Therefore, three new jobs with the same name and configuration will be created in the workspace, but none of them will be executed until they are manually triggered or scheduled.
Verified References: [Databricks Certified Data Engineer Professional], under "Monitoring & Logging" section; [Databricks Documentation], under "Jobs API - Create" section.
NEW QUESTION # 192
A data team is automating a daily multi-task ETL pipeline in Databricks. The pipeline includes a notebook for ingesting raw data, a Python wheel task for data transformation, and a SQL query to update aggregates. They want to trigger the pipeline programmatically and see previous runs in the GUI. They need to ensure tasks are retried on failure and stakeholders are notified by email if any task fails.
Which two approaches will meet these requirements? (Choose 2 answers)
- A. Use Databricks Asset Bundles (DABs) to deploy the workflow, then trigger individual tasks directly by referencing each task's notebook or script path in the workspace.
- B. Create a multi-task job using the UI, Databricks Asset Bundles (DABs), or the Jobs REST API (/jobs/create) with notebook, Python wheel, and SQL tasks. Configure task-level retries and email notifications in the job definition.
- C. Create a single orchestrator notebook that calls each step with dbutils.notebook.run(), defining a job for that notebook and configuring retries and notifications at the notebook level.
- D. Use the REST API endpoint /jobs/runs/submit to trigger each task individually as separate job runs and implement retries using custom logic in the orchestrator.
- E. Trigger the job programmatically using the Databricks Jobs REST API (/jobs/run-now), the CLI (databricks jobs run-now), or one of the Databricks SDKs.
Answer: B,E
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Databricks Jobs supports defining multi-task workflows that include notebooks, SQL statements, and Python wheel tasks. These can be configured with retry policies, dependency chains, and failure notifications. The correct practice, as stated in the documentation, is to use the Jobs REST API (/jobs/create) or Databricks Asset Bundles to define multi-task jobs, and then trigger them programmatically using /jobs/run-now, CLI, or SDK. This allows the team to maintain full job history, handle retries automatically, and receive alerts via configured email notifications. Using /jobs/runs/submit creates one-off ad hoc runs without maintaining dependency visibility. Therefore, options B and C together satisfy the operational, automation, and governance requirements.
NEW QUESTION # 193
What is true for Delta Lake?
- A. Z-ORDER can only be applied to numeric values stored in Delta Lake tables.
- B. Views in the Lakehouse maintain a valid cache of the most recent versions of source tables at all times.
- C. Delta Lake automatically collects statistics on the first 32 columns of each table, which are leveraged in data skipping based on query filters.
- D. Primary and foreign key constraints can be leveraged to ensure duplicate values are never entered into a dimension table.
Answer: C
Explanation:
* Delta Lake automatically collects statistics on the first 32 columns of each table. These statistics help optimize query performance through data skipping, which allows Databricks to scan only relevant parts of a table.
* This feature significantly improves query efficiency, especially when dealing with large datasets.
Why Other Options Are Incorrect:
* Option A: Views do not cache the most recent versions of the source table; they are recomputed when queried.
* Option C: Z-ORDER can be applied to any data type, including strings, to optimize read performance.
* Option D: Delta Lake does not enforce primary or foreign key constraints.
Reference: Delta Lake Optimization
NEW QUESTION # 194
The viewupdatesrepresents an incremental batch of all newly ingested data to be inserted or updated in the customerstable.
The following logic is used to process these records.
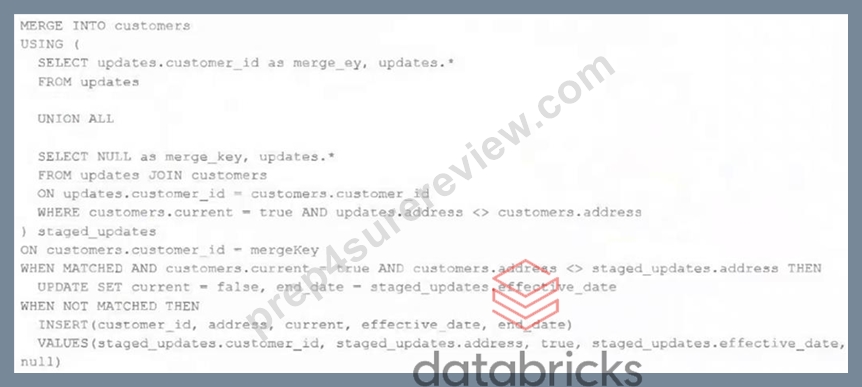
Which statement describes this implementation?
- A. The customers table is implemented as a Type 3 table; old values are maintained as a new column alongside the current value.
- B. The customers table is implemented as a Type 1 table; old values are overwritten by new values and no history is maintained.
- C. The customers table is implemented as a Type 2 table; old values are maintained but marked as no longer current and new values are inserted.
- D. The customers table is implemented as a Type 2 table; old values are overwritten and new customers are appended.
- E. The customers table is implemented as a Type 0 table; all writes are append only with no changes to existing values.
Answer: C
Explanation:
Explanation
The logic uses the MERGE INTO command to merge new records from the view updates into the table customers. The MERGE INTO command takes two arguments: a target table and a source table or view. The command also specifies a condition to match records between the target and the source, and a set of actions to perform when there is a match or not. In this case, the condition is to match records by customer_id, which is the primary key of the customers table. The actions are to update the existing record in the target with the new values from the source, and set the current_flag to false to indicate that the record is no longer current; and to insert a new record in the target with the new values from the source, and set the current_flag to true to indicate that the record is current. This means that old values are maintained but marked as no longer current and new values are inserted, which is the definition of a Type 2 table. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Merge Into (Delta Lake on Databricks)" section.
NEW QUESTION # 195
A table named user_ltv is being used to create a view that will be used by data analysis on various teams.
Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
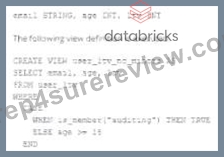
An analyze who is not a member of the auditing group executing the following query:
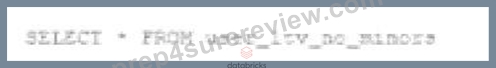
Which result will be returned by this query?
- A. All columns will be displayed normally for those records that have an age greater than 17; records not meeting this condition will be omitted.
- B. All records from all columns will be displayed with the values in user_ltv.
- C. All columns will be displayed normally for those records that have an age greater than 18; records not meeting this condition will be omitted.
- D. All age values less than 18 will be returned as null values all other columns will be returned with the values in user_ltv.
Answer: C
Explanation:
Given the CASE statement in the view definition, the result set for a user not in the auditing group would be constrained by the ELSE condition, which filters out records based on age. Therefore, the view will return all columns normally for records with an age greater than 18, as users who are not in the auditing group will not satisfy the is_member('auditing') condition. Records not meeting the age > 18 condition will not be displayed.
NEW QUESTION # 196
......
Believe it or not, our Databricks-Certified-Professional-Data-Engineer preparation questions will relieve you from poverty. It is important to make large amounts of money in modern society. Our Databricks-Certified-Professional-Data-Engineer practice engine has assisted many people to improve themselves. You also can become the lucky guys as long as you are willing to learn. And with our Databricks-Certified-Professional-Data-Engineer Exam Materials, you will find that to learn something is also a happy and enjoyable experience, and you can be rewarded by the certification as well.
Free Databricks-Certified-Professional-Data-Engineer Study Material: https://www.prep4surereview.com/Databricks-Certified-Professional-Data-Engineer-latest-braindumps.html
- Databricks-Certified-Professional-Data-Engineer 100% Correct Answers ⬅️ Databricks-Certified-Professional-Data-Engineer Exam Discount 🐃 Valid Databricks-Certified-Professional-Data-Engineer Study Guide ⬇ Open website 【 www.examdiscuss.com 】 and search for ☀ Databricks-Certified-Professional-Data-Engineer ️☀️ for free download 🚬Databricks-Certified-Professional-Data-Engineer Valid Exam Bootcamp
- Databricks-Certified-Professional-Data-Engineer bootcamp pdf, Databricks Databricks-Certified-Professional-Data-Engineer dumps pdf ⌨ Go to website 「 www.pdfvce.com 」 open and search for “ Databricks-Certified-Professional-Data-Engineer ” to download for free 🧬Valid Databricks-Certified-Professional-Data-Engineer Study Guide
- www.troytecdumps.com Latest Databricks-Certified-Professional-Data-Engineer Dumps Will Help You Build A SuccessFul Career ⛵ Immediately open [ www.troytecdumps.com ] and search for { Databricks-Certified-Professional-Data-Engineer } to obtain a free download 🕜New Databricks-Certified-Professional-Data-Engineer Study Guide
- Databricks-Certified-Professional-Data-Engineer Exam Discount 🌜 Databricks-Certified-Professional-Data-Engineer Test Quiz 📘 Databricks-Certified-Professional-Data-Engineer Real Question 🖍 Download ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ for free by simply searching on 《 www.pdfvce.com 》 ☔Databricks-Certified-Professional-Data-Engineer Exam Discount
- Exam Databricks-Certified-Professional-Data-Engineer Format 🥏 Databricks-Certified-Professional-Data-Engineer Free Practice Exams 🚧 Databricks-Certified-Professional-Data-Engineer Real Question 🍈 Easily obtain 「 Databricks-Certified-Professional-Data-Engineer 」 for free download through 「 www.examcollectionpass.com 」 🔢Free Databricks-Certified-Professional-Data-Engineer Download Pdf
- Databricks-Certified-Professional-Data-Engineer Certification Materials 😓 Databricks-Certified-Professional-Data-Engineer Certification Materials 🎩 Free Databricks-Certified-Professional-Data-Engineer Updates 🥿 Search for { Databricks-Certified-Professional-Data-Engineer } and easily obtain a free download on { www.pdfvce.com } 🐔Free Databricks-Certified-Professional-Data-Engineer Download Pdf
- New Databricks-Certified-Professional-Data-Engineer Exam Online 🦍 New Databricks-Certified-Professional-Data-Engineer Exam Online 🏺 Exam Databricks-Certified-Professional-Data-Engineer Blueprint 📓 Copy URL 【 www.torrentvce.com 】 open and search for ▷ Databricks-Certified-Professional-Data-Engineer ◁ to download for free 💏Databricks-Certified-Professional-Data-Engineer Exam Discount
- Databricks-Certified-Professional-Data-Engineer bootcamp pdf, Databricks Databricks-Certified-Professional-Data-Engineer dumps pdf 💧 Go to website 【 www.pdfvce.com 】 open and search for ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ to download for free 😒Databricks-Certified-Professional-Data-Engineer Certification Materials
- Desktop Practice Databricks Databricks-Certified-Professional-Data-Engineer Exam Software No Internet Required 💉 Easily obtain ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ for free download through ✔ www.exam4labs.com ️✔️ 🏚Free Databricks-Certified-Professional-Data-Engineer Download Pdf
- Databricks-Certified-Professional-Data-Engineer Exam Discount 📬 Exam Databricks-Certified-Professional-Data-Engineer Format 🏎 Valid Test Databricks-Certified-Professional-Data-Engineer Tutorial 🏆 Search for ✔ Databricks-Certified-Professional-Data-Engineer ️✔️ on 「 www.pdfvce.com 」 immediately to obtain a free download 🐖Free Databricks-Certified-Professional-Data-Engineer Updates
- Databricks-Certified-Professional-Data-Engineer Test Quiz 🚴 Databricks-Certified-Professional-Data-Engineer 100% Correct Answers ⛽ Databricks-Certified-Professional-Data-Engineer Test Quiz 🆘 Search on ⏩ www.examcollectionpass.com ⏪ for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ to obtain exam materials for free download 🦕Valid Databricks-Certified-Professional-Data-Engineer Study Guide
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, startupxplore.com, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes