Implementing Data Engineering Solutions Using Azure Databricks (DP-750) practice test software is another great way to reduce your stress level when preparing for the Microsoft Exam Questions. With our software, you can practice your excellence and improve your competence on the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam dumps. Each Microsoft DP-750 practice exam, composed of numerous skills, can be measured by the same model used by real examiners.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Topic 2: Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Topic 3: Prepare and process data | 30–35% | - Ingest and transform data
|
| Topic 4: Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
There are a lot of experts and professors in our company. All DP-750 study torrent of our company are designed by these excellent experts and professors in different area. We can make sure that our Microsoft DP-750 test torrent has a higher quality than other study materials. The aim of our design is to improving your learning and helping you gains your Implementing Data Engineering Solutions Using Azure Databricks DP-750 Certification in the shortest time. If you long to gain the certification, our Implementing Data Engineering Solutions Using Azure Databricks guide torrent will be your best choice.
NEW QUESTION # 86
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named Catalog 1. Catalog 1 contains a table named Transactions. Transactions contains the following columns:
* transaction_id
* customet_name
* email address
* credit_card_number
* transaction_amount
You need to ensure that business analysts can query all the tows in the Transactions table. The solution must meet the following requirements:
* Prevent the analysts from seeing the full values in the email_address and credit_catd_number columns.
* Ensure that the analysts can see only the values after the @ character in each email address.
* Ensure that the analysts can see only the last four digits of each credit card number.
* Enable the analysts to query the table without errors.
* Follow the principle of least privilege.
What should you do?
Answer: D
Explanation:
The correct answer is C. Column masks are the right tool when you need to partially expose sensitive data rather than hide it entirely. A column mask is a SQL function attached to a column that rewrites the returned value based on who is querying. For email_address, the mask returns only the substring after '@'. For credit_card_number, it returns only the last four digits. Business analysts get useful data without seeing anything sensitive, and they can still query the table without errors.
Option A (row-level filters) controls which rows a user sees, not the values within a row - it can't partially redact a column. Option B (grant SELECT only on non-sensitive columns) removes the columns entirely, so analysts can't see even partial email or card values - that doesn't meet the 'can see only partial values' requirement. Option D (column-level encryption) requires key management infrastructure and decryption at query time, which is significantly more complex than column masking for this use case.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/row-and-column- filters
NEW QUESTION # 87
You have an Azure Databricks workspace
You are creating a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically. You need to configure compute for the pipeline. The solution must minimize operational costs and effort. What should you use?
Answer: C
Explanation:
The correct answer is C - a job cluster that uses autoscaling.
Job clusters (also called pipeline clusters in the SDP context) are created exclusively for a pipeline run and terminated when the pipeline stops. You pay only for what the pipeline uses, and there's no idle cost between runs. Autoscaling on a job cluster lets the pipeline expand during heavy processing and contract during lighter stages - the combination of on-demand lifecycle and elastic scaling gives the lowest operational cost.
Option A (all-purpose cluster) runs at a higher DBU rate and persists beyond the pipeline's lifecycle, meaning you're paying for it even when the pipeline isn't running. Option B (SQL warehouse) is optimised for interactive BI and ad-hoc queries, not for the batch/streaming workloads SDP pipelines run. Option D (single- node all-purpose) has no scaling, runs at the all-purpose DBU rate, and is capped at one node - unsuitable for any production pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/configure-pipeline
NEW QUESTION # 88
You use Declarative Automation Bundles to manage two jobs and an app.
You need to deploy the bundle to development and production environments. The solution must meet the following requirements:
* Deploy the app to both environments.
* Deploy only one job to development.
* Minimize administrative effort.
What should you use?
Answer: A
Explanation:
The targets mapping defines environment-specific deployment configurations within one databricks.yml file.
Development and production targets can apply different resource settings or exclusions while sharing the bundle's common definitions. This allows the app to be deployed to both environments and limits the development deployment to the required job without maintaining duplicate configuration files. Separate YAML files would duplicate shared settings and increase maintenance effort. The resources mapping declares jobs, pipelines, apps, and other Databricks resources but does not independently provide environment-specific deployment behavior. Variables provide reusable values and substitutions; they are not the primary mechanism for defining deployment environments. Declarative Automation Bundle targets are explicitly intended to model configurations such as development, staging, and production in a single bundle. Microsoft Learn
NEW QUESTION # 89
You have an Azure Databricks workspace.
You need to ingest streaming data from Azure Event Hubs by using Apache Spark Structured Streaming The solution must authenticate to Event Hubs and read the event payload.
How should you complete the PySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.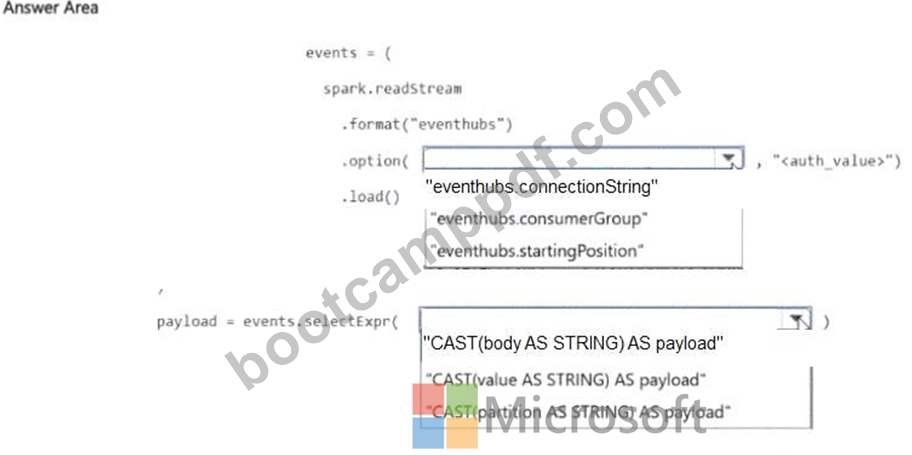
Answer:
Explanation: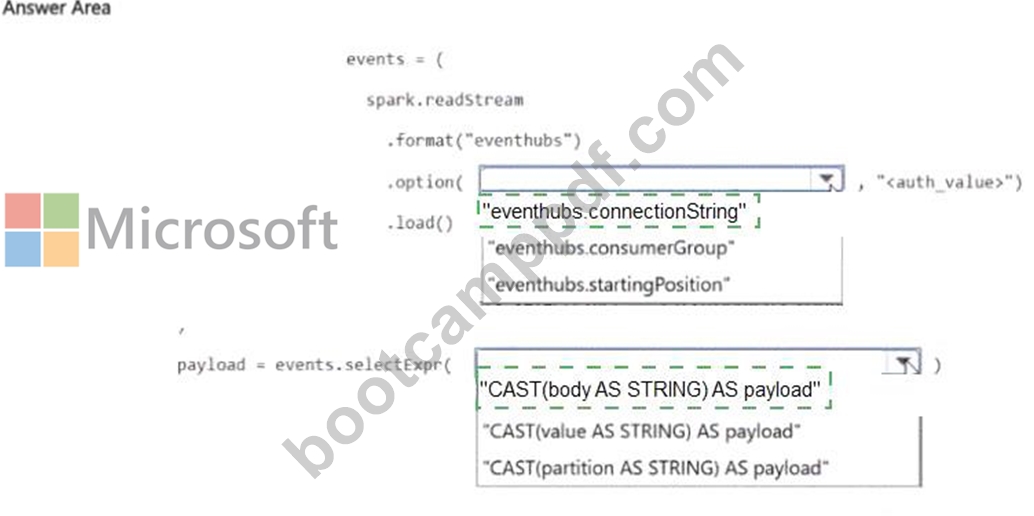
Explanation:
Reading from Azure Event Hubs in Spark Structured Streaming requires three things:
An EventHubsConf object built with the Event Hubs connection string (eventhubs.connectionString). This object is then converted to a map with .toMap before being passed to Spark.
spark.readStream.format( ' eventhubs ' ).options(**ehConf).load() to create the streaming DataFrame. The ' eventhubs ' format is provided by the azure-eventhubs-spark connector library.
A cast( ' string ' ) on the body column to decode the binary payload. Event Hubs delivers messages with the raw event bytes in a column called body - without the cast, you get binary data rather than the readable JSON or text payload.
This is the standard, documented integration pattern for connecting Azure Databricks to Event Hubs with Structured Streaming, providing the checkpoint-based exactly-once semantics required by the Contoso telemetry pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/storage/events/eventhubs
NEW QUESTION # 90
You need to configure compute for the ingestion of telemetry data. The solution must meet the data ingestion and processing requirements.
What should you do?
Answer: D
Explanation:
The correct answer is A. Photon is Azure Databricks ' native vectorized query engine, written in C++, designed to accelerate data ingestion and SQL-heavy workloads significantly over the standard Spark JVM path. Enabling it on a job compute cluster directly addresses Contoso ' s requirement for ' fast and consistent performance for BI workloads ' and ' production ingestion workloads that can scale automatically during telemetry spikes. ' Photon integrates transparently - no code changes are needed - and pairs well with autoscaling job clusters to handle the bursty 40,000-sensor telemetry load.
Option B contradicts the isolation requirement: Contoso explicitly needs production and development separated, not merged onto shared compute. Option C with a fixed large node gives peak capacity at all times, driving up costs even during quiet periods. Option D disabling autoscaling is the opposite of what ' s needed
- telemetry spikes require elastic scaling, not a locked node count.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/photon
NEW QUESTION # 91
......
During your use of our DP-750 learning materials, we also provide you with 24 hours of free online services. Whenever you encounter any DP-750 problems in the learning process, you can email us and we will help you to solve them immediately. And you will find that our service can give you not only the most professional advice on DP-750 Exam Questions, but also the most accurate data on the updates.
Latest DP-750 Exam Notes: https://www.bootcamppdf.com/DP-750_exam-dumps.html