BTW, DOWNLOAD part of Prep4SureReview ARA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1x4I4yKZN43w1rzk6mhh_-BdxtkH42J2c
Our ARA-C01 training materials provide three different versions to the client and they include the PDF version, PC version, APP online version. Each version’s using method and functions are different but the questions and answers of our ARA-C01 Study Materials is the same. The client can decide which version of our ARA-C01 exam questions to choose according their hobbies and their practical conditions.
| Section | Objectives |
|---|---|
| Topic 1: Data Sharing and Collaboration | - Secure data sharing
|
| Topic 2: Data Pipelines and Data Engineering | - Data ingestion and transformation
|
| Topic 3: Data Architecture and Design | - Design scalable Snowflake architectures
|
| Topic 4: Security, Governance, and Compliance | - Access control and security model
|
| Topic 5: Performance and Optimization | - Query performance tuning
|
>> New ARA-C01 Test Materials <<
Best practice indicates that people who have passed the ARA-C01 exam would not pass the exam without the help of the ARA-C01 study materials. So the study materials will be very important for all people. If you also want to pass the exam and get the related certification in a short, the good study materials are the best choice for you. Now we are going to make an introduction about the ARA-C01 Study Materials from our company for you. We sincerely hope that our study materials will help you achieve your dream.
NEW QUESTION # 143
An Architect needs to define a table structure for an unfamiliar semi-structured data set. The Architect wants to identify a list of distinct key names present in the semi-structured objects.
What function should be used?
Answer: D
Explanation:
When working with unfamiliar semi-structured data such as JSON, a common first step is to explore its structure and identify all possible keys. Snowflake's FLATTEN function is specifically designed to explode VARIANT, OBJECT, or ARRAY data into relational form. Using the RECURSIVE option allows FLATTEN to traverse nested objects and arrays, returning all nested keys regardless of depth (Answer A).
This approach enables architects to query and aggregate distinct key names, making it ideal for schema discovery and exploratory analysis. INFER_SCHEMA, by contrast, is used primarily with staged files to infer column definitions for external tables or COPY operations, not for exploring existing VARIANT data already stored in tables. PARSE_JSON simply converts a string into a VARIANT type and does not help identify keys. RESULT_SCAN is used to query the results of a previously executed query and is unrelated to schema discovery.
For SnowPro Architect candidates, this highlights an important semi-structured data design pattern: using FLATTEN (often with RECURSIVE) to explore, profile, and understand evolving data structures before committing to a relational schema or transformation pipeline.
=========
NEW QUESTION # 144
An Architect is using SnowCD to investigate a connectivity issue.
Which system function will provide a list of endpoints that the network must be able to access to use a specific Snowflake account, leveraging private connectivity?
Answer: A
Explanation:
The SYSTEM$GET_PRIVATELINK function is used to retrieve the list of Snowflake service endpoints that need to be accessible when configuring private connectivity (such as AWS PrivateLink or Azure Private Link) for a Snowflake account. The function returns information necessary for setting up the networking infrastructure that allows secure and private access to Snowflake without using the public internet. SnowCD can then be used to verify connectivity to these endpoints.
NEW QUESTION # 145
A user is executing the following command sequentially within a timeframe of 10 minutes from start to finish: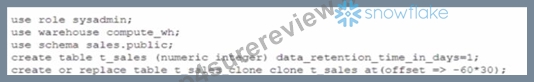
What would be the output of this query?
Answer: A
Explanation:
The query is executing a clone operation on an existing table t_sales with an offset to account for the retention time. The syntax used is correct for cloning a table in Snowflake, and the use of the at(offset => -60*30) clause is valid. This specifies that the clone should be based on the state of the table 30 minutes prior (60 seconds * 30). Assuming the table t_sales exists and has been modified within the last 30 minutes, and considering the data_retention_time_in_days is set to 1 day (which enables time travel queries for the past 24 hours), the table t_sales_clone would be successfully created based on the state of t_sales 30 minutes before the clone command was issued.
NEW QUESTION # 146
An Architect needs to grant a group of ORDER_ADMIN users the ability to clean old data in an ORDERS table (deleting all records older than 5 years), without granting any privileges on the table. The group's manager (ORDER_MANAGER) has full DELETE privileges on the table.
How can the ORDER_ADMIN role be enabled to perform this data cleanup, without needing the DELETE privilege held by the ORDER_MANAGER role?
Answer: A
Explanation:
This is the correct answer because it allows the ORDER_ADMIN role to perform the data cleanup without needing the DELETE privilege on the ORDERS table. A stored procedure is a feature that allows scheduling and executing SQL statements or stored procedures in Snowflake. A stored procedure can run with either the caller's rights or the owner's rights. A caller's rights stored procedure runs with the privileges of the role that called the stored procedure, while an owner's rights stored procedure runs with the privileges of the role that created the stored procedure. By creating a stored procedure that runs with owner's rights, the ORDER_MANAGER role can delegate the specific task of deleting old data to the ORDER_ADMIN role, without granting the ORDER_ADMIN role more general privileges on the ORDERS table. The stored procedure must include the appropriate business logic to delete only the records older than 5 years, and the ORDER_MANAGER role must grant the USAGE privilege on the stored procedure to the ORDER_ADMIN role. The ORDER_ADMIN role can then execute the stored procedure to perform the data cleanup12.
Snowflake Documentation: Stored Procedures
Snowflake Documentation: Understanding Caller's Rights and Owner's Rights Stored Procedures
NEW QUESTION # 147
Company A would like to share data in Snowflake with Company B. Company B is not on the same cloud platform as Company A.
What is required to allow data sharing between these two companies?
Answer: B
Explanation:
Explanation
According to the SnowPro Advanced: Architect documents and learning resources, the requirement to allow data sharing between two companies that are not on the same cloud platform is to set up data replication to the region and cloud platform where the consumer resides. Data replication is a feature of Snowflake that enables copying databases across accounts in different regions and cloud platforms. Data replication allows data providers to securely share data with data consumers across different regions and cloud platforms by creating a replica database in the consumer's account. The replica database is read-only and automatically synchronized with the primary database in the provider's account. Data replication is useful for scenarios where data sharing is not possible or desirable due to latency, compliance, or security reasons1. The other options are incorrect because they are not required or feasible to allow data sharing between two companies that are not on the same cloud platform. Option A is incorrect because creating a pipeline to write shared data to a cloud storage location in the target cloud provider is not a secure or efficient way of sharing data. It would require additional steps to load the data from the cloud storage to the consumer's account, and it would not leverage the benefits of Snowflake's data sharing features. Option B is incorrect because ensuring that all views are persisted is not relevant for data sharing across cloud platforms. Views can be shared across cloud platforms as long as they reference objects in the same database. Persisting views is an option to improve the performance of querying views, but it is not required for data sharing2. Option D is incorrect because Company A and Company B do not need to agree to use a single cloud platform. Data sharing is possible across different cloud platforms using data replication or other methods, such as listings or auto-fulfillment3. References: ReplicatingDatabases Across Multiple Accounts | Snowflake Documentation, Persisting Views | Snowflake Documentation, Sharing Data Across Regions and Cloud Platforms | Snowflake Documentation
NEW QUESTION # 148
......
With limited time for your preparation, many exam candidates can speed up your pace of making progress. Our ARA-C01 study materials will remedy your faults of knowledge understanding. As we know, some people failed the exam before, and lost confidence in this agonizing exam before purchasing our ARA-C01 training guide. Also it is good for releasing pressure. Many customers get manifest improvement and lighten their load with our ARA-C01 exam braindumps. So just come and have a try!
Valid ARA-C01 Exam Question: https://www.prep4surereview.com/ARA-C01-latest-braindumps.html
DOWNLOAD the newest Prep4SureReview ARA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1x4I4yKZN43w1rzk6mhh_-BdxtkH42J2c