Es ist schwierig, Microsoft DP-750 Zertifizierungsprüfung zu bestehen. Sorgen Sie sich um die Vorbereitung der DP-750 Prüfung nach der Anmeldung? Wenn ja, lesen Sie bitte die folgenden Inhalte. Sie können den kürzesten Weg zum Erfolg der DP-750 Prüfung finden, der Ihnen helfen, Microsoft DP-750 Prüfung mit guter Note bestanden. Das ist ja Microsoft DP-750 Dumps von ZertFragen. Wenn Sie diese DP-750 Prüfung sehr leicht bestehen wollen, probieren Sie bitte diese Dumps.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Topic 2: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Topic 3: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 4: Prepare and process data | 30-35% | - Ingest and transform data
|
>> DP-750 Deutsche Prüfungsfragen <<
Wissen Sie Microsoft DP-750 Dumps von ZertFragen? Warum sind diese Dumps von den Benutzern gut bewertet? Wollen Sie diese Dumps probieren? Klicken Sie bitte ZertFragen Website und die Demo herunterladen. Und jedr Fragenkatalog hat eine kostlose Demo. Wenn Sie es gut finden, können Sie diese Dumps sofort kaufen. Nach dem Kauf können Sie auch einen einjährigen kostlosen Aktualisierungsservice bekommen. Innerhalb eines Jahres können Sie die neuesten Microsoft DP-750 Prüfungsunterlagen besitzen. Damit können Sie Microsoft DP-750 Zertifizierungsprüfung sehr leicht bestehen und dieses Zertifikat bekommen.
74. Frage
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.dropna(subset=["order_amount"])
Does this meet the goal?
Antwort: B
Begründung:
Correct:
* You run the following expression.
df.dropna(subset=["order_amount"])
The expression df.dropna(subset=["order_amount"]) is an appropriate and effective way to exclude rows where order_amount is null.
* You run the following expression.
df.filter(df.order_amount.isNotNull())
To exclude rows where the order amount is null, you can use the isNotNull() method or a SQL expression within the filter() or where() functions.Here are the standard, appropriate expressions:
Option 1: Python/PySpark API (Recommended)
pythondf_clean = df.filter(df["order_amount"].isNotNull())
Incorrect:
* You run the following expression.
df.fillna(0, subset=['order_amount'])
* You run the following expression.
df.filter(df.order_amount != None)
Reference:
https://www.geeksforgeeks.org/python/filter-pyspark-dataframe-columns-with-none-or-null-values/
https://learn.microsoft.com/en-us/azure/databricks/pyspark/reference/classes/dataframe/dropna
75. Frage
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! runs every hour.
Occasionally, the job run takes longer than one hour to complete. Overlapping runs must be prevented to avoid data corruption.
You need to configure the job scheduling behavior.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.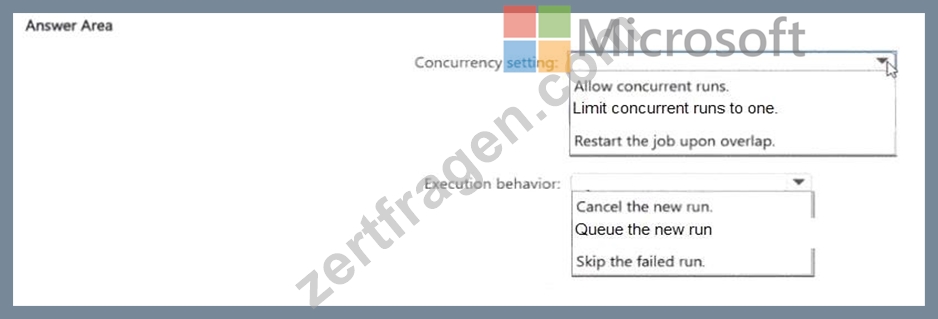
Antwort:
Begründung: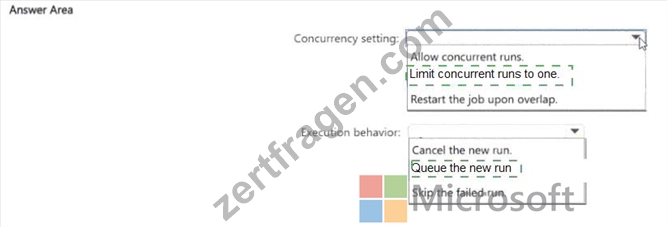
Explanation:
Two settings address the overlapping-run problem:
Concurrent Runs policy set to ' Skip ' (or ' Allow only one concurrent run ' ). When a new scheduled trigger fires while the previous run is still in progress, the new run is skipped rather than starting alongside the ongoing one. This prevents two runs from writing to the same tables at the same time - which is the data corruption risk the question highlights.
Cron-based schedule for the hourly trigger. A cron expression defines the regular execution cadence.
Combined with the concurrency setting, the job runs hourly but never overlaps.
An alternative to ' Skip ' is ' Wait ' (queue the new run), which ensures every scheduled run eventually executes - but for this scenario where overlapping is the primary concern, skipping the missed run is typically preferable to building up a queue of back-to-back executions.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#concurrent-runs
76. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to profile a table to meet the following requirements:
* The count of null values per column must be evaluated repeatedly as new records are added to the table.
* Changes in the count of null values must be observable over the progression of the dataset.
Which type of profile should you create?
Antwort: A
Begründung:
A time series profile repeatedly calculates data-quality metrics as a table changes and preserves those measurements over time. This makes it possible to observe whether the number of null values in each column is increasing, decreasing, or remaining stable as new records are added. A snapshot profile evaluates the table at a particular point in time and is therefore insufficient when the requirement is to analyze metric progression across multiple updates. Inference is associated with deriving information such as a schema or statistical characteristics; it is not the profile type used to maintain a historical sequence of monitoring measurements.
Because the question requires repeated evaluation and the ability to observe changes throughout the dataset's progression, the time series profile satisfies both requirements.
77. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two Delta tables named Table1 and Table2 of the same data type.
Table1 contains a column named Columnl. Table2 contains a column named Column2. You run the following query.
SELECT Column1
FROM Table1
GROUP BY Column1
HAVING COUNT(") > 1
INTERSECT
SELECT C0lumn2
FROM Table2
GROUP BY Column2
HAVING COUNT(') > 1;
What occurs when you run the query?
Antwort: A
Begründung:
The correct answer is B - values appear in both tables more than once.
Reading the query from the inside out: each subquery identifies values that appear more than once within their own table. The first subquery returns Column1 values that are duplicated in Table1. The second returns Column2 values that are duplicated in Table2. INTERSECT then returns only the values that appear in both result sets - meaning values that are duplicated in Table1 AND also duplicated in Table2.
Option A describes a UNION result (values in either table), not INTERSECT. Option C only considers duplicates in Table1, ignoring the Table2 condition - that would be the first subquery in isolation. Option D describes values exclusive to Table2 (EXCEPT or MINUS), the opposite of INTERSECT's requirement that values appear in both sets.
INTERSECT always requires membership in both operands - that's its fundamental definition in standard SQL.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/sql-ref-syntax-qry-select- setops
78. Frage
You have an Azure Databricks job named Job1 that contains an ingestion task named Task1 and transformation task named Task2. You need to ensure that if Task1 fails, the task retries automatically, and Task2 is prevented from running How should you configure Job1? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.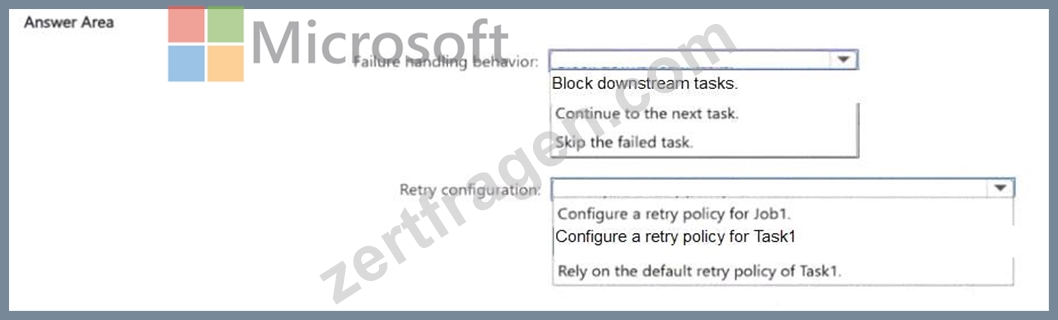
Antwort:
Begründung: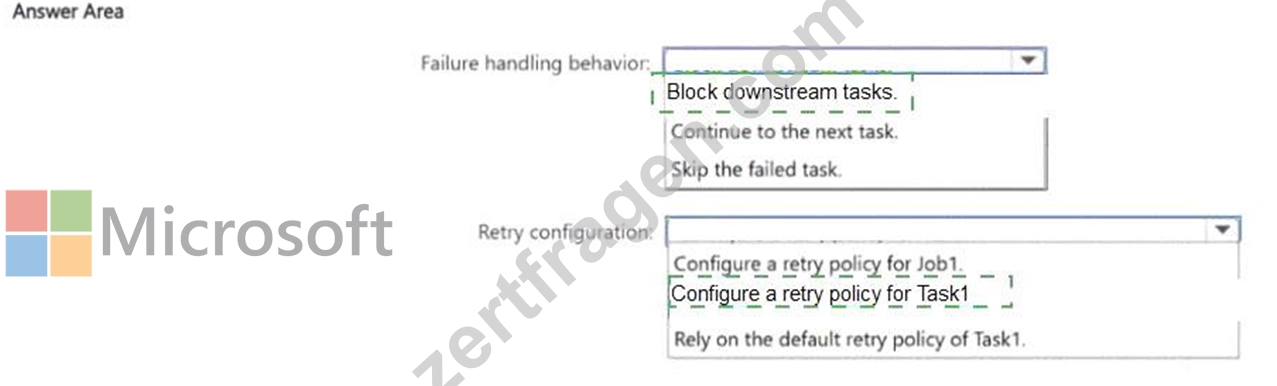
Explanation:
Two task-level settings solve this:
Task1 retry policy: configure Task1 with a maximum number of retries and a retry interval. When Task1 fails, Lakeflow Jobs automatically re-runs it up to the retry limit without any manual intervention. This handles transient infrastructure failures transparently.
Task2 run condition set to 'All succeeded' with Task1 as its dependency: this means Task2 only starts when Task1 has succeeded. If Task1 fails and exhausts all retries, Task2 remains blocked - it never runs on data from a failed upstream ingestion. The dependency is declared in Task2's 'Depends on' setting in the job configuration.
These two settings are independent and composable. Task1's retry policy gives it multiple chances to recover.
Task2's dependency and run condition ensure the downstream transformation only runs on clean, successfully ingested data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#task-retries
79. Frage
......
Das Zertifikat für Microsoft DP-750 beteudet einen neuen Meilenstein im Leben. Mit dem bekommt man mehr berufliche Auftiegschancen und bessere Arbeitsaussichten. Daher träumt jeder IT-Fachmann davon. Es ist allen bekannt, dass solche Microsoft DP-750 Prüfung schwer zu bestehen ist. In der Tat ist es auch so, zahlreiche Prüflinge fallen in der Prüfung durch. Wenn man sich gar nicht um die Prüfung bemüht, fällt einem noch schwerer. Die Microsoft DP-750 Zertifizierungsprüfung verlangt jedoch umfangreiche Fachkenntnisse. Unser ZertFragen bitet Ihnen einen kürzeren Weg zu der Microsoft DP-750 Zertifizierung. Auf unserer Website gibt es viele Prüfungsmaterialien für die Microsoft DP-750 Zertifizierung, die Ihnen zum Bestehen der Prüfung unter Garantie helfen. Außerdem können Sie dabei viel Zeit ersparen. So ist es Ihnen ganz preisgünstig, dass man per ZertFragen mit weniger Zeit und Geld ein wertvolles Zertifikat bekommt.
DP-750 Prüfungsinformationen: https://www.zertfragen.com/DP-750_prufung.html