Our desktop Databricks Databricks-Certified-Professional-Data-Engineer practice exam software is designed for all those candidates who want to learn and practice in the actual Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam environment. This desktop practice exam software completely depicts the Databricks Databricks-Certified-Professional-Data-Engineer Exam scenario with proper rules and regulations so you can practice all the hurdles and difficulties.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Available Languages: | Korean, Portuguese (Brazil), Japanese, English |
| Related Certifications: | Databricks Certified Associate Data Engineer |
| Real Exam Qty: | 59 |
| Exam Format: | Multiple Choice |
| Passing Score: | 70% |
| Exam Duration: | 120 minutes |
| Exam Price: | USD 200 |
| Certificate Validity Period: | 2 years |
| Recommended Training: | Databricks Data Engineer Professional Training |
| Exam Registration: | Databricks Official Certification Registration |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored or onsite test center |
| Pre Condition: | No mandatory prerequisites; 1+ year hands-on experience and related training highly recommended |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-engineer-professional |
>> Databricks-Certified-Professional-Data-Engineer New Question <<
With our numerous advantages of our Databricks-Certified-Professional-Data-Engineer latest questions and service, what are you hesitating for? Our company always serves our clients with professional and precise attitudes, and we know that your satisfaction is the most important thing for us. We always aim to help you pass the Databricks-Certified-Professional-Data-Engineer Exam smoothly and sincerely hope that all of our candidates can enjoy the tremendous benefit of our Databricks-Certified-Professional-Data-Engineer exam material, which might lead you to a better future!
The Databricks Databricks-Certified-Professional-Data-Engineer Exam is designed to test the candidate's ability to work with Databricks in a real-world setting. Candidates are required to demonstrate their ability to design and implement data pipelines that are scalable, efficient, and reliable. They must also be able to troubleshoot issues that arise during the data engineering process and optimize performance to ensure that pipelines run smoothly.
NEW QUESTION # 90
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table named users.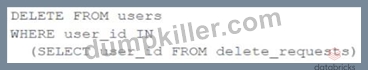
Assuming that user_id is a unique identifying key and that delete_requests contains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
Answer: E
Explanation:
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion. The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Delete from a table" section; Databricks Documentation, under "Remove files no longer referenced by a Delta table" section.
NEW QUESTION # 91
A data engineer manages a production Lakeflow Declarative Pipeline that processes customer transaction data. The pipeline includes several data quality expectations such as transaction_amount > 0 and customer_id IS NOT NULL. These expectations are defined using the EXPECT clause in SQL.
The engineer aims to monitor the pipeline's data quality by analyzing the number of records that passed or failed each expectation during the latest pipeline update. The Lakeflow Declarative Pipelines event logs are stored in a Delta table named event_log_table.
For the most recent pipeline update, determine a programmatically appropriate approach to extract information like the name of each expectation, associated dataset, count of records that passed the expectation, and count of records that failed the expectation.
Which method retrieves the desired data quality metrics from the Lakeflow Declarative Pipelines event log?
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
The Databricks documentation specifies that for Lakeflow Declarative Pipelines, detailed data quality metrics are logged as events of type expectation_result within the event log. Each record of this type contains fields including expectation_name, dataset_name, passed_records, and failed_records. Filtering on event_type = 'expectation_result' and expanding the details field allows retrieving metrics for each expectation from the most recent pipeline update. While flow_progress provides summary statistics and data_quality events aggregate results, only expectation_result events provide granular, per-expectation metrics required for audit and monitoring automation.
NEW QUESTION # 92
Which statement describes the correct use of pyspark.sql.functions.broadcast?
Answer: D
Explanation:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html The broadcast function in PySpark is used in the context of joins. When you mark a DataFrame with broadcast, Spark tries to send this DataFrame to all worker nodes so that it can be joined with another DataFrame without shuffling the larger DataFrame across the nodes. This is particularly beneficial when the DataFrame is small enough to fit into the memory of each node. It helps to optimize the join process by reducing the amount of data that needs to be shuffled across the cluster, which can be a very expensive operation in terms of computation and time.
Thepyspark.sql.functions.broadcastfunction in PySpark is used to hint to Spark that a DataFrame is small enough to be broadcast to all worker nodes in the cluster. When this hint is applied, Spark can perform a broadcast join, where the smaller DataFrame is sent to each executor only once and joined with the larger DataFrame on each executor. This can significantly reduce the amount of data shuffled across the network and can improve the performance of the join operation.
In a broadcast join, the entire smaller DataFrame is sent to each executor, not just a specific column or a cached version on attached storage. This function is particularly useful when one of the DataFrames in a join operation is much smaller than the other, and can fit comfortably in the memory of each executor node.
References:
* Databricks Documentation on Broadcast Joins: Databricks Broadcast Join Guide
* PySpark API Reference: pyspark.sql.functions.broadcast
NEW QUESTION # 93
The data analyst team had put together queries that identify items that are out of stock based on orders and replenishment but when they run all together for final output the team noticed it takes a really long time, you were asked to look at the reason why queries are running slow and identify steps to improve the performance and when you looked at it you noticed all the code queries are running sequentially and using a SQL endpoint cluster. Which of the following steps can be taken to resolve the issue?
Here is the example query
1.--- Get order summary
2.create or replace table orders_summary
3.as
4.select product_id, sum(order_count) order_count
5.from
6. (
7. select product_id,order_count from orders_instore
8. union all
9. select product_id,order_count from orders_online
10. )
11.group by product_id
12.-- get supply summary
13.create or repalce tabe supply_summary
14.as
15.select product_id, sum(supply_count) supply_count
16.from supply
17.group by product_id
18.
19.-- get on hand based on orders summary and supply summary
20.
21.with stock_cte
22.as (
23.select nvl(s.product_id,o.product_id) as product_id,
24. nvl(supply_count,0) - nvl(order_count,0) as on_hand
25.from supply_summary s
26.full outer join orders_summary o
27. on s.product_id = o.product_id
28.)
29.select *
30.from
31.stock_cte
32.where on_hand = 0
Answer: C
Explanation:
Explanation
The answer is to increase the cluster size of the SQL Endpoint, here queries are running sequentially and since the single query can not span more than one cluster adding more clusters won't improve the query but rather increasing the cluster size will improve performance so it can use additional compute in a warehouse.
In the exam please note that additional context will not be given instead you have to look for cue words or need to understand if the queries are running sequentially or concurrently. if the que-ries are running sequentially then scale up(more nodes) if the queries are running concurrently (more users) then scale out(more clusters).
Below is the snippet from Azure, as you can see by increasing the cluster size you are able to add more worker nodes.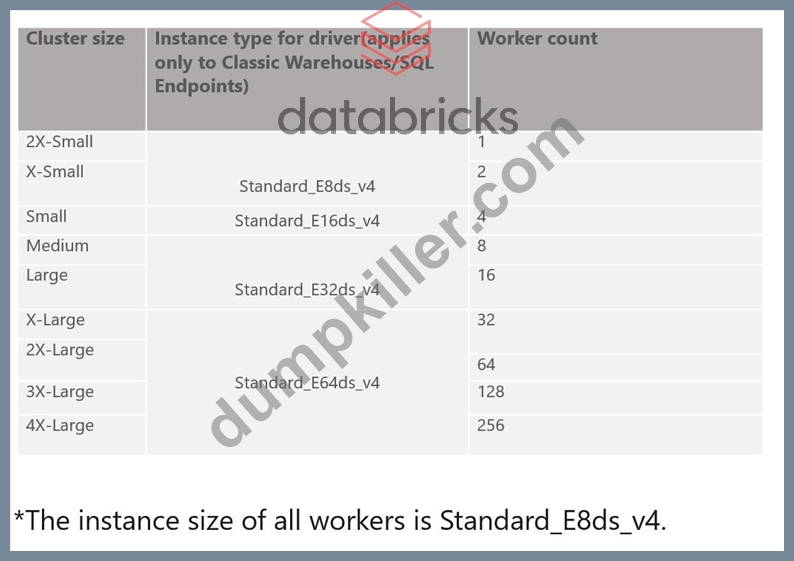
SQL endpoint scales horizontally(scale-out) and vertically (scale-up), you have to understand when to use what.
Scale-up-> Increase the size of the cluster from x-small to small, to medium, X Large....
If you are trying to improve the performance of a single query having additional memory, additional nodes and cpu in the cluster will improve the performance.
Scale-out -> Add more clusters, change max number of clusters
If you are trying to improve the throughput, being able to run as many queries as possible then having an additional cluster(s) will improve the performance.
SQL endpoint
A picture containing diagram Description automatically generated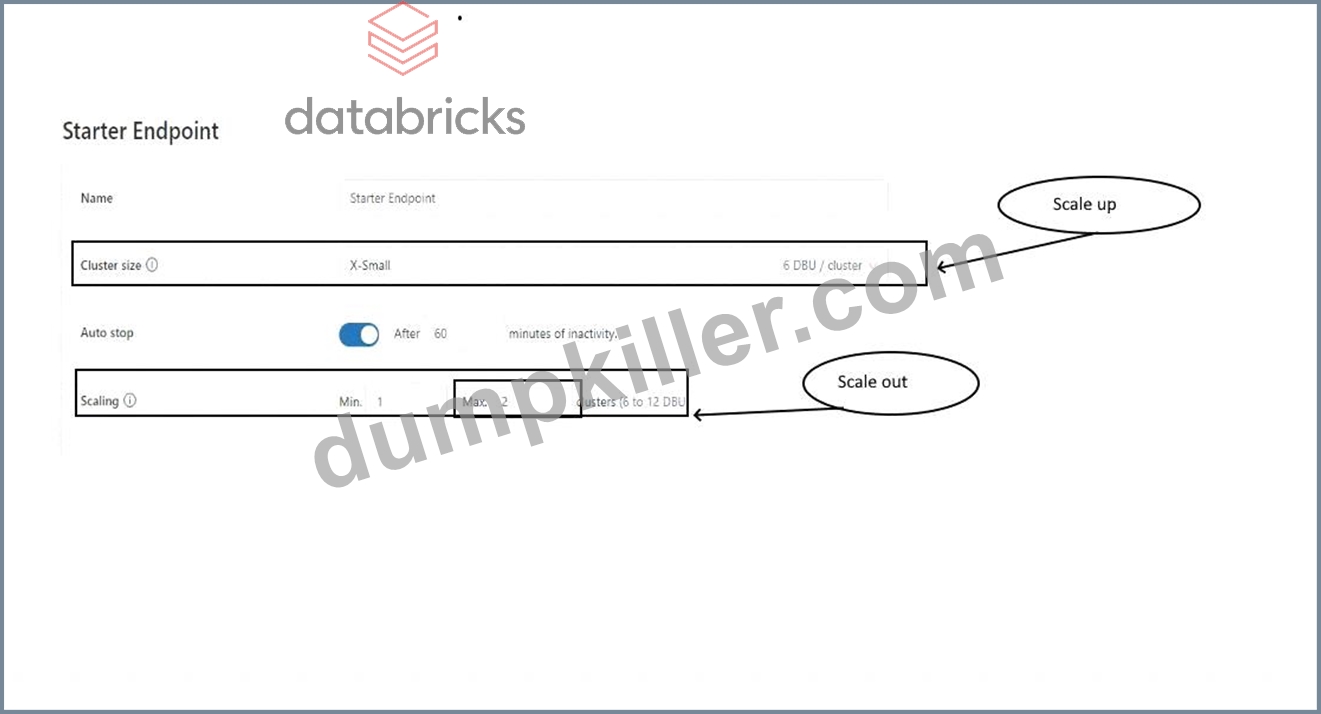
NEW QUESTION # 94
Review the following error traceback: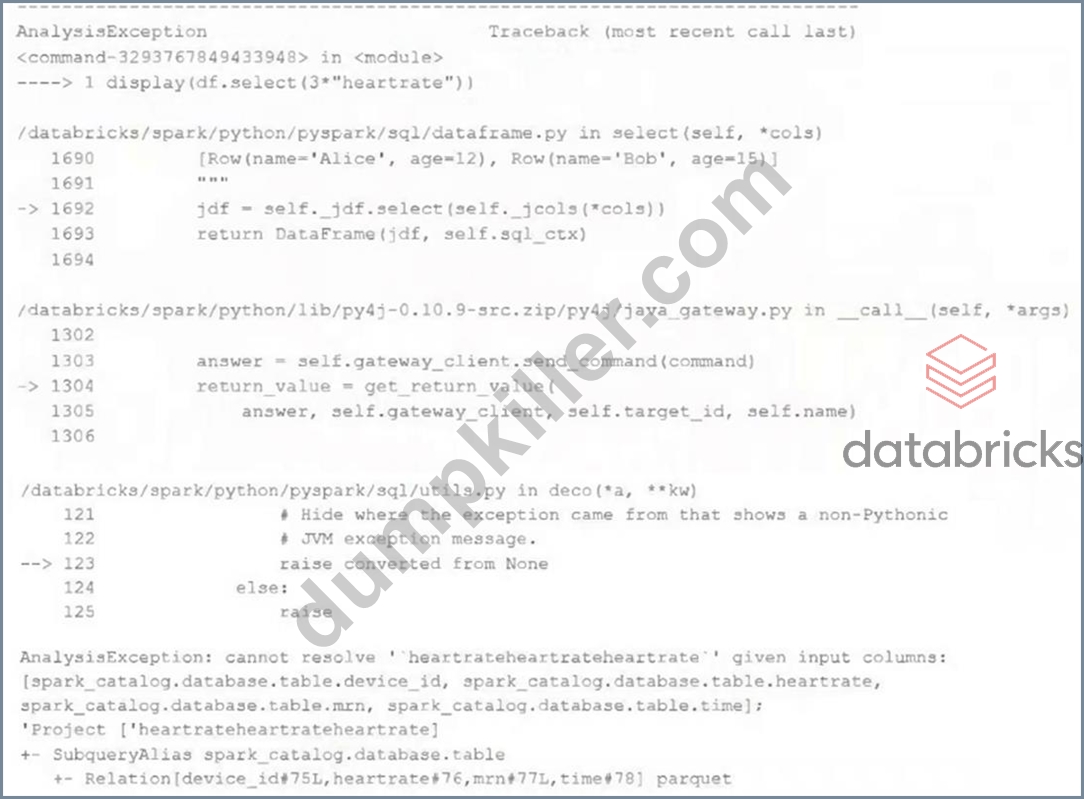
Which statement describes the error being raised?
Answer: C
Explanation:
The error being raised is an AnalysisException, which is a type of exception that occurs when Spark SQL cannot analyze or execute a query due to some logical or semantic error1. In this case, the error message indicates that the query cannot resolve the column name 'heartrateheartrateheartrate' given the input columns 'heartrate' and 'age'. This means that there is no column in the table named 'heartrateheartrateheartrate', and the query is invalid. A possible cause of this error is a typo or a copy-paste mistake in the query. To fix this error, the query should use a valid column name that exists in the table, such as 'heartrate'. Reference: AnalysisException
NEW QUESTION # 95
......
Exam Databricks-Certified-Professional-Data-Engineer Reference: https://www.dumpkiller.com/Databricks-Certified-Professional-Data-Engineer_braindumps.html