Snowflake SPS-C01 Examinations Actual Questions - Test SPS-C01 Engine Version

With the simulation function, our SPS-C01 training guide is easier to understand and have more vivid explanations to help you learn more knowledge. You can set time to test your study efficiency, so that you can accomplish your test within the given time when you are in the Real SPS-C01 Exam. Besides, you can get the real feeling of taking part in the real exam for our SPS-C01 exam questions have the function of simulating the real exam. So that you can have a better performance when you attend the real exam.
| Section | Weight | Objectives |
|---|
| Topic 1: Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
- 1. Transformations vs actions
- 2. Client-side vs server-side processing
- 3. Lazy evaluation and DAG execution
- Session management and connection
- 1. Authentication and connection settings
- 2. Create and configure Snowpark sessions
|
| Topic 2: Snowpark API and Development | 30% | - Python API fundamentals
- 1. DataFrame creation from tables, views, SQL
- 2. Data persistence and writing results
- 3. Column operations and functions
- Multi-language support
- 1. Environment setup and dependencies
- 2. Java and Scala API basics
|
| Topic 3: Data Transformations and Operations | 35% | - User-defined logic
- 1. UDFs, UDAFs, UDTFs
- 2. Stored procedures with Snowpark
- Advanced operations
- 1. Semi-structured data processing
- 2. Window functions and analytics
- 3. Pivot and unpivot transformations
- DataFrame manipulation
- 1. Filtering, sorting, grouping, aggregation
- 2. Joins, unions, set operations
- 3. Selection, projection, renaming, casting
|
| Topic 4: Performance and Best Practices | 10% | - Optimization techniques
- 1. Query pushdown and execution plans
- 2. Caching and warehouse sizing
- 3. Minimizing data movement
- Security and governance
- 1. Data protection and compliance
- 2. Access control and permissions
|
>> Snowflake SPS-C01 Examinations Actual Questions <<
Quiz 2026 Snowflake Marvelous SPS-C01: Snowflake Certified SnowPro Specialty - Snowpark Examinations Actual Questions
Would you like to register Snowflake SPS-C01 certification test? Would you like to obtain SPS-C01 certificate? Without having enough time to prepare for the exam, what should you do to pass your exam? In fact, there are techniques that can help. Even if you have a very difficult time preparing for the exam, you also can pass your exam successfully. How do you do that? The method is very simple, that is to use ValidVCE Snowflake SPS-C01 Dumps to prepare for your exam.
Snowflake Certified SnowPro Specialty - Snowpark Sample Questions (Q35-Q40):
NEW QUESTION # 35
You are developing a Snowpark application that performs several complex transformations on a large DataFrame representing customer purchase history. This DataFrame is used multiple times in the application. You need to optimize the application's performance by caching the DataFrame. Which of the following approaches is the MOST efficient and memory-conscious way to cache the DataFrame in Snowpark?
- A. Using to store the entire DataFrame in a Python list, then creating a new DataFrame from that list for each subsequent operation.
- B. Using immediately after the initial DataFrame creation.
- C. Using without specifying a storage level. Snowflake will choose a default storage level.
- D. Creating a temporary table in Snowflake using and then reading it back into a new DataFrame for each subsequent operation.
- E. Using 'session.createDataFrame(df.toPandas())' to convert the Snowpark DataFrame to Pandas and back to Snowpark DataFrame.
Answer: B
Explanation:
' df.cache_result()' is the recommended approach for caching DataFrames in Snowpark. It is designed to efficiently materialize the results of a DataFrame and store them in Snowflake's internal cache. This avoids recomputation in subsequent operations. brings the entire DataFrame into the client's memory, which is inefficient for large datasets. is not directly available in Snowpark like Spark. Creating a temporary table involves unnecessary I/O operations. Converting to Pandas and back introduces overhead and defeats the purpose of using Snowpark's optimized execution.
NEW QUESTION # 36
You are designing a Snowpark application to process streaming data ingested into Snowflake using Snowpipe. The application needs to apply a complex set of transformations and aggregations to the incoming data in real-time. Which of the following approaches would be MOST suitable for this scenario, leveraging the strengths of Snowpark architecture?
- A. Define a Snowpark Stored Procedure ('sproc') that is triggered automatically by a Snowflake Task whenever new data arrives via Snowpipe. The stored procedure performs the transformations and aggregations and stores the results in a new table.
- B. Use Snowpark to define a series of chained UDFs that perform the transformations and aggregations directly within the Snowpipe pipeline.
- C. Utilize Snowflake's Streams and Tasks feature and define views with complex SQL transformations that leverages Snowpipe.
- D. Continuously query the incoming data from Snowpipe using a Snowpark DataFrame and perform the transformations and aggregations on the client-side in a loop.
- E. Create a Snowpark DataFrame that represents the incoming data and use the 'write_pandaS function to write the transformed data to a separate Snowflake table after each micro-batch.
Answer: A
Explanation:
Using a Snowpark Stored Procedure triggered by a Snowflake Task provides the best solution for real-time processing of streaming data from Snowpipe. The Task automates the execution of the stored procedure whenever new data is available, and the stored procedure leverages Snowpark's server-side capabilities to perform the transformations and aggregations efficiently within the Snowflake environment. Option A involves client-side processing, Option B isn't compatible with Snowpipe directly and chained UDFs may not optimal for complex transformations and aggregations. Option C involves constant writes and may have performance issues with large datasets. While option E could work, utilizing Snowpark stored procedures provides better flexibility and Python code integration for more complex logic.
NEW QUESTION # 37
A data engineering team is using Snowpark Python to build a data pipeline. They need to create a User-Defined Function (UDF) that transforms a JSON string column representing customer information into a STRUCT type containing flattened fields for 'name', 'age', and 'city'. The UDF should handle null values gracefully and return NULL if the input JSON is invalid or if the 'name' field is missing. Considering performance implications and error handling, which of the following approaches is MOST optimal for defining and registering this UDF?
- A. Using 'snowflake.snowpark.functions.udf with defining the STRUCT schema explicitly, and handling JSON parsing and field extraction using the 'snowflake.snowpark.functions.parse_json' function. Return None for invalid json.
- B. Using 'snowflake.snowpark.functions.udf with and relying solely on Snowflake's built-in JSON functions within the UDF, even for complex transformations, and handling exceptions with try-except blocks within the UDF to return NULL.
- C. Using 'snowflake.snowpark.functions.udf with and handling JSON parsing and field extraction using standard Python libraries within the UDF, returning a JSON string representation of the STRUCT.
- D. Using 'session.register_function' to register a Python function as a UDF with and manually constructing a VARIANT object in Python from the extracted JSON fields.
- E. Using 'snowflake.snowpark.functions.sproc' to create a stored procedure that performs the JSON transformation and returns the transformed data.
Answer: A
Explanation:
Option B is the most optimal. Using allows Snowpark to understand the schema of the returned data, enabling efficient type checking and query optimization. 'snowflake.snowpark.functions.parse_json' leverages Snowflake's internal JSON parsing capabilities, leading to better performance. Returning None from UDF handles nulls gracefully. Other options either involve less efficient StringType return types, manual VARIANT object creation which is less type-safe, or suggest stored procedures when a simple UDF is sufficient.
NEW QUESTION # 38
Consider the following Snowpark Python code snippet for creating a stored procedure:
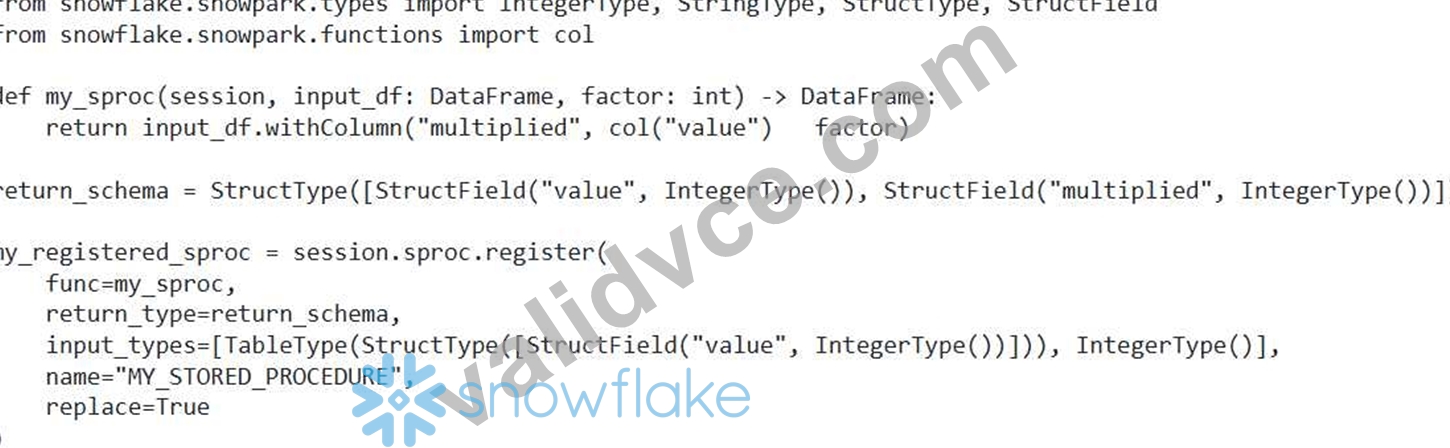
What is the PRIMARY reason for explicitly defining 'input_types' and during the stored procedure registration?
- A. To allow Snowflake to automatically generate documentation for the stored procedure's input and output types.
- B. To improve the performance of the stored procedure by enabling compile-time optimizations.
- C. To ensure data type safety and schema validation during deployment and execution, preventing unexpected runtime errors due to type mismatches between the stored procedure and the calling environment.
- D. To allow Snowsight to correctly display the stored procedure's metadata, making it easier for users to understand its functionality.
- E. To enable the stored procedure to be called from other programming languages besides Python.
Answer: C
NEW QUESTION # 39
You need to perform a set difference operation between two DataFrames in Snowpark Python. 'dfl' contains customer IDs from a marketing campaign, and 'df2 contains customer IDs from a recent purchase event. You want to identify customers who were targeted in the campaign but did not make a recent purchase. Both DataFrames have a column named 'customer id'. Which of the following approaches provides the most efficient way to accomplish this task in Snowpark?
Answer: B
Explanation:
Option C, using a 'left_anti' join, is the most efficient way to perform a set difference operation between two DataFrames in Snowpark. A join returns only the rows from the left DataFrame Cdfl s) where the join condition is not met in the right DataFrame Cdf2). This leverages Snowflake's query optimizer for optimal performance. Option A, 'subtract(df2)' , is equivalent to 'exceptAll(df2)' (Option B) and removes duplicate rows. While functionally correct, join is often more performant, especially for larger datasets. Option D is highly inefficient as it collects the 'customer_id' from 'df2 to the driver, it should be avoided. Option E calculates intersection, not difference.
NEW QUESTION # 40
......
ValidVCE exam study material is essential for candidates who want to appear for the Snowflake SPS-C01 certification exams and clear it to validate their skill set. This preparation material comes with Up To 1 year OF Free Updates And Free Demos. Place your order now and get Real SPS-C01 Exam Questions with these offers.
Test SPS-C01 Engine Version: https://www.validvce.com/SPS-C01-exam-collection.html
- SPS-C01 Training Courses 🐏 SPS-C01 Real Dump 💧 Valid Braindumps SPS-C01 Pdf 🥎 Download ▷ SPS-C01 ◁ for free by simply searching on ➤ www.practicevce.com ⮘ 🧇New SPS-C01 Exam Name
- Latest Braindumps SPS-C01 Book 💺 SPS-C01 Training Courses 🐔 SPS-C01 Dumps Guide 🥔 Simply search for ✔ SPS-C01 ️✔️ for free download on ▷ www.pdfvce.com ◁ ⓂValid Test SPS-C01 Tips
- Free Download SPS-C01 Examinations Actual Questions - Useful Test SPS-C01 Engine Version - The Best Snowflake Snowflake Certified SnowPro Specialty - Snowpark 👪 Search for ▛ SPS-C01 ▟ on ➠ www.examcollectionpass.com 🠰 immediately to obtain a free download 🗽Valid Braindumps SPS-C01 Ebook
- 100% Pass 2026 SPS-C01: Perfect Snowflake Certified SnowPro Specialty - Snowpark Examinations Actual Questions 🚢 Search for ⇛ SPS-C01 ⇚ and download it for free on ⏩ www.pdfvce.com ⏪ website 💥New SPS-C01 Study Notes
- Don't Miss Up to 1 year of Free Updates – Buy Snowflake SPS-C01 Dumps Now 🎍 Search for ➤ SPS-C01 ⮘ and download it for free on ( www.torrentvce.com ) website 🚒Reliable SPS-C01 Braindumps Ebook
- Exam SPS-C01 Voucher 🅱 Latest Braindumps SPS-C01 Book 👮 Valid Test SPS-C01 Tips 👬 Easily obtain free download of ➽ SPS-C01 🢪 by searching on [ www.pdfvce.com ] 🍬New SPS-C01 Study Notes
- Simplified Document Sharing and Accessibility With Snowflake SPS-C01 PDF (Dumps) 💆 Go to website ☀ www.examcollectionpass.com ️☀️ open and search for 【 SPS-C01 】 to download for free ☂Latest Braindumps SPS-C01 Book
- Valid Braindumps SPS-C01 Pdf ‼ Valid Braindumps SPS-C01 Ebook 📙 Valid Braindumps SPS-C01 Ebook 🧷 Open ➠ www.pdfvce.com 🠰 and search for ▷ SPS-C01 ◁ to download exam materials for free 🗨Reliable SPS-C01 Braindumps Ebook
- Why do you need to get help form www.prepawaypdf.com Snowflake SPS-C01 Exam Questions? 🏟 Search on { www.prepawaypdf.com } for “ SPS-C01 ” to obtain exam materials for free download 🙂SPS-C01 Preparation Store
- SPS-C01 Test Tutorials 🚣 SPS-C01 Online Lab Simulation 💛 Valid Test SPS-C01 Braindumps 🙎 Search for ➡ SPS-C01 ️⬅️ on ( www.pdfvce.com ) immediately to obtain a free download 🐓Valid Braindumps SPS-C01 Pdf
- New SPS-C01 Exam Name 🗾 Exam SPS-C01 Objectives 🤼 SPS-C01 Test Dates ☸ ▷ www.practicevce.com ◁ is best website to obtain ⮆ SPS-C01 ⮄ for free download 💍SPS-C01 Dumps Guide
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes




