Actual Microsoft AI-300 exam questions in our PDF format are ideal for restrictions-free quick preparation for the test. Microsoft AI-300 Real exam questions which are available for download in PDF format can be printed and studied in a hard copy format. Our Operationalizing Machine Learning and Generative AI Solutions (AI-300) PDF file of updated exam questions is compatible with smartphones, laptops, and tablets. Therefore, you can use this Operationalizing Machine Learning and Generative AI Solutions PDF to prepare for the test without limits of time and place.
| Section | Objectives |
|---|---|
| Topic 1: Plan and design AI solutions using Azure AI services | - Responsible AI design
|
| Topic 2: Design and implement generative AI solutions | - Large language model integration
|
| Topic 3: Operationalizing machine learning solutions | - ML lifecycle management
|
| Topic 4: Implement secure and scalable AI systems | - Security and governance
|
So for this reason, our Microsoft AI-300 are very similar to the actual exam. With a vast knowledge in this field, ValidExam always tries to provide candidates with the actual questions so that when they appear in their real Microsoft AI-300 Exam they do not feel any difference. The Desktop Microsoft AI-300 Practice Exam Software of ValidExam arranges a mock exam for the one who wants to evaluate and improve preparation.
NEW QUESTION # 187
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You manage a Retrieval-Augmented Generation (RAG) application built on Microsoft Foundry.
The application retrieves documents from an indexed knowledge base and generates answers for internal users.
Recent feedback indicates that answers are fluent but sometimes include information that is not supported by the documents that were retrieved.
You need to evaluate whether a proposed change improves RAG answer quality by using supported and measurable techniques.
Solution: Measure token throughput and average response latency before and after applying the proposed change.
Does the solution meet the goal?
Answer: A
Explanation:
Correct:
* Review user feedback comments collected after deployment to determine whether answers appear more accurate.
Relying solely on user feedback comments is not the proper immediate action for evaluating this specific issue but it is still the best choice.
Evaluate whether your proposed change improves the Retrieval-Augmented Generation (RAG) system by reducing hallucinations (unsupported information), you need to measure faithfulness and context relevance using automated, quantifiable metrics.
The proper course of action is to implement an LLM-as-a-Judge framework using an open-source evaluation library like Ragas or TruLens.
Recommended Evaluation Plan
Establish a baseline: Run your current RAG pipeline through a test dataset of 50-100 representative user queries.
Capture the outputs: Save the user query, the exact retrieved document snippets, and the generated response for every test.
Apply the change: Deploy your proposed modification (e.g., altered prompt, different temperature, or re-ranking algorithm).Run the evaluation: Pass the test dataset through the updated pipeline to generate a new set of responses.
Compare the metrics: Use the framework to score both sets of data and mathematically verify if the change reduced unsupported claims.
Incorrect:
* Compare embedding vector dimensions used by the retrieval pipeline before and after the change.
Comparing embedding vector dimensions is not a valid or effective method for measuring RAG answer quality. Vector dimensions (e.g., 1536 or 3072) are static architectural properties of your embedding model. They do not reflect factual accuracy, semantic grounding, or the rate of hallucinations in your text generation.
* Measure token throughput and average response latency before and after applying the proposed change.
Measuring token throughput and latency is not the correct action to solve this specific problem.
Reference:
https://www.getmaxim.ai/articles/how-to-evaluate-your-rag-system/
NEW QUESTION # 188
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You work in Microsoft Foundry with a prompt flow.
You must manually evaluate prompts and compare results across prompt variants.
You need to capture the inputs, outputs, token usage, and latencies for each flow run for the evaluation.
Solution: In Microsoft Foundry, turn on Tracing for the prompt flow of the project and execute test runs to produce trace data.
Does the solution meet the goal?
Answer: A
Explanation:
Correct:
* In Microsoft Foundry, turn on Tracing for the prompt flow of the project and execute test runs to produce trace data.
Incorrect:
* Create prompt variants and compare their outputs in the Evaluation experience.
* Use the prompt flow SDK to enable tracing for the flow before executing runs. Then run the flow to generate traceable results.
Note:
In Azure AI Foundry, you can capture and compare these metrics by enabling Tracing and using the Bulk Test feature. This allows you to systematically evaluate different prompt variants against a common dataset.
Steps to Evaluate and Compare Prompt Variants
*-> 1. Enable Tracing
Navigate to your Prompt Flow project.
Locate the Tracing toggle at the top of the flow authoring page.
Switch it to On.
This ensures every execution captures latency, token counts, and node-level inputs/outputs.
2. Create Prompt Variants
Within your flow, identify the LLM node you want to test.
Click Variants to create multiple versions of your prompt (e.g., Variant_0, Variant_1).
This allows you to test different instructions or few-shot examples side-by-side.
3. Run a Bulk Test (Evaluation)
4. Analyze the Results
Reference:
https://www.linkedin.com/pulse/streamlining-generative-ai-development-azure-foundry-tracing- taneja-mbwze
NEW QUESTION # 189
Drag and Drop Question
A data science team trains a model that depends on features that are stored in a managed feature store.
The model is registered in Azure Machine Learning and will be deployed to a real-time endpoint.
After deployment, the model must:
- Retrieve feature values dynamically at inference time.
- Use the same feature definitions that were used during training.
- Run without manual configuration changes across environments.
You need to define feature store entities so that feature retrieval behaves as expected when the model is deployed.
Which feature store entity should you select for each requirement? To answer, move the appropriate feature store entities to the correct requirements. You may use each feature store entity once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 190
You manage a Retrieval-Augmented Generation (RAG) system that uses Azure AI Search to retrieve documents from an indexed knowledge base.
The system must support the following retrieval requirements:
Queries that include exact policy identifiers must return matching documents even when semantic similarity is low.
Natural-language questions must prioritize semantically relevant documents even when keywords are not an exact match.
You need to configure the retrieval approach to meet the requirements.
How should you configure the retrieval behavior for each requirement? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.
Answer:
Explanation: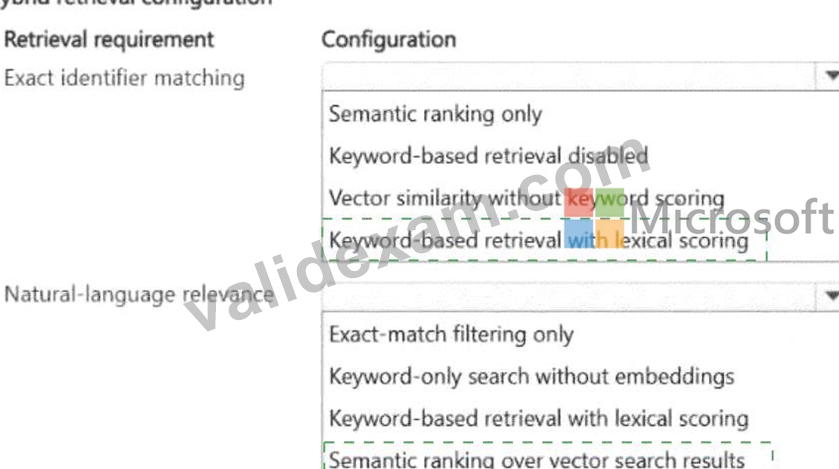
Explanation:
Different query types require fundamentally different retrieval algorithms. For queries that include exact policy identifiers, keyword or BM25 search is the correct choice because BM25 scores documents based on term frequency and inverse document frequency - an exact match on a specific policy identifier such as POL-
2024-HR-042 scores very highly regardless of semantic context. This is the right approach when semantic similarity is low but exact term matching is critical. For natural-language questions where keywords may not be an exact match, semantic or vector search is the correct choice because vector embeddings capture meaning rather than exact tokens, finding relevant documents even when the user ' s vocabulary differs from the document ' s terminology. Azure AI Search supports both modes through its hybrid search capability, and the correct configuration maps each query type to its optimal retrieval algorithm.
Microsoft Learn Reference Topic: Configure hybrid search in Azure AI Search - BM25 keyword search vs.
semantic vector search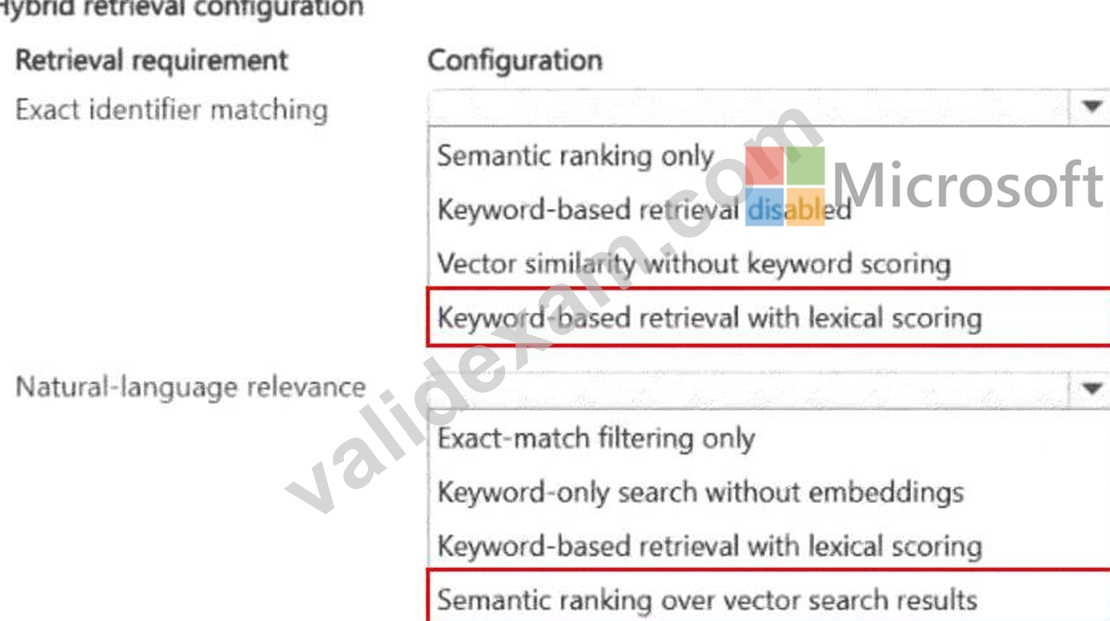
NEW QUESTION # 191
You create an Azure Machine Learning workspace and install the MLflow library.
You need to tog different types of data by using the MLflow library.
Which method should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation: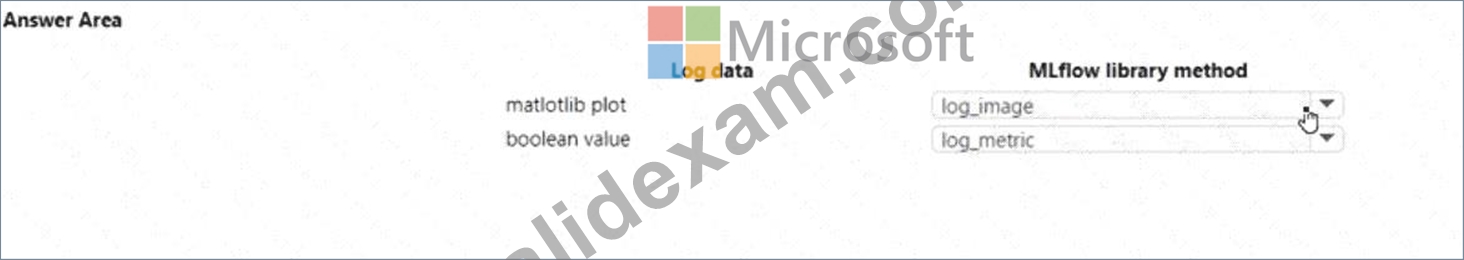
NEW QUESTION # 192
......
The ValidExam AI-300 PDF file contains the real, valid, and updated Microsoft AI-300 exam practice questions. These are the real AI-300 exam questions that surely will appear in the upcoming exam and by preparing with them you can easily pass the final exam. The AI-300 PDF Questions file is easy to use and install. You can use the AI-300 PDF practice questions on your laptop, desktop, tabs, or even on your smartphone and start AI-300 exam preparation right now.
Hot AI-300 Questions: https://www.validexam.com/AI-300-latest-dumps.html