Databricks-Certified-Professional-Data-Engineer Testking Learning Materials & Databricks-Certified-Professional-Data-Engineer Dumps PDF
What's more, part of that Test4Sure Databricks-Certified-Professional-Data-Engineer dumps now are free: https://drive.google.com/open?id=1xSx6PKDZDiWYTi9wwoNUKr-57IqpqatU
In order to make you confirm the quality of our Databricks-Certified-Professional-Data-Engineer Dumps and let you know whether the dumps suit you, pdf and software version in Test4Sure exam dumps can let you download the free part of our Databricks-Certified-Professional-Data-Engineer training materials. We will offer free the part of questions and answers for you and you can visit Test4Sure.com to search for and download these certification training materials. You cannot buy the dumps until you experience it so that you can avoid buying ignorantly the exam dumps without fully understanding the quality of questions and answers.
| Section | Weight | Objectives |
|---|
| Topic 1: Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Differences between data lake, data warehouse, and lakehouse
- 2. Data governance fundamentals
- 3. Bronze, silver, gold data layers
|
| Topic 2: Delta Lake | 20-25% | - Delta Lake fundamentals
- 1. Time travel and data versioning
- 2. ACID transactions
- 3. Optimize and Z-order
- Delta Lake operations
- 1. Schema evolution and enforcement
- 2. Merge, update, delete operations
- 3. Delta Live Tables
|
| Topic 3: Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Task dependencies and orchestration
- 2. Monitoring and alerting
- 3. Jobs and job scheduling
|
| Topic 4: Data Ingestion | 15-20% | - Streaming ingestion
- 1. Kafka integration
- 2. Structured streaming fundamentals
- Batch ingestion methods
- 1. Integration with external systems
- 2. Spark APIs for ingestion
- 3. DBR autoloader
|
| Topic 5: Data Processing with Spark | 25-30% | - Python and SQL for data engineering
- 1. Spark APIs in Python
- 2. Built-in and user-defined functions
- 3. Performance optimization techniques
- Spark DataFrames and Spark SQL
- 1. Spark SQL queries and functions
- 2. DataFrame operations and transformations
- 3. Window functions
|
>> Databricks-Certified-Professional-Data-Engineer Testking Learning Materials <<
Databricks-Certified-Professional-Data-Engineer Dumps PDF & Databricks-Certified-Professional-Data-Engineer Interactive Course
Do not waste further time and money, get real Databricks Databricks-Certified-Professional-Data-Engineer pdf questions and practice test software, and start Databricks-Certified-Professional-Data-Engineer test preparation today. Test4Sure will also provide you with up to 365 days of free exam questions updates. Free demo of Databricks-Certified-Professional-Data-Engineer Dumps PDF allowing you to try before you buy and one-year free update will be allowed after purchased.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q45-Q50):
NEW QUESTION # 45
A task orchestrator has been configured to run two hourly tasks. First, an outside system writes Parquet data to a directory mounted at /mnt/raw_orders/. After this data is written, a Databricks job containing the following code is executed:
(spark.readStream
.format("parquet")
.load("/mnt/raw_orders/")
.withWatermark("time", "2 hours")
.dropDuplicates(["customer_id", "order_id"])
.writeStream
.trigger(once=True)
.table("orders")
)
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order, and that the time field indicates when the record was queued in the source system. If the upstream system is known to occasionally enqueue duplicate entries for a single order hours apart, which statement is correct?
- A. Duplicate records enqueued more than 2 hours apart may be retained and the orders table may contain duplicate records with the same customer_id and order_id.
- B. The orders table will not contain duplicates, but records arriving more than 2 hours late will be ignored and missing from the table.
- C. All records will be held in the state store for 2 hours before being deduplicated and committed to the orders table.
- D. The orders table will contain only the most recent 2 hours of records and no duplicates will be present.
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
Exact extract: "dropDuplicates with watermark performs stateful deduplication on the keys within the watermark delay." Exact extract: "Records older than the event-time watermark are considered late and may be dropped." Exact extract: "trigger(once) processes all available data once and then stops."
NEW QUESTION # 46
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active user. They then modify their code to the following (leaving all other variables unchanged).
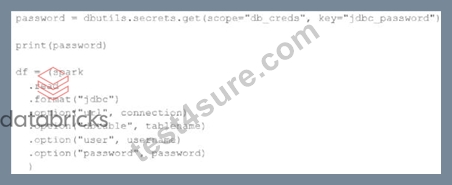
Which statement describes what will happen when the above code is executed?
- A. The connection to the external table will fail; the string "redacted" will be printed.
- B. The connection to the external table will succeed; the string value of password will be printed in plain text.
- C. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the encoded password will be saved to DBFS.
- D. An interactive input box will appear in the notebook; if the right password is provided, the connection will succeed and the password will be printed in plain text.
- E. The connection to the external table will succeed; the string "redacted" will be printed.
Answer: E
Explanation:
This is the correct answer because the code is using the dbutils.secrets.get method to retrieve the password from the secrets module and store it in a variable. The secrets module allows users to securely store and access sensitive information such as passwords, tokens, or API keys. The connection to the external table will succeed because the password variable will contain the actual password value. However, when printing the password variable, the string "redacted" will be displayed instead of the plain text password, as a security measure to prevent exposing sensitive information in notebooks. Verified References: [Databricks Certified Data Engineer Professional], under "Security & Governance" section; Databricks Documentation, under
"Secrets" section.
NEW QUESTION # 47
A table named user_ltv is being used to create a view that will be used by data analysis on various teams.
Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
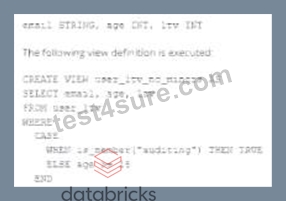
An analyze who is not a member of the auditing group executing the following query:
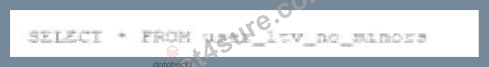
Which result will be returned by this query?
- A. All columns will be displayed normally for those records that have an age greater than 18; records not meeting this condition will be omitted.
- B. All records from all columns will be displayed with the values in user_ltv.
- C. All columns will be displayed normally for those records that have an age greater than 17; records not meeting this condition will be omitted.
- D. All age values less than 18 will be returned as null values all other columns will be returned with the values in user_ltv.
Answer: A
Explanation:
Given the CASE statement in the view definition, the result set for a user not in the auditing group would be constrained by the ELSE condition, which filters out records based on age. Therefore, the view will return all columns normally for records with an age greater than 18, as users who are not in the auditing group will not satisfy the is_member('auditing') condition. Records not meeting the age > 18 condition will not be displayed.
NEW QUESTION # 48
You have noticed the Data scientist team is using the notebook versioning feature with git integra-tion, you have recommended them to switch to using Databricks Repos, which of the below reasons could be the reason the why the team needs to switch to Databricks Repos.
- A. Databricks Repos allows multiple users to make changes
- B. Databricks Repos allow you to add comments and select the changes you want to commit.
- C. Databricks Repos allows merge and conflict resolution
- D. Databricks Repos has a built-in version control system
- E. Databricks Repos automatically saves changes
Answer: B
Explanation:
Explanation
The answer is Databricks Repos allow you to add comments and select the changes you want to commit.
NEW QUESTION # 49
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream for highly selective joins on a number of fields, and will also be leveraged by the machine learning team to filter on a handful of relevant fields, in total, 15 fields have been identified that will often be used for filter and join logic.
The data engineer is trying to determine the best approach for dealing with these nested fields before declaring the table schema.
Which of the following accurately presents information about Delta Lake and Databricks that may Impact their decision-making process?
- A. Tungsten encoding used by Databricks is optimized for storing string data: newly-added native support for querying JSON strings means that string types are always most efficient.
- B. Schema inference and evolution on Databricks ensure that inferred types will always accurately match the data types used by downstream systems.
- C. By default Delta Lake collects statistics on the first 32 columns in a table; these statistics are leveraged for data skipping when executing selective queries.
- D. Because Delta Lake uses Parquet for data storage, Dremel encoding information for nesting can be directly referenced by the Delta transaction log.
Answer: C
Explanation:
Delta Lake, built on top of Parquet, enhances query performance through data skipping, which is based on the statistics collected for each file in a table. For tables with a large number of columns, Delta Lake by default collects and stores statistics only for the first 32 columns. These statistics include min/max values and null counts, which are used to optimize query execution by skipping irrelevant data files. When dealing with highly nested JSON structures, understanding this behavior is crucial for schema design, especially when determining which fields should be flattened or prioritized in the table structure to leverage data skipping efficiently for performance optimization.
Reference: Databricks documentation on Delta Lake optimization techniques, including data skipping and statistics collection (https://docs.databricks.com/delta/optimizations/index.html).
NEW QUESTION # 50
......
In order to solve customers’ problem in the shortest time, our Databricks Certified Professional Data Engineer Exam guide torrent provides the twenty four hours online service for all people. Maybe you have some questions about our Databricks-Certified-Professional-Data-Engineer test torrent when you use our products; it is your right to ask us in anytime and anywhere. You just need to send us an email, our online workers are willing to reply you an email to solve your problem in the shortest time. During the process of using our Databricks-Certified-Professional-Data-Engineer study torrent, we can promise you will have the right to enjoy the twenty four hours online service provided by our online workers. At the same time, we warmly welcome that you tell us your suggestion about our Databricks-Certified-Professional-Data-Engineer study torrent, because we believe it will be very useful for us to utilize our Databricks-Certified-Professional-Data-Engineer test torrent.
Databricks-Certified-Professional-Data-Engineer Dumps PDF: https://www.test4sure.com/Databricks-Certified-Professional-Data-Engineer-pass4sure-vce.html
- Databricks-Certified-Professional-Data-Engineer Latest Test Format 🐐 Exam Databricks-Certified-Professional-Data-Engineer Vce Format 🍗 Valid Databricks-Certified-Professional-Data-Engineer Exam Online 🌼 Open website “ www.testkingpass.com ” and search for ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ for free download ☎Training Databricks-Certified-Professional-Data-Engineer Tools
- Databricks-Certified-Professional-Data-Engineer Testking Learning Materials - Databricks Databricks-Certified-Professional-Data-Engineer Dumps PDF: Databricks Certified Professional Data Engineer Exam Pass Success 👈 Search for [ Databricks-Certified-Professional-Data-Engineer ] and download it for free on ⏩ www.pdfvce.com ⏪ website 🏯Testing Databricks-Certified-Professional-Data-Engineer Center
- Free PDF 2026 Databricks-Certified-Professional-Data-Engineer: Accurate Databricks Certified Professional Data Engineer Exam Testking Learning Materials 🕷 Search for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ and download it for free immediately on ▷ www.prep4away.com ◁ 🔭Databricks-Certified-Professional-Data-Engineer Online Lab Simulation
- Databricks-Certified-Professional-Data-Engineer Testking Learning Materials - Databricks Databricks-Certified-Professional-Data-Engineer Dumps PDF: Databricks Certified Professional Data Engineer Exam Pass Success 🎢 Go to website ☀ www.pdfvce.com ️☀️ open and search for ▶ Databricks-Certified-Professional-Data-Engineer ◀ to download for free 🐫Valid Databricks-Certified-Professional-Data-Engineer Test Questions
- Covers 100% Composite Exams Databricks-Certified-Professional-Data-Engineer Critical Information 🚋 Search for “ Databricks-Certified-Professional-Data-Engineer ” and download it for free on ☀ www.examdiscuss.com ️☀️ website 🥱Databricks-Certified-Professional-Data-Engineer Exam Paper Pdf
- Test Databricks-Certified-Professional-Data-Engineer Cram Review 🥦 Databricks-Certified-Professional-Data-Engineer Latest Test Format 🛕 Databricks-Certified-Professional-Data-Engineer Latest Test Format ✋ Copy URL ( www.pdfvce.com ) open and search for ▛ Databricks-Certified-Professional-Data-Engineer ▟ to download for free 🥄Databricks-Certified-Professional-Data-Engineer Exam Paper Pdf
- Databricks-Certified-Professional-Data-Engineer Testking Learning Materials - Databricks Databricks-Certified-Professional-Data-Engineer Dumps PDF: Databricks Certified Professional Data Engineer Exam Pass Success 💆 Search for { Databricks-Certified-Professional-Data-Engineer } and obtain a free download on ⇛ www.dumpsmaterials.com ⇚ 👞New Databricks-Certified-Professional-Data-Engineer Study Notes
- Exam Databricks-Certified-Professional-Data-Engineer Vce Format 🏍 Latest Databricks-Certified-Professional-Data-Engineer Test Voucher 🍡 Databricks-Certified-Professional-Data-Engineer Examcollection Questions Answers 🍿 Search for ➽ Databricks-Certified-Professional-Data-Engineer 🢪 on ✔ www.pdfvce.com ️✔️ immediately to obtain a free download ⛷Databricks-Certified-Professional-Data-Engineer Exam Cost
- Databricks-Certified-Professional-Data-Engineer Exam Cost 🦠 Valid Databricks-Certified-Professional-Data-Engineer Exam Online 🐆 Databricks-Certified-Professional-Data-Engineer Hot Spot Questions 🍪 Go to website ➠ www.pass4test.com 🠰 open and search for { Databricks-Certified-Professional-Data-Engineer } to download for free 🎤Exam Databricks-Certified-Professional-Data-Engineer Vce Format
- Training Databricks-Certified-Professional-Data-Engineer Tools 🚆 Databricks-Certified-Professional-Data-Engineer Free Dumps 🥶 Valid Databricks-Certified-Professional-Data-Engineer Exam Online 📞 Search for ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ and obtain a free download on ( www.pdfvce.com ) 🥴Databricks-Certified-Professional-Data-Engineer Examcollection Questions Answers
- Databricks-Certified-Professional-Data-Engineer Reliable Exam Online 💌 Databricks-Certified-Professional-Data-Engineer Certification Materials 🍊 Test Databricks-Certified-Professional-Data-Engineer Cram Review 🦇 Enter ▷ www.exam4labs.com ◁ and search for [ Databricks-Certified-Professional-Data-Engineer ] to download for free 🔑Reliable Databricks-Certified-Professional-Data-Engineer Test Practice
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, buyerseller.xyz, www.wilderness-survival.net, www.stes.tyc.edu.tw, Disposable vapes
2026 Latest Test4Sure Databricks-Certified-Professional-Data-Engineer PDF Dumps and Databricks-Certified-Professional-Data-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1xSx6PKDZDiWYTi9wwoNUKr-57IqpqatU