Latest Certified-Data-Engineer-Professional Learning Materials - Certified-Data-Engineer-Professional Test Registration

Our Certified-Data-Engineer-Professional exam dumps are famous for instant access to download, and you can receive the downloading link and password within ten minutes, so that you can start your practice as soon as possible. Moreover, we offer you free demo to have a try, so that you can know what the complete version is like. We are pass guarantee and money back guarantee for Certified-Data-Engineer-Professional Exam Dumps, if you fail to pass the exam, we will give refund. Online and offline chat service are available, they possess the professional knowledge for Certified-Data-Engineer-Professional exam materials, and if you have any questions, you can consult us.
| Section | Objectives |
|---|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot third-party library installations and dependencies
- 2. Develop User-Defined Functions using Pandas/Python UDFs
- 3. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- Building and Testing ETL Pipelines
- 1. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 2. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 3. Use control flow operators in pipeline components
- 4. Configure environments, dependencies, memory, and retry behavior
- 5. Use APPLY CHANGES APIs for change data capture
- 6. Develop unit and integration tests for data processing code
- 7. Compare streaming tables and materialized views
- 8. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest data from message buses and cloud storage
- 2. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 3. Build append-only pipelines for batch and streaming data using Delta
|
| Ensuring Data Security and Compliance | - Data Security
- 1. Apply anonymization and pseudonymization techniques
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Use row filters and column masks for sensitive data
- Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
|
| Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Configure sharing with external platforms using the open sharing protocol
- 2. Share live Lakehouse data with external computing platforms
- 3. Configure Databricks-to-Databricks Sharing
|
| Data Modelling | - Scalable Data Models
- 1. Understand Liquid Clustering versus partitioning and Z-Ordering
- 2. Optimize data layout using Liquid Clustering
- 3. Design and implement scalable data models using Delta Lake
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
|
| Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
- Monitoring
- 1. Use Query Profiler and Spark UI to monitor workloads
- 2. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 3. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 4. Use system tables for resource, cost, audit, and workload monitoring
|
| Cost & Performance Optimisation | - Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Understand deletion vectors and liquid clustering
- 3. Use Change Data Feed to address streaming table limitations and improve latency
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Analyze errors and remediate failed job runs
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
|
>> Latest Certified-Data-Engineer-Professional Learning Materials <<
Fantastic Latest Certified-Data-Engineer-Professional Learning Materials Provide Prefect Assistance in Certified-Data-Engineer-Professional Preparation
In order to meet the demands of all the customers, we can promise that we will provide all customers with three different versions of the Certified-Data-Engineer-Professional study materials: PDF version, Soft version and APP version. In addition, we can make sure that we are going to offer high quality Certified-Data-Engineer-Professional practice study materials with reasonable prices but various benefits for all customers. It is our sincere hope to help you pass Certified-Data-Engineer-Professional exam by the help of our Certified-Data-Engineer-Professional certification guide. Just come and buy our Certified-Data-Engineer-Professional learning prep!
Databricks Certified Data Engineer Professional Sample Questions (Q45-Q50):
NEW QUESTION # 45
A view is registered with the following code:
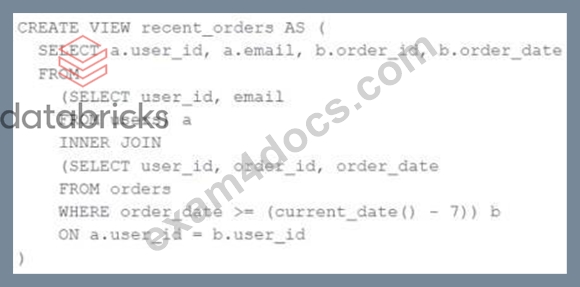
Both users and orders are Delta Lake tables.
Which statement describes the results of querying recent_orders?
- A. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query finishes.
- B. Results will be computed and cached when the view is defined; these cached results will incrementally update as new records are inserted into source tables.
- C. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query began.
- D. All logic will execute when the view is defined and store the result of joining tables to the DBFS; this stored data will be returned when the view is queried.
Answer: C
NEW QUESTION # 46
Which configuration parameter directly affects the size of a spark-partition upon ingestion of data into Spark?
- A. spark.sql.autoBroadcastJoinThreshold
- B. spark.sql.files.maxPartitionBytes
- C. spark.sql.files.openCostInBytes
- D. spark.sql.adaptive.advisoryPartitionSizeInBytes
- E. spark.sql.adaptive.coalescePartitions.minPartitionNum
Answer: B
Explanation:
This is the correct answer because spark.sql.files.maxPartitionBytes is a configuration parameter that directly affects the size of a spark-partition upon ingestion of data into Spark. This parameter configures the maximum number of bytes to pack into a single partition when reading files from file- based sources such as Parquet, JSON and ORC. The default value is 128 MB, which means each partition will be roughly 128 MB in size, unless there are too many small files or only one large file.
NEW QUESTION # 47
A data organization has adopted Delta Sharing to securely distribute curated datasets from a Unity Catalog-enabled workspace. The data engineering team shares large Delta tables internally via Databricks-to-Databricks and externally via Open Sharing for aggregated reports. While testing, they encounter challenges related to access control, data update visibility, and shareable object types. What is a limitation of the Delta Sharing protocol or implementation when used with Databricks-to-Databricks or Open Sharing?
- A. With Databricks-to-Databricks sharing, Unity Catalog recipients must re-ingest data manually using COPY INTO or REST APIs.
- B. With Open Sharing, recipients cannot access Volumes, Models, or notebooks -- only static Delta tables are supported.
- C. Delta Sharing does not support Unity Catalog-enabled tables; only legacy Hive Metastore tables are shareable.
- D. Delta Sharing (both Databricks-to-Databricks and Open Sharing) allows recipients to modify the source data if they have select privileges.
Answer: B
Explanation:
According to Databricks' documentation, Open Sharing allows secure sharing of Delta tables to any recipient via a REST-based protocol without requiring a Databricks account. However, the Open Sharing protocol is limited to static Delta tables--it does not support sharing of Unity Catalog objects like Volumes, Machine Learning models, or notebooks. Only Databricks-to- Databricks sharing supports dynamic data sharing with update visibility and streaming reads.
Thus, the inability to share non-table objects in Open Sharing represents a known limitation of the protocol. Option A accurately reflects this constraint as described in Delta Sharing design principles and documentation.
NEW QUESTION # 48
A data engineer is reviewing the PySpark code to copy a part of the production dataset to the sandbox environment, and needs to be sure that no PII(Personally Identifiable Information) data is being copied. After checking the sales table, the data engineer notices that it has user emails as the only PII data included as well as being the only column to identify the user.
from pyspark.sql import functions as F
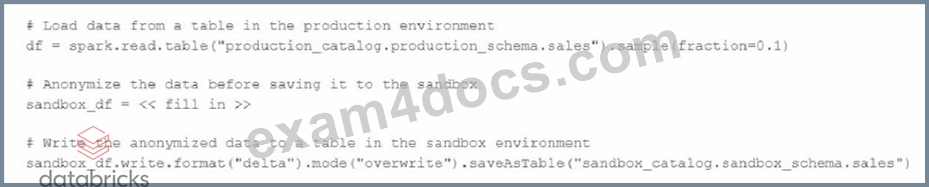
Which anonymised code should be used to achieve the required outcome?
- A. df.withColumn ("hashed_email", sha2 ("user_email"))
- B. df.withColumn ("user_email", F.sha2 ("user_email"))
- C. df.withColumn ("user_email", F.regexp_replace ("user_eamail", "@*", "@anonymized.com"))
- D. df.withColumn ("user_emai", F.expr("uuid()"))
Answer: B
Explanation:
Hashing the email column replaces the original PII with a deterministic, irreversible value while preserving its role as a unique identifier. This ensures no actual email addresses are copied to the sandbox environment, while still allowing consistent joins or user-level analysis if needed.
NEW QUESTION # 49
A data engineer is setting up a pipeline to ingest data from a message bus system that occasionally delivers duplicate messages. The duplicate messages can be a week apart. The target is a Databricks Delta Lake table where each record should appear exactly once. Which Databricks ingestion pattern should be implemented to handle potential duplicates where events can arrive outside of the configured watermark?
- A. Implement a write operation using MERGE INTO with a unique key
- B. Configure Structured Streaming with dropDuplicates transformation
- C. Use Delta Lake time travel to identify and remove duplicates
- D. Use Delta Lake's change data feed to filter duplicate records
Answer: A
Explanation:
Using MERGE INTO with a unique key enforces idempotent writes at the Delta Lake table level.
This approach reliably handles duplicates even when events arrive far outside any streaming watermark, ensuring that each logical record is written exactly once regardless of arrival time.
NEW QUESTION # 50
......
As old saying goes, no pains, no gains. You must depend on yourself to acquire what you want. No one can substitute you with the process. Of course, life has shortcut, which can ensure you have a bright future. Our Certified-Data-Engineer-Professional training quiz will become your new hope. As the most popular exam provider in the market, we are warmly praised and we can receive thousands of the grateful feedbacks from our worthy customers on Certified-Data-Engineer-Professional Exam Questions. please trust and buy our Certified-Data-Engineer-Professional study materials!
Certified-Data-Engineer-Professional Test Registration: https://www.exam4docs.com/Certified-Data-Engineer-Professional-study-questions.html
- Certified-Data-Engineer-Professional Exam Dumps Demo 🛀 Certified-Data-Engineer-Professional Exam Price 🔃 Frequent Certified-Data-Engineer-Professional Updates 🎍 Immediately open ▶ www.examdiscuss.com ◀ and search for ▷ Certified-Data-Engineer-Professional ◁ to obtain a free download 🥬Latest Certified-Data-Engineer-Professional Questions
- Test Certified-Data-Engineer-Professional Dumps Demo 🕔 Certified-Data-Engineer-Professional Exam Price ⬆ Certified-Data-Engineer-Professional Exam Topics 🥃 Open ➡ www.pdfvce.com ️⬅️ and search for ⮆ Certified-Data-Engineer-Professional ⮄ to download exam materials for free ⏫Certified-Data-Engineer-Professional Exam Topics
- Free Download Latest Certified-Data-Engineer-Professional Learning Materials - Leading Offer in Qualification Exams - Trustworthy Certified-Data-Engineer-Professional Test Registration ⬆ Search for 「 Certified-Data-Engineer-Professional 」 and easily obtain a free download on ➡ www.pdfdumps.com ️⬅️ 🦪Exam Certified-Data-Engineer-Professional Exercise
- Latest Certified-Data-Engineer-Professional Dumps Questions 🔕 Certified-Data-Engineer-Professional Exam Dumps Demo 🖋 Dumps Certified-Data-Engineer-Professional Download ⚗ Download ➽ Certified-Data-Engineer-Professional 🢪 for free by simply entering ➥ www.pdfvce.com 🡄 website 😬Certified-Data-Engineer-Professional Exam Overview
- Certified-Data-Engineer-Professional Exam Topics 🌁 Dumps Certified-Data-Engineer-Professional Download 📷 Exam Certified-Data-Engineer-Professional Actual Tests 🦜 Download “ Certified-Data-Engineer-Professional ” for free by simply entering ➥ www.easy4engine.com 🡄 website 😒Frequent Certified-Data-Engineer-Professional Updates
- Maximize Your Success with Pdfvce Customizable Certified-Data-Engineer-Professional Databricks Certified Data Engineer Professional Practice Test 😣 Easily obtain free download of “ Certified-Data-Engineer-Professional ” by searching on 「 www.pdfvce.com 」 🌤Certified-Data-Engineer-Professional Exam Sample
- Buy Actual Databricks Certified-Data-Engineer-Professional Exam Questions Now on Discount ▛ Search for ⏩ Certified-Data-Engineer-Professional ⏪ and download it for free immediately on ➽ www.testkingpass.com 🢪 📦Certification Certified-Data-Engineer-Professional Training
- Certified-Data-Engineer-Professional Test Guide - Databricks Certified Data Engineer Professional Study Question -amp; Certified-Data-Engineer-Professional Exam Questions 🏮 Enter [ www.pdfvce.com ] and search for ▶ Certified-Data-Engineer-Professional ◀ to download for free ✡Latest Certified-Data-Engineer-Professional Exam Topics
- Certified-Data-Engineer-Professional Exam Dumps Demo 🟡 Exam Certified-Data-Engineer-Professional Vce Format 👒 Certification Certified-Data-Engineer-Professional Training 🎤 Open website ✔ www.practicevce.com ️✔️ and search for “ Certified-Data-Engineer-Professional ” for free download 🔖Certified-Data-Engineer-Professional Exam Sample
- Exam Certified-Data-Engineer-Professional Actual Tests 🪔 Certified-Data-Engineer-Professional Certification Cost 📜 Exam Certified-Data-Engineer-Professional Exercise 👋 Easily obtain ➤ Certified-Data-Engineer-Professional ⮘ for free download through ➠ www.pdfvce.com 🠰 🐻Certified-Data-Engineer-Professional Exam Price
- Certification Certified-Data-Engineer-Professional Book Torrent 🔥 Certified-Data-Engineer-Professional Exam Price 🎎 Test Certified-Data-Engineer-Professional Collection 🗓 Enter ▶ www.pdfdumps.com ◀ and search for ☀ Certified-Data-Engineer-Professional ️☀️ to download for free 🚥Certified-Data-Engineer-Professional Exam Dumps Demo
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes