Some of our customers are white-collar workers with no time to waste, and need a Databricks certification urgently to get their promotions, meanwhile the other customers might aim at improving their skills. So we try to meet different requirements by setting different versions of our Databricks-Certified-Professional-Data-Engineer question dumps. The first one is online Databricks-Certified-Professional-Data-Engineer engine version. As an online tool, it is convenient and easy to study, supports all Web Browsers and system including Windows, Mac, Android, iOS and so on. You can practice online anytime and check your test history and performance review, which will do help to your study. The second is Databricks-Certified-Professional-Data-Engineer Desktop Test Engine. As an installable Databricks-Certified-Professional-Data-Engineer software application, it simulated the real Databricks-Certified-Professional-Data-Engineer exam environment, and builds 200-125 exam confidence. The third one is Practice PDF version. PDF Version is easy to read and print. So you can study anywhere, anytime.
| Section | Weight | Objectives |
|---|---|---|
| Data Ingestion | 15-20% | - Streaming ingestion
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
| Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
| Delta Lake | 20-25% | - Delta Lake operations
|
>> Databricks-Certified-Professional-Data-Engineer Exam Fee <<
The Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) practice test questions prep material has actual Databricks Certified Professional Data Engineer Exam exam questions for our customers so they don't face any hurdles while preparing for Databricks Databricks-Certified-Professional-Data-Engineer certification exam. The study material is made by professionals while thinking about our users. We have made the product user-friendly so it will be an easy-to-use learning material. We even guarantee our users that if they couldn't pass the Databricks Databricks-Certified-Professional-Data-Engineer Certification Exam on the first try with their efforts, they can claim a full refund of their payment from us (terms and conditions apply).
NEW QUESTION # 43
Which of the following locations in Databricks product architecture hosts jobs/pipelines and queries?
Answer: E
Explanation:
Explanation
The answer is Control Plane,
Databricks operates most of its services out of a control plane and a data plane, please note serverless features like SQL Endpoint and DLT compute use shared compute in Control pane.
Control Plane: Stored in Databricks Cloud Account
*The control plane includes the backend services that Databricks manages in its own Azure account. Notebook commands and many other workspace configurations are stored in the control plane and encrypted at rest.
Data Plane: Stored in Customer Cloud Account
*The data plane is managed by your Azure account and is where your data resides. This is also where data is processed. You can use Azure Databricks connectors so that your clusters can connect to external data sources outside of your Azure account to ingest data or for storage.
Here is the product architecture diagram highlighted where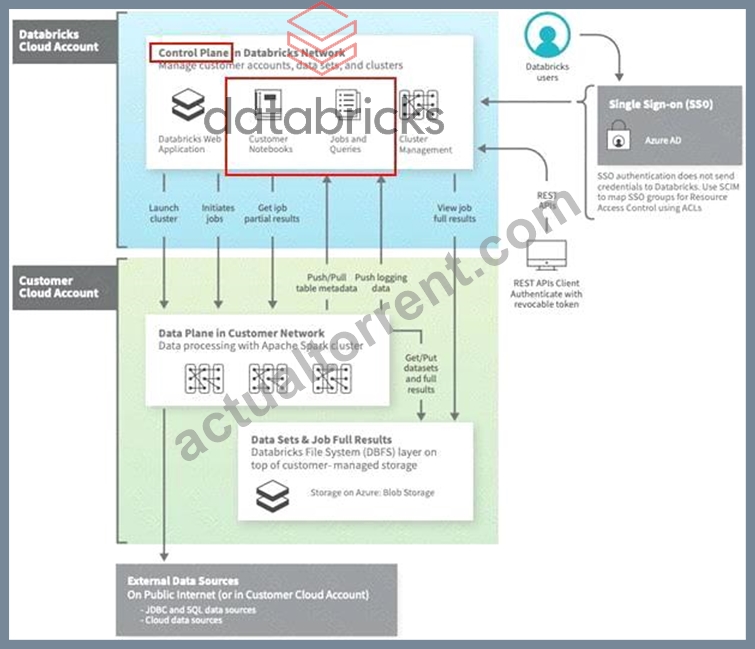
NEW QUESTION # 44
While reviewing a query's execution in the Databricks Query Profiler, a data engineer observes that the Top Operators panel shows a Sort operator with high Time Spent and Memory Peak metrics. The Spark UI also reports frequent data spilling.
How should the data engineer address this issue?
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
When Spark performs wide transformations such as sortBy or orderBy, large data volumes can exceed memory limits, causing disk spilling. The official Databricks performance tuning guide recommends increasing the shuffle partition count to distribute the data more evenly across executors. By default, Spark uses a fixed number of shuffle partitions (e.g., 200), which can lead to memory imbalance and spill if some partitions are too large. Increasing this number (via spark.sql.shuffle.partitions) results in smaller partitions, reduced in-memory pressure, and improved sort performance. Other options like broadcast joins or single partition sorts do not apply to single-table sorts, and converting to filters changes query logic. Thus, option D is the correct remedy.
NEW QUESTION # 45
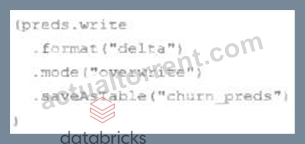
The data science team has created and logged a production model using MLflow. The following code correctly imports and applies the production model to output the predictions as a new DataFrame namedpredswith the schema "customer_id LONG, predictions DOUBLE, date DATE".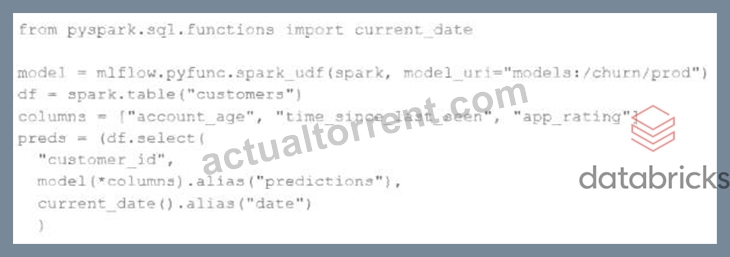
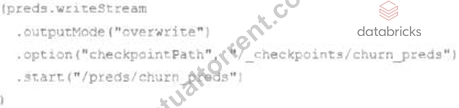
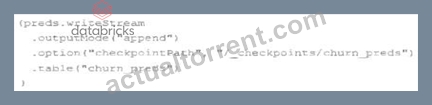
The data science team would like predictions saved to a Delta Lake table with the ability to compare all predictions across time. Churn predictions will be made at most once per day.
Which code block accomplishes this task while minimizing potential compute costs?
Answer: E
NEW QUESTION # 46
A data engineer is designing a system to process batch patient encounter data stored in an S3 bucket, creating a Delta table (patient_encounters) with columns encounter_id, patient_id, encounter_date, diagnosis_code, and treatment_cost. The table is queried frequently by patient_id and encounter_date, requiring fast performance. Fine-grained access controls must be enforced. The engineer wants to minimize maintenance and boost performance.
How should the data engineer create the patient_encounters table?
Answer: A
Explanation:
Databricks documentation specifies that Unity Catalog managed tables are the preferred choice for secure, low-maintenance Delta Lake architectures. Managed tables provide full lifecycle management, including metadata, file storage, and access control integration with Unity Catalog. Fine-grained permissions can be enforced at the column and row level through built-in Unity Catalog governance.
Additionally, Predictive Optimization (Auto Optimize + Auto Compaction) automatically manages file sizes, metadata pruning, and layout optimization, eliminating the need for manual maintenance such as scheduling OPTIMIZE or VACUUM.
External tables (A) require manual path management, and Hive Metastore tables (D) do not support Unity Catalog access policies. Therefore, creating a managed Unity Catalog table with predictive optimization provides both the security and performance benefits needed, making B the correct solution.
NEW QUESTION # 47
The data science team has requested assistance in accelerating queries on free form text from user reviews. The data is currently stored in Parquet with the below schema:
item_id INT, user_id INT, review_id INT, rating FLOAT, review STRING
The review column contains the full text of the review left by the user. Specifically, the data science team is looking to identify if any of 30 key words exist in this field.
A junior data engineer suggests converting this data to Delta Lake will improve query performance.
Which response to the junior data engineer s suggestion is correct?
Answer: B
Explanation:
Converting the data to Delta Lake may not improve query performance on free text fields with high cardinality, such as the review column. This is because Delta Lake collects statistics on the minimum and maximum values of each column, which are not very useful for filtering or skipping data on free text fields. Moreover, Delta Lake collects statistics on the first 32 columns by default, which may not include the review column if the table has more columns. Therefore, the junior data engineer's suggestion is not correct. A better approach would be to use a full-text search engine, such as Elasticsearch, to index and query the review column. Alternatively, you can use natural language processing techniques, such as tokenization, stemming, and lemmatization, to preprocess the review column and create a new column with normalized terms that can be used for filtering or skipping data. Reference:
Optimizations: https://docs.delta.io/latest/optimizations-oss.html
Full-text search with Elasticsearch: https://docs.databricks.com/data/data-sources/elasticsearch.html Natural language processing: https://docs.databricks.com/applications/nlp/index.html
NEW QUESTION # 48
......
As the tech industry continues to evolve and adapt to new technologies, professionals who hold the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) certification are better equipped to navigate these changes and stay ahead of the curve, increasing their value to employers and clients. In today's fast-paced and ever-changing Databricks sector, having the Databricks Databricks-Certified-Professional-Data-Engineer Certification has become a necessary requirement for individuals looking to advance their careers and stay competitive in the job market.
Databricks-Certified-Professional-Data-Engineer Free Exam Dumps: https://www.actualtorrent.com/Databricks-Certified-Professional-Data-Engineer-questions-answers.html