Databricks-Certified-Data-Engineer-Professional Exam PDF Questions & Trustable Databricks-Certified-Data-Engineer-Professional Test Review Pass Success

The pages of our Databricks-Certified-Data-Engineer-Professional guide torrent provide the demo and you can understand part of our titles and the form of our software. On the pages of our Databricks-Certified-Data-Engineer-Professional exam torrent you can see the version of the product, the updated time, the quantity of the questions and answers, the characteristics and merits of the product, the price of the product and the discounts. The pages also list the details and the guarantee of our Databricks-Certified-Data-Engineer-Professional Exam Torrent, the methods to contact us, the evaluations of the past client on our product, the related exams and other information about our Databricks-Certified-Data-Engineer-Professional guide torrent. So before your purchase you can have an understanding of our product and then decide whether to buy our Databricks-Certified-Data-Engineer-Professional study questions or not.
| Section | Weight | Objectives |
|---|
| Data Governance | 7% | - Enforce data policies and standards
- Use Unity Catalog for governance
- Manage data assets and metadata
|
| Data Transformation, Cleansing, and Quality | 10% | - Apply data cleansing and validation rules
- Enforce data quality standards
- Implement schema evolution and management
|
| Developing Code for Data Processing using Python and SQL | 22% | - Implement complex data processing logic
- Write efficient and maintainable code
- Use Databricks-specific libraries and APIs
|
| Data Sharing and Federation | 5% | - Manage cross-platform data access
- Use Delta Sharing for secure data sharing
- Implement Lakehouse Federation
|
| Ensuring Data Security and Compliance | 10% | - Secure data at rest and in transit
- Ensure data privacy and compliance
- Implement access control and permissions
|
| Data Modelling | 6% | - Optimize table design and partitioning
- Design Medallion Architecture
- Implement dimensional and relational models
|
| Debugging and Deploying | 10% | - Implement CI/CD and DevOps practices
- Deploy using Asset Bundles, CLI, and APIs
- Troubleshoot and debug pipelines
|
| Cost & Performance Optimisation | 13% | - Optimize compute and storage resources
- Improve query and pipeline performance
- Apply cost management best practices
|
| Data Ingestion & Acquisition | 7% | - Handle incremental and batch data loads
- Use Auto Loader and structured streaming
- Ingest data from diverse sources
|
| Monitoring and Alerting | 10% | - Monitor pipeline performance and health
- Track data lineage and metrics
- Set up alerts and notifications
|
>> Databricks-Certified-Data-Engineer-Professional PDF Questions <<
Databricks Databricks-Certified-Data-Engineer-Professional Test Review | Databricks-Certified-Data-Engineer-Professional Sure Pass
Practice what you preach is the beginning of success. Since you have chosen to participate in the demanding IT certification exam. Then you have to pay your actions, and achieve excellent results. Itcerttest's Databricks Databricks-Certified-Data-Engineer-Professional exam training materials are the best training materials for this exam. With it you will have a key to success. Itcerttest's Databricks Databricks-Certified-Data-Engineer-Professional Exam Training materials are absolutely reliable materials. You should believe that you can pass the exam easily, too.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q165-Q170):
NEW QUESTION # 165
A production cluster has 3 executor nodes and uses the same virtual machine type for the driver and executor.
When evaluating the Ganglia Metrics for this cluster, which indicator would signal a bottleneck caused by code executing on the driver?
- A. The five Minute Load Average remains consistent/flat
- B. Total Disk Space remains constant
- C. Bytes Received never exceeds 80 million bytes per second
- D. Network I/O never spikes
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from - E. Overall cluster CPU utilization is around 25%
Answer: E
Explanation:
This is the correct answer because it indicates a bottleneck caused by code executing on the driver. A bottleneck is a situation where the performance or capacity of a system is limited by a single component or resource. A bottleneck can cause slow execution, high latency, or low throughput. A production cluster has 3 executor nodes and uses the same virtual machine type for the driver and executor. When evaluating the Ganglia Metrics for this cluster, one can look for indicators that show how the cluster resources are being utilized, such as CPU, memory, disk, or network. If the overall cluster CPU utilization is around 25%, it means that only one out of the four nodes (driver + 3 executors) is using its full CPU capacity, while the other three nodes are idle or underutilized. This suggests that the code executing on the driver is taking too long or consuming too much CPU resources, preventing the executors from receiving tasks or data to process. This can happen when the code has driver-side operations that are not parallelized or distributed, such as collecting large amounts of data to the driver, performing complex calculations on the driver, or using non-Spark libraries on the driver.
NEW QUESTION # 166
A data engineer is designing a system leveraging Lakeflow Declarative Pipeline technology to process real-time truck telemetry data ingested from JSON files in S3 using Auto Loader. The data includes truck_id, timestamp, location, speed, and fuel_level. The system must support two use cases:
- Near-real-time monitoring of the latest location, speed, and
fuel_level per truck_id for the operations team.
- Daily aggregated reports of total distance traveled and average fuel
efficiency per truck_id for the management team.
Which approach should the data engineer use for streaming tables and materialized views in the Lakeflow Declarative Pipeline to meet these requirements?
- A. Define a streaming table to ingest and store the raw telemetry data, and create a materialized view to compute the latest location, speed, and fuel_level per truck_id for real-time monitoring.
Create another materialized view to compute the daily aggregated distance and fuel efficiency per truck_id for reporting. - B. Define a streaming table to ingest and store the raw telemetry data, and create a streaming table to compute the daily aggregated distance and fuel efficiency per truck_id reporting. Create a materialized view to compute the latest location, speed, and fuel_level per truck_id for real-time monitoring.
- C. Define a materialized view to ingest and store the raw telemetry data, and create a streaming table to compute the latest location, speed, and fuel_level per truck_id for real-time monitoring.Create another materialized view to compute the daily aggregated distance and fuel efficiency per truck_id for reporting.
- D. Define a streaming table to ingest and store the raw telemetry data, and create a streaming table to incrementally compute the latest location, speed, and fuel_level per truck_id for real-time monitoring. Create a materialized view to compute the daily aggregated distance and fuel efficiency per truck_id for reporting.
Answer: D
Explanation:
A streaming table is the right construct to ingest continuously arriving telemetry from Auto Loader.
Computing the latest per truck_id requires near-real-time incremental updates as new events arrive, which is best handled with a downstream streaming table. The daily aggregates are naturally suited to a materialized view, which maintains precomputed results for reporting and refreshes efficiently without requiring a continuously running streaming aggregation for a once- per-day consumption pattern.
NEW QUESTION # 167
A data engineer is brining an existing production Databricks job under asset bundle management and wants to ensure that:
- The job's current configuration is captured as YAML, and all
referenced files are included in their bundle project.
- Future changes to the bundle's YAML will update the existing job in-
place (not create a new job)
How should the data engineer successfully move the production job under asset bundle management?
- A. Run Databricks bundle generate job --existing-job-id to generate the YAML and download referenced files. Then, run Databricks bundle deploy to deploy the bundle, which will always update the existing job automatically.
- B. Export the job definition as JSON, convert it to YAML, and place it in your bundle. Then, run Databricks bundle deploy to update the existing job.
- C. Run databricks bundle generate job --existing-job-id to generate the YAML and download referenced files. Then, run Databricks bundle deployment, bind to link the bundle's job resource to the existing job in Databricks.
- D. Manually create the YAML configuration for the job in your bundle project, ensuring all settings match the existing job. Then, run Databricks bundle deploy the bundle, which will update the existing job in your workspace.
Answer: C
Explanation:
Generating the bundle from the existing job captures the full job configuration as YAML and pulls in all referenced files into the bundle project. Binding the generated job resource to the existing Databricks job establishes a persistent link, ensuring that future bundle deployments update the same production job in place rather than creating a new one.
NEW QUESTION # 168
The data engineering team maintains the following code:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
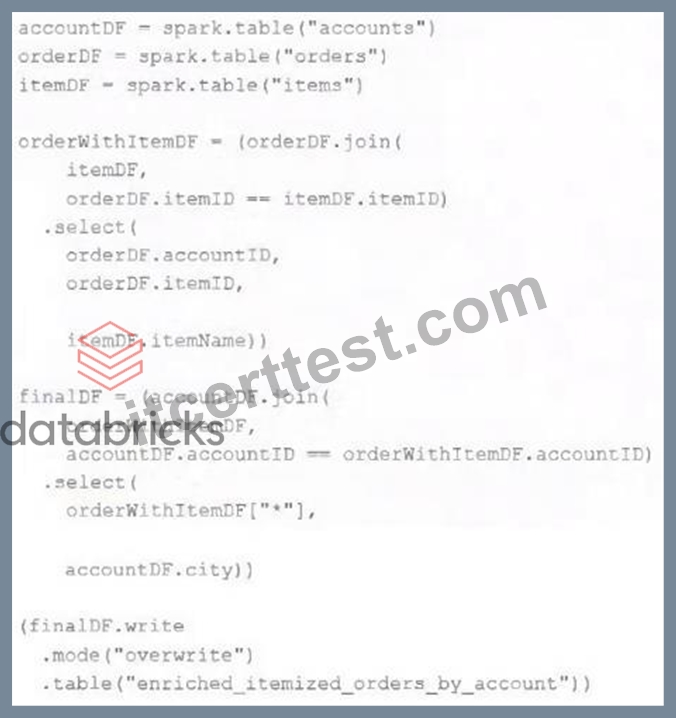
Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. No computation will occur until enriched_itemized_orders_by_account is queried; upon query materialization, results will be calculated using the current valid version of data in each of the three tables referenced in the join logic.
- B. The enriched_itemized_orders_by_account table will be overwritten using the current valid version of data in each of the three tables referenced in the join logic.
- C. An incremental job will detect if new rows have been written to any of the source tables; if new rows are detected, all results will be recalculated and used to overwrite the enriched_itemized_orders_by_account table.
- D. A batch job will update the enriched_itemized_orders_by_account table, replacing only those rows that have different values than the current version of the table, using accountID as the primary key.
- E. An incremental job will leverage information in the state store to identify unjoined rows in the source tables and write these rows to the enriched_iteinized_orders_by_account table.
Answer: B
Explanation:
This is the correct answer because it describes what will occur when this code is executed. The Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from code uses three Delta Lake tables as input sources: accounts, orders, and order_items. These tables are joined together using SQL queries to create a view called new_enriched_itemized_orders_by_account, which contains information about each order item and its associated account details. Then, the code uses write.format("delta").mode("overwrite") to overwrite a target table called enriched_itemized_orders_by_account using the data from the view. This means that every time this code is executed, it will replace all existing data in the target table with new data based on the current valid version of data in each of the three input tables.
NEW QUESTION # 169
All records from an Apache Kafka producer are being ingested into a single Delta Lake table with the following schema:
key BINARY, value BINARY, topic STRING, partition LONG, offset LONG, timestamp LONG There are 5 unique topics being ingested. Only the "registration" topic contains Personal Identifiable Information (PII). The company wishes to restrict access to PII. The company also wishes to only retain records containing PII in this table for 14 days after initial ingestion.
However, for non-PII information, it would like to retain these records indefinitely.
Which of the following solutions meets the requirements?
- A. Because the value field is stored as binary data, this information is not considered PII and no special precautions should be taken.
- B. Data should be partitioned by the registration field, allowing ACLs and delete statements to be set for the PII directory.
- C. Separate object storage containers should be specified based on the partition field, allowing isolation at the storage level.
- D. Data should be partitioned by the topic field, allowing ACLs and delete statements to leverage partition boundaries.
- E. All data should be deleted biweekly; Delta Lake's time travel functionality should be leveraged to maintain a history of non-PII information.
Answer: D
Explanation:
By default partitionning by a column will create a separate folder for each subset data linked to the partition.
NEW QUESTION # 170
......
Itcerttest aims to assist its clients in making them capable of passing the Databricks Databricks-Certified-Data-Engineer-Professional certification exam with flying colors. It fulfills its mission by giving them an entirely free Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) demo of the dumps. Thus, this demonstration will enable them to scrutinize the quality of the Databricks Databricks-Certified-Data-Engineer-Professional study material.
Databricks-Certified-Data-Engineer-Professional Test Review: https://www.itcerttest.com/Databricks-Certified-Data-Engineer-Professional_braindumps.html
- Databricks-Certified-Data-Engineer-Professional Training Courses 🧞 Latest Databricks-Certified-Data-Engineer-Professional Braindumps Files 📒 Authorized Databricks-Certified-Data-Engineer-Professional Certification ⌛ Open website ⮆ www.examcollectionpass.com ⮄ and search for ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ for free download 🍦Accurate Databricks-Certified-Data-Engineer-Professional Test
- Databricks Certified Data Engineer Professional Exam Latest Pdf Material - Databricks-Certified-Data-Engineer-Professional Valid Practice Files - Databricks Certified Data Engineer Professional Exam Updated Study Guide 🙃 Simply search for 「 Databricks-Certified-Data-Engineer-Professional 」 for free download on ⇛ www.pdfvce.com ⇚ 👌Latest Databricks-Certified-Data-Engineer-Professional Dumps Questions
- Exam Databricks-Certified-Data-Engineer-Professional Overview 🆖 Latest Databricks-Certified-Data-Engineer-Professional Dumps Questions 🔈 Exams Databricks-Certified-Data-Engineer-Professional Torrent 💮 Open ⏩ www.practicevce.com ⏪ enter 《 Databricks-Certified-Data-Engineer-Professional 》 and obtain a free download ✉Databricks-Certified-Data-Engineer-Professional Exam Book
- 2026 Databricks Marvelous Databricks-Certified-Data-Engineer-Professional PDF Questions 🚟 Open ➠ www.pdfvce.com 🠰 enter ▷ Databricks-Certified-Data-Engineer-Professional ◁ and obtain a free download 🤍Test Databricks-Certified-Data-Engineer-Professional Study Guide
- Databricks-Certified-Data-Engineer-Professional PDF Questions - Pass Guaranteed Quiz 2026 Databricks-Certified-Data-Engineer-Professional: First-grade Databricks Certified Data Engineer Professional Exam Test Review ✨ Copy URL ➽ www.examcollectionpass.com 🢪 open and search for ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ to download for free 🩺Test Databricks-Certified-Data-Engineer-Professional Study Guide
- Databricks-Certified-Data-Engineer-Professional Reliable Braindumps Ppt 🚧 Databricks-Certified-Data-Engineer-Professional Actual Test 🛷 Exams Databricks-Certified-Data-Engineer-Professional Torrent 🎋 Search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ and obtain a free download on ⏩ www.pdfvce.com ⏪ 🚹Latest Databricks-Certified-Data-Engineer-Professional Dumps Questions
- Databricks-Certified-Data-Engineer-Professional Test Preparation 🐽 Exams Databricks-Certified-Data-Engineer-Professional Torrent 🥵 Latest Test Databricks-Certified-Data-Engineer-Professional Experience 🔭 Search for ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ and easily obtain a free download on 「 www.examdiscuss.com 」 💬Databricks-Certified-Data-Engineer-Professional Best Preparation Materials
- New Databricks-Certified-Data-Engineer-Professional Test Sample ⏭ Databricks-Certified-Data-Engineer-Professional Test Preparation 🐃 Latest Databricks-Certified-Data-Engineer-Professional Dumps Questions 🥋 Search for ➠ Databricks-Certified-Data-Engineer-Professional 🠰 and obtain a free download on ▶ www.pdfvce.com ◀ 🎡Exam Databricks-Certified-Data-Engineer-Professional Overview
- 100% Pass 2026 Fantastic Databricks Databricks-Certified-Data-Engineer-Professional PDF Questions 🔖 Copy URL ➥ www.practicevce.com 🡄 open and search for ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ to download for free 🔋Latest Databricks-Certified-Data-Engineer-Professional Dumps Questions
- 100% Pass Databricks - Valid Databricks-Certified-Data-Engineer-Professional PDF Questions 🦏 Simply search for ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ for free download on ⮆ www.pdfvce.com ⮄ 😚Reliable Databricks-Certified-Data-Engineer-Professional Test Simulator
- Databricks-Certified-Data-Engineer-Professional Best Preparation Materials 🌻 Authorized Databricks-Certified-Data-Engineer-Professional Certification 👜 Exams Databricks-Certified-Data-Engineer-Professional Torrent 🌷 Search for ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ and download it for free on ✔ www.prepawaypdf.com ️✔️ website ⬅Databricks-Certified-Data-Engineer-Professional Test Preparation
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.dibiz.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes