You will notice the above features in the Microsoft DP-750 Web-based format too. But the difference is that it is suitable for all operating systems. There is no need to go through time-taking installations or agitating plugins to use this format. It will lead to your convenience while preparing for the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification test. Above all, it operates on all browsers.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Topic 2: Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Topic 3: Prepare and process data | 30-35% | - Data transformation and modeling
|
| Topic 4: Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
To get success in exams and especially in a professional certification test like the Implementing Data Engineering Solutions Using Azure Databricks DP-750 test is very important to build a bright career. People from all over the world can get the best-paying jobs after passing the Microsoft DP-750 Exam. So ExamDiscuss will help you to study well for the Implementing Data Engineering Solutions Using Azure Databricks DP-750 certification exam. And price is benefit and reliable.
NEW QUESTION # 34
You have an Azure Databricks workspace that contains the objects shown in the following table.
Name | Type
Catalog1 | Catalog
Schema1 | Schema
Sales1 | Table
Notebook1 | Notebook
Space1 | AI/BI Genie space
Users often use the following words to refer to a sale: transaction, event, order, and invoice.
You need to create a knowledge store. The solution must ensure that when the users use any of the words in Space1, Genie queries the Sales1 table. Any other Genie spaces must remain unaffected.
To which object should you add the instructions?
Answer: D
Explanation:
The instructions must be added to Space1 because a Genie knowledge store is scoped to the individual Genie space, now called a Genie Agent. Adding synonyms and business-language instructions there teaches Space1 that "transaction," "event," "order," and "invoice" refer to sales information in Sales1. The configuration affects only that Genie space, satisfying the requirement that other spaces remain unchanged. Adding instructions to Sales1 or Schema1 would modify shared Unity Catalog metadata and could affect other consumers of those objects. Notebook1 is unrelated to the semantic instructions used by Genie when converting natural-language questions into SQL. Genie knowledge stores contain space-specific definitions, synonyms, join relationships, SQL expressions, and prompt-matching guidance without changing the underlying Unity Catalog objects. Microsoft Learn
NEW QUESTION # 35
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 processes raw data files stored in Azure Storage.
New files arrive at unpredictable intervals.
You need to ensure that Job1 starts automatically when new files arrive and does NOT consume compute resources when no data is available.
Which type of job trigger should you use?
Answer: A
Explanation:
The File arrival trigger is exactly what you need for this use case. It natively solves your problem by launching a job the moment new files land in your Azure Storage container, automatically scaling down to zero compute when no data is processing.
Event-Driven: Instead of relying on a time-based schedule (cron) that wastes resources, the Lakeflow Job monitors the specific Azure location and starts exactly when new data appears.
Zero Idle Compute: You can use serverless compute or an ephemeral job cluster that spins up just for the duration of the run and terminates immediately after, meaning zero billing during downtime.
Cloud Cost Efficient: Listing files to detect new arrivals is typically free or fractions of a cent (only incurring minimal cloud provider API costs for listing the storage location).
Reference:
https://learn.microsoft.com/en-us/azure/databricks/jobs/file-arrival-triggers
NEW QUESTION # 36
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.dropna(subset=["order_amount"])
Does this meet the goal?
Answer: A
Explanation:
Correct:
* You run the following expression.
df.dropna(subset=["order_amount"])
The expression df.dropna(subset=["order_amount"]) is an appropriate and effective way to exclude rows where order_amount is null.
* You run the following expression.
df.filter(df.order_amount.isNotNull())
To exclude rows where the order amount is null, you can use the isNotNull() method or a SQL expression within the filter() or where() functions.Here are the standard, appropriate expressions:
Option 1: Python/PySpark API (Recommended)
pythondf_clean = df.filter(df["order_amount"].isNotNull())
Incorrect:
* You run the following expression.
df.fillna(0, subset=['order_amount'])
* You run the following expression.
df.filter(df.order_amount != None)
Reference:
https://www.geeksforgeeks.org/python/filter-pyspark-dataframe-columns-with-none-or-null-values/
https://learn.microsoft.com/en-us/azure/databricks/pyspark/reference/classes/dataframe/dropna
NEW QUESTION # 37
You have an Azure Databricks workspace that contains a Git folder and uses Azure Repos as the Git provider.
From the main branch, you create a branch named Branch1. You commit changes to Branch1.
You need to incorporate the changes from Branch1 into main The solution must preserve the commit history in the repository. Which command should you run?
Answer: A
Explanation:
The correct answer is A - merge.
A Git merge combines the histories of two branches by creating a merge commit that joins them. Every individual commit from Branch1 remains visible in the repository log - the full development history is preserved. This is the requirement: 'the solution must preserve the commit history in the repository.' Option C (rebase) moves Branch1's commits on top of main by replaying them as new commits with new hashes. The end result looks like a linear history, but the original commit hashes are rewritten - the prior history is not preserved in its original form. For a shared repository, rebase rewrites public history, which is considered problematic.
Option B (pull) fetches remote changes and merges or rebases them into the current branch - it's used to sync with a remote, not to incorporate a feature branch. Option D (push) sends local commits to the remote but doesn't incorporate any branch into another.
Reference: https://learn.microsoft.com/en-us/azure/databricks/repos/git-operations-with-repos
NEW QUESTION # 38
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.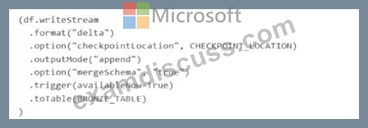
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.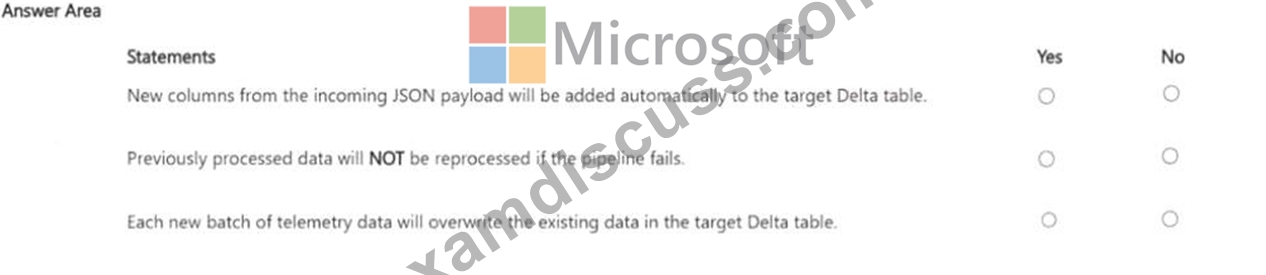
Answer:
Explanation: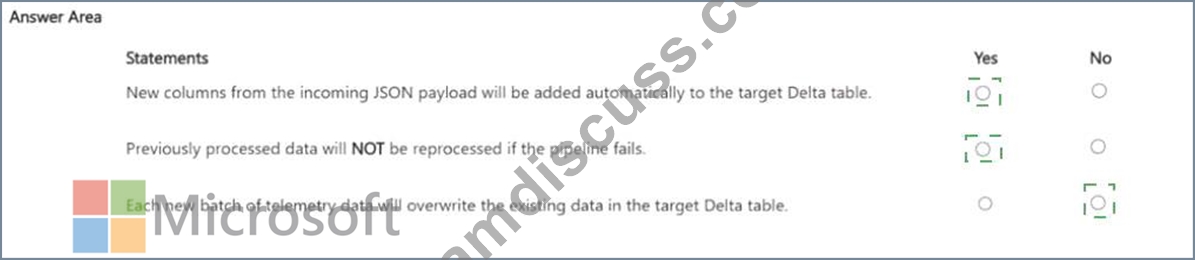
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: ' overwrite ' replaces existing data; ' append ' adds to it.
Always check whether the code uses the correct Delta format (.format( ' delta ' )), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 39
......
Our DP-750 exam questions just focus on what is important and help you achieve your goal. When the reviewing process gets some tense, our DP-750 practice materials will solve your problems with efficiency. With high-quality DP-750 Guide materials and flexible choices of learning mode, they would bring about the convenience and easiness for you. Every page is carefully arranged by our experts with clear layout and helpful knowledge to remember.
DP-750 Latest Study Questions: https://www.examdiscuss.com/Microsoft/exam/DP-750/