What's more, part of that RealVCE Databricks-Certified-Professional-Data-Engineer dumps now are free: https://drive.google.com/open?id=1PWNoX4CPz9i5w6d_f6tMnT6sw1WQS6g5
Databricks Databricks-Certified-Professional-Data-Engineer exam torrent is famous for instant download. You will receive downloading link and password within ten minutes, and if you don’t receive, just contact us, we will check for you. In addition, Databricks-Certified-Professional-Data-Engineer Exam Materials are high quality, it covers major knowledge points for the exam, you can have an easy study if you choose us.
| Section | Objectives |
|---|---|
| Production Pipelines and Orchestration | - Pipeline reliability and fault tolerance - Build and manage workflows using Databricks Jobs - Automate ETL pipelines and scheduling |
| Security, Governance, Monitoring, and Optimization | - Monitor and optimize Spark workloads - Cost optimization and performance tuning - Implement Unity Catalog governance and access control |
| Data Modeling and Storage | - Delta Lake table design and optimization - Schema evolution and data partitioning strategies - Design scalable data lakehouse architectures |
| Data Ingestion and Transformation | - Ingest data using Apache Spark and Databricks - Transform and clean datasets using Spark SQL and DataFrame APIs - Handle batch and streaming data pipelines |
>> Databricks-Certified-Professional-Data-Engineer Study Center <<
With our Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) study material, you'll be able to make the most of your time to ace the test. Despite what other courses might tell you, let us prove that studying with us is the best choice for passing your Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) certification exam! If you want to increase your chances of success and pass your Databricks-Certified-Professional-Data-Engineer exam, start learning with us right away!
NEW QUESTION # 114
A data engineer wants to reflector the following DLT code, which includes multiple definition with very similar code: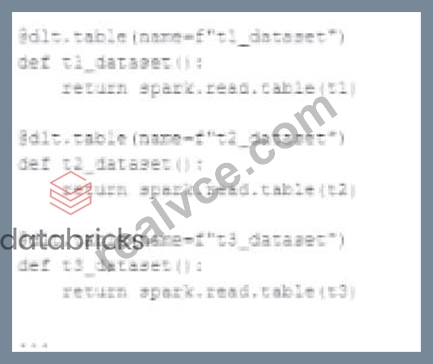
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.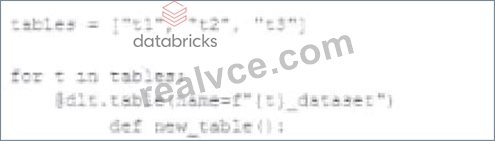
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for tables.
How can the data engineer fix this?
Answer: B
Explanation:
The issue with the refactored code is that it tries to use string interpolation to dynamically create table names within the dlc.table decorator, which will not correctly interpret the table names. Instead, by using a dictionary with table names as keys and their configurations as values, the data engineer can iterate over the dictionary items and use the keys (table names) to properly configure the table settings. This way, the decorator can correctly recognize each table name, and the corresponding configuration settings can be applied appropriately.
NEW QUESTION # 115
An engineering manager uses a Databricks SQL query to monitor their team's progress on fixes related to
customer-reported bugs. The manager checks the results of the query every day, but they are manually
rerunning the query each day and waiting for the results.
Which of the following approaches can the manager use to ensure the results of the query are up-dated each
day?
Answer: A
NEW QUESTION # 116
A data engineering team is configuring access controls in Databricks Unity Catalog. They grant the SELECT privilege on the sales catalog to the analyst_group, expecting that members of this group will automatically have SELECT access to all current and future schemas, tables, and views within the catalog.
What describes the privilege inheritance behavior in Unity Catalog?
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
In Unity Catalog, privileges are non-cascading-meaning that granting a privilege (like SELECT) on a catalog does not automatically grant the same privilege on contained objects (schemas, tables, or views). Each object type has its own independent access control hierarchy.
According to the Databricks access control documentation: "Privileges do not automatically cascade from catalog to schema or table levels." Administrators must explicitly grant privileges on each level if users need access across objects. This design ensures tighter governance and least-privilege enforcement. Therefore, option B correctly describes Unity Catalog's privilege model, while A and D incorrectly imply automatic inheritance.
NEW QUESTION # 117
A data architect is designing a Databricks solution to efficiently process data for different business requirements.
In which scenario should a data engineer use a materialized view compared to a streaming table ?
Answer: D
Explanation:
Materialized views in Databricks are optimized for precomputing and caching results of complex SQL queries, joins, and aggregations. They store query outputs physically and automatically refresh on a schedule or incremental change basis, drastically improving BI dashboard performance and reducing compute costs.
Conversely, streaming tables are designed for real-time data ingestion and processing , enabling event- driven analytics and low-latency use cases.
Databricks documentation explicitly recommends materialized views for analytical workloads with periodic updates and streaming tables for continuously updating sources. Therefore, the correct choice is C , where complex aggregations from large tables benefit most from materialized precomputation for fast reporting.
NEW QUESTION # 118
A Structured Streaming job deployed to production has been experiencing delays during peak hours of the day.
At present, during normal execution, each microbatch of data is processed in less than 3 seconds. During peak hours of the day, execution time for each microbatch becomes very inconsistent, sometimes exceeding 30 seconds. The streaming write is currently configured with a trigger interval of 10 seconds.
Holding all other variables constant and assuming records need to be processed in less than 10 seconds, which adjustment will meet the requirement?
Answer: C
Explanation:
The adjustment that will meet the requirement of processing records in less than 10 seconds is to decrease the trigger interval to 5 seconds. This is because triggering batches more frequently may prevent records from backing up and large batches from causing spill. Spill is a phenomenon where the data in memory exceeds the available capacity and has to be written to disk, which can slow down the processing and increase the execution time1. By reducing the trigger interval, the streaming query can process smaller batches of data more quickly and avoid spill. This can also improve the latency and throughput of the streaming job2.
The other options are not correct, because:
* Option A is incorrect because triggering batches more frequently does not allow idle executors to begin processing the next batch while longer running tasks from previous batches finish. In fact, the opposite is true. Triggering batches more frequently may cause concurrent batches to compete for the same resources and cause contention and backpressure2. This can degrade the performance and stability of the streaming job.
* Option B is incorrect because increasing the trigger interval to 30 seconds is not a good practice to ensure no records are dropped. Increasing the trigger interval means that the streaming query will process larger batches of data less frequently, which can increase the risk of spill, memory pressure, and timeouts12. This can also increase the latency and reduce the throughput of the streaming job.
* Option C is incorrect because the trigger interval can be modified without modifying the checkpoint directory. The checkpoint directory stores the metadata and state of the streaming query, such as the offsets, schema, and configuration3. Changing the trigger interval does not affect the state of the streaming query, and does not require a new checkpoint directory. However, changing the number of shuffle partitions may affect the state of the streaming query, and may require a new checkpoint directory4.
* Option D is incorrect because using the trigger once option and configuring a Databricks job to execute the query every 10 seconds does not ensure that all backlogged records are processed with each batch. The trigger once option means that the streaming querywill process all the available data in the source and then stop5. However, this does not guarantee that the query will finish processing within 10 seconds, especially if there are a lot of records in the source. Moreover, configuring a Databricks job to execute the query every 10 seconds may cause overlapping or missed batches, depending on the execution time of the query.
References: Memory Management Overview, Structured Streaming Performance Tuning Guide, Checkpointing, Recovery Semantics after Changes in a Streaming Query, Triggers
NEW QUESTION # 119
......
The format name of Databricks Databricks-Certified-Professional-Data-Engineer practice test questions is Databricks PDF Questions file, desktop practice test software, and web-based practice test software. Choose the nay type of Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer Practice Exam Questions that fit your Databricks-Certified-Professional-Data-Engineer exam preparation requirement and budget and start preparation without wasting further time.
Test Databricks-Certified-Professional-Data-Engineer Valid: https://www.realvce.com/Databricks-Certified-Professional-Data-Engineer_free-dumps.html
What's more, part of that RealVCE Databricks-Certified-Professional-Data-Engineer dumps now are free: https://drive.google.com/open?id=1PWNoX4CPz9i5w6d_f6tMnT6sw1WQS6g5