P.S. Free 2026 Google Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by ActualTorrent: https://drive.google.com/open?id=1I7OHWZAwpS0kq-wvAVTfv8YaEpHu6Qhm
Windows computers support the desktop practice test software. ActualTorrent has a complete support team to fix issues of Google Professional-Machine-Learning-Engineer PRACTICE TEST software users. ActualTorrent practice tests (desktop and web-based) produce score report at the end of each attempt. So, that users get awareness of their Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) preparation status and remove their mistakes.
| Section | Objectives |
|---|---|
| ML pipeline automation and orchestration | - Pipeline design
|
| ML model development | - Model training and tuning
|
| Data preparation and processing | - Feature engineering
|
| Deployment and operations | - Model deployment
|
| Designing ML solutions | - ML architecture design
|
>> Valid Professional-Machine-Learning-Engineer Exam Dumps <<
We believe that the best brands are those that go beyond expectations. They don't just do the job – they go deeper and become the fabric of our lives. Therefore, our company as the famous brand, even though we have been very successful we have never satisfied with the status quo, and always be willing to constantly update the contents of our Professional-Machine-Learning-Engineer Exam Torrent in order to keeps latest information about Professional-Machine-Learning-Engineer exam.
NEW QUESTION # 127
You trained a text classification model. You have the following SignatureDefs: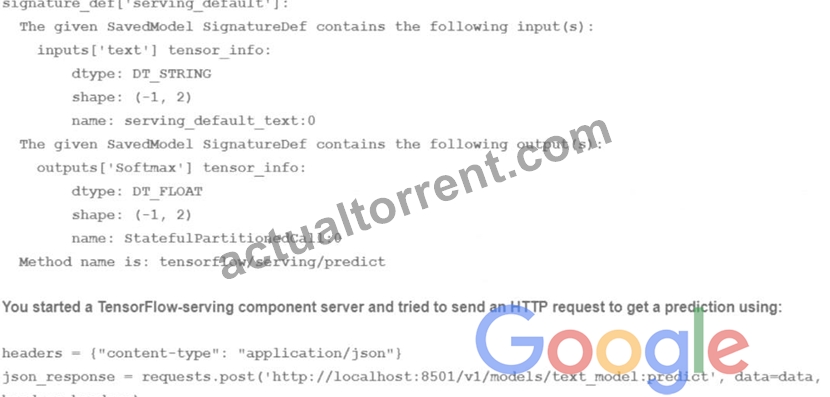
What is the correct way to write the predict request?
Answer: B
Explanation:
A predict request is a way to send data to a trained model and get predictions in return. A predict request can be written in different formats, such as JSON, protobuf, or gRPC, depending on the service and the platform that are used to host and serve the model. A predict request usually contains the following information:
* The signature name: This is the name of the signature that defines the inputs and outputs of the model.
A signature is a way to specify the expected format, type, and shape of the data that the model can accept and produce. A signature can be specified when exporting or saving the model, or it can be automatically inferred by the service or the platform. A model can have multiple signatures, but only one can be used for each predict request.
* The instances: This is the data that is sent to the model for prediction. The instances can be a single instance or a batch of instances, depending on the size and shape of the data. The instances should match the input specification of the signature, such as the number, name, and type of the input tensors.
For the use case of training a text classification model, the correct way to write the predict request is D. data = json.dumps({"signature_name": "serving_default", "instances": [['a', 'b'], ['c', 'd'], ['e', 'f']]}) This option involves writing the predict request in JSON format, which is a common and convenient format for sending and receiving data over the web. JSON stands for JavaScript Object Notation, and it is a way to represent data as a collection of name-value pairs or an ordered list of values. JSON can be easily converted to and from Python objects using the json module.
This option also involves using the signature name "serving_default", which is the default signature name that is assigned to the model when it is saved or exported without specifying a custom signature name. The serving_default signature defines the input and output tensors of the model based on the SignatureDef that is shown in the image. According to the SignatureDef, the model expects an input tensor called "text" that has a shape of (-1, 2) and a type of DT_STRING, and produces an output tensor called "softmax" that has a shape of (-1, 2) and a type of DT_FLOAT. The -1 in the shape indicates that the dimension can vary depending on the number of instances, and the 2 indicates that the dimension is fixed at 2. The DT_STRING and DT_FLOAT indicate that the data type is string and float, respectively.
This option also involves sending a batch of three instances to the model for prediction. Each instance is a list of two strings, such as ['a', 'b'], ['c', 'd'], or ['e', 'f']. These instances match the input specification of the signature, as they have a shape of (3, 2) and a type of string. The model will process these instances and produce a batch of three predictions, each with a softmax output that has a shape of (1, 2) and a type of float.
The softmax output is a probability distribution over the two possible classes that the model can predict, such as positive or negative sentiment.
Therefore, writing the predict request as data = json.dumps({"signature_name": "serving_default",
"instances": [['a', 'b'], ['c', 'd'], ['e', 'f']]}) is the correct and valid way to send data to the text classification model and get predictions in return.
References:
* [json - JSON encoder and decoder]
NEW QUESTION # 128
You work for a gaming company that develops massively multiplayer online (MMO) games. You built a TensorFlow model that predicts whether players will make in-app purchases of more than $10 in the next two weeks. The model's predictions will be used to adapt each user's game experience. User data is stored in BigQuery. How should you serve your model while optimizing cost, user experience, and ease of management?
Answer: C
Explanation:
The best option to serve the model while optimizing cost, user experience, and ease of management is to deploy the model to Vertex AI Prediction, which is a managed service that can scale up or down according to the demand and provide low latency and high availability. Vertex AI Prediction can also handle TensorFlow models natively, without requiring any additional steps or conversions. By using batch prediction, the model can process large volumes of data efficiently and periodically, without affecting the user experience. The data can be read from Cloud Bigtable, which is a scalable and performant NoSQL database that can store user data in a flexible schema. The predictions can then be pushed to Cloud SQL, which is a fully managed relational database that can store the predictions in a structured format and enable easy querying and analysis. This option also simplifies the management of the model and the data, as it leverages the existing Google Cloud services and does not require any additional infrastructure or code.
The other options are not optimal for the following reasons:
* A. Importing the model into BigQuery ML is not a good option, as it requires converting the TensorFlow model into a format that BigQuery ML can understand, which can introduce errors and reduce the performance. Moreover, BigQuery ML is not designed for serving real-time predictions, but rather for training and evaluating models using SQL queries. Reading and writing data from BigQuery and Cloud SQL can also incur additional costs and latency, as they are both relational databases that require schema definition and data transformation.
* C. Embedding the model in the mobile application is not a good option, as it increases the size and
* complexity of the application, and requires updating the application every time the model changes.
Moreover, it exposes the model to the users, which can pose security and privacy risks, as well as potential misuse or abuse. Additionally, it does not leverage the benefits of the cloud, such as scalability, reliability, and performance.
* D. Embedding the model in the streaming Dataflow pipeline is not a good option, as it requires building and maintaining a custom pipeline that can handle the model inference and data processing. This can increase the development and operational costs and complexity, as well as the potential for errors and failures. Moreover, it does not take advantage of the batch prediction feature of Vertex AI Prediction, which can optimize the resource utilization and cost efficiency.
References:
* Professional ML Engineer Exam Guide
* Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate
* Google Cloud launches machine learning engineer certification
* Vertex AI Prediction documentation
* Cloud Bigtable documentation
* Cloud SQL documentation
NEW QUESTION # 129
You are training a Resnet model on Al Platform using TPUs to visually categorize types of defects in automobile engines. You capture the training profile using the Cloud TPU profiler plugin and observe that it is highly input-bound. You want to reduce the bottleneck and speed up your model training process. Which modifications should you make to the tf .data dataset?
Choose 2 answers
Answer: B,E
Explanation:
The tf.data dataset is a TensorFlow API that provides a way to create and manipulate data pipelines for machine learning. The tf.data dataset allows you to apply various transformations to the data, such as reading, shuffling, batching, prefetching, and interleaving. These transformations can affect the performance and efficiency of the model training process1 One of the common performance issues in model training is input-bound, which means that the model is waiting for the input data to be ready and is not fully utilizing the computational resources. Input-bound can be caused by slow data loading, insufficient parallelism, or large data size. Input-bound can be detected by using the Cloud TPU profiler plugin, which is a tool that helps you analyze the performance of your model on Cloud TPUs. The Cloud TPU profiler plugin can show you the percentage of time that the TPU cores are idle, which indicates input-bound2 To reduce the input-bound bottleneck and speed up the model training process, you can make some modifications to the tf.data dataset. Two of the modifications that can help are:
Use the interleave option for reading data. The interleave option allows you to read data from multiple files in parallel and interleave their records. This can improve the data loading speed and reduce the idle time of the TPU cores. The interleave option can be applied by using the tf.data.Dataset.interleave method, which takes a function that returns a dataset for each input element, and a number of parallel calls3 Set the prefetch option equal to the training batch size. The prefetch option allows you to prefetch the next batch of data while the current batch is being processed by the model. This can reduce the latency between batches and improve the throughput of the model training. The prefetch option can be applied by using the tf.data.Dataset.prefetch method, which takes a buffer size argument. The buffer size should be equal to the training batch size, which is the number of examples per batch4 The other options are not effective or counterproductive. Reducing the value of the repeat parameter will reduce the number of epochs, which is the number of times the model sees the entire dataset. This can affect the model's accuracy and convergence. Increasing the buffer size for the shuffle option will increase the randomness of the data, but also increase the memory usage and the data loading time. Decreasing the batch size argument in your transformation will reduce the number of examples per batch, which can affect the model's stability and performance.
NEW QUESTION # 130
You are an AI architect at a popular photo-sharing social media platform. Your organization's content moderation team currently scans images uploaded by users and removes explicit images manually. You want to implement an AI service to automatically prevent users from uploading explicit images. What should you do?
Answer: C
Explanation:
Cloud Vision API offers pre-trained models specialized in identifying explicit or inappropriate content. By sending a copy of each image to a Cloud Storage bucket and triggering Cloud Vision through Cloud Run, the detection of explicit content is automated with minimal development time. Vertex AI custom models require more training data and infrastructure management, while AutoML-based solutions add more complexity. Cloud Vision's existing capabilities meet the requirement effectively and are highly scalable for real-time moderation needs.
NEW QUESTION # 131
Your data science team has requested a system that supports scheduled model retraining, Docker containers, and a service that supports autoscaling and monitoring for online prediction requests. Which platform components should you choose for this system?
Answer: B
NEW QUESTION # 132
......
When you see other people in different industry who feel relaxed with high salary, do you want to try another field? And is the difficulty of learning a new piece of knowledge often deterring you? It doesn't matter, now Professional-Machine-Learning-Engineer practice exam offers you a great opportunity to enter a new industry. Our Professional-Machine-Learning-Engineer learning material was compiled from the wisdom and sweat of many industry experts. And it is easy to learn and understand our Professional-Machine-Learning-Engineer exam questions.
Exam Professional-Machine-Learning-Engineer Assessment: https://www.actualtorrent.com/Professional-Machine-Learning-Engineer-questions-answers.html
BONUS!!! Download part of ActualTorrent Professional-Machine-Learning-Engineer dumps for free: https://drive.google.com/open?id=1I7OHWZAwpS0kq-wvAVTfv8YaEpHu6Qhm