2026 Latest iPassleader Databricks-Generative-AI-Engineer-Associate PDF Dumps and Databricks-Generative-AI-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=16VNEvqtrnyksagiOZT9-5aILoAzBZzMJ
With the rapid development of the economy, the demands of society on us are getting higher and higher. If you can have Databricks-Generative-AI-Engineer-Associate certification, then you will be more competitive in society. Our Databricks-Generative-AI-Engineer-Associate study materials will help you get the according certification. Believe me, after using our Databricks-Generative-AI-Engineer-Associate Study Materials, you will improve your work efficiency. Our Databricks-Generative-AI-Engineer-Associate free training materials will make you more prominent in the labor market than others, and more opportunities will take the initiative to find you.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate Exam |
| Exam Number: | Databricks-Generative-AI-Engineer-Associate |
| Passing Score: | 700/1000 or 70% |
| Available Languages: | Japanese, English, Korean, Brazilian Portuguese |
| Exam Duration: | 90 minutes |
| Certificate Validity Period: | 2 years |
| Real Exam Qty: | 45 |
| Exam Price: | USD 200 |
| Exam Format: | Multiple choice |
| Recommended Training: | Generative AI Engineering with Databricks |
| Exam Registration: | Databricks Certification Registration |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online proctored or in-person test center |
| Pre Condition: | No formal prerequisites; recommended 6+ months hands-on experience building generative AI solutions |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/genai-engineer-associate |
>> Databricks-Generative-AI-Engineer-Associate Accurate Test <<
Perhaps you are in a bad condition and need help to solve all the troubles. Don’t worry, once you realize economic freedom, nothing can disturb your life. Our Databricks-Generative-AI-Engineer-Associate exam questions can help you out. Learning is the best way to make money. So you need to learn our Databricks-Generative-AI-Engineer-Associate guide materials carefully after you have paid for them. And in fact, our Databricks-Generative-AI-Engineer-Associate Practice Braindumps are quite interesting and enjoyable for our professionals have compiled them carefully with the latest information and also designed them to different versions to your needs.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 56
A company has a typical RAG-enabled, customer-facing chatbot on its website.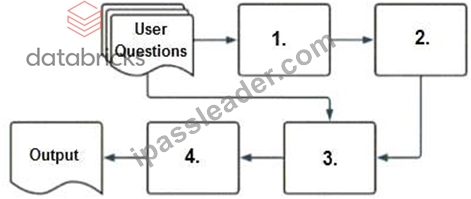
Select the correct sequence of components a user's questions will go through before the final output is returned. Use the diagram above for reference.
Answer: D
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user's question, let's go through the correct sequence as depicted in the diagram and explained in option A:
* Embedding Model (1):The first step involves the user's question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
* Vector Search (2):The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
* Context-Augmented Prompt (3):The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
* Response-Generating LLM (4):Finally, the context-augmented prompt is fed into a response- generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable:
* B, C, D: These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence isembedding model, vector search, context-augmented prompt, response- generating LLM, which is option A.
NEW QUESTION # 57
A Generative Al Engineer is developing a RAG application and would like to experiment with different embedding models to improve the application performance.
Which strategy for picking an embedding model should they choose?
Answer: C
Explanation:
The task involves improving a Retrieval-Augmented Generation (RAG) application's performance by experimenting with embedding models. The choice of embedding model impacts retrieval accuracy, which is critical for RAG systems. Let's evaluate the options based on Databricks Generative AI Engineer best practices.
* Option A: Pick an embedding model trained on related domain knowledge
* Embedding models trained on domain-specific data (e.g., industry-specific corpora) produce vectors that better capture the semantics of the application's context, improving retrieval relevance. For RAG, this is a key strategy to enhance performance.
* Databricks Reference : " For optimal retrieval in RAG systems, select embedding models aligned with the domain of your data " ( " Building LLM Applications with Databricks, " 2023).
* Option B: Pick the most recent and most performant open LLM released at the time
* LLMs are not embedding models; they generate text, not embeddings for retrieval. While recent LLMs may be performant for generation, this doesn't address the embedding step in RAG. This option misunderstands the component being selected.
* Databricks Reference : Embedding models and LLMs are distinct in RAG workflows: " Embedding models convert text to vectors, while LLMs generate responses " ( " Generative AI Cookbook " ).
* Option C: Pick the embedding model ranked highest on the Massive Text Embedding Benchmark (MTEB) leaderboard hosted by HuggingFace
* The MTEB leaderboard ranks models across general tasks, but high overall performance doesn't guarantee suitability for a specific domain. A top-ranked model might excel in generic contexts but underperform on the engineer's unique data.
* Databricks Reference : General performance is less critical than domain fit: " Benchmark rankings provide a starting point, but domain-specific evaluation is recommended " ( " Databricks Generative AI Engineer Guide " ).
* Option D: Pick an embedding model with multilingual support to support potential multilingual user questions
* Multilingual support is useful only if the application explicitly requires it. Without evidence of multilingual needs, this adds complexity without guaranteed performance gains for the current use case.
* Databricks Reference : " Choose features like multilingual support based on application requirements " ( " Building LLM-Powered Applications " ).
Conclusion : Option A is the best strategy because it prioritizes domain relevance, directly improving retrieval accuracy in a RAG system-aligning with Databricks' emphasis on tailoring models to specific use cases.
NEW QUESTION # 58
A Generative AI Engineer I using the code below to test setting up a vector store: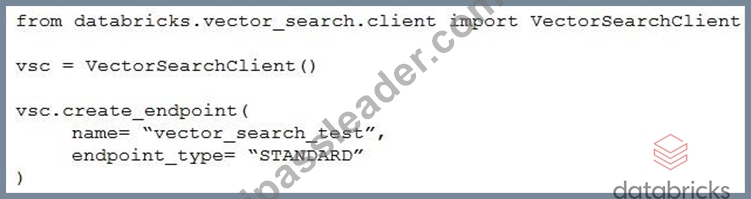
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: C
Explanation:
* Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
* Explanation of Options:
Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, hence Option B.
NEW QUESTION # 59
A Generative AI Engineer is evaluating a customer-support agent in Databricks. The team needs to score each response on a domain-specific policy: the answer must cite an approved refund rule and must not mention unsupported escalation paths. Built-in evaluation metrics do not capture this logic. The team wants the metric to run during agent evaluation in Databricks and return a repeatable, structured score for each trace.
Which approach should the engineer use?
Answer: A
Explanation:
MLflow supports custom scorers for application-specific evaluation requirements that built-in metrics do not address. The engineer can define a scorer that examines the generated answer and, when necessary, the complete execution trace. It can verify references against an approved refund-rule list and check whether escalation statements violate the policy. The scorer returns structured feedback, such as a Boolean result, numerical score, or Feedback object, and is supplied to mlflow.genai.evaluate(). Deterministic checks are appropriate when repeatability is essential; semantic checks may require a carefully specified judge. Latency and token counts measure operational behavior rather than policy compliance. Reviewing traces manually does not create an automated metric, and the generating model's self-assessment is not an independent compliance evaluation. Databricks documentation
NEW QUESTION # 60
A Generative Al Engineer has built an LLM-based system that will automatically translate user text between two languages. They now want to benchmark multiple LLM's on this task and pick the best one. They have an evaluation set with known high quality translation examples. They want to evaluate each LLM using the evaluation set with a performant metric.
Which metric should they choose for this evaluation?
Answer: A
Explanation:
The task is to benchmark LLMs for text translation using an evaluation set with known high-quality examples, requiring a performant metric. Let's evaluate the options.
Option A: ROUGE metric
ROUGE (Recall-Oriented Understudy for Gisting Evaluation) measures overlap between generated and reference texts, primarily for summarization. It's less suited for translation, where precision and word order matter more.
Databricks Reference: "ROUGE is commonly used for summarization, not translation evaluation" ("Generative AI Cookbook," 2023).
Option B: BLEU metric
BLEU (Bilingual Evaluation Understudy) evaluates translation quality by comparing n-gram overlap with reference translations, accounting for precision and brevity. It's widely used, performant, and appropriate for this task.
Databricks Reference: "BLEU is a standard metric for evaluating machine translation, balancing accuracy and efficiency" ("Building LLM Applications with Databricks").
Option C: NDCG metric
NDCG (Normalized Discounted Cumulative Gain) assesses ranking quality, not text generation. It's irrelevant for translation evaluation.
Databricks Reference: "NDCG is suited for ranking tasks, not generative output scoring" ("Databricks Generative AI Engineer Guide").
Option D: RECALL metric
Recall measures retrieved relevant items but doesn't evaluate translation quality (e.g., fluency, correctness). It's incomplete for this use case.
Databricks Reference: No specific extract, but recall alone lacks the granularity of BLEU for text generation tasks.
Conclusion: Option B (BLEU) is the best metric for translation evaluation, offering a performant and standard approach, as endorsed by Databricks' guidance on generative tasks.
NEW QUESTION # 61
......
Reliable Databricks-Generative-AI-Engineer-Associate Test Materials: https://www.ipassleader.com/Databricks/Databricks-Generative-AI-Engineer-Associate-practice-exam-dumps.html
BTW, DOWNLOAD part of iPassleader Databricks-Generative-AI-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=16VNEvqtrnyksagiOZT9-5aILoAzBZzMJ