Realistic Databricks Databricks-Machine-Learning-Professional Questions with Multiple Offers
P.S. Free & New Databricks-Machine-Learning-Professional dumps are available on Google Drive shared by Itexamguide: https://drive.google.com/open?id=19hgyYh7LVWXZhUL16y4dGGLroFO7eswO
Itexamguide is a leading provider of top-quality Databricks Certified Machine Learning Professional (Databricks-Machine-Learning-Professional) preparation material for the Databricks-Machine-Learning-Professional test. Our Databricks Certified Machine Learning Professional (Databricks-Machine-Learning-Professional) exam questions are designed to help customers get success on the first try. These latest Databricks Databricks-Machine-Learning-Professional Questions are the result of extensive research by a team of professionals with years of experience.
Databricks Databricks-Machine-Learning-Professional Exam Overview:
| Certification Vendor: | Databricks |
|---|
| Exam Name: | Databricks Certified Machine Learning Professional |
|---|
| Exam Number: | Databricks-Machine-Learning-Professional |
|---|
| Passing Score: | Not publicly disclosed |
|---|
| Exam Price: | $200 USD |
|---|
| Certificate Validity Period: | 2 years |
|---|
| Exam Duration: | 120 minutes |
|---|
| Related Certifications: | Databricks Certified Machine Learning Associate |
|---|
| Available Languages: | English |
|---|
| Real Exam Qty: | Approximately 45–60 |
|---|
| Exam Format: | Multiple choice, Scenario-based questions, Multiple select |
|---|
| Recommended Training: | Databricks Academy Machine Learning Training |
|---|
| Exam Registration: | Databricks Certification Portal |
|---|
| Sample Questions: | Databricks Databricks-Machine-Learning-Professional Sample Questions |
|---|
| Exam Way: | Online proctored exam (typically delivered via Databricks certification partners such as Certiverse or Pearson VUE depending on region and current program structure) |
|---|
| Pre Condition: | Recommended experience with Databricks platform and machine learning workflows; Databricks Certified Machine Learning Associate certification is often recommended but not strictly required. |
|---|
| Official Syllabus URL: | https://www.databricks.com/learn/certification |
|---|
>> Databricks-Machine-Learning-Professional Reliable Guide Files <<
Why Choose Itexamguide Databricks Databricks-Machine-Learning-Professional Exam Questions?
The "Itexamguide" is one of the top-rated and reliable platforms that offer real, valid, and updated Databricks Certified Machine Learning Professional (Databricks-Machine-Learning-Professional) exam questions in three different formats. The names of these formats are Itexamguide Databricks-Machine-Learning-Professional PDF dumps file, desktop practice test software, and web-based practice test software. All these three Itexamguide Databricks-Machine-Learning-Professional Exam Questions formats are easy to use and perfectly work with desktop computers, laptops, tabs, or even on your smartphone devices.
| Topic | Details |
|---|
| Topic 1 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| Topic 2 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
| Topic 3 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
| Topic 4 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
| Topic 5 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| Topic 6 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| Topic 7 | - Test whether the updated model performs better on the more recent data
- Identify when retraining and deploying an updated model is a probable solution to drift
|
Databricks Certified Machine Learning Professional Sample Questions (Q23-Q28):
NEW QUESTION # 23
A Machine Learning Engineer is working with a Spark DataFrame containing 100 million rows of retail transactions across thousands of stores. Each store requires its own demand forecasting model using the same scikit-learn pipeline. They want to train and apply these models in parallel for each store without collecting the data to the driver. Which approach will do this?
- A. Use rdd.mapPartitions() to iterate through each store and apply the model logic in Python.
- B. Use groupBy("store_id").applyInPandas() to train and apply the model per group using a Pandas UDF.
- C. Use pyspark.pandas to call .groupby("store_id").apply() and train the model on each group.
- D. Convert the DataFrame to a Pandas DataFrame using .toPandas() and loop through each store locally.
Answer: B
Explanation:
groupBy().applyInPandas() enables grouped Pandas UDFs that receive each store's data as a Pandas DataFrame on the executors. This allows training and applying a separate scikit-learn model per store in parallel without collecting data to the driver, making it the correct and scalable approach for large Spark DataFrames.
NEW QUESTION # 24
A Data Scientist is building a propensity model for an e-commerce start-up. The company maintains 7GB of historical data and receives about 5MB of new transaction data daily. The goal is to generate daily purchase predictions for all users by 7:00 AM each morning. As the start-up is in its early stages, the data scientist must prioritize a highly cost-efficient approach. Which approach should the Data Scientist take?
- A. Use a multi-node compute and leverage distributed frameworks like SparkML to train the model.
The model can then be scheduled as a nightly batch job that runs on a multi-node compute. - B. Use a single-node compute to build a model with libraries like scikit-learn. The model can then be integrated into an always-on streaming pipeline, to ensure immediate processing of incoming data in order to meet the SLA.
- C. Use a single-node compute to build a model with libraries like scikit-learn. The model can then be deployed as an always-on REST API so that users can query the API to get the predictions whenever they want.
- D. Use a single-node memory compute to build a model with libraries like scikit-learn. The model can then be scheduled as a nightly batch job that runs on a single-node compute.
Answer: D
Explanation:
With only 7GB of historical data and a small daily increment (about 5MB), a single-node memory- optimized cluster can comfortably train and score using scikit-learn without the overhead and cost of distributed compute. Scheduling a nightly batch job is the most cost-efficient way to meet a fixed daily SLA (7:00 AM) because the compute can be started only for the job run and then terminated, avoiding the expense of always-on serving or streaming infrastructure.
NEW QUESTION # 25
Which of the following is a simple statistic to monitor for categorical feature drift?
- A. Percentage of missing values
- B. Mode, number of unique values, and percentage of missing values
- C. None of these
- D. Number of unique values
- E. Mode
Answer: B
NEW QUESTION # 26
A machine learning engineer has developed a model and registered it using the FeatureStoreClient fs. The model has model URI model_uri. The engineer now needs to perform batch inference on customer-level Spark DataFrame spark_df, but it is missing a few of the static features that were used when training the model. The customer_id column is the primary key of spark_df and the training set used when training and logging the model.
Which of the following code blocks can be used to compute predictions for spark_df when the missing feature values can be found in the Feature Store by searching for features by customer_id?
- A. df = fs.get_missing_features(spark_df, model_uri)
fs.score_batch(model_uri, df) - B. df = fs.get_missing_features(spark_df, model_uri)
fs.score_model(model_uri, df) - C. df = fs.get_missing_features(spark_df)
fs.score_batch(model_uri, df) - D. fs.score_model(model_uri, spark_df)
- E. fs.score_batch(model_uri, spark_df)
Answer: E
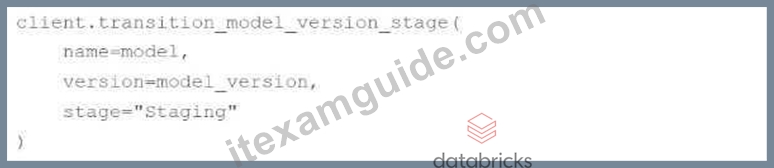
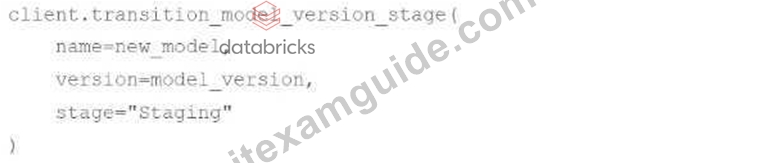
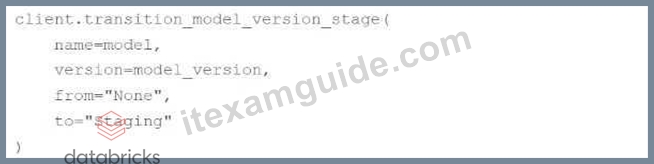
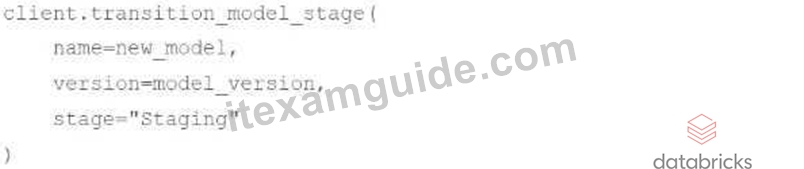
NEW QUESTION # 27
A machine learning engineer has created a webhook with the following code block:
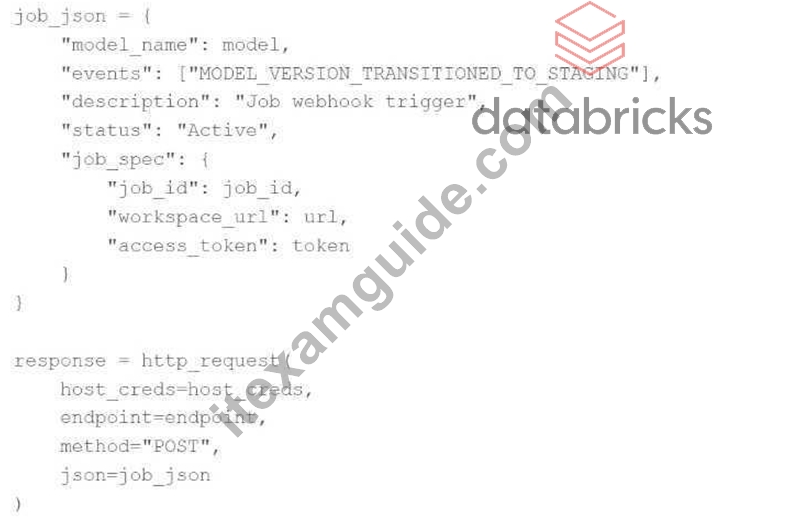
Which of the following code blocks will trigger this webhook to run the associate job?
Answer: D
NEW QUESTION # 28
......
Dumps Databricks-Machine-Learning-Professional Reviews: https://www.itexamguide.com/Databricks-Machine-Learning-Professional_braindumps.html
- Databricks-Machine-Learning-Professional Valid Dumps Free 🍲 Exam Databricks-Machine-Learning-Professional Course 🐜 Databricks-Machine-Learning-Professional Valid Test Guide 🕊 Open website ➤ www.practicevce.com ⮘ and search for 《 Databricks-Machine-Learning-Professional 》 for free download 🐄Databricks-Machine-Learning-Professional Valid Dumps Free
- Pass Guaranteed Databricks-Machine-Learning-Professional - The Best Databricks Certified Machine Learning Professional Reliable Guide Files 🟧 Easily obtain free download of ▶ Databricks-Machine-Learning-Professional ◀ by searching on ☀ www.pdfvce.com ️☀️ 🤓Databricks-Machine-Learning-Professional New Dumps Book
- Databricks-Machine-Learning-Professional Latest Test Cost 🦥 Databricks-Machine-Learning-Professional Reliable Test Preparation 🌳 Databricks-Machine-Learning-Professional Valid Dumps Free 🏗 Copy URL ✔ www.examcollectionpass.com ️✔️ open and search for ▛ Databricks-Machine-Learning-Professional ▟ to download for free 💗Databricks-Machine-Learning-Professional New Dumps Book
- Databricks-Machine-Learning-Professional New Dumps Book 🛩 New Databricks-Machine-Learning-Professional Test Prep 👿 Databricks-Machine-Learning-Professional Well Prep 🥾 Go to website “ www.pdfvce.com ” open and search for 「 Databricks-Machine-Learning-Professional 」 to download for free 🤖Databricks-Machine-Learning-Professional New Dumps Book
- Databricks-Machine-Learning-Professional Well Prep ⏫ Databricks-Machine-Learning-Professional Test Fee 💮 Databricks-Machine-Learning-Professional Valid Test Guide 🔕 Enter ▛ www.exam4labs.com ▟ and search for [ Databricks-Machine-Learning-Professional ] to download for free 🚧Databricks-Machine-Learning-Professional Exam Simulations
- Boost Your Exam Prep With Pdfvce Databricks Databricks-Machine-Learning-Professional Questions 🔀 Search on 《 www.pdfvce.com 》 for ▷ Databricks-Machine-Learning-Professional ◁ to obtain exam materials for free download 📤Exam Databricks-Machine-Learning-Professional Course
- Minimum Databricks-Machine-Learning-Professional Pass Score 🥗 Databricks-Machine-Learning-Professional Reliable Exam Vce ✉ Databricks-Machine-Learning-Professional Exam Lab Questions ✊ 【 www.examcollectionpass.com 】 is best website to obtain [ Databricks-Machine-Learning-Professional ] for free download 🦡Databricks-Machine-Learning-Professional Reliable Exam Vce
- New Launch Databricks Databricks-Machine-Learning-Professional Exam Questions Are Out: Download And Prepare 🥓 Copy URL ▷ www.pdfvce.com ◁ open and search for ➽ Databricks-Machine-Learning-Professional 🢪 to download for free 🚊Databricks-Machine-Learning-Professional Test Fee
- Databricks-Machine-Learning-Professional Reliable Exam Vce 🧤 Databricks-Machine-Learning-Professional Valid Test Guide 📣 Minimum Databricks-Machine-Learning-Professional Pass Score 🦚 Download [ Databricks-Machine-Learning-Professional ] for free by simply searching on ➥ www.pdfdumps.com 🡄 🪐Databricks-Machine-Learning-Professional Latest Test Cost
- Minimum Databricks-Machine-Learning-Professional Pass Score 🦈 Databricks-Machine-Learning-Professional Exam Lab Questions 🎼 Databricks-Machine-Learning-Professional Examcollection 🔶 Open ▶ www.pdfvce.com ◀ enter [ Databricks-Machine-Learning-Professional ] and obtain a free download 🕒Databricks-Machine-Learning-Professional Well Prep
- Databricks-Machine-Learning-Professional Real Question 🕓 Databricks-Machine-Learning-Professional Training Material ⚔ Reliable Databricks-Machine-Learning-Professional Test Pass4sure 🔇 Search for ( Databricks-Machine-Learning-Professional ) and download exam materials for free through ⏩ www.troytecdumps.com ⏪ 🏡Databricks-Machine-Learning-Professional Examcollection
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BONUS!!! Download part of Itexamguide Databricks-Machine-Learning-Professional dumps for free: https://drive.google.com/open?id=19hgyYh7LVWXZhUL16y4dGGLroFO7eswO