What's more, part of that Actual4Exams Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1POkxZJJG9JfEne31JpdFvEjghnC-563X
Great concentrative progress has been made by our company, who aims at further cooperation with our candidates in the way of using our Data-Engineer-Associate exam engine as their study tool. with more people joining in the Data-Engineer-Associate exam army, we has become the top-raking training materials provider in the international market. In addition, we always adhere to the principle of “mutual development and benefit”, and we believe our Data-Engineer-Associate practice materials can give you a timely and effective helping hand whenever you need in the process of learning.
| Section | Weight | Objectives |
|---|---|---|
| Data Security and Governance | 18% | - Implement access control and authentication
- Protect sensitive data - Enforce compliance and data governance
|
| Data Store Management | 26% | - Manage data lifecycle and storage tiers - Design and implement data storage solutions
|
| Data Operations and Support | 22% | - Backup, restore, and disaster recovery - Ensure reliability and scalability - Monitor and troubleshoot data pipelines
|
| Data Ingestion and Transformation | 34% | - Implement data quality and validation - Ingest data from various sources
|
>> Data-Engineer-Associate Test Dumps Free <<
Generally speaking, preparing for the Data-Engineer-Associate exam is a very hard and even some suffering process. Because time is limited, sometimes we have to spare time to do other things to review the exam content, which makes the preparation process full of pressure and anxiety. But from the point of view of customers, our Data-Engineer-Associate Actual Exam will not let you suffer from this. We have a high pass rate of our Data-Engineer-Associate study materials as 98% to 100%. Our Data-Engineer-Associate learning quiz will be your best choice.
NEW QUESTION # 192
A data engineer needs to create an Amazon Athena table based on a subset of data from an existing Athena table named cities_world. The cities_world table contains cities that are located around the world. The data engineer must create a new table named cities_us to contain only the cities from cities_world that are located in the US.
Which SQL statement should the data engineer use to meet this requirement?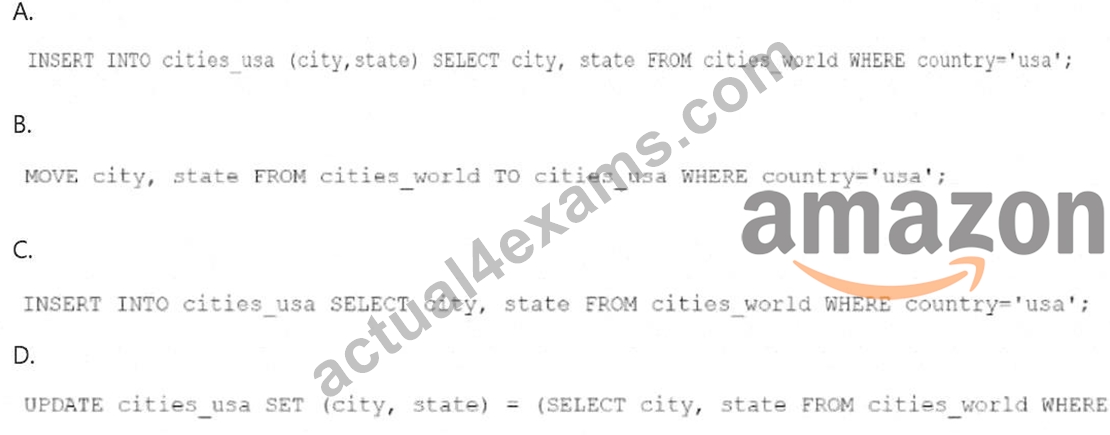
Answer: D
Explanation:
To create a new table named cities_usa in Amazon Athena based on a subset of data from the existing cities_world table, you should use an INSERT INTO statement combined with a SELECT statement to filter only the records where the country is 'usa'. The correct SQL syntax would be:
Option A: INSERT INTO cities_usa (city, state) SELECT city, state FROM cities_world WHERE country='usa';This statement inserts only the cities and states where the country column has a value of 'usa' from the cities_world table into the cities_usa table. This is a correct approach to create a new table with data filtered from an existing table in Athena.
Options B, C, and D are incorrect due to syntax errors or incorrect SQL usage (e.g., the MOVE command or the use of UPDATE in a non-relevant context).
References:
Amazon Athena SQL Reference
Creating Tables in Athena
NEW QUESTION # 193
A data engineer needs to analyze time-sensitive sales data. The company stores the data in an Amazon S3 bucket. The data engineer uses AWS Glue Data Catalog to access the data.
When performing the analysis, the data engineer notices that some records are missing or out of date.
What is the likely cause of these issues?
Answer: A
Explanation:
AWS Glue Data Catalog stores metadata about data stored in Amazon S3, including table schemas and partitions. If new partitions are added to S3 and the Glue Data Catalog is not updated-either through crawlers or explicit API calls-query engines such as Amazon Athena and AWS Glue will not be aware of the new data.
This leads to analysis results that appear incomplete or outdated, even though the underlying data exists in S3.
This is a common issue in time-sensitive analytics workloads where data arrives frequently and partitions change often.
IAM permission issues would typically cause access failures rather than missing records. S3 versioning affects object history, not query visibility. Overlapping Glue job schedules could cause processing delays but would not directly cause missing data during query time.
Therefore, the most likely cause is that the Glue Data Catalog metadata is not synchronized with the latest S3 partitions.
NEW QUESTION # 194
A company uses Amazon S3 as a data lake. The company sets up a data warehouse by using a multi-node Amazon Redshift cluster. The company organizes the data files in the data lake based on the data source of each data file.
The company loads all the data files into one table in the Redshift cluster by using a separate COPY command for each data file location. This approach takes a long time to load all the data files into the table. The company must increase the speed of the data ingestion. The company does not want to increase the cost of the process.
Which solution will meet these requirements?
Answer: C
Explanation:
The company is facing performance issues loading data into Amazon Redshift because it is issuing separate COPY commands for each data file location. The most efficient way to increase the speed of data ingestion into Redshift without increasing the cost is to use a manifest file.
* Option D: Create a manifest file that contains the data file locations. Use a COPY command to load the data into Amazon Redshift.A manifest file provides a list of all the data files, allowing the COPY command to load all files in parallel from different locations in Amazon S3. This significantly improves the loading speed without adding costs, as it optimizes the data loading process in a single COPY operation.
Other options (A, B, C) involve additional steps that would either increase the cost (provisioning clusters, using Glue, etc.) or do not address the core issue of needing a unified and efficient COPY process.
References:
* Amazon Redshift COPY Command
* Redshift Manifest File Documentation
NEW QUESTION # 195
A data engineer manages a provisioned Amazon Redshift cluster that stores petabytes of data. The cluster receives continuous data ingestion from multiple sources. As data volume grows, the query performance has degraded. The current table design uses the AUTO distribution style and default sort keys. The data engineer needs to optimize the query performance for recent transactions.
Which solution will meet these requirements?
Answer: C
Explanation:
The correct answer is A because the workload has grown to petabyte scale, but the performance requirement is focused on recent transactions. The best architecture is to keep hot, frequently queried data inside Amazon Redshift and move historical/cold data to Amazon S3. Amazon Redshift Spectrum lets Redshift efficiently query structured and semi-structured files in S3 without loading that data into Redshift tables, and most of the data remains in S3 while Spectrum performs parallel processing. This reduces pressure on the provisioned cluster while preserving query access to historical data. Decreasing nodes would worsen performance. DISTSTYLE ALL for historical tables can increase storage and maintenance overhead. Redshift is already columnar, so switching to row-based storage is not valid.
NEW QUESTION # 196
A company stores customer data that contains personally identifiable information (PII) in an Amazon Redshift cluster. The company's marketing, claims, and analytics teams need to be able to access the customer data.
The marketing team should have access to obfuscated claim information but should have full access to customer contact information.
The claims team should have access to customer information for each claim that the team processes.
The analytics team should have access only to obfuscated PII data.
Which solution will enforce these data access requirements with the LEAST administrative overhead?
Answer: B
Explanation:
Step 1: Understand the Data Access Requirements
The question presents distinct access needs for three teams:
Marketing team: Needs full access to customer contact info but only obfuscated claim information.
Claims team: Needs access to customer information relevant to the claims they process.
Analytics team: Needs only obfuscated PII data.
These teams require different levels of access, and the solution needs to enforce data security while keeping administrative overhead low.
Step 2: Why Option B is Correct
Option B (Creating Views) is a common best practice in Amazon Redshift to restrict access to specific data without duplicating data or managing multiple clusters. By creating views:
You can define customized views of the data with obfuscated fields for the analytics team and marketing team while still providing full access where necessary.
Views provide a logical separation of data and allow Redshift administrators to grant access permissions based on roles or groups, ensuring that each team sees only what they are allowed to.
Obfuscation or masking of PII can be easily applied to the views by transforming or hiding sensitive data fields.
This approach avoids the complexity of managing multiple Redshift clusters or S3-based data lakes, which introduces higher operational and administrative overhead.
Step 3: Why Other Options Are Not Ideal
Option A (Separate Redshift Clusters) introduces unnecessary administrative overhead by managing multiple clusters. Maintaining several clusters for each team is costly, redundant, and inefficient.
Option C (Separate Redshift Roles) involves creating multiple roles and managing complex masking policies, which adds to administrative burden and complexity. While Redshift does support column-level access control, it's still more overhead than managing simple views.
Option D (Move to S3 and Lake Formation) is a more complex and heavy-handed solution, especially when the data is already stored in Redshift. Migrating the data to S3 and setting up a data lake with Lake Formation introduces significant operational complexity that isn't needed for this specific requirement.
Conclusion:
Creating views in Amazon Redshift allows for flexible, fine-grained access control with minimal overhead, making it the optimal solution to meet the data access requirements of the marketing, claims, and analytics teams.
NEW QUESTION # 197
......
In the PDF version, the AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) exam questions are printable and portable. You can take these Amazon Data-Engineer-Associate pdf dumps anywhere and even take a printout of AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) exam questions. The PDF version is mainly composed of real Amazon Data-Engineer-Associate Exam Dumps. Actual4Exams updates regularly to improve its AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) pdf questions and also makes changes when required.
Exam Data-Engineer-Associate Quiz: https://www.actual4exams.com/Data-Engineer-Associate-valid-dump.html
P.S. Free 2026 Amazon Data-Engineer-Associate dumps are available on Google Drive shared by Actual4Exams: https://drive.google.com/open?id=1POkxZJJG9JfEne31JpdFvEjghnC-563X