Prepare with updated Databricks Databricks-Machine-Learning-Professional dumps - Get up to one year of free updates

BONUS!!! Download part of iPassleader Databricks-Machine-Learning-Professional dumps for free: https://drive.google.com/open?id=1a6zT_3n-ftEgkiVScAOEbjYuwUXSwkf0
The study material to get Databricks Certified Machine Learning Professional should be according to individual's learning style and experience. Real Databricks Databricks-Machine-Learning-Professional Exam Questions certification makes you more dedicated and professional as it will provide you complete information required to work within a professional working environment. These questions will familiarize you with the Databricks-Machine-Learning-Professional Exam Format and the content that will be covered in the actual test. You will not get a passing score if you rely on outdated practice questions.
Databricks Databricks-Machine-Learning-Professional Exam Overview:
| Certification Vendor: | Databricks |
|---|
| Exam Name: | Databricks Certified Machine Learning Professional |
|---|
| Exam Number: | Databricks-Machine-Learning-Professional |
|---|
| Real Exam Qty: | 60 |
|---|
| Certificate Validity Period: | 2 years |
|---|
| Available Languages: | English |
|---|
| Passing Score: | 70% |
|---|
| Exam Price: | USD 200 |
|---|
| Exam Format: | Multiple choice |
|---|
| Exam Duration: | 120 minutes |
|---|
| Related Certifications: | Databricks Certified Machine Learning Associate |
|---|
| Sample Questions: | Databricks Databricks-Machine-Learning-Professional Sample Questions |
|---|
| Exam Way: | Online (proctored) or Test Center |
|---|
| Pre Condition: | No formal prerequisites, but 1+ years of hands-on experience performing the machine learning tasks outlined in the exam guide is highly recommended. Recommended courses: Machine Learning at Scale and Advanced Machine Learning Operations (instructor-led or self-paced via Databricks Academy). |
|---|
| Official Syllabus URL: | https://www.databricks.com/learn/certification/machine-learning-professional |
|---|
>> Test Databricks-Machine-Learning-Professional Sample Online <<
Databricks-Machine-Learning-Professional Test Online & Databricks-Machine-Learning-Professional Test Price
Our iPassleader Databricks-Machine-Learning-Professional exam certification training material is the collection of experience and innovation results of highly certified IT professionals in IT industry. We guarantee that after you buy iPassleader Databricks-Machine-Learning-Professional certification exam training materials, we will provide free renewal service for one year. If Databricks-Machine-Learning-Professional Exam Certification training materials have any quality problem or you fail Databricks-Machine-Learning-Professional exam certification, we will give a full refund unconditionally.
| Topic | Details |
|---|
| Topic 1 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| Topic 2 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| Topic 3 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| Topic 4 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| Topic 5 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
| Topic 6 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
| Topic 7 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
| Topic 8 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
| Topic 9 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| Topic 10 | - Test whether the updated model performs better on the more recent data
- Identify when retraining and deploying an updated model is a probable solution to drift
|
Databricks Certified Machine Learning Professional Sample Questions (Q145-Q150):
NEW QUESTION # 145
A machine learning engineer is converting a Hyperopt-based hyperparameter tuning process from manual MLflow logging to MLflow Autologging. They notice that not all details and objects are automatically logged, and they will need to manually log some things. Which of the following will need to be manually logged when performing nested runs with Hyperopt and MLflow Autologging?
- A. Best trial evaluation metric
- B. Trial status
- C. Trial models
- D. Evaluation metrics
- E. Hyperparameter values
Answer: A
Explanation:
When using MLflow Autologging with Hyperopt and nested runs, the best trial evaluation metric is not automatically logged and must be logged manually. Autologging captures trial-level details like hyperparameters and evaluation metrics, but summarizing and logging the overall best trial's result is a manual responsibility of the engineer.
NEW QUESTION # 146
Which statement describes streaming with Spark as a model deployment strategy?
- A. The inference of incrementally processed records as soon as a Spark job is run
- B. The inference of batch processed records as soon as a Spark job is run
- C. The inference of incrementally processed records as soon as trigger is hit
- D. The inference of all types of records in real-time
- E. The inference of batch processed records as soon as a trigger is hit
Answer: A
NEW QUESTION # 147
A Machine Learning Engineer needs to build a time series model. In Databricks, they have created isolated environments in different workspaces for development, staging, and production.
To manage this model, they are planning on using a "deploy code" strategy. They are concerned that the model trained in development will not remain consistent across environments, due to differences in the dependencies installed. What can they do to ensure that the model is trained with the same packages?
- A. Use the same Databricks Runtime (DBR) version across environments and define dependencies in a lock file that is installed as part of the job.
- B. Use MLflow to track the model parameters and metrics in development, then export the same training conditions in staging and production.
- C. Use Databricks Repos to store the model code and install the required libraries in the notebook.
- D. Use custom init scripts that install the necessary packages as part of the job.
Answer: A
Explanation:
Using the same Databricks Runtime across environments ensures a consistent base environment, and installing dependencies from a lock file guarantees identical package versions during training. This combination follows best practices for deploy-code workflows by making the training environment reproducible and preventing dependency drift between development, staging, and production.
NEW QUESTION # 148
A Machine Learning Engineer has a large dataset with a customer_region column and wants to train separate models for each region, then generate predictions. They need to parallelize this group-specific model training process using Databricks and the Pandas Function API. Which approach will implement this solution?
- A. Use collect() to gather all data and process regions using standard pandas groupby.
- B. Use mapInPandas() to apply the training function across all partitions without grouping.
- C. Use groupBy("customer_region") and apply a training function with applyInPandas().
- D. Use foreachBatch() to sequentially process each region's data.
Answer: C
Explanation:
The Pandas Function API supports parallel, group-specific processing by using groupBy on the grouping column and applyInPandas to execute a custom training function independently for each group. This enables separate models to be trained per region in parallel across the cluster, with each function invocation receiving only the data for its group.
NEW QUESTION # 149
A machine learning engineer wants to view all of the active MLflow Model Registry Webhooks for a specific model.
They are using the following code block:
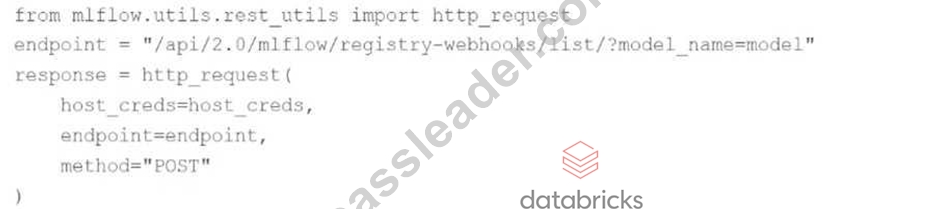
Which of the following changes does the machine learning engineer need to make to this code block so it will successfully accomplish the task?
- A. Replace list with view in the endpoint URL
- B. Replace list with webhooks in the endpoint URL
- C. Replace POST with PUT in the call to http request
- D. Replace POST with GET in the call to http request
- E. There are no necessary changes
Answer: D
NEW QUESTION # 150
......
Databricks-Machine-Learning-Professional Test Online: https://www.ipassleader.com/Databricks/Databricks-Machine-Learning-Professional-practice-exam-dumps.html
- Free PDF Quiz 2026 Databricks Useful Test Databricks-Machine-Learning-Professional Sample Online 🏚 Search for ⮆ Databricks-Machine-Learning-Professional ⮄ and download it for free immediately on ➥ www.validtorrent.com 🡄 🚗Dumps Databricks-Machine-Learning-Professional Download
- Reliable Databricks-Machine-Learning-Professional Exam Vce 🍳 Reliable Databricks-Machine-Learning-Professional Exam Voucher 🦓 Reliable Databricks-Machine-Learning-Professional Exam Vce 🙃 Download ✔ Databricks-Machine-Learning-Professional ️✔️ for free by simply searching on ➥ www.pdfvce.com 🡄 🎣Databricks-Machine-Learning-Professional Test Papers
- Databricks-Machine-Learning-Professional Latest Demo 🔄 Reliable Databricks-Machine-Learning-Professional Exam Voucher 🍑 Reliable Databricks-Machine-Learning-Professional Exam Vce 🔤 Immediately open ▶ www.dumpsmaterials.com ◀ and search for { Databricks-Machine-Learning-Professional } to obtain a free download 👍Exam Databricks-Machine-Learning-Professional Pass Guide
- Reliable Databricks-Machine-Learning-Professional Test Online 😝 Actual Databricks-Machine-Learning-Professional Test Pdf 🎨 Actual Databricks-Machine-Learning-Professional Test Pdf 🥦 Download ⮆ Databricks-Machine-Learning-Professional ⮄ for free by simply entering 【 www.pdfvce.com 】 website 🕣Study Databricks-Machine-Learning-Professional Material
- Databricks-Machine-Learning-Professional Quiz Torrent: Databricks Certified Machine Learning Professional - Databricks-Machine-Learning-Professional Exam Guide - Databricks-Machine-Learning-Professional Test Braindumps 🪑 Download ➥ Databricks-Machine-Learning-Professional 🡄 for free by simply searching on ➤ www.dumpsquestion.com ⮘ 🍖Databricks-Machine-Learning-Professional Reliable Exam Bootcamp
- Databricks-Machine-Learning-Professional Hot Spot Questions 🚁 Valid Databricks-Machine-Learning-Professional Exam Test 🛑 Databricks-Machine-Learning-Professional Latest Demo 🤕 Download ( Databricks-Machine-Learning-Professional ) for free by simply entering ➡ www.pdfvce.com ️⬅️ website 🔕Reliable Databricks-Machine-Learning-Professional Exam Voucher
- Braindumps Databricks-Machine-Learning-Professional Pdf ❤️ Sure Databricks-Machine-Learning-Professional Pass 🌐 Databricks-Machine-Learning-Professional Latest Demo 🕒 Enter ⇛ www.testkingpass.com ⇚ and search for { Databricks-Machine-Learning-Professional } to download for free 🔳Databricks-Machine-Learning-Professional Latest Demo
- Unparalleled Databricks Test Sample Online – Marvelous Databricks-Machine-Learning-Professional Test Online 😀 Search for ✔ Databricks-Machine-Learning-Professional ️✔️ and download exam materials for free through ➤ www.pdfvce.com ⮘ 👿Sure Databricks-Machine-Learning-Professional Pass
- Get Free Updates Up to 365 days On Developing Databricks Certified Machine Learning Professional Databricks-Machine-Learning-Professional Braindumps 🛶 Open ➽ www.vce4dumps.com 🢪 enter ➽ Databricks-Machine-Learning-Professional 🢪 and obtain a free download 🟦Study Databricks-Machine-Learning-Professional Material
- Get Free Updates Up to 365 days On Developing Databricks Certified Machine Learning Professional Databricks-Machine-Learning-Professional Braindumps 🟥 Search for ▛ Databricks-Machine-Learning-Professional ▟ and download it for free immediately on ➡ www.pdfvce.com ️⬅️ 🍷Databricks-Machine-Learning-Professional Braindump Pdf
- Real Databricks Databricks-Machine-Learning-Professional Questions - Your Key to Success 🚗 Search for ▛ Databricks-Machine-Learning-Professional ▟ and obtain a free download on ➡ www.easy4engine.com ️⬅️ 🎉Dumps Databricks-Machine-Learning-Professional Download
- swipy.ru, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, audiomack.com, letterboxd.com, Disposable vapes
What's more, part of that iPassleader Databricks-Machine-Learning-Professional dumps now are free: https://drive.google.com/open?id=1a6zT_3n-ftEgkiVScAOEbjYuwUXSwkf0