DOWNLOAD the newest VCEEngine SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1mdO_G1YhPPtQJjGi117BIqd3vbgmHnNN
If you want to pass your exam and get your certification, we can make sure that our SPS-C01 guide questions will be your ideal choice. Our company will provide you with professional team, high quality service and reasonable price. In order to help customers solve problems, our company always insist on putting them first and providing valued service. We are living in the highly competitive world now. We have no choice but improve our soft power, such as get SPS-C01 Certification. It is of great significance to have SPS-C01 guide torrents to pass exams as well as highlight your resume, thus helping you achieve success in your workplace.
| Section | Objectives |
|---|---|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Testing, Debugging, and Deployment | - Production readiness
|
| Data Engineering with Snowpark | - Pipeline development
|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
>> Valid SPS-C01 Test Guide <<
SPS-C01 Soft test engine can stimulate the real exam environment, so that you can know the procedures of the exam, and your nerves can be relieved. This version can also build up your confidence for the exam. In addition, SPS-C01 exam dumps contain most of knowledge points for the exam, and you can master them as well as improve your ability in the process learning. We also pass guarantee and money back guarantee if you fail to pass the exam, we will return your money if you fail to pass the exam. Free update for SPS-C01 Training Materials is also available, and our system will send you the latest version to your email automatically.
NEW QUESTION # 221
You are tasked with optimizing a Snowpark Python stored procedure that performs complex data transformations on a DataFrame. The procedure frequently encounters out-of-memory errors when processing large datasets. Which of the following strategies could you implement to mitigate these memory issues within the stored procedure's code ? Choose all that apply.
Answer: A,B,E
Explanation:
Options B, C, and D directly address memory management within the stored procedure. Option B: 'repartition()' and allow you to control how the data is distributed across partitions. By adjusting the number of partitions, you can influence the amount of memory required to process each partition. Fewer, larger partitions can sometimes be problematic, whereas many smaller partitions might improve memory management but increase overhead. The best strategy depends on the specifics of the data and the transformations. Option C: Performing filtering and aggregation early reduces the volume of data that needs to be processed in subsequent steps, directly reducing memory consumption. This is a common optimization technique in data processing pipelines. Option D: Using smaller data types can significantly reduce memory footprint, especially when dealing with large datasets. Using 'Int16' when the range of values allows for it, instead of defaulting to Int64', can halve the memory usage for that column. Option A (increasing the warehouse size) provides more resources but doesn't address the underlying code inefficiencies that lead to memory errors. It's a valid approach, but should be considered after code-level optimizations. Option E(using 'sample()') is primarily for testing and debugging and does not solve the memory issue when processing the full dataset.
NEW QUESTION # 222
You have a DataFrame 'df containing user profile data'. A column named "profile" stores JSON objects with potentially missing fields. These objects might include 'name', 'age', 'location', and 'preferences'. You need to extract the user's name and age. If 'age' is missing, you want to default to 0. Furthermore, you want to filter out any rows where the 'location' field is an empty string. Which combination of Snowpark code snippets will achieve this? (Select all that apply)





Answer: A,B,D
Explanation:
Options A, B and C correctly address the requirements. They extract the name and handle the missing 'age' by defaulting to 0, and filter out rows with an empty string for 'location'. - Option A uses 'nvr to replace NULL 'age' values and ' to filter out empty locations. - Option B uses 'iff to achieve the same age default and sf.lit(")' for filtering. - Option C uses 'coalesce' to default 'age' and 'sf.lengtm to check if the location string has any characters. Option D will filter out all the rows where location is Null and option E uses zeroifnull function which is deprecated, and replaces age which is 0 if column is NULL. and option D wont filer empty string in location
NEW QUESTION # 223
Consider the following Snowpark code snippet designed to create a temporary table: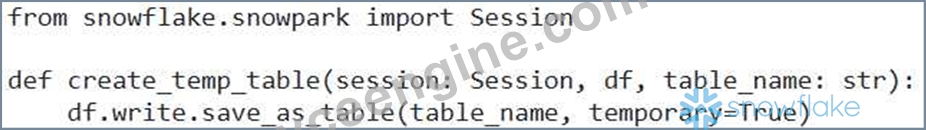
A developer encounters an error when calling this function. The error message indicates that the table already exists. How should the developer modify the code to handle this scenario gracefully, preventing the error and ensuring the temporary table is either created or overwritten?
Answer: B,E
Explanation:
The option will replace the existing table if it exists. Alternatively, explicitly dropping the table using session.sql(fDROP TABLE IF EXISTS {table_name}')' ensures that a new table is created, even if one with the same name already exists. mode='ignore" would just skip the operation and no table may exist after execution. 'mode='append'' may fail as well as temporary tables typically do not allow appending. createOrReplaceTempView creates a temporary view , not a temporary table.
NEW QUESTION # 224
A data engineering team is building a Snowpark application in Python to perform advanced time series analysis on sensor data stored in Snowflake. They need to leverage a specific, but older, version of the 'pandas' library (version 1.1.5) that is not available in the default Snowflake Anaconda channel. Which of the following approaches is the MOST efficient and recommended way to ensure this specific version of 'pandas' is available to their Snowpark application, while minimizing security risks and operational overhead?
Answer: C
Explanation:
Creating a new Snowflake Anaconda environment is the most efficient and secure way to manage specific package versions. It leverages Snowflake's built-in dependency management capabilities and avoids external dependencies or manual package management within the application code. Options A and D introduce potential security risks and maintenance overhead. Option B is inefficient for dependency management. Option E will not work, as it tries to install dependencies at runtime, which isn't supported in Snowpark.
NEW QUESTION # 225
You have a Snowpark DataFrame named with the following schema: '(timestamp: TmestampType, sensor_id: StringType, value: FloatType)'. You need to identify the top 3 sensors with the highest average value over the entire dataset. Which of the following Snowpark Python code snippets correctly implements this requirement?





Answer: B
Explanation:
Option A provides the correct and most concise solution. It groups the 'sensor_data' DataFrame by , calculates the average value for each sensor using , orders the results by the average value in descending order using ascending-Falsey , and then limits the results to the top 3 sensors using 'limit(3)'. Option B attempts to use window function over the entire dataset without grouping by sensor, the result would be incorrect. Option C incorrectly attempts to use window specification without partition. Option D is similar as C with missing group by partition. Option E use 'sort' instead of 'orderBy' .
NEW QUESTION # 226
......
Our company keeps pace with contemporary talent development and makes every learners fit in the needs of the society. Based on advanced technological capabilities, our SPS-C01 study materials are beneficial for the masses of customers. Our experts have plenty of experience in meeting the requirement of our customers and try to deliver satisfied SPS-C01 Exam guides to them. Our SPS-C01 exam prepare is definitely better choice to help you go through the test.
New SPS-C01 Test Question: https://www.vceengine.com/SPS-C01-vce-test-engine.html
P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by VCEEngine: https://drive.google.com/open?id=1mdO_G1YhPPtQJjGi117BIqd3vbgmHnNN