あなたは我々JPTestKingの提供するIT試験のためのソフトを使用したことがありますか?もしあったら、あなたは我々のMicrosoftのAI-103試験のソフトウェアを使用することを躊躇しないでしょう。そうでない場合、今回使用してからあなたがJPTestKingを必要な選択肢として使用できるようになります。私たちが提供するMicrosoftのAI-103試験のソフトウェアはITエリートによって数年以来MicrosoftのAI-103試験の内容から分析して開発されます、オンライン、PDF、およびソフトウェアが3つのバージョンあります。あなたの気に入る版を選ぶことができます。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement agentic solutions | 20-25% | - Manage agent operations
|
| Topic 2: Implement text analysis and information extraction solutions | 10-15% | - Analyze and extract information
|
| Topic 3: Implement generative AI solutions | 25-30% | - Develop generative AI applications
|
| Topic 4: Plan and manage Azure AI solutions | 25-30% | - Manage AI solution lifecycle
|
| Topic 5: Implement computer vision solutions | 10-15% | - Analyze visual content
|
業界のリーダーとなっているために、我々は確かに独自のリソースを拡大し続ける必要があります。我々JPTestKingは常に試験問題集とソフトウェアの内容を更新します。だから、あなたの使用しているMicrosoftのAI-103試験のソフトウェアは、最新かつ最も全面的な問題集を確認することができます。あなたのMicrosoftのAI-103試験準備のどの段階にあっても、当社のソフトウェアは、あなたの最高のヘルパープロフォーマになることができます。我々はMicrosoftのAI-103試験のデータを整理したり、分析したりするため、経験豊富なエリートチームにそれを完了させます。
質問 # 82
You have a Microsoft Foundry project that contains an agent.
The agent accepts user-uploaded screenshots and uses a multimodal chat model.
Some screenshots contain potentially malicious embedded text.
You need to prevent a prompt injection attack and ensure that third-party content is treated as lower trust.
How should you configure prompt shields for document attacks? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
正解:
解説: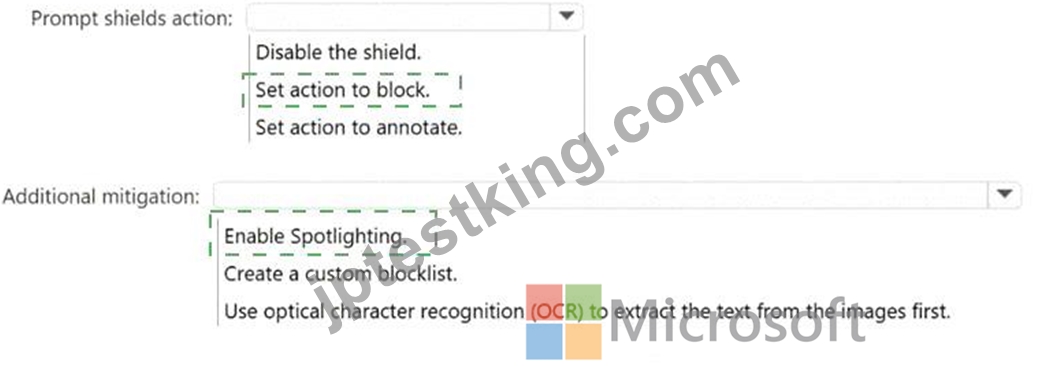
Explanation:
Prompt shields action: Set action to block.
Additional mitigation: Enable Spotlighting.
The correct configuration is to set the Prompt Shields document attack action to block and enable Spotlighting . Prompt Shields in Microsoft Foundry are designed to detect attempts to manipulate model behavior through adversarial input. Microsoft distinguishes document attacks from direct user prompt attacks:
document attacks are malicious instructions embedded in third-party content such as documents, webpages, emails, or other externally supplied material. In this scenario, the embedded text inside uploaded screenshots is third-party content and can attempt to override the agent's instructions. Setting the action to block prevents detected document-attack content from being processed normally, which is required because the goal is prevention rather than passive logging or annotation.
Spotlighting is the additional mitigation because it marks or transforms document content so the model treats it as lower trust than system and user instructions. Microsoft's Foundry guidance describes Spotlighting as a Prompt Shields subfeature that helps protect against indirect or embedded document attacks by tagging input documents with special formatting to indicate lower trust. A custom blocklist is insufficient for unknown attacks, and OCR alone only extracts the malicious text; it does not mitigate prompt injection. Reference topics: Prompt Shields, document attacks, guardrails, Spotlighting, multimodal safety, and prompt injection defense.
質問 # 83
You have a Python application named App1 that integrates with a Microsoft Foundry project named Project1.
You need to ensure that App1 meets the following requirements:
* Authenticates by using a Microsoft Entra managed identity
* Sends prompts to a deployed model by using the Azure OpenAI Responses API How should you complete the Python code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.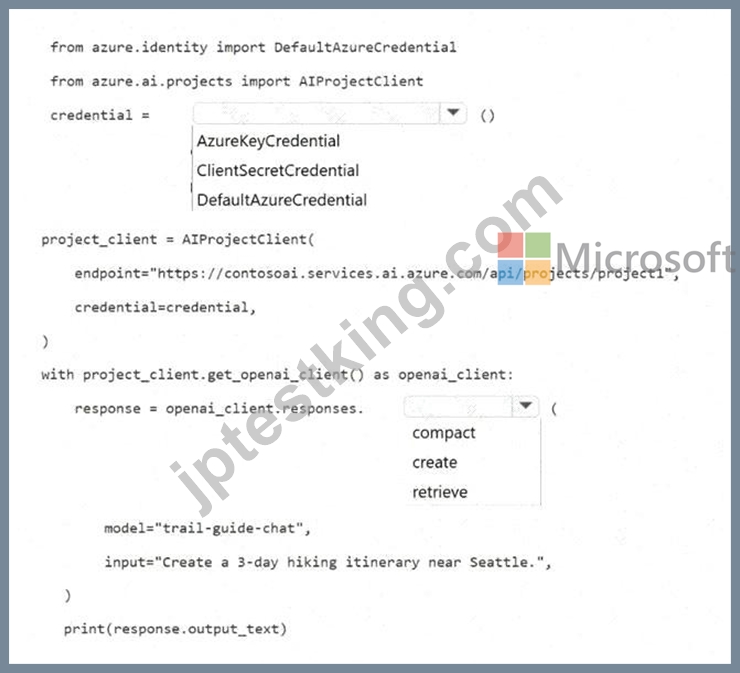
正解:
解説:
Explanation:
credential = DefaultAzureCredential
response = openai_client.responses.create
The correct authentication class is DefaultAzureCredential because the requirement is Microsoft Entra-based authentication, and this credential supports managed identity in hosted Azure environments. The Microsoft Foundry quickstart for Python shows the project client being created with AIProjectClient (endpoint=PROJECT_ENDPOINT, credential=DefaultAzureCredential()), which enables the Foundry SDK to authenticate without using API keys or embedded secrets. The same guidance shows creating an OpenAI- compatible client from the project by calling project.get_openai_client().
The correct Responses API method is create because the application must send a new prompt to the deployed model and receive generated output. Microsoft's Foundry quickstart demonstrates the exact pattern: response
= openai.responses.create(model= " gpt-5-mini " , input= " ... " ), followed by reading response.output_text.
The retrieve operation is used to fetch an existing response, not submit a new inference request, and compact is not the correct method for generating a model response. AzureKeyCredential would violate the Microsoft Entra managed identity requirement, while ClientSecretCredential uses an application secret rather than managed identity. Reference topics: Microsoft Foundry SDK, AIProjectClient, Microsoft Entra authentication, DefaultAzureCredential, and Azure OpenAI Responses API.
質問 # 84
You have a Microsoft Foundry project named Project1.
Project1 contains an application that processes PDF vendor invoices.
You need to configure Azure Document Intelligence in Foundry Tools to generate a Markdown output that preserves the sections and table structure of the PDFs. The solution must minimize development effort.
What should you do?
正解:C
解説:
Setting the output format parameter to Markdown is the correct and recommended action, but the exact property and enum name depend on whether you are interacting with the REST API directly or using the Python SDK.
To process PDF invoices and preserve their tables, headings, and visual sections in GitHub Flavored Markdown (GFM), configure your Azure Document Intelligence layout model parameters using the precise syntax detailed below.
Implementation Details
Python SDK Syntax: In the Azure Python client library, the parameter name is output_content_format, and its required value is DocumentContentFormat.MARKDOWN (rather than ContentFormat.MARKDOWN, which is used in the .NET C# SDK) Reference:
https://learn.microsoft.com/en-us/azure/ai-services/document-intelligence/concept/markdown-elements
質問 # 85
You are building an Azure AI Search indexing pipeline named Pipeline1 that ingests invoices stored in Azure Blob Storage. The invoices are stored as scanned images.
You need to enable users to search invoice data across the invoice fields.
Which built-in skill should you add to the skillset of Pipeline1?
正解:A
解説:
You should add the Azure Machine Learning OCR skill (historically known as the Microsoft.Skills.Vision.OcrSkill) to your skillset pipeline.
Text Extraction: Scanned images contain unsearchable pixels rather than text.
Data Ingestion: The OCR skill extracts the printed text and layout information from the images.
Downstream Processing: It feeds raw text into subsequent skills (like Entity Recognition) or directly into your search index fields.
Reference:
https://techcommunity.microsoft.com/blog/azurearchitectureblog/from-large-semi-structured-docs-to-actionable-data-reusable-pipelines-with-adi-a/4474054
質問 # 86
You have a Microsoft Foundry project that processes procurement documents submitted by suppliers.
You need to implement two pipelines by using Azure Content Understanding in Foundry Tools. The solution must meet the following requirements:
* Include a pipeline named Pipeline1 that supports cost-effective, high-volume processing of standalone PDF invoices.
* Include a pipeline named Pipeline2 that supports cross-document validation by using multi-step reasoning and reference data.
How should you configure each pipeline? To answer, drag the appropriate configurations to the correct pipelines. Each configuration may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.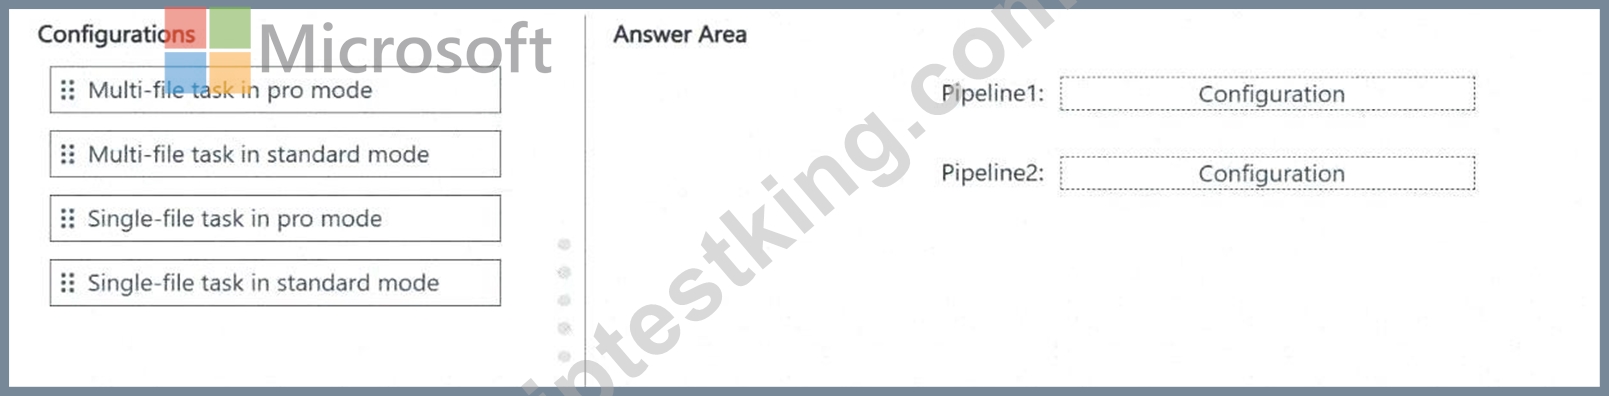
正解:
解説: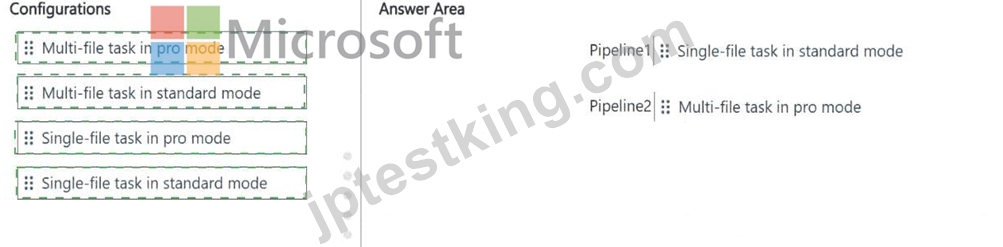
Explanation:
Pipeline1: Single-file task in standard mode
Pipeline2: Multi-file task in pro mode
Pipeline1 should use a single-file task in standard mode because the workload is high-volume processing of standalone PDF invoices. Azure Content Understanding standard mode is intended for individual files that require straightforward structured extraction, and Microsoft describes it as minimizing cost and latency for broad, data-centric processing scenarios. This makes it the best fit for cost-effective invoice extraction where each PDF can be processed independently.
Pipeline2 should use a multi-file task in pro mode because the requirement includes cross-document validation, multi-step reasoning, and reference data. Microsoft guidance states that pro mode is designed for advanced scenarios requiring multi-step reasoning and cross-file analysis, including processing multiple input files in a single request, validating or enriching data across documents, and using reference data to guide extraction and validation.
Single-file pro mode would add unnecessary capability for Pipeline1 and would not optimize for cost- effective high-volume standalone processing. Multi-file standard mode does not meet the pro-mode requirement for reference-data-based reasoning. Reference topics: Azure Content Understanding standard mode, pro mode, single-file tasks, multi-file tasks, field extraction, and procurement document validation.
質問 # 87
......
JPTestKing を選択して100%のAI-103合格率を確保することができて、もしAI-103試験に失敗したら、JPTestKingが全額で返金いたします。
AI-103英語版: https://www.jptestking.com/AI-103-exam.html