P.S. Free & New AI-103 dumps are available on Google Drive shared by Prep4King: https://drive.google.com/open?id=11EVjZ9ONF4Rh0aWti6tdfiPG5yC4g_Ag
You many face many choices of attending the certificate exams and there are a variety of certificates for you to get. You want to get the most practical and useful certificate which can reflect your ability in some area. If you choose to attend the test AI-103 certification buying our AI-103 exam guide can help you pass the AI-103 test and get the valuable certificate. Our company has invested a lot of personnel, technology and capitals on our products and is always committed to provide the top-ranking AI-103 study material to the clients and serve for the client wholeheartedly.
| Section | Weight | Objectives |
|---|---|---|
| Implement generative AI and agentic solutions | 30–35% | - Build generative AI applications
|
| Implement information extraction and knowledge mining | 10–15% | - Build knowledge bases and search solutions
|
| Implement text and speech analysis solutions | 10–15% | - Implement speech capabilities
|
| Plan and manage Azure AI solutions | 25–30% | - Design Azure AI infrastructure
|
| Implement computer vision solutions | 10–15% | - Build multimodal solutions
|
>> Reliable AI-103 Exam Testking <<
Wrong topic tend to be complex and no regularity, and the AI-103 torrent prep can help the users to form a good logical structure of the wrong question, this database to each user in the simulation in the practice of all kinds of wrong topic all induction and collation, and the Developing AI Apps and Agents on Azure study question then to the next step in-depth analysis of the wrong topic, allowing users in which exist in the knowledge module, tell users of our AI-103 Exam Question how to make up for their own knowledge loophole, summarizes the method to deal with such questions for, to prevent such mistakes from happening again.
NEW QUESTION # 118
You have a Microsoft Foundry project that contains an internal Q & A agent.
Users report the following issues when they ask the agent questions:
* An increase in the following response: "No relevant information found"
* Periodic HTTP 429 rate limit exceeded errors during peak hours
You need to identify whether each issue is caused by model unavailability, resource limits, or inference failures.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.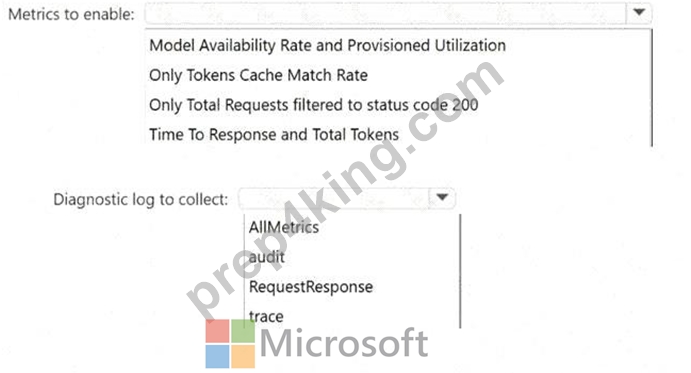
Answer:
Explanation: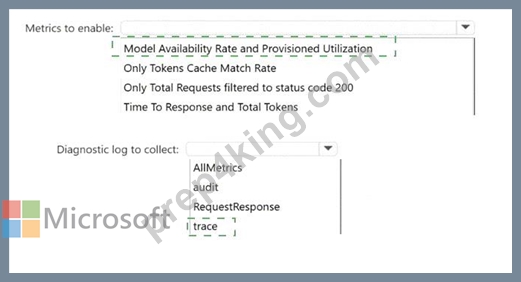
Explanation:
Metrics to enable: Model Availability Rate and Provisioned Utilization
Diagnostic log to collect: trace
The correct metrics are Model Availability Rate and Provisioned Utilization . Model Availability Rate identifies whether failures are caused by service-side model unavailability because it is calculated from total calls minus server errors. Provisioned Utilization identifies resource-limit conditions because Microsoft states that when utilization reaches or exceeds 100%, calls are throttled and HTTP 429 errors are returned. This directly maps to the reported peak-hour rate-limit errors.
The correct diagnostic log is trace . For an internal Q & A scenario, trace logging is required to analyze question-answering behavior, including unanswered questions. Microsoft's custom question answering analytics guidance states that diagnostic logging stores telemetry and chat logs and instructs enabling Trace in addition to Audit, RequestResponse, and AllMetrics. The sample Kusto queries for unanswered questions inspect the answer, question, score, and knowledge base ID, and filter unanswered results by a score of zero.
RequestResponse is useful for request status and latency, and Audit is for administrative operations, but neither is the best diagnostic category for analyzing Q & A inference behavior such as "No relevant information found." Reference topics: Foundry monitoring, model availability, provisioned utilization, diagnostic logging, custom question answering analytics, and trace logs.
NEW QUESTION # 119
A customer support agent must answer from an internal knowledge base that is updated weekly with new product documentation, and its answers must always reflect the latest content. Which approach should you implement?
Answer: D
Explanation:
RAG injects fresh, frequently changing knowledge at inference time by retrieving relevant content from an index and grounding the model's answer in it, which is exactly the "chat with your data" pattern this scenario describes. Microsoft's guidance is direct on the boundary between the two techniques.
Use fine-tuning when you need to change model behavior, style, or task performance, rather than add fresh knowledge.
NEW QUESTION # 120
You have a Microsoft Foundry project named Project1.
Project1 contains an application that processes PDF vendor invoices.
You need to configure Azure Document Intelligence in Foundry Tools to generate a Markdown output that preserves the sections and table structure of the PDFs. The solution must minimize development effort.
What should you do?
Answer: A
Explanation:
The correct answer is D. Set the output_content_format=ContentFormat.MARKDOWN value . Azure Document Intelligence Layout API can return extracted document content in Markdown format, preserving semantic structure such as headings, paragraphs, sections, tables, and other layout elements. Microsoft's Document Intelligence layout guidance shows the Python SDK pattern for analyzing a document with the prebuilt-layout model and setting output_content_format=ContentFormat.MARKDOWN in the begin_analyze_document call. The Markdown output is returned in the top-level content section of the analysis result.
This minimizes development effort because the service produces structure-preserving Markdown directly, rather than requiring custom post-processing to reconstruct sections and table formatting from raw OCR spans. Microsoft's Markdown output documentation states that specifying Markdown output produces semantically structured content that maintains paragraphs, headings, tables, and other document elements in their proper hierarchy.
Option A only changes validation behavior and does not generate Markdown. Option B requests figures, not structured Markdown. Option C uses an incorrect parameter name; the documented SDK setting is output_content_format, not content. Reference topics: Azure Document Intelligence Layout API, Markdown output, PDF analysis, table extraction, and Foundry Tools document processing.
NEW QUESTION # 121
You have a Microsoft Foundry project that contains an agent.
The agent uses Azure Content Understanding in Foundry Too to process vendor onboarding packets. The packs include digital PDFs that contain tables and hyperlinks.
The extracted content is indexed for search and provided to a downstream agent in the Markdown format.
You need to generate a Markdown output that has a layout and a semantic structure optimized for Retrieval Augmented Generation (RAG) workflows.
Which built-in analyzer should you use?
Answer: B
Explanation:
The appropriate built-in analyzer to use is prebuilt-documentSearch.
RAG Optimization: The prebuilt-documentSearch analyzer is part of the dedicated Retrieval- Augmented Generation (RAG) analyzer suite within Azure Content Understanding. It is specifically built to perform semantic analysis and extract documents in structures optimized for chunking, indexing, and vector workflows.
Native Markdown Layout: It extracts layout structures (such as paragraphs, complex multi-page tables, and hierarchical sections) directly into clean Markdown format. This structural preservation is ideal for downstream consumption by large language models (LLMs) or other AI agents.
Reference:
https://learn.microsoft.com/en-us/azure/ai-services/content-understanding/concepts/prebuilt-analyzers
NEW QUESTION # 122
You have a customer support agent built by using the Microsoft Foundry Agent Service. The agent calls an Azure OpenAI model deployment.
During load testing, calls intermittently fail and return an HTTP 429 rate limit exceeded error.
You need to handle throttling to reduce call failures and improve reliability under load. The solution must remain within the service and model limits.
What should you do?
Answer: A
Explanation:
To handle HTTP 429 throttling and improve load testing reliability for your Microsoft Foundry Agent Service, implement exponential backoff with jitter on the client side, deploy a load- balancing gateway across multiple Azure OpenAI regions, or upgrade your deployment to Provisioned Throughput Units (PTU).
*-> 1. Implement Client-Side Retry LogicConfigure your agent's HTTP client or SDK to handle
429 errors gracefully rather than failing immediately.
Exponential Backoff: Increase the wait time between subsequent retry attempts exponentially .
Jitter: Add a small amount of random delay (jitter) to the backoff time to prevent a "thundering herd" effect where all throttled requests retry simultaneously.
Header Inspection: Programmatically read the Retry-After or x-ratelimit-reset values from the HTTP 429 response headers to pause execution for the exact duration requested by Azure.
2. Set Up Multi-Region Load Balancing
3. Switch to Provisioned Throughput (PTU)
4. Optimize Token Consumption
Reference:
https://learn.microsoft.com/en-us/answers/questions/1518859/help-with-resolving-ptu-m-service-429-error
NEW QUESTION # 123
......
You can overcome this hurdle by selecting real Microsoft AI-103 Exam Dumps that can help you ace the AI-103 test quickly on the maiden endeavor. If you aspire to earn the Microsoft AI-103 Certification then obtaining trusted prep material is the most significant part of your AI-103 test preparation.
AI-103 Reliable Test Pattern: https://www.prep4king.com/AI-103-exam-prep-material.html
What's more, part of that Prep4King AI-103 dumps now are free: https://drive.google.com/open?id=11EVjZ9ONF4Rh0aWti6tdfiPG5yC4g_Ag