2026 Latest ExamsTorrent DP-700 PDF Dumps and DP-700 Exam Engine Free Share: https://drive.google.com/open?id=1Rf6QTi0sNvRi3hDQi5d04-tAjTYmO1An
We are constantly updating our practice material to ensure that you receive the latest preparation material based on the actual Microsoft DP-700 exam content. Up to 1 year of free Implementing Data Engineering Solutions Using Microsoft Fabric (DP-700) exam questions updates are also available at ExamsTorrent. The ExamsTorrent offers a money-back guarantee (terms and conditions apply) for students who fail to pass their Implementing Data Engineering Solutions Using Microsoft Fabric (DP-700) exam on the first try.
| Section | Objectives |
|---|---|
| Manage and monitor data solutions | - Optimize performance and reliability
|
| Design and implement data ingestion solutions | - Ingest batch and streaming data into Microsoft Fabric
|
| Secure and govern data in Microsoft Fabric | - Data governance and compliance
|
| Develop data transformation solutions | - Transform data using Spark in Fabric
|
>> Unlimited Microsoft DP-700 Exam Practice <<
The Microsoft DP-700 mock tests are specially built for you to evaluate what you have studied. These Implementing Data Engineering Solutions Using Microsoft Fabric (DP-700) practice exams (desktop and web-based) are customizable, which means that you can change the time and questions according to your needs. Our Implementing Data Engineering Solutions Using Microsoft Fabric (DP-700) practice tests teach you time management so you can pass the Implementing Data Engineering Solutions Using Microsoft Fabric (DP-700) certification exam.
NEW QUESTION # 65
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric eventstream that loads data into a table named Bike_Location in a KQL database. The table contains the following columns:
BikepointID
Street
Neighbourhood
No_Bikes
No_Empty_Docks
Timestamp
You need to apply transformation and filter logic to prepare the data for consumption. The solution must return data for a neighbourhood named Sands End when No_Bikes is at least 15. The results must be ordered by No_Bikes in ascending order.
Solution: You use the following code segment: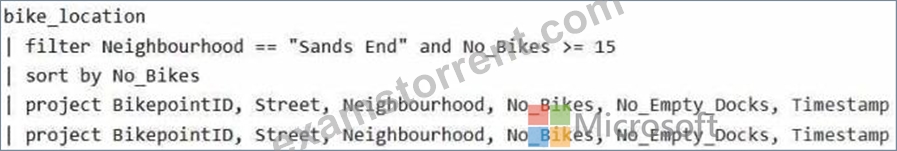
Does this meet the goal?
Answer: A
Explanation:
This code does not meet the goal because it uses sort by without specifying the order, which defaults to ascending, but explicitly mentioning asc improves clarity.
Correct code should look like: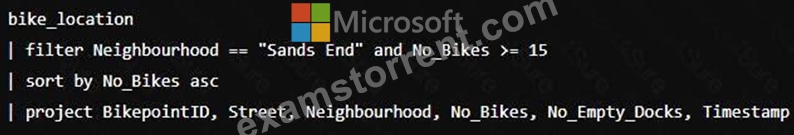
NEW QUESTION # 66
You have a Fabric .
In Warehouse1, you create a table named DimCustomer by running the following statement.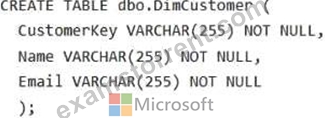
You need to set the Customerkey column as a primary key of the DimCustomer table.
Which three code segments should you run in sequence? To answer, move the appropriate code segments from the list of code segments to the answer area and arrange them in the correct order.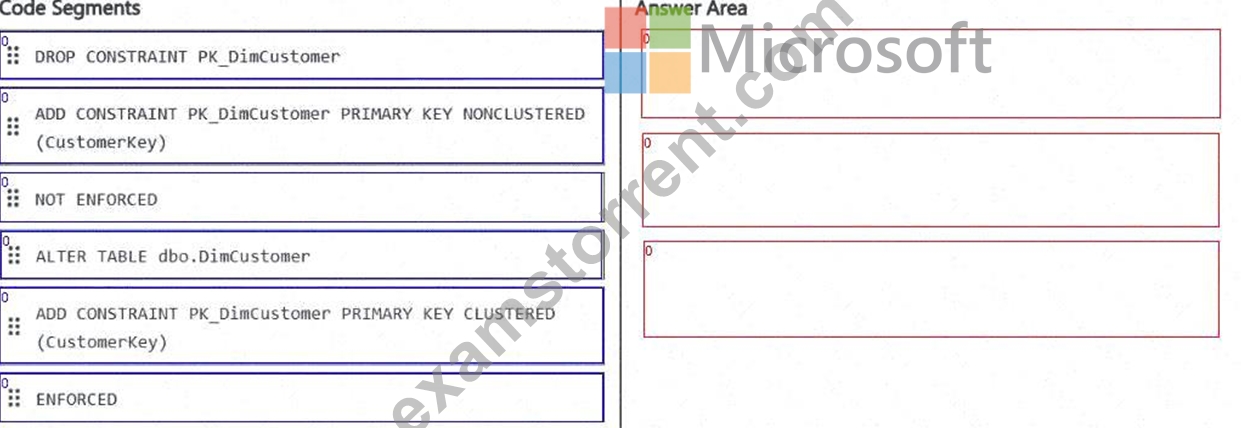
Answer:
Explanation: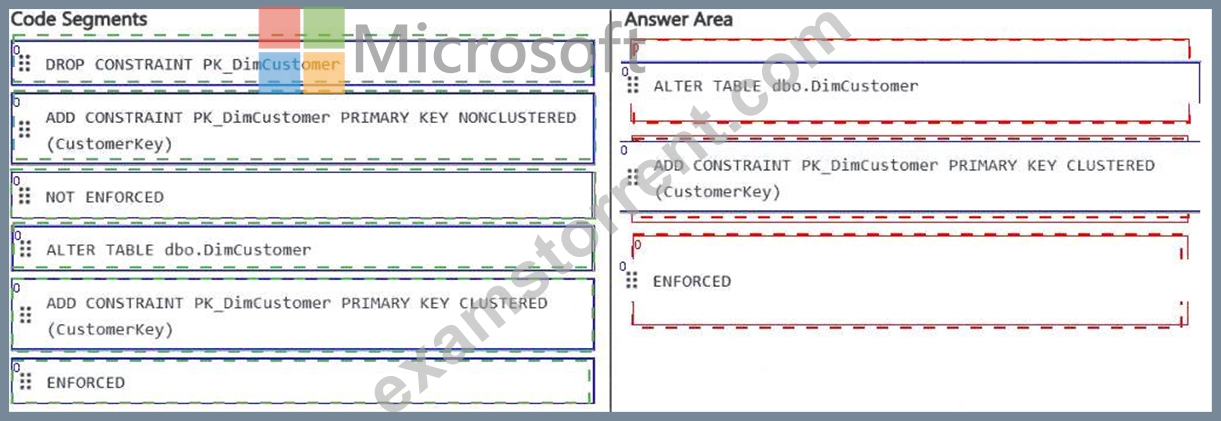
Explanation: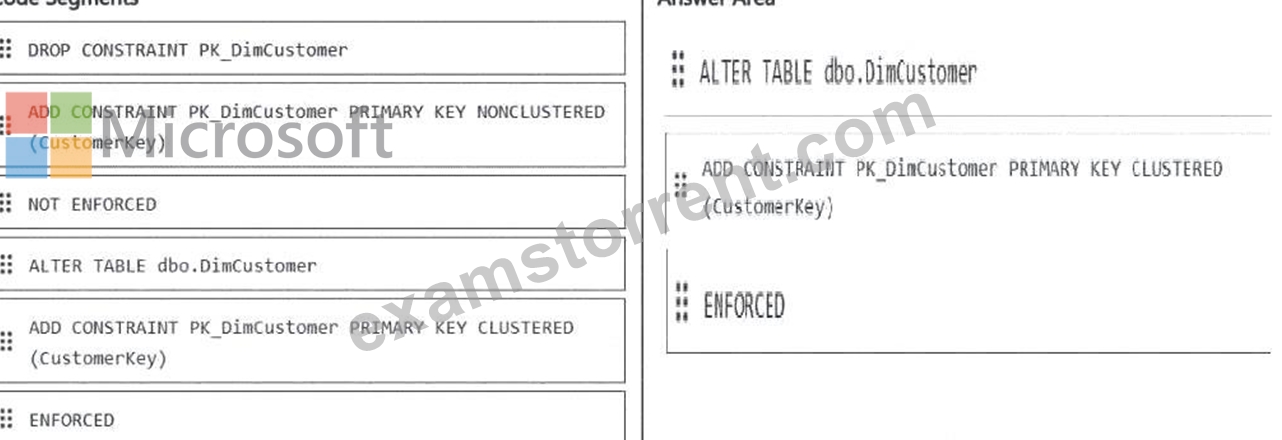
NEW QUESTION # 67
You have a Fabric workspace that contains a lakehouse named Lakehousel. Lakehousel contains a table named Status_Target that has the following columns:
* Key
* Status
* LastModified
The data source contains a table named Status.Source that has the same columns as Status_Target. Status.
Source is used to populate Status_Target. In a notebook name Notebook!, you load Status_Source to a DataFrame named sourceDF and Status_Target to a DataFrame named targetDF. You need to implement an incremental loading pattern by using Notebook-!. The solution must meet the following requirements:
* For all the matching records that have the same value of key, update the value of LastModified in Status_Target to the value of LastModified in Status_Source.
* Insert all the records that exist in Status_Source that do NOT exist in Status_Target.
* Set the value of Status in Status_Target to inactive for all the records that were last modified more than seven days ago and that do NOT exist in Status.Source.
How should you complete the statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.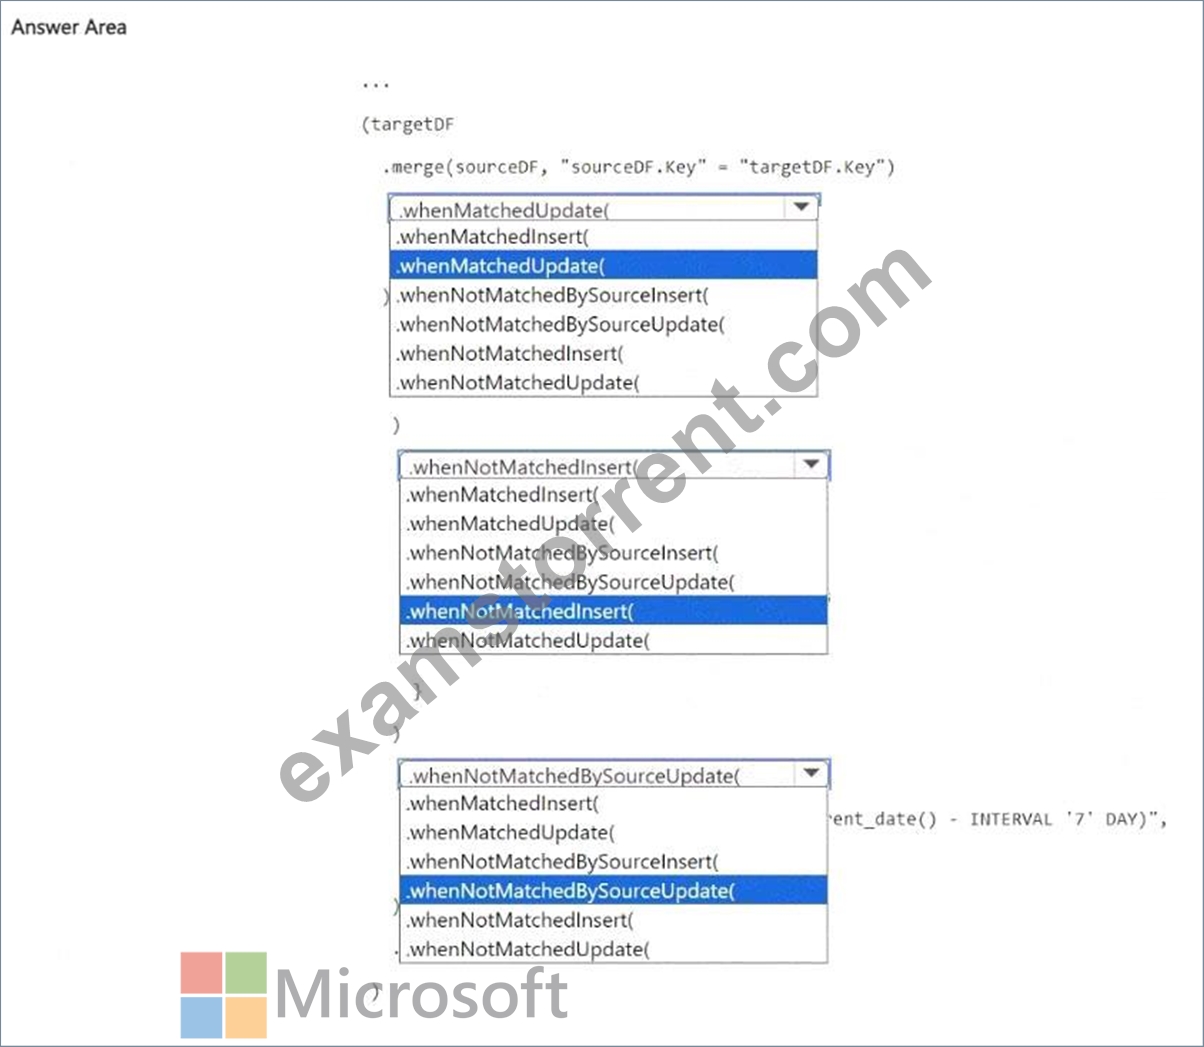
Answer:
Explanation: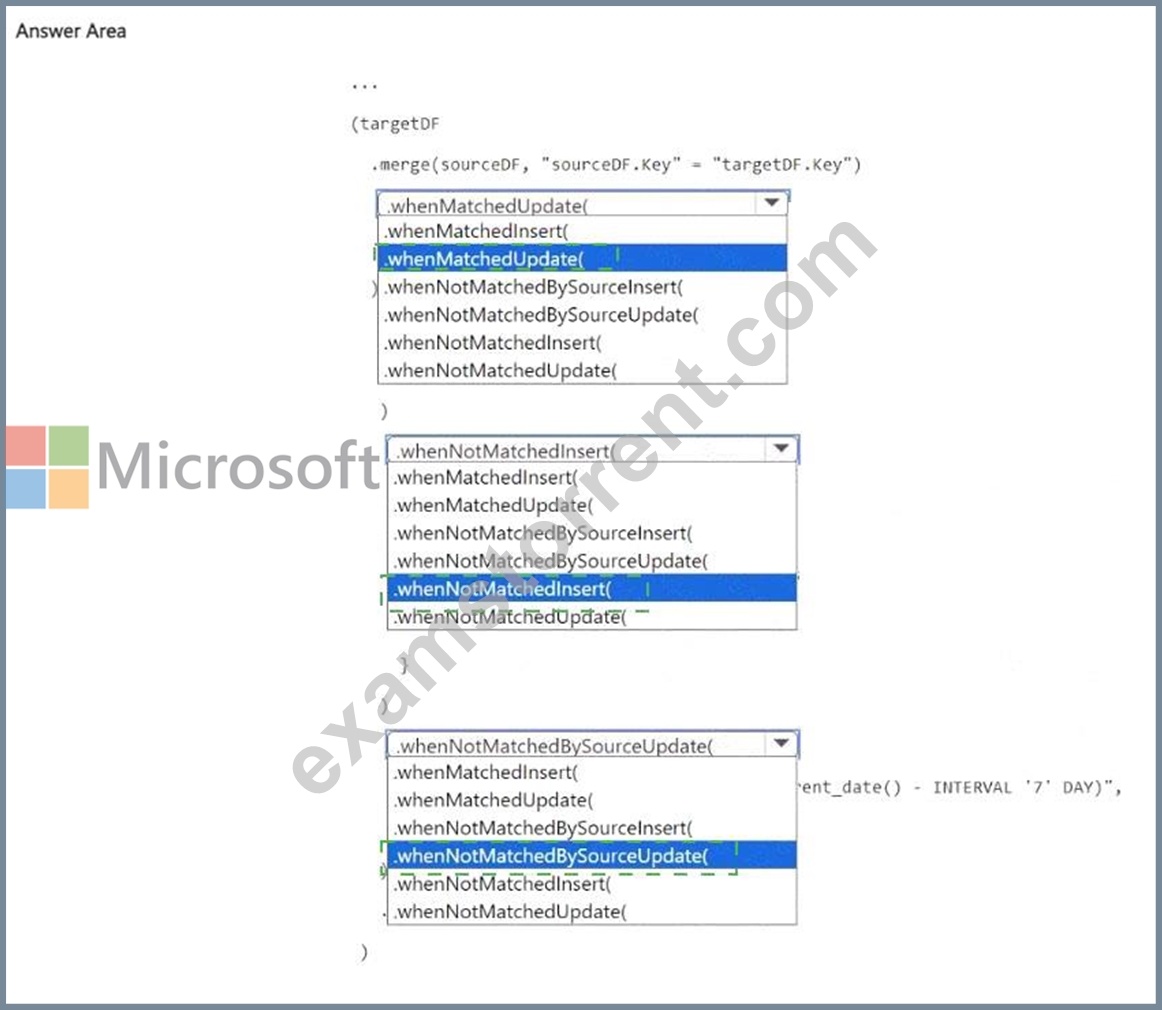
Explanation: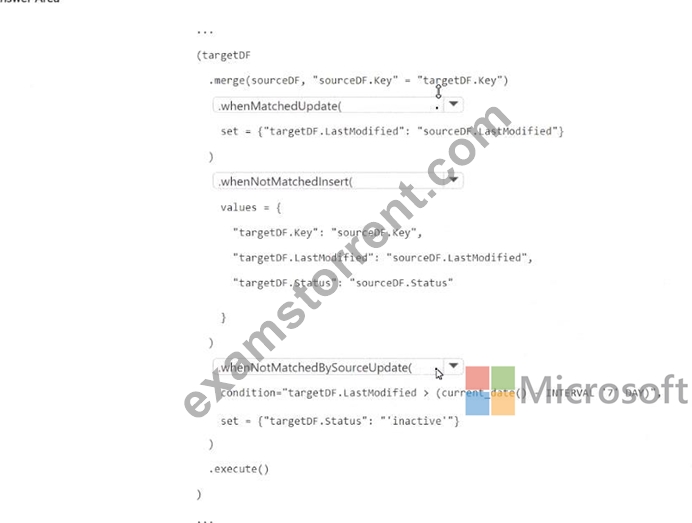
NEW QUESTION # 68
You have a Fabric workspace that contains a lakehouse named Lakehouse1.
In an external data source, you have data files that are 500 GB each. A new file is added every day.
You need to ingest the data into Lakehouse1 without applying any transformations. The solution must meet the following requirements Trigger the process when a new file is added.
Provide the highest throughput.
Which type of item should you use to ingest the data?
Answer: A
Explanation:
To efficiently ingest large data files (500 GB each) into Lakehouse1 with high throughput and trigger the process when a new file is added, a Data pipeline is the most suitable solution. Data pipelines in Fabric are ideal for orchestrating data movement and can be configured to automatically trigger based on file arrivals or other events. This solution meets both requirements: ingesting the data without transformations (since you just need to copy the data) and triggering the process when new files are added.
NEW QUESTION # 69
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a KQL database that contains two tables named Stream and Reference. Stream contains streaming data in the following format.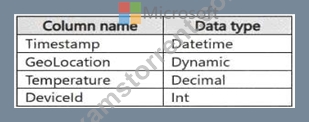
Reference contains reference data in the following format.
Both tables contain millions of rows.
You have the following KQL queryset.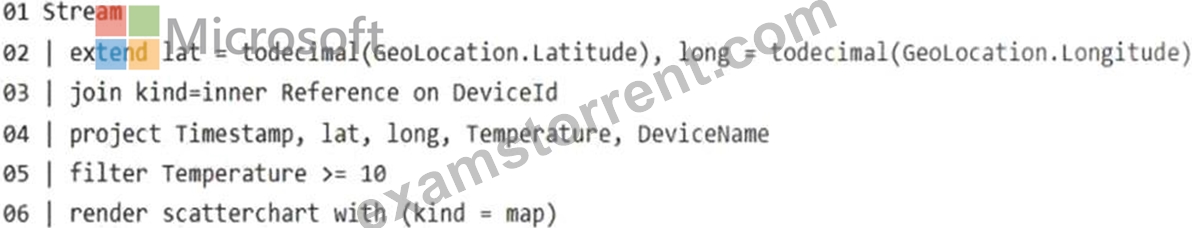
You need to reduce how long it takes to run the KQL queryset.
Solution: You change the join type to kind=outer.
Does this meet the goal?
Answer: A
Explanation:
An outer join will include unmatched rows from both tables, increasing the dataset size and processing time.
It does not improve query performance.
NEW QUESTION # 70
......
In today's society, the pace of life is very fast. No matter what your current status is DP-700 exam questions can save you the most time, and then pass the exam while still having your own life time. The users of the DP-700 Study Materials are very extensive, but everyone has a common feature, that is, hope to obtain the DP-700 certification in the shortest possible time. You can really do this in our DP-700 learning guide.
Exam Vce DP-700 Free: https://www.examstorrent.com/DP-700-exam-dumps-torrent.html
P.S. Free 2026 Microsoft DP-700 dumps are available on Google Drive shared by ExamsTorrent: https://drive.google.com/open?id=1Rf6QTi0sNvRi3hDQi5d04-tAjTYmO1An