DOWNLOAD the newest ITPassLeader DP-750 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1H7VjLhce5soOc5iV6JcNPh-qA8ZMxF2k
But the helpful feature is that it works without a stable internet service. What makes your Microsoft Certification Exams preparation super easy is it imitates the exact syllabus and structure of the actual Microsoft DP-750 Certification Exam. ITPassLeader never leaves its customers in the lurch.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30–35% | - Ingest and transform data
|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
Developing your niche is very easy in the presence of the DP-750 dumps. The credentials are not very difficult to achieve because like DP-750 the acclaimed vendors are highly successful in the industry. If you need a boost in your career, then ITPassLeader is the site you have to opt for taking DP-750 Certification exams. Some of the vital features of the DP-750 dumps of ITPassLeader are given below. DP-750 dumps are the most verified and authentic braindumps that are used to pass the DP-750 certification exam. The whole DP-750 study material is approved by the expert.
NEW QUESTION # 21
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1. Job1 contains multiple tasks.
Failures of non-critical tasks must be logged but must NOT trigger notifications. Notifications must be triggered only when critical tasks have failed, and Job1 has completed You need to configure the job alerting behavior.
What should trigger a notification?
Answer: A
Explanation:
The correct answer is B - a job failure.
The requirement draws a clear line: non-critical task failures should be logged silently; notifications should only fire when a critical failure causes the whole job to stop. Configuring the alert on 'Job Failure' achieves this precisely - the notification triggers when the job itself reaches a Failed terminal state, which only happens when at least one critical task has failed and the job cannot complete.
Option A (task failure) would send a notification for every task-level failure, including non-critical ones.
That's exactly the noise the question wants to avoid. Option C (job success) would never alert on failures at all. Option D (task success) confirms completion but doesn't catch failures.
Setting alerting at the job level rather than the task level is also simpler to configure - you don't need to mark individual tasks as critical or non-critical in the notification settings.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/alerts
NEW QUESTION # 22
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two Delta tables named Table1 and Table2 of the same data type.
Table1 contains a column named Columnl. Table2 contains a column named Column2. You run the following query.
SELECT Column1
FROM Table1
GROUP BY Column1
HAVING COUNT(") > 1
INTERSECT
SELECT C0lumn2
FROM Table2
GROUP BY Column2
HAVING COUNT(') > 1;
What occurs when you run the query?
Answer: C
Explanation:
The correct answer is B - values appear in both tables more than once.
Reading the query from the inside out: each subquery identifies values that appear more than once within their own table. The first subquery returns Column1 values that are duplicated in Table1. The second returns Column2 values that are duplicated in Table2. INTERSECT then returns only the values that appear in both result sets - meaning values that are duplicated in Table1 AND also duplicated in Table2.
Option A describes a UNION result (values in either table), not INTERSECT. Option C only considers duplicates in Table1, ignoring the Table2 condition - that would be the first subquery in isolation. Option D describes values exclusive to Table2 (EXCEPT or MINUS), the opposite of INTERSECT's requirement that values appear in both sets.
INTERSECT always requires membership in both operands - that's its fundamental definition in standard SQL.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/sql-ref-syntax-qry-select- setops
NEW QUESTION # 23
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Table1. Table1 stores customer data.
You need to implement a data retention solution that meets the following requirements:
- Deleted data must be retained for 30 days to support audits.
- Deleted data that is older than 30 days must be removed permanently.
- The solution must minimize administrative effort
Which two properties should you configure? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,E
Explanation:
To configure an Azure Databricks managed Delta table to retain deleted data for 30 days and minimize administrative overhead, you must set the following table properties:
delta.logRetentionDuration: Set this to interval 30 days. This property controls how long the transaction log history is kept, which is essential for audit trails and time travel.delta.
deletedFileRetentionDuration: Set this to interval 30 days. This property determines the threshold for when deleted data files become eligible for permanent removal by the VACUUM command.
Reference:
https://docs.databricks.com/aws/en/delta/history
NEW QUESTION # 24
You have an Azure Databricks workspace that uses Databricks SQL.
You have a table named sales_goals_source that contains the following columns:
* Salesperson
* Item
* 2019
* 2020
* 2021
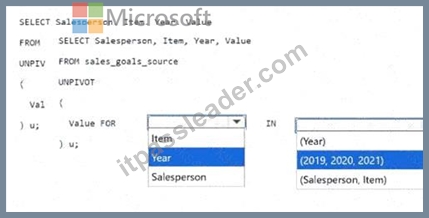
You need to transform the year columns into rows and return the columns Salesperson, Item, Year, and Value.
How should you complete the SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
SELECT Salesperson, Item, Year, Value
FROM sales_goals_source
UNPIVOT
(
Value FOR [first dropdown] IN [second dropdown]
);
Answer:
Explanation: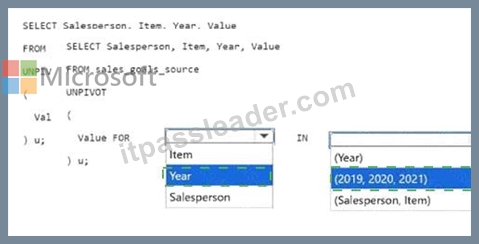
Explanation:
First dropdown: Year
Second dropdown: (2019, 2020, 2021)
The UNPIVOT operator converts the separate 2019, 2020, and 2021 columns into rows. Value becomes the output column containing the values previously stored in those year columns. Year becomes the output name column that identifies the original column from which each value came. Therefore, the expression must use Value FOR Year IN (2019, 2020, 2021). The Salesperson and Item columns are not included in the IN list because they remain identifier columns and are repeated for every resulting year row. A single source row consequently produces three output rows-one for each listed year. Selecting (Year) would reference an output name rather than the source columns that must be rotated.
NEW QUESTION # 25
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to ensure that data lineage is captured and can be reviewed for tables accessed by Databricks notebooks and jobs. The solution must minimize administrative effort.
Which compute configuration should you use to capture the data lineage, and what should you use to review the data lineage? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.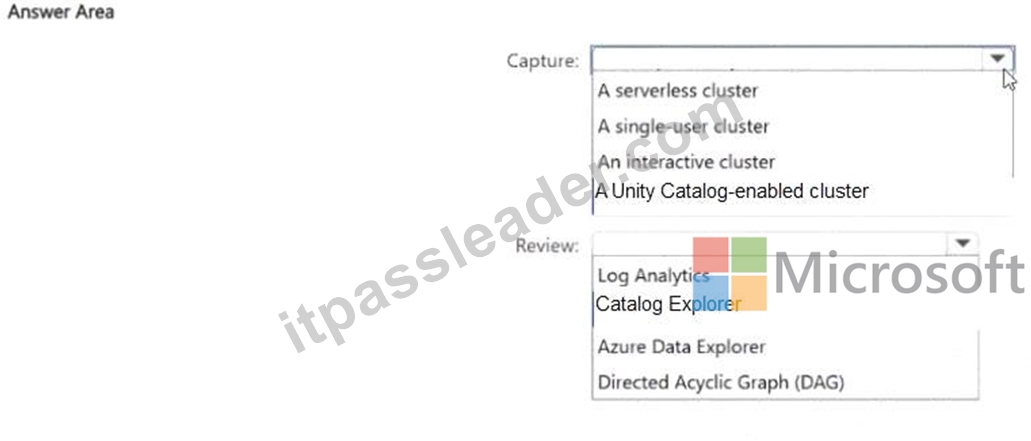
Answer:
Explanation: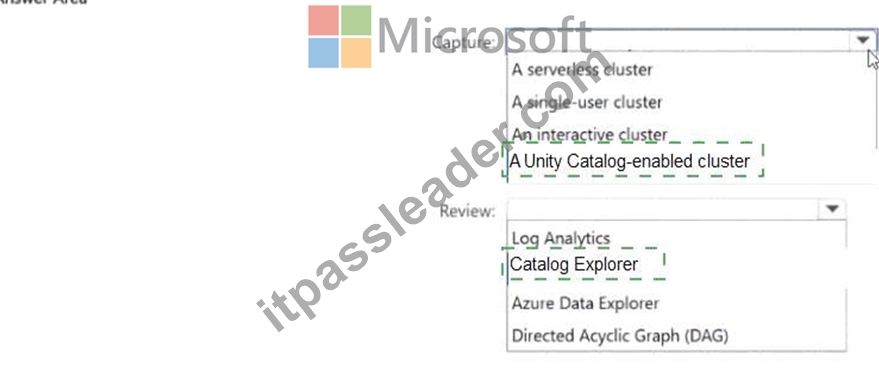
Explanation:
Data lineage in Unity Catalog is captured automatically - but only when jobs and notebooks run on clusters that are Unity Catalog-aware. Specifically, clusters must use 'Shared' or 'Single User' access mode. Clusters set to 'No Isolation Shared' or legacy 'High Concurrency' mode do not emit lineage events to the Unity Catalog lineage service.
No instrumentation, logging code, or external tools are required. The lineage service operates transparently, intercepting read and write operations at the Spark plan level and recording the table-to-table and column-to- column relationships.
To review captured lineage, open Catalog Explorer, navigate to the table, and select the Lineage tab. This shows the upstream sources that populate the table and the downstream consumers that read from it - all as an interactive graph, with no additional tooling needed. This built-in visibility is one of the core governance benefits Unity Catalog provides.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/data-lineage
NEW QUESTION # 26
......
Our DP-750 exam cram has been revised for lots of times to ensure all candidates can easily understand all knowledge parts. In the meantime, the learning process is recorded clearly in the system, which helps you adjust your learning plan. On the one hand, our company has benefited a lot from renovation. Customers are more likely to choose our products. On the other hand, the money we have invested is meaningful, which helps to renovate new learning style of the DP-750 Exam. So, why not buy our DP-750 test guide?
Examcollection DP-750 Free Dumps: https://www.itpassleader.com/Microsoft/DP-750-dumps-pass-exam.html
P.S. Free & New DP-750 dumps are available on Google Drive shared by ITPassLeader: https://drive.google.com/open?id=1H7VjLhce5soOc5iV6JcNPh-qA8ZMxF2k