100% Pass Databricks - High Hit-Rate Certified-Data-Engineer-Professional - Study Databricks Certified Data Engineer Professional Tool

We even guarantee our customers that they will pass Databricks Certified-Data-Engineer-Professional exam easily with our provided study material and if they failed to do it despite all their efforts they can claim a full refund of their money (terms and conditions apply). The third format is the desktop software format which can be accessed after installing the software on your Windows computer or laptop. The Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) has three formats so that the students don't face any serious problems and prepare themselves with fully focused minds.
| Section | Objectives |
|---|
| Data Modeling | - Design and optimize data models
- 1. Simplify data layout decisions and optimize query performance using liquid clustering
- 2. Design and implement scalable data models using Delta Lake to manage large datasets
- 3. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 4. Design dimensional models for analytical workloads with efficient querying and aggregation
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 2. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 3. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 4. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 5. Apply Change Data Feed to address streaming table limitations and improve latency
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Develop User-Defined Functions using Pandas/Python UDF
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 2. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 3. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 4. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 5. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 6. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 7. Create pipeline components using control flow operators such as if/else and foreach
- 8. Explain the advantages and disadvantages of streaming tables compared to materialized views
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Monitoring and Alerting | - Monitoring
- 1. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 2. Use Query Profile and Spark UI to monitor workloads
- 3. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 4. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
|
| Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 2. Use row filters and column masks to protect sensitive table data
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
- Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
|
| Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
>> Study Certified-Data-Engineer-Professional Tool <<
Certified-Data-Engineer-Professional Test Questions - Certified-Data-Engineer-Professional Test Torrent & Certified-Data-Engineer-Professional Latest Torrents
It is a universally accepted fact that the Certified-Data-Engineer-Professional exam is a tough nut to crack for the majority of candidates, but there are still a lot of people in this field who long to gain the related certification so that a lot of people want to try their best to meet the challenge of the Certified-Data-Engineer-Professional exam. A growing number of people know that if they have the chance to pass the Certified-Data-Engineer-Professional Exam, they will change their present situation and get a more decent job in the near future. More and more people have realized that they need to try their best to prepare for the Certified-Data-Engineer-Professional exam.
Databricks Certified Data Engineer Professional Sample Questions (Q191-Q196):
NEW QUESTION # 191
Which statement characterizes the general programming model used by Spark Structured Streaming?
- A. Structured Streaming is implemented as a messaging bus and is derived from Apache Kafka.
- B. Structured Streaming models new data arriving in a data stream as new rows appended to an unbounded table.
- C. Structured Streaming relies on a distributed network of nodes that hold incremental state values for cached stages.
- D. Structured Streaming uses specialized hardware and I/O streams to achieve sub-second latency for data transfer.
- E. Structured Streaming leverages the parallel processing of GPUs to achieve highly parallel data throughput.
Answer: B
Explanation:
The key idea in Structured Streaming is to treat a live data stream as a table that is being continuously appended. This leads to a new stream processing model that is very similar to a batch processing model. You will express your streaming computation as standard batch-like query as on a static table, and Spark runs it as an incremental query on the unbounded input table. Let's understand this model in more detail.
https://spark.apache.org/docs/latest/structured-streaming-programming-guide.html
NEW QUESTION # 192
A data engineer is implementing Unity Catalog governance for a multi-team environment. Data scientists need interactive clusters for basic data exploration tasks, while automated ETL jobs require dedicated processing. How should the data engineer configure cluster isolation policies to enforce least privilege and ensure Unity Catalog compliance?
- A. Allow all users to create any cluster type and rely on manual configuration to enable Unity Catalog access modes.
- B. Use only DEDICATED access mode for both interactive workloads and automated jobs to maximize security isolation.
- C. Configure all clusters with NO ISOLATION_SHARED access mode since Unity Catalog works with any cluster configuration.
- D. Create compute policies with STANDARD access mode for interactive workloads and DEDICATED access mode for automated jobs.
Answer: D
Explanation:
Unity Catalog enforces governance and data isolation through cluster access modes and compute policies. According to Databricks documentation, "Interactive clusters that multiple users share should use Standard access mode, while automated jobs and production pipelines should use Dedicated access mode for stricter isolation." Standard access mode allows multiple users to share the same compute resources but still respects Unity Catalog permissions. Dedicated access mode isolates the job run's execution environment, ensuring that data access is limited to the job's identity. Configuring these modes within compute policies enforces least privilege and ensures all compute complies with Unity Catalog security standards. Options A and C are incorrect because using only Dedicated clusters reduces resource efficiency, while "No isolation" clusters are not Unity Catalog compliant.
NEW QUESTION # 193
The data engineer team has been tasked with configured connections to an external database that does not have a supported native connector with Databricks. The external database already has data security configured by group membership. These groups map directly to user group already created in Databricks that represent various teams within the company. A new login credential has been created for each group in the external database. The Databricks Utilities Secrets module will be used to make these credentials available to Databricks users. Assuming that all the credentials are configured correctly on the external database and group membership is properly configured on Databricks, which statement describes how teams can be granted the minimum necessary access to using these credentials?
- A. No additional configuration is necessary as long as all users are configured as administrators in the workspace where secrets have been added.
- B. "Read'' permissions should be set on a secret key mapped to those credentials that will be used by a given team.
- C. "Manage" permission should be set on a secret scope containing only those credentials that will be used by a given team.
- D. "Read" permissions should be set on a secret scope containing only those credentials that will be used by a given team.
Answer: D
Explanation:
In Databricks, using the Secrets module allows for secure management of sensitive information such as database credentials. Granting 'Read' permissions on a secret key that maps to database credentials for a specific team ensures that only members of that team can access these credentials. This approach aligns with the principle of least privilege, granting users the minimum level of access required to perform their jobs, thus enhancing security.
NEW QUESTION # 194
A data engineering team is collaborating on a Databricks project where each team member needs to develop and test code independently before merging changes into the main branch.
They want to avoid accidental overwrites or branch switching issues while ensuring that all work is version- controlled and can be integrated into their CI/CD pipeline.
How should the data engineer achieve collaboration?
- A. Team members edit notebooks directly in the workspace's shared folder and periodically copy changes into a Git folder for version control.
- B. All team members work in the same Databricks Git folder and perform Git operations (pull, push, commit, branch switching) directly in that shared folder.
- C. Each team member creates their own Databricks Git folder, mapped to the same remote Git repository, and works in their own development branch within their personal folder.
- D. Team members use the Databricks CLI to clone the Git repository and perform Git operations from a cluster's web terminal.
Answer: C
Explanation:
Using separate Databricks Git folders per user mapped to the same remote repository allows each team member to work independently on their own branch without interfering with others.
This prevents accidental overwrites or branch conflicts while ensuring all changes are version- controlled and easily integrated into CI/CD workflows.
NEW QUESTION # 195
The data engineering team has configured a Databricks SQL query and alert to monitor the values in a Delta Lake table. The recent_sensor_recordings table contains an identifying sensor_id alongside the timestamp and temperature for the most recent 5 minutes of recordings.
The below query is used to create the alert:
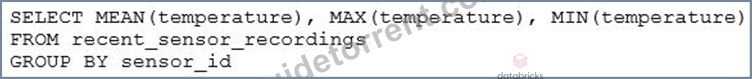
The query is set to refresh each minute and always completes in less than 10 seconds. The alert is set to trigger when mean (temperature) > 120. Notifications are triggered to be sent at most every 1 minute.
If this alert raises notifications for 3 consecutive minutes and then stops, which statement must be true?
- A. The recent_sensor_recordingstable was unresponsive for three consecutive runs of the query
- B. The maximum temperature recording for at least one sensor exceeded 120 on three consecutive executions of the query
- C. The source query failed to update properly for three consecutive minutes and then restarted
- D. The average temperature recordings for at least one sensor exceeded 120 on three consecutive executions of the query
- E. The total average temperature across all sensors exceeded 120 on three consecutive executions of the query
Answer: D
Explanation:
This is the correct answer because the query is using a GROUP BY clause on the sensor_id column, which means it will calculate the mean temperature for each sensor separately. The alert will trigger when the mean temperature for any sensor is greater than 120, which means at least one sensor had an average temperature above 120 for three consecutive minutes. The alert will stop when the mean temperature for all sensors drops below 120.
NEW QUESTION # 196
......
You must want to receive our Certified-Data-Engineer-Professional practice materials at the first time after payment. Don't worry. As long as you finish your payment, our online workers will handle your orders of the study materials quickly. The whole payment process lasts a few seconds. Besides that, you can ask what you want to know about our Certified-Data-Engineer-Professional Study Guide. Once you submit your questions, we will soon give you detailed explanations. Even you come across troubles during practice the Certified-Data-Engineer-Professional study materials; we will also help you solve the problems. We are willing to deal with your problems on Certified-Data-Engineer-Professional learning guide.
New Certified-Data-Engineer-Professional Braindumps Files: https://www.guidetorrent.com/Certified-Data-Engineer-Professional-pdf-free-download.html
- Databricks Certified-Data-Engineer-Professional Practice Test Prepare for Success 🍆 ▷ www.torrentvce.com ◁ is best website to obtain ✔ Certified-Data-Engineer-Professional ️✔️ for free download 🎽Exam Certified-Data-Engineer-Professional Bootcamp
- Certified-Data-Engineer-Professional Reliable Exam Simulator 🏄 Certified-Data-Engineer-Professional Exam Dumps 🔱 Certified-Data-Engineer-Professional Valid Braindumps Book 🤤 Search for [ Certified-Data-Engineer-Professional ] and download it for free on 《 www.pdfvce.com 》 website 👬Certified-Data-Engineer-Professional Valid Exam Objectives
- New Certified-Data-Engineer-Professional Braindumps Files 😟 Certified-Data-Engineer-Professional Exam Certification 📿 Certified-Data-Engineer-Professional Valid Practice Questions 🍸 Enter ➽ www.vceengine.com 🢪 and search for ➽ Certified-Data-Engineer-Professional 🢪 to download for free 🧖Certified-Data-Engineer-Professional Reliable Exam Materials
- Free PDF 2026 Databricks High Hit-Rate Study Certified-Data-Engineer-Professional Tool 🐃 Copy URL ▷ www.pdfvce.com ◁ open and search for ( Certified-Data-Engineer-Professional ) to download for free 👒Certified-Data-Engineer-Professional Certified
- Databricks Certified-Data-Engineer-Professional Practice Test Prepare for Success 🛣 Search for ➤ Certified-Data-Engineer-Professional ⮘ and obtain a free download on ⮆ www.vceengine.com ⮄ ‼Certified-Data-Engineer-Professional Pdf Braindumps
- Certified-Data-Engineer-Professional Certified 🩺 Certified-Data-Engineer-Professional Demo Test 🔤 Certified-Data-Engineer-Professional Valid Braindumps Book 🍙 Enter ⮆ www.pdfvce.com ⮄ and search for “ Certified-Data-Engineer-Professional ” to download for free 😽New Certified-Data-Engineer-Professional Study Guide
- Certified-Data-Engineer-Professional Reliable Exam Materials ⛹ Certified-Data-Engineer-Professional Study Tool 🍀 Certified-Data-Engineer-Professional Valid Study Questions 🙅 Immediately open ⇛ www.pdfdumps.com ⇚ and search for [ Certified-Data-Engineer-Professional ] to obtain a free download 🥳Certified-Data-Engineer-Professional New Study Guide
- Certified Certified-Data-Engineer-Professional Questions 🅱 New Certified-Data-Engineer-Professional Braindumps Files 👽 Certified Certified-Data-Engineer-Professional Questions ⏯ Easily obtain 《 Certified-Data-Engineer-Professional 》 for free download through ▶ www.pdfvce.com ◀ ➖Certified-Data-Engineer-Professional Certified
- Databricks Certified-Data-Engineer-Professional Practice Test Prepare for Success 📙 Search for 《 Certified-Data-Engineer-Professional 》 and download exam materials for free through ⏩ www.dumpsquestion.com ⏪ 📑Certified-Data-Engineer-Professional Valid Braindumps Book
- Why do you need to Trust Pdfvce Databricks Certified-Data-Engineer-Professional Exam Questions? 🥠 Download ▶ Certified-Data-Engineer-Professional ◀ for free by simply entering 「 www.pdfvce.com 」 website 💂Hot Certified-Data-Engineer-Professional Spot Questions
- Certified-Data-Engineer-Professional Valid Practice Questions 🦏 Braindumps Certified-Data-Engineer-Professional Downloads ❔ Hot Certified-Data-Engineer-Professional Spot Questions 🔐 Search on [ www.prepawayexam.com ] for ➽ Certified-Data-Engineer-Professional 🢪 to obtain exam materials for free download 🗯Certified-Data-Engineer-Professional Exam Dumps
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, everlink.tools, www.stes.tyc.edu.tw, github.com, Disposable vapes