BTW, DOWNLOAD part of PassLeaderVCE DP-800 dumps from Cloud Storage: https://drive.google.com/open?id=14P4GykHeay2IYEOD-6SYLOwpaq7ijE5R
The PassLeaderVCE is a leading platform that is committed to making the Microsoft DP-800 exam dumps preparation simple, quick, and successful. To achieve this objective PassLeaderVCE is offering real, valid, and updated Developing AI-Enabled Database Solutions (DP-800) practice questions in three different formats. These formats are PassLeaderVCE Microsoft DP-800 PDF Dumps Files, desktop practice test software, and web-based practice test software. All these PassLeaderVCE Microsoft exam questions formats are easy to use and compatible with all web browsers, operating systems, and devices.
| Section | Objectives |
|---|---|
| Design and implement data solutions | - Implement data storage and data processing solutions - Design database solutions using Azure data services |
| Integrate AI capabilities with database systems | - Use Azure AI services with database workloads - Implement AI-assisted data processing |
| Monitor, troubleshoot, and maintain solutions | - Monitoring database health and performance - Troubleshooting data pipeline issues |
| Develop and manage database solutions | - Optimize performance and scalability - Ensure security and compliance of data solutions |
One advantage is that if you use our DP-800 practice questions for the first time in a network environment, then the next time you use our study materials, there will be no network requirements. You can open the DP-800 real exam anytime and anywhere. It means that it can support offline practicing. And our DP-800 learning braindumps are easy to understand for the questions and answers are carefully compiled by the professionals.
NEW QUESTION # 30
You have an SDK-style SQL database project stored in a Git repository. The project targets an Azure SQL database.
The CI build fails with unresolved reference errors when the project leferences system objects.
You need to update the SQL database project to ensure that dotnet build validates successfully by including the correct system objects in the database model for Azure SQL Database.
Solution: Add an artifact reference to the Azure SQL Database master.dacpac file.
Does this meet the goal?
Answer: B
Explanation:
For an SDK-style SQL database project targeting Azure SQL Database , Microsoft recommends using the Azure SQL system DACPAC as a NuGet package reference rather than adding a direct artifact reference to master.dacpac for new SDK-style development. Microsoft's SQL Database Projects documentation says direct .dacpac artifact references are not recommended for new development in SDK-style projects ; instead, use NuGet package references .
Because the goal is specifically to make dotnet build validate successfully with the correct Azure SQL system objects , adding an artifact reference to master.dacpac is not the recommended SDK-style solution. It can work in some project styles, but it does not meet the stated goal as the proper approach for SDK-style Azure SQL projects.
NEW QUESTION # 31
You have an Azure SQL database named SalesDB on a logical server named sales-sql01.
You have an Azure App Service web app named OrderApi that connects to SalesDB by using SQL authentication.
You enable a user-assigned managed identity named OrderApi-Id for OrderApi.
You need to configure OrderApi to connect to SalesDB by using Microsoft Entra authentication. The managed identity must have read and write permissions to SalesDB.
Which Transact-SQL statements should you run in SalesDB?
Answer: C
Explanation:
For an Azure App Service using a user-assigned managed identity to connect to Azure SQL Database with Microsoft Entra authentication , the required database-side step is to create a database user from the external provider , then grant the needed database roles. Microsoft's Azure SQL documentation for managed identities states that to let a managed identity access the target database, you create a SQL user for that identity by using:
CREATE USER [ < identity-name > ] FROM EXTERNAL PROVIDER;
and then assign the appropriate roles.
That makes db_datareader and db_datawriter the right role grants here, because the requirement says the identity must have read and write permissions to SalesDB.
The other options are incorrect:
* A uses CREATE LOGIN ... FROM EXTERNAL PROVIDER, which is not the right choice for this Azure SQL Database scenario; the documented pattern is to create a database user from the external provider.
* B and D create SQL-authentication principals with passwords, which does not meet the Microsoft Entra managed-identity requirement.
* D also grants sysadmin, which is a server-level overgrant and not appropriate for the stated read/write requirement.
NEW QUESTION # 32
Hotspot Question
You have an Azure SQL database that contains a table named Table1. Table1 contains
25,000,000 rows of data and a datetime2 column named DateKey. The data in Table1 spans the years 2020 through 2021.
You need to partition the data in Table1 by year. The solution must minimize how long it takes to rebuild or reindex the table.
How should you complete the Transact-SQL code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.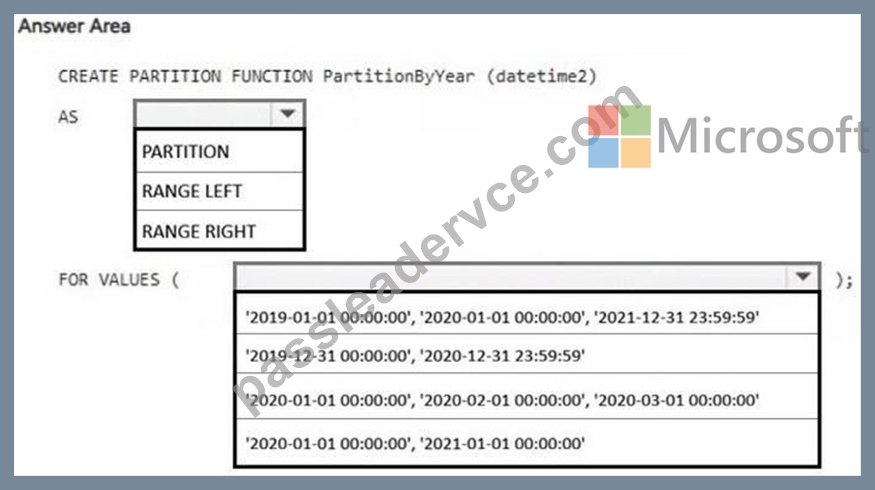
Answer:
Explanation: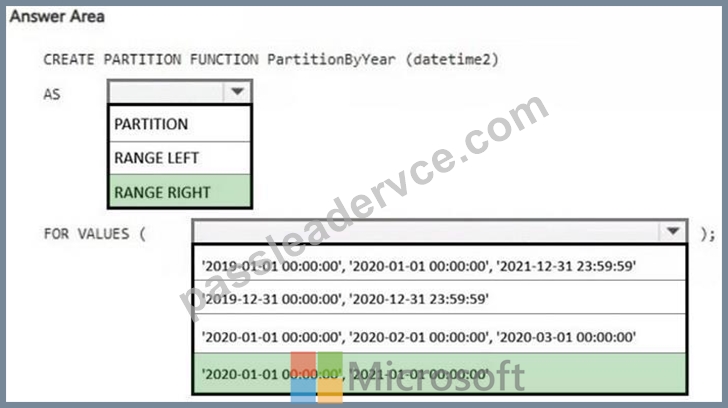
NEW QUESTION # 33
You have an Azure AI Search service and an index named hotels that includes a vector field named DescriptionVector.
You query hotels by using the Search Documents REST API.
You need to implement a hybrid search query that uses DescriptionVector and includes captions.
How should you complete the REST request body? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.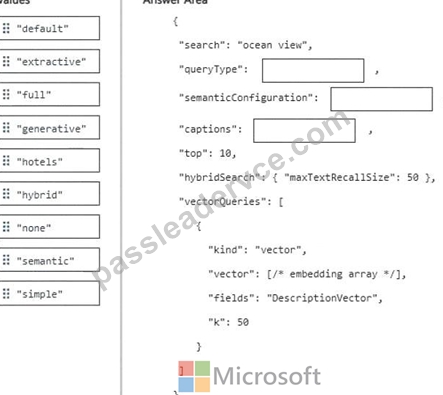
Answer:
Explanation: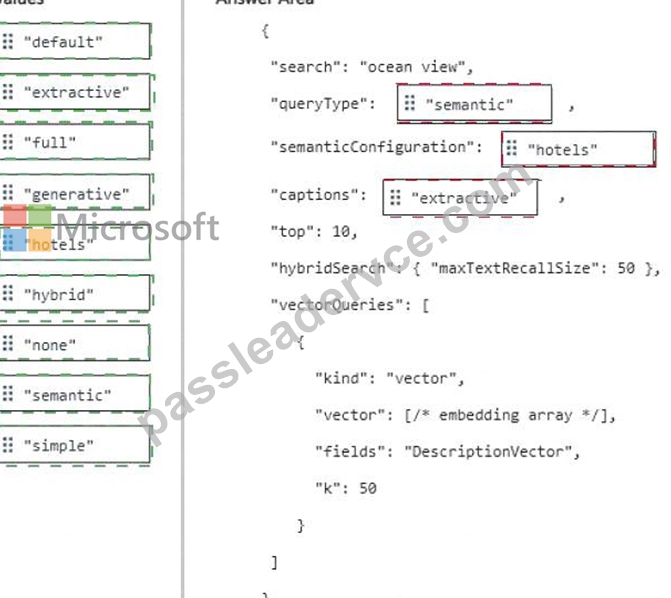
Explanation:
Verified Answer : =
* queryType # " semantic "
* semanticConfiguration # " hotels "
* captions # " extractive "
Comprehensive and Detailed Explanation with all Developing AI-Enabled Database Solutions documents : = The correct configuration is queryType: " semantic " , semanticConfiguration: " hotels " , and captions: " extractive " .
The request is already a hybrid search because it contains both a textual search value ( " ocean view " ) and a vectorQueries block targeting DescriptionVector . Microsoft documents that hybrid search executes full-text and vector searches together and merges their result sets. When semantic ranking is required, queryType must be set to " semantic " .
The semanticConfiguration value must reference the semantic configuration defined for the target index.
Since the index in this question is named hotels and the available answer choice is " hotels " , that is the appropriate configuration value in the supplied answer set. Microsoft's REST examples show that semantic queries require both queryType: " semantic " and a valid semanticConfiguration .
To return semantic captions, use " captions " : " extractive " . Microsoft states that extractive captions identify the most relevant passages from the indexed content and return them with each result. They are generated from existing document text rather than generated by an LLM.
The completed request body is therefore:
{
" search " : " ocean view " ,
" queryType " : " semantic " ,
" semanticConfiguration " : " hotels " ,
" captions " : " extractive " ,
" top " : 10,
" hybridSearch " : {
" maxTextRecallSize " : 50
},
" vectorQueries " : [
{
" kind " : " vector " ,
" vector " : [ /* embedding array */ ],
" fields " : " DescriptionVector " ,
" k " : 50
}
]
}
Final drag-and-drop selections:
* First target: " semantic "
* Second target: " hotels "
* Third target: " extractive "
NEW QUESTION # 34
You have a GitHub Enterprise subscription.
Your team is developing an Azure SQL dataset solution from a locally cloned GitHub repository by using Microsoft Visual Studio Code and GitHub Copilot Chat.
A mix of GitHub Copilot instructions is configured at different levels, including organization-wide, repository-wide, agent-specific, and personal.
Which instructions will take precedence over the others?
Answer: B
Explanation:
In a GitHub Enterprise environment, personal instructions (user-level) generally have the highest precedence for individual interactions in VS Code.
Order of Precedence
When GitHub Copilot processes instructions, it follows a "specific-to-general" hierarchy. The most specific context (the individual user) typically overrides broader organizational settings.
1. Personal Instructions
Set via .github/copilot-instructions.md in your local home directory or VS Code settings.
Overrides all other layers for your specific session.
2. Agent-Specific / Extension Instructions
Specific instructions provided to a custom agent (like @workspace or a custom Chat participant).
3. Repository-wide Instructions
Stored in the .github/copilot-instructions.md file within the specific repository.
4. Organization-wide Policies
Set by Enterprise/Org admins. These usually act as "guardrails" (e.g., blocking suggestions) rather than stylistic instructions.
Reference:
https://aiddbot.com/vscode-and-github-copilot
NEW QUESTION # 35
......
As is known to all, before purchasing the DP-800 Study Guide, we need to know the features of it. We offer you free demo to have a try, so that you can know the characteristics of DP-800 exam dumps. Beside we have three versions, each version have its own advantages, and they can meet all of your demands. And we have free update for 365 days after buying, the latest version will send to you email box automatically.
DP-800 Valid Test Sims: https://www.passleadervce.com/Microsoft-Certified-SQL-AI-Developer/reliable-DP-800-exam-learning-guide.html
What's more, part of that PassLeaderVCE DP-800 dumps now are free: https://drive.google.com/open?id=14P4GykHeay2IYEOD-6SYLOwpaq7ijE5R