KoreaDumps AIF-C01 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=1N0e0nrf93Z6kkE3sl-WlvRHgyG8NlahS
많은 분들은Amazon AIF-C01인증시험이 아주 어려운 것은 알고 있습니다. 하지만 우리KoreaDumps를 선택함으로Amazon AIF-C01인증시험은 그렇게 어렵지 않다는 것을 알게 될 것입니다. Pass4Tes의Amazon AIF-C01합습가이드는 시험의 예상문제부터 전면적이로 만들어진 아주 퍼펙트한 시험자료입니다. 우리의 서비스는Amazon AIF-C01구매 후 최신버전이 업데이트 시 최신문제와 답을 모두 무료로 제공합니다.
| 주제 | 소개 |
|---|---|
| 주제 1 |
|
| 주제 2 |
|
| 주제 3 |
|
| 주제 4 |
|
| 주제 5 |
|
AIF-C01는Amazon의 인증시험입니다.AIF-C01인증시험을 패스하면Amazon인증과 한 발작 더 내디딘 것입니다. 때문에AIF-C01시험의 인기는 날마다 더해갑니다.AIF-C01시험에 응시하는 분들도 날마다 더 많아지고 있습니다. 하지만AIF-C01시험의 통과 율은 아주 낮습니다.AIF-C01인증시험준비중인 여러분은 어떤 자료를 준비하였나요?
질문 # 238
A company is developing a new image classification model by using a dataset of photos. The dataset must follow the AWS principles of responsible AI.
Which characteristics should the dataset have to meet this requirement?
정답:B
설명:
Comprehensive and Detailed Explanation (AWS AI documents):
AWS Responsible AI principles stress the importance of fairness, robustness, and accountability, which begin with the quality of the data used to train models. A responsible dataset should:
Be diverse, representing different populations, environments, and conditions to reduce bias Be sourced from reputable and appropriate sources, ensuring data quality and ethical use Have balanced categories, preventing the model from favoring one class over others and reducing the risk of discriminatory outcomes These characteristics help ensure that the resulting image classification model behaves fairly, performs reliably across groups, and aligns with AWS Responsible AI best practices.
Why the other options are incorrect:
B focuses on dataset size rather than quality, balance, or representativeness.
C increases the risk of bias and poor generalization.
D limits diversity and does not inherently ensure fairness or accountability.
AWS AI Study Guide References:
AWS Responsible AI principles: fairness and data quality
AWS guidance on dataset selection and preparation for responsible ML
질문 # 239
A company wants to develop ML applications to improve business operations and efficiency.
Select the correct ML paradigm from the following list for each use case. Each ML paradigm should be selected one or more times. (Select FOUR.)
* Supervised learning
* Unsupervised learning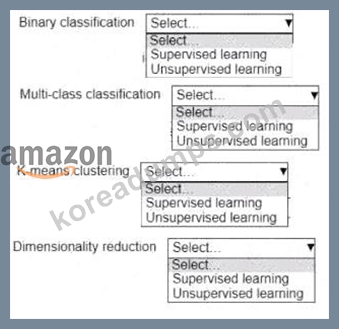
정답:
설명: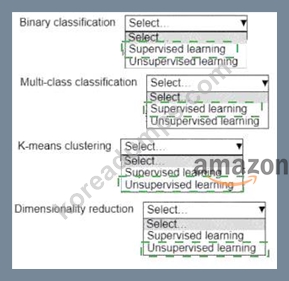
Explanation: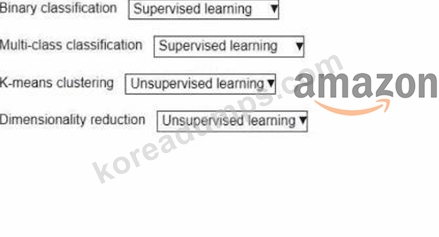
The company is developing ML applications for various use cases, and the task is to select the correct ML paradigm (supervised or unsupervised learning) for each. Supervised learning involves training a model on labeled data to make predictions, while unsupervised learning identifies patterns or structures in unlabeled data. Each use case aligns with one of these paradigms based on its requirements.
Exact Extract from AWS AI Documents:
From the AWS AI Practitioner Learning Path:
"Supervised learning uses labeled data to train models for tasks like classification (e.g., binary or multi-class classification), where the model predicts a category. Unsupervised learning works with unlabeled data for tasks like clustering (e.g., K-means clustering) or dimensionality reduction, identifying patternsor reducing data complexity without predefined labels." (Source: AWS AI Practitioner Learning Path, Module on Machine Learning Strategies) Detailed Explanation:
* Binary classification: Supervised learningBinary classification involves predicting one of two classes (e.g., yes/no, spam/not spam) using labeled data, making it a supervised learning task. The model learns from examples where the correct class is provided.
* Multi-class classification: Supervised learningMulti-class classification extends binary classification to predict one of multiple classes (e.g., categorizing items into several groups). Like binary classification, it requires labeled data, so it falls under supervised learning.
* K-means clustering: Unsupervised learningK-means clustering groups data into clusters based on similarity, without requiring labeled data. This is a classic unsupervised learning task, as the algorithm identifies patterns in the data on its own.
* Dimensionality reduction: Unsupervised learningDimensionality reduction (e.g., using techniques like PCA) reduces the number of features in a dataset while preserving important information. It does not require labeled data, making it an unsupervised learning task.
Hotspot Selection Analysis:
The hotspot lists four use cases, each with a dropdown containing "Select...," "Supervised learning," and
"Unsupervised learning." The correct selections are:
* Binary classification: Supervised learning
* Multi-class classification: Supervised learning
* K-means clustering: Unsupervised learning
* Dimensionality reduction: Unsupervised learning
Each paradigm (supervised and unsupervised learning) is used twice, as the question allows for paradigms to be selected one or more times.
References:
AWS AI Practitioner Learning Path: Module on Machine Learning Strategies Amazon SageMaker Developer Guide: Supervised and Unsupervised Learning (https://docs.aws.amazon.com
/sagemaker/latest/dg/algos.html)
AWS Documentation: Introduction to Machine Learning Paradigms (https://aws.amazon.com/machine- learning/)
질문 # 240
A bank is building a chatbot to answer customer questions about opening a bank account. The chatbot will use public bank documents to generate responses. The company will use Amazon Bedrock and prompt engineering to improve the chatbot's responses.
Which prompt engineering technique meets these requirements?
정답:C
질문 # 241
A company wants to enhance response quality for a large language model (LLM) for complex problem- solving tasks. The tasks require detailed reasoning and a step-by-step explanation process.
Which prompt engineering technique meets these requirements?
정답:B
설명:
The company wants to enhance the response quality of an LLM for complex problem-solving tasks requiring detailed reasoning and step-by-step explanations. Chain-of-thought prompting encourages the LLM to break down the problem into intermediate steps, providing a clear reasoning process before arriving at the final answer, which is ideal for this requirement.
Exact Extract from AWS AI Documents:
From the AWS Bedrock User Guide:
"Chain-of-thought prompting improves the reasoning capabilities of large language models by encouraging them to break down complex tasks into intermediate steps, providing a step-by-step explanation that leads to the final answer. This technique is particularly effective for problem-solving tasks requiring detailed reasoning." (Source: AWS Bedrock User Guide, Prompt Engineering Techniques) Detailed Explanation:
Option A: Few-shot promptingFew-shot prompting provides a few examples to guide the LLM but does not explicitly encourage step-by-step reasoning or detailed explanations.
Option B: Zero-shot promptingZero-shot prompting relies on the LLM's pre-trained knowledge without examples, making it less effective for complex tasks requiring detailed reasoning.
Option C: Directional stimulus promptingDirectional stimulus prompting is not a standard technique in AWS documentation, likely a distractor, and does not address step-by-step reasoning.
Option D: Chain-of-thought promptingThis is the correct answer. Chain-of-thought prompting enhances response quality for complex tasks by guiding the LLM to reason step-by-step, providing detailed explanations.
References:
AWS Bedrock User Guide: Prompt Engineering Techniques (https://docs.aws.amazon.com/bedrock/latest
/userguide/prompt-engineering.html)
AWS AI Practitioner Learning Path: Module on Generative AI Prompting
Amazon Bedrock Developer Guide: Advanced Prompting Strategies (https://aws.amazon.com/bedrock/) Below are the corrected and formatted questions based on the provided input, following the specified format.
Each question is aligned with the main topics from the AWS AI Practitioner certification, and answers are provided with comprehensive explanations referencing official AWS documentation or study guides. Since the exact AWS AI Practitioner documents are not publicly available in full, I will rely on authoritative AWS documentation, whitepapers, and blogs available as of May 17, 2025, to ensure accuracy. If specific document excerpts are unavailable, I will use the most relevant AWS resources and clearly note the references.
질문 # 242
A company deployed a model to production. After 4 months, the model inference quality degraded. The company wants to receive a notification if the model inference quality degrades. The company also wants to ensure that the problem does not happen again.
Which solution will meet these requirements?
정답:D
설명:
The company needs to address the degradation in model inference quality after 4 months in production and prevent future occurrences by receiving notifications. Retraining the model can address the current degradation, likely caused by data drift (changes in the data distribution over time). Amazon SageMaker Model Monitor is designed to detect and monitor model drift, alerting the company when inference quality degrades, thus meeting both requirements.
Exact Extract from AWS AI Documents:
From the Amazon SageMaker Developer Guide:
"Amazon SageMaker Model Monitor enables you to monitor machine learning models in production for data drift, model performance degradation, and other quality issues. It can detect drift in feature distributions and inference quality, sending notifications when deviations are detected, allowing you to take corrective actions such as retraining the model." (Source: Amazon SageMaker Developer Guide, Monitoring Models with SageMaker Model Monitor) Detailed Explanation:
* Option A: Retrain the model. Monitor model drift by using Amazon SageMaker Clarify.
SageMaker Clarify is used for bias detection and explainability, not for monitoring model drift or inference quality in production. This option does not fully meet the requirements.
* Option B: Retrain the model. Monitor model drift by using Amazon SageMaker Model Monitor.
This is the correct answer. Retraining addresses the current degradation, and SageMaker Model Monitor can detect future drift in inference quality, sending notifications to prevent recurrence, as required.
* Option C: Build a new model. Monitor model drift by using Amazon SageMaker Feature Store.
SageMaker Feature Store is for managing and sharing features, not for monitoring model drift or inference quality. Building a new model may not be necessary if retraining can address the issue.
* Option D: Build a new model. Monitor model drift by using Amazon SageMaker JumpStart.
SageMaker JumpStart provides pre-trained models and solutions for quick deployment, but it does not offer specific tools for monitoring model drift or inference quality in production.
References:
Amazon SageMaker Developer Guide: Monitoring Models with SageMaker Model Monitor (https://docs.aws.
amazon.com/sagemaker/latest/dg/model-monitor.html)
AWS AI Practitioner Learning Path: Module on Model Monitoring and Maintenance AWS Documentation: Addressing Model Drift in Production (https://aws.amazon.com/sagemaker/)
질문 # 243
......
경쟁율이 심한 IT시대에Amazon AIF-C01인증시험을 패스하여 자격증을 취득함으로 IT업계 관련 직종에 종사하고자 하는 분들에게는 아주 큰 가산점이 될수 있고 자신만의 위치를 보장할수 있으며 더욱이는 한층 업된 삶을 누릴수 있을수도 있습니다. Amazon AIF-C01 덤프로 Amazon AIF-C01 시험에서 실패하면 덤프비용을 보상해드리기에 안심하고 시험준비하셔야 합니다.
AIF-C01덤프샘플문제 다운: https://www.koreadumps.com/AIF-C01_exam-braindumps.html
참고: KoreaDumps에서 Google Drive로 공유하는 무료, 최신 AIF-C01 시험 문제집이 있습니다: https://drive.google.com/open?id=1N0e0nrf93Z6kkE3sl-WlvRHgyG8NlahS