You can absolutely assure about the high quality of our products, because the contents of Databricks-Certified-Professional-Data-Engineer training materials have not only been recognized by hundreds of industry experts, but also provides you with high-quality after-sales service. Before purchasing Databricks-Certified-Professional-Data-Engineer exam torrent, you can log in to our website for free download. During your installation, Databricks-Certified-Professional-Data-Engineer exam questions hired dedicated experts to provide you with free remote online guidance. During your studies, Databricks-Certified-Professional-Data-Engineer Exam Torrent also provides you with free online services for 24 hours, regardless of where and when you are, as long as an email, we will solve all the problems for you. At the same time, if you fail to pass the exam after you have purchased Databricks-Certified-Professional-Data-Engineer training materials, you just need to submit your transcript to our customer service staff and you will receive a full refund.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Processing with Spark | 25-30% | - Python and SQL for data engineering
|
| Topic 2: Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
| Topic 3: Data Ingestion | 15-20% | - Batch ingestion methods
|
| Topic 4: Delta Lake | 20-25% | - Delta Lake operations
|
| Topic 5: Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
>> Dumps Databricks-Certified-Professional-Data-Engineer Vce <<
Why do we need so many certifications? One thing has to admit, more and more certifications you own, it may bring you more opportunities to obtain a better job, earn more salary. This is the reason why we need to recognize the importance of getting the test Databricks-Certified-Professional-Data-Engineer certification. Our passing rate is 98%-100% and there is little possibility for you to fail in the exam. But if you are unfortunately to fail in the exam we will refund you in full immediately. Some people worry that if they buy our Databricks-Certified-Professional-Data-Engineer Exam Questions they may fail in the exam and the procedure of the refund is complicated.
NEW QUESTION # 155
A data engineer is configuring a Lakeflow Declarative Pipeline to process CDC (Change Data Capture) data from a source. The source events sometimes arrive out of order, and multiple updates may occur with the same update_timestamp but with different update_sequence_id.
What should the data engineer do to ensure events are sequenced correctly?
Answer: A
Explanation:
Comprehensive and Detailed Explanation from Databricks Documentation:
When handling CDC data, sequencing is critical because updates may arrive out of order or multiple changes may occur for the same record at the same timestamp. Databricks' AUTO CDC APIs provide built-in constructs to handle ordering logic.
The correct mechanism is to use the SEQUENCE BY clause in the CDC configuration. Specifically, when both update_timestamp and update_sequence_id exist, the recommended approach is:
SEQUENCE BY STRUCT(event_timestamp, update_sequence_id)
This ensures that within the same record key, the engine applies updates in the exact sequence they occurred, resolving conflicts where multiple updates share the same timestamp but differ in sequence ID.
Option A (track_history_column_list) is used for historical tracking and auditing changes, not for sequencing logic. It ensures lineage but does not enforce correct event order.
Option B (dropDuplicates()) only removes exact duplicates; it cannot guarantee sequencing correctness when multiple updates exist.
Option C is correct: SEQUENCE BY STRUCT(event_timestamp, update_sequence_id) explicitly enforces ordering, as recommended by the CDC pipeline guidelines.
Option D (window function) would be a manual approach in Spark Structured Streaming, but Lakeflow Declarative Pipelines already provide native CDC sequencing support, making this unnecessary.
Thus, the best practice per Databricks CDC documentation is to use Option C with SEQUENCE BY STRUCT.
NEW QUESTION # 156
Which is a key benefit of an end-to-end test?
Answer: D
Explanation:
End-to-end testing is a methodology used to test whether the flow of an application, from start to finish, behaves as expected. The key benefit of an end-to-end test is that it closely simulates real-world, user behavior, ensuring that the system as a whole operates correctly.
Reference:
Software Testing: End-to-End Testing
NEW QUESTION # 157
A data engineer is configuring a Databricks Asset Bundle to deploy a job with granular permissions. The requirements are:
* Grant the data-engineers group CAN_MANAGE access to the job.
* Ensure the auditors group can view the job but not modify or run it.
* Avoid granting unintended permissions to other users or groups.
How should the data engineer deploy the job while meeting the requirements?
Answer: B
Explanation:
Databricks documents that resource-specific permissions for bundle resources can be defined under the resource itself, such as resources.jobs. < job > .permissions , using group_name and level . The documented syntax supports CAN_VIEW , CAN_MANAGE , and related permission levels, which matches option B. ( Databricks Documentation ) Option C is invalid because it repeats the permissions key incorrectly. Option D applies top-level permissions more broadly across bundle resources instead of scoping them specifically to the job, which does not best satisfy the "avoid unintended permissions" requirement. Option B is therefore the correct and properly scoped configuration. ( Databricks Documentation )
======
NEW QUESTION # 158
A data architect has designed a system in which two Structured Streaming jobs will concurrently write to a single bronze Delta table. Each job is subscribing to a different topic from an Apache Kafka source, but they will write data with the same schem a. To keep the directory structure simple, a data engineer has decided to nest a checkpoint directory to be shared by both streams.
The proposed directory structure is displayed below: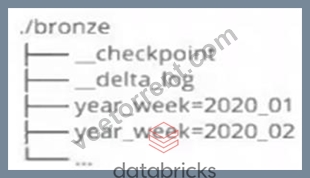
Which statement describes whether this checkpoint directory structure is valid for the given scenario and why?
Answer: D
Explanation:
This is the correct answer because checkpointing is a critical feature of Structured Streaming that provides fault tolerance and recovery in case of failures. Checkpointing stores the current state and progress of a streaming query in a reliable storage system, such as DBFS or S3. Each streaming query must have its own checkpoint directory that is unique and exclusive to that query. If two streaming queries share the same checkpoint directory, they will interfere with each other and cause unexpected errors or data loss. Verified Reference: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under "Checkpointing" section.
NEW QUESTION # 159
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings.
The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream for highly selective joins on a number of fields, and will also be leveraged by the machine learning team to filter on a handful of relevant fields, in total, 15 fields have been identified that will often be used for filter and join logic.
The data engineer is trying to determine the best approach for dealing with these nested fields before declaring the table schema.
Which of the following accurately presents information about Delta Lake and Databricks that may Impact their decision-making process?
Answer: B
Explanation:
Delta Lake, built on top of Parquet, enhances query performance through data skipping, which is based on the statistics collected for each file in a table. For tables with a large number of columns, Delta Lake by default collects and stores statistics only for the first 32 columns. Thesestatistics include min/max values and null counts, which are used to optimize query execution by skipping irrelevant data files. When dealing with highly nested JSON structures, understanding this behavior is crucial for schema design, especially when determining which fields should be flattened or prioritized in the table structure to leverage data skipping efficiently for performance optimization.References: Databricks documentation on Delta Lake optimization techniques, including data skipping and statistics collection (https://docs.databricks.com/delta/optimizations
/index.html).
NEW QUESTION # 160
......
The VCETorrent is a leading platform that is committed to making the Databricks Databricks-Certified-Professional-Data-Engineer exam dumps preparation simple, quick, and successful. To achieve this objective VCETorrent is offering real, valid, and updated Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) practice questions in three different formats. These formats are VCETorrent Databricks Databricks-Certified-Professional-Data-Engineer PDF Dumps Files, desktop practice test software, and web-based practice test software. All these VCETorrent Databricks exam questions formats are easy to use and compatible with all web browsers, operating systems, and devices.
Pass Databricks-Certified-Professional-Data-Engineer Exam: https://www.vcetorrent.com/Databricks-Certified-Professional-Data-Engineer-valid-vce-torrent.html