Our HP HPE7-J01 exam dumps PDF can help you prepare casually and pass exam easily. If you make the best use of your time and obtain a useful certification you may get a senior position ahead of others. Chance favors the prepared mind. TestPassKing provide the best HP HPE7-J01 Exam Dumps Pdf materials in this field which is helpful for you.
| Section | Objectives |
|---|---|
| Hybrid Cloud and Data Mobility | - Data migration and mobility strategies - Hybrid cloud storage integration |
| HPE Storage Architecture Overview | - Enterprise storage fundamentals and architectures - HPE storage portfolio positioning |
| Storage Security and Best Practices | - Secure storage architecture design - Data encryption and access control |
| Data Protection and Availability | - Backup, replication, and disaster recovery concepts - High availability design considerations |
| Performance and Capacity Planning | - Workload analysis and sizing - Performance optimization techniques |
| HPE Storage Platforms and Solutions | - Legacy HPE 3PAR architecture concepts - HPE Alletra storage systems - HPE Primera and Nimble storage solutions |
| SAN and NAS Technologies | - NAS protocols and file services - Fibre Channel and iSCSI fundamentals |
>> Valid Exam HPE7-J01 Registration <<
Perhaps you are in a bad condition and need help to solve all the troubles. Don’t worry, once you realize economic freedom, nothing can disturb your life. Our HPE7-J01 exam questions can help you out. Learning is the best way to make money. So you need to learn our HPE7-J01 guide materials carefully after you have paid for them. And in fact, our HPE7-J01 Practice Braindumps are quite interesting and enjoyable for our professionals have compiled them carefully with the latest information and also designed them to different versions to your needs.
NEW QUESTION # 10
A customer currently has an HPE Alletra 9000 with data reduction on all volumes and plans to migrate to an HPE Alletra MP B10000. Which formula should be used to size the new solution?
Answer: D
Explanation:
When sizing a migration from a highly efficient array like the HPE Alletra 9000 (or Primera) to the next- generation HPE Alletra MP B10000, storage architects must account for the difference between the "Written Capacity" (what the host thinks it has stored) and the "Consumed Capacity" (the physical space used after data reduction).
The standard best practice for an HPE Master ASE when performing these migrations is to Size to consumption multiplied by 1.25. This "1.25 factor" (representing a 25% overhead) is the recommended safety margin used in sizing tools like HPE NinjaStars and the HPE Cloud Physics assessment reports.
This 25% buffer is designed to cover several critical architectural requirements:
* System Metadata and Overhead: Both the Alletra 9000 and Alletra MP require physical capacity to store internal metadata, map tables, and the structures required for their respective data reduction engines.
* Snapshot Reserve: While snapshots are thin and pointer-based, they still consume physical space as data changes over time. The 1.25 multiplier ensures there is enough "headroom" for typical snapshot retention policies.
* Data Reduction Parity: Data reduction ratios (deduplication and compression) can fluctuate based on the specific workload. Sizing exactly to current consumption without a buffer risks an out-of-space condition if the new array's reduction engine handles a specific block pattern slightly differently during the initial ingest.
* Operational Performance: SSD-based arrays perform best when they are not "packed" to 100% capacity, as the garbage collection and wear-leveling processes require free blocks to operate efficiently.
Sizing to "original capacity" (Option D) would lead to a massive over-provisioning and wasted cost, as it ignores the benefits of modern data reduction. Option C (1.5) is generally considered overly conservative for modern flash environments, while 1.25 provides the optimal balance of cost-efficiency and technical risk mitigation.
NEW QUESTION # 11
Drag and Drop Question
Match the fibre channel topology to its use case. Each answer will be used once.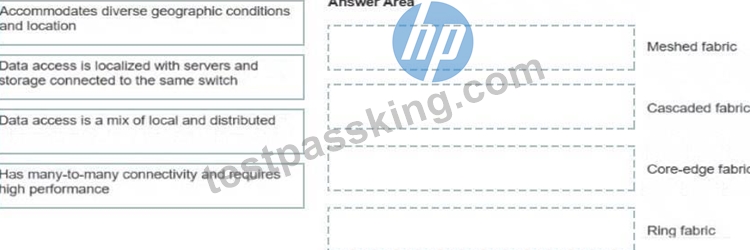
Answer:
Explanation: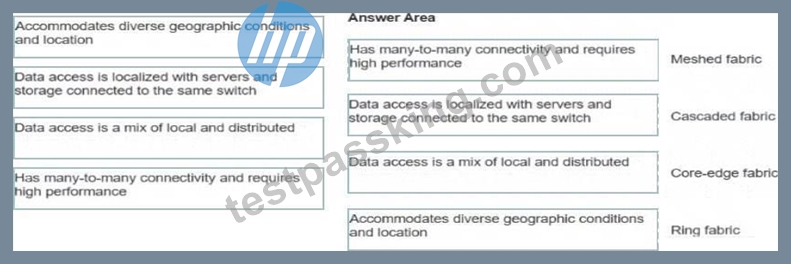
NEW QUESTION # 12
Which statement is correct concerning the hardware configuration of the HPE Alletra 5000 storage arrays?
Answer: A
Explanation:
The HPE Alletra 5000 is a hybrid storage array family built on the legacy of the HPE Nimble Storage Adaptive Flash architecture. Its hardware design is optimized for a mixture of high- capacity Hard Disk Drives (HDDs) and high-performance Solid State Drives (SSDs) used for caching (CASL architecture). The chassis is a 4U enclosure featuring 24 drive slots. To maintain consistent performance and thermal profiles, the architecture designates specific slots for different media types. According to the HPE Alletra 5000 Installation and Service Guide, the SSDs used for cache are housed in Dual Flash Carriers (DFC). Each DFC can hold either one or two SSDs, allowing for a total of 3 or 6 cache drives per shelf. These DFCs are specifically required to be installed in the last three slots of the array, which are slots 22, 23, and 24.
The remaining 21 slots (slots 1 through 21) are populated with Large Form Factor (LFF) HDDs for the primary capacity tier.
NEW QUESTION # 13
A customer wants to implement an HPE Morpheus life-cycle management solution at a single site with 1004 VMs using a redundant architecture and distributed services. Which statement is correct regarding the setup and operation of this solution?
Answer: C
Explanation:
When designing an HPE Morpheus environment for an enterprise-scale workload (such as 1,000+ VMs), a standalone "all-in-one" installation is insufficient for high availability (HA) and performance requirements.
Instead, a 3-node Distributed Architecture must be implemented to ensure redundancy across all critical service layers.
In a distributed, redundant Morpheus setup, the architecture is broken down into three primary tiers: the Application tier, the Database tier (MySQL/Percona), and the Messaging/Search tier (Elasticsearch and RabbitMQ). To achieve a basic redundant footprint, you require at least two Morpheus application nodes, three database nodes (for quorum), and a messaging cluster. According to the HPE Morpheus Architecture and Sizing Guide, a standard HA deployment starts with a minimum of six VMs to separate these functions.
However, for a production environment of this size, it is recommended to have a minimum of 10 VMs. This expanded footprint typically includes 3 App nodes, 3 Database nodes, and a 3-node cluster for Elasticsearch
/RabbitMQ, plus a dedicated load balancer or management node, ensuring that the loss of any single host does not impact the management plane's availability.
Option C is incorrect because a distributed installation is significantly more complex than the "all-in-one" appliance approach and requires manual configuration of externalized services. Option B is slightly inaccurate because while RabbitMQ itself is required, a dedicated "RabbitMQ load balancer" is often handled by the primary application load balancer (like an F5 or NetScaler) rather than being a specific required installation component. Option D is incorrect as upgrades in a distributed environment involve a coordinated, multi-step process across all nodes, which typically requires a scheduled maintenance window rather than "minimal" downtime.
NEW QUESTION # 14
What will occur when a new node is added to an existing HPE Alletra MP X10000 storage array?
Answer: A
Explanation:
The HPE Alletra MP X10000 is an object and file storage solution utilizing a Disaggregated Shared- Everything (DASE) architecture. A key differentiator of this disaggregated design is the stateless nature of the controller nodes and the centralized management of the data plane. When a cluster expansion occurs--such as adding a new controller node or an additional JBOF (Just a Bunch of Flash) storage shelf--the system is designed to automatically optimize the workload distribution. According to the HPE Alletra MP Architectural Guide, adding an additional JBOF or drives triggers an automatic rebalancing of the data stripes. Unlike older architectures where manual rebalancing services were required (such as in the 3PAR/B10000 block lineage), the X10000 uses a sophisticated hashing mechanism.
Specifically, data is distributed across DSPs (Data Storage Processors) which are virtualized management units. Upon the addition of hardware, these DSPs are rebalanced across the available compute and storage resources in a matter of seconds. Because the nodes are stateless and state is persisted only within the JBOFs, this rebalancing happens with minimal performance impact and no need for the massive "data movement" traditionally associated with expanding a RAID group. This ensures that as a customer scales from the minimum of 3 nodes up to 8 or more, the system always maintains an optimal load balance and utilizes all available flash bandwidth and compute cycles in parallel.
NEW QUESTION # 15
......
TestPassKing delivers up to date HPE7-J01 exam products and modify them time to time. Latest HPE7-J01 exam questions are assembled in our practice test modernizes your way of learning and replaces the burdensome preparation techniques with flexible learning. We accord you an actual exam environment simulated through our practice test sessions that proves beneficial for HPE7-J01 Exams preparation. Our HPE7-J01 practice tests provide you knowledge and confidence simultaneously. Candidates who run across the extensive search, TestPassKing products are the remedy for their worries. Once you have chosen for our HPE7-J01 practice test products, no more resources are required for exam preparation.
Valid Test HPE7-J01 Tutorial: https://www.testpassking.com/HPE7-J01-exam-testking-pass.html