BONUS!!! Download part of Exam4Free DP-800 dumps for free: https://drive.google.com/open?id=12dtd8isejkjbhrUh3l3VQPngaNoGJXnR
Exam4Free is a legal authorized company offering the best Microsoft DP-800 test preparation materials. So for some candidates who are not confident for real tests or who have no enough to time to prepare I advise you that purchasing valid and Latest DP-800 Test Preparation materials will make you half the efforts double the results. Our products help thousands of people pass exams and can help you half the work with double the results.
| Section | Weight | Objectives |
|---|---|---|
| Design and develop database solutions | 35-40% | - Design database solutions
|
| Implement AI capabilities in database solutions | 25-30% | - Build intelligent search and retrieval
|
| Secure, optimize, and deploy database solutions | 35-40% | - Secure database solutions
|
The latest DP-800 dumps pdf covers every topic of the certification exam and contains the latest test questions and answers. By practicing our DP-800 vce pdf, you can test your skills and knowledge for the test and make well preparation for the formal exam. One-year free updating will ensure you get the Latest DP-800 Study Materials first time and the accuracy of our DP-800 exam questions guarantee the high passing score.
NEW QUESTION # 58
You have a SQL database in Microsoft Fabric named Sales BD that contains a table named dbo.Products. You need to modify SalesBD to meet the following requirements:
* Create a vector index on the appropriate column.
* Use a supplied natural language query vector.
How should you complete the Transact-SQL code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.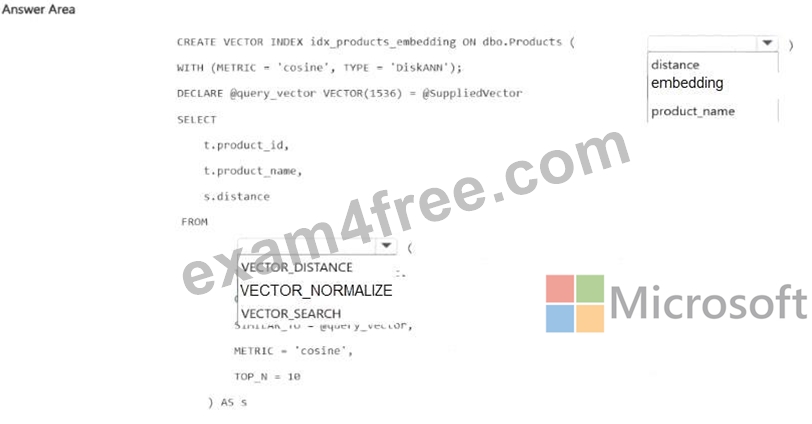
Answer:
Explanation: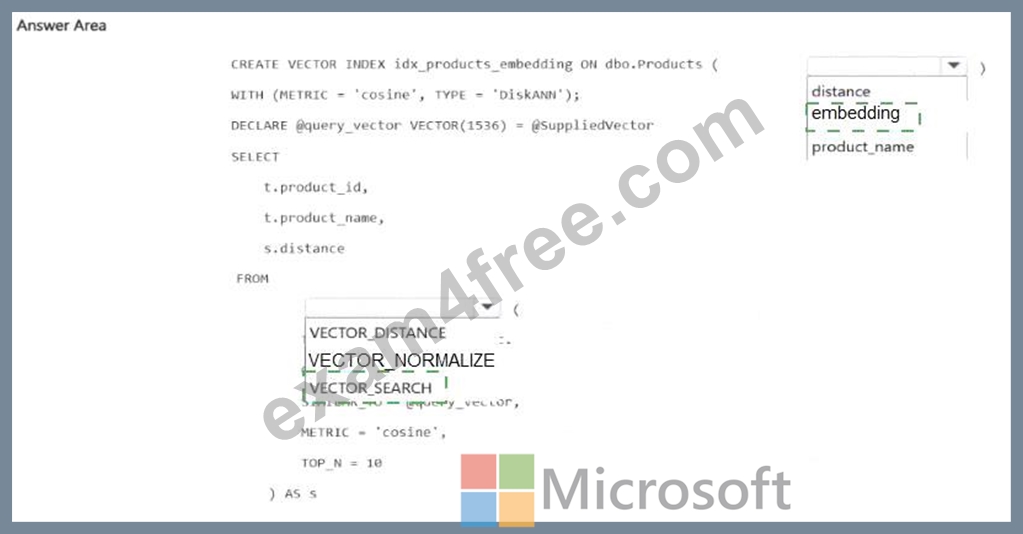
Explanation: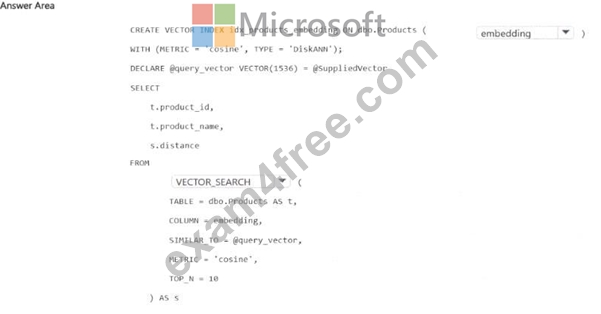
The first correct selection is embedding because a vector index must be created on the vector column , not on a scalar distance column or a text column such as product_name. Microsoft's CREATE VECTOR INDEX documentation shows that the index is created directly on the vector-valued column, for example ON product_embeddings(embedding).
The second correct selection is VECTOR_SEARCH because the requirement is to use a supplied natural language query vector and search against the indexed embeddings. Microsoft documents that VECTOR_SEARCH is the Transact-SQL function for approximate nearest neighbor vector retrieval and that it applies to SQL database in Microsoft Fabric as well as other supported SQL platforms.
This also matches the shown code pattern:
* declare a vector variable such as @query_vector VECTOR(1536),
* create a vector index on dbo.Products(embedding),
* query with VECTOR_SEARCH(... SIMILAR_TO = @query_vector, METRIC = ' cosine ' , TOP_N =
10).
NEW QUESTION # 59
Your development team uses Microsoft Visual Studio Code with the MSSQL extension and the GitHub Copilot Chat extension.
The team connects to an Azure SQL database by using individual database logins and uses the
@mssql chat participant to generate and run Transact-SQL queries from prompts.
What is used to ensure that GitHub Copilot Chat-generated queries run in the context of the developer?
Answer: B
Explanation:
To ensure that GitHub Copilot Chat-generated queries run in the context of a specific developer when using the @mssql chat participant, SQL Permissions must be used.
Why SQL Permissions are the Key
When the @mssql extension executes a query generated by Copilot, it uses the active connection currently established in VS Code. Because your team uses individual database logins, the execution context is governed by the following:
Authentication: The developer logs in with their specific credentials.
Authorization: The SQL Server engine checks the SQL Permissions (GRANT/DENY/REVOKE) assigned to that specific database user.
Execution: Any T-SQL command sent by the Copilot chat participant is limited by what that specific login is allowed to do (e.g., SELECT, UPDATE, or DROP).
Reference:
https://learn.microsoft.com/en-us/sql/tools/visual-studio-code-extensions/github-copilot/limitations- and-known-issues
NEW QUESTION # 60
You have a GitHub Enterprise subscription.
Your team is developing an Azure SQL dataset solution from a locally cloned GitHub repository by using Microsoft Visual Studio Code and GitHub Copilot Chat.
A mix of GitHub Copilot instructions is configured at different levels, including organization-wide, repository-wide, agent-specific, and personal.
Which instructions will take precedence over the others?
Answer: C
Explanation:
In a GitHub Enterprise environment, personal instructions (user-level) generally have the highest precedence for individual interactions in VS Code.
Order of Precedence
When GitHub Copilot processes instructions, it follows a "specific-to-general" hierarchy. The most specific context (the individual user) typically overrides broader organizational settings.
1. Personal Instructions
Set via .github/copilot-instructions.md in your local home directory or VS Code settings.
Overrides all other layers for your specific session.
2. Agent-Specific / Extension Instructions
Specific instructions provided to a custom agent (like @workspace or a custom Chat participant).
3. Repository-wide Instructions
Stored in the .github/copilot-instructions.md file within the specific repository.
4. Organization-wide Policies
Set by Enterprise/Org admins. These usually act as "guardrails" (e.g., blocking suggestions) rather than stylistic instructions.
Reference:
https://aiddbot.com/vscode-and-github-copilot
NEW QUESTION # 61
Vou have a SQL database in Microsoft Fabric that contains a nvarchar(max) column named MessageText. An ID is always contained within the first paragraph of MessageText.
You need to write a Transact SQL query that uses REGEXP_SUBSTR to extract the ID from MessageText.
What should you include in the query?
Answer: D
Explanation:
Microsoft documents REGEXP_SUBSTR for Transact-SQL with the string_expression parameter as supporting character string types char, nchar, varchar, and nvarchar. For the regex functions, support for LOB types such as varchar(max) and nvarchar(max) is specifically called out for REGEXP_LIKE , REGEXP_COUNT , and REGEXP_INSTR up to 2 MB, but that support note is not listed for REGEXP_SUBSTR in the surfaced documentation. In exam terms, the safe and expected approach is to cast the nvarchar(max) column to nvarchar(4000) before calling REGEXP_SUBSTR.
This also fits the scenario detail that the ID is always contained within the first paragraph of MessageText.
Since the needed value is near the start of the text, narrowing the input to a non-LOB string type such as nvarchar(4000) is sufficient and avoids incompatibility concerns with nvarchar(max).
The other options are not appropriate:
* A STRING_ESCAPE(..., ' json ' ) is for JSON escaping, not regex extraction.
* C adding a case-sensitive collation changes comparison behavior, but it is not the required fix for REGEXP_SUBSTR on nvarchar(max).
* D TRY_CONVERT(varchar(max), ...) still leaves a MAX type and also risks unnecessary Unicode loss.
NEW QUESTION # 62
You have an Azure SQL database that contains a table named stores, stores contains a column named description and a vector column named embedding.
You need to implement a hybrid search query that meets the following requirements:
* Uses full-text search on description for the keyword portion
* Returns the top 20 results based on a combined score that uses a weighted formula of 60% vector distance and 40% full-text rank How should you configure the query components? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.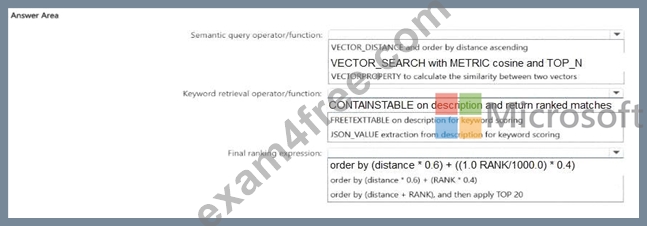
Answer:
Explanation: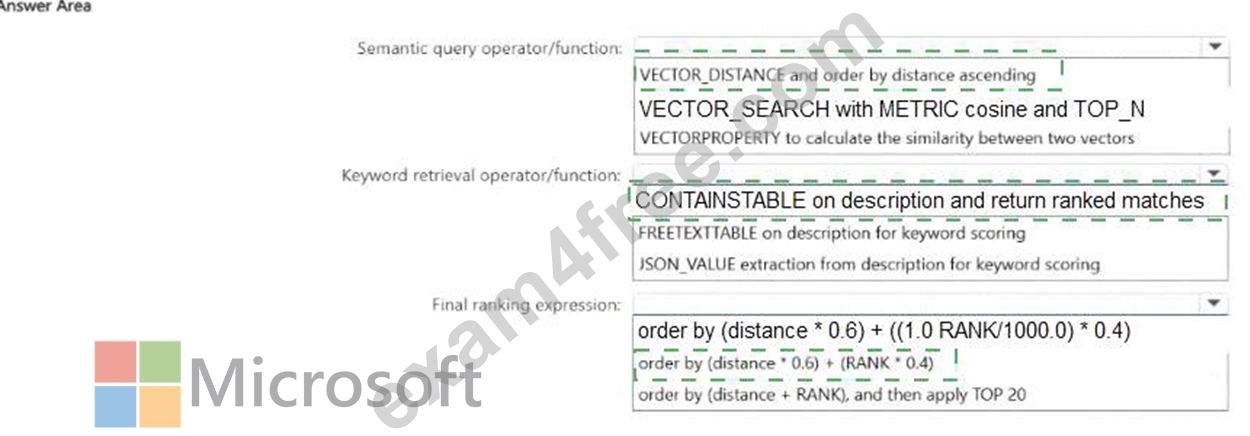
Explanation: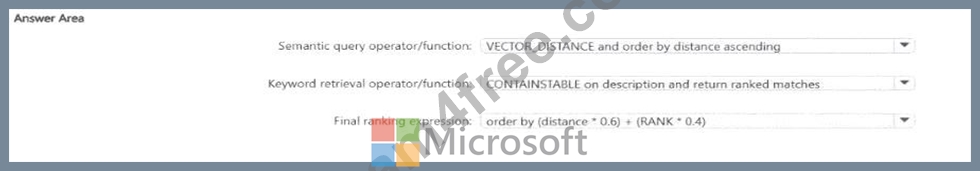
For the vector portion, the correct choice is VECTOR_DISTANCE and order by distance ascending . The requirement is to build a combined weighted formula using the actual vector distance. Microsoft documents that VECTOR_DISTANCE returns the exact distance between two vectors. Since lower distance means greater similarity, ascending distance is the right direction for ranking. VECTOR_SEARCH is for ANN retrieval, but this hotspot specifically asks for a weighted formula based on distance , so VECTOR_DISTANCE is the appropriate operator.
For the keyword portion, the correct choice is CONTAINSTABLE on description and return ranked matches . Microsoft documents that CONTAINSTABLE returns a RANK column from 0 through 1000 , which is exactly what is needed for weighted scoring in a hybrid formula.
For the final ranking expression, the best choice is order by (distance * 0.6) + ((1.0 - RANK/1000.0) * 0.4) .
This works because vector distance is a lower-is-better metric, while full-text RANK is a higher-is-better metric. Dividing RANK by 1000 normalizes it to the documented range, and subtracting from 1.0 converts it into a lower-is-better term so both components can be combined consistently in one ascending score. This final step is a sound inference based on Microsoft's documented distance semantics and full-text rank range.
NEW QUESTION # 63
......
All people dream to become social elite. However, less people can take the initiative. If you spend less time on playing computer games and spend more time on improving yourself, you are bound to escape from poverty. Maybe our DP-800 real dump could give your some help. Our company concentrates on relieving your pressure of preparing the DP-800 Exam. Getting the certificate equals to embrace a promising future and good career development. Perhaps you have heard about our DP-800 exam question from your friends or news. Why not has a brave attempt? You will certainly benefit from your wise choice.
New DP-800 Test Answers: https://www.exam4free.com/DP-800-valid-dumps.html
What's more, part of that Exam4Free DP-800 dumps now are free: https://drive.google.com/open?id=12dtd8isejkjbhrUh3l3VQPngaNoGJXnR