DOWNLOAD the newest Lead2Passed Mule-Arch-201 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1_mu9kYMfH-rdffK1LKYYDvYaed-SOpVN
We often ask, what is the purpose of learning? Why should we study? Why did you study for Mule-Arch-201exam so long? As many people think that, even if one day we forget the formula for the area of a triangle, we can still live very well, but if it were not for the knowledge of learning Mule-Arch-201 Exam and try to obtain certification, how can we have the opportunity to good to future life? So, the examination is necessary, only to get the test Mule-Arch-201 certification, get a certificate, to prove better us, to pave the way for our future life.
| Section | Objectives |
|---|---|
| Anypoint Platform Architecture | - Runtime Fabric architecture overview - Anypoint Platform components and capabilities - Deployment models (CloudHub, hybrid, on-premises) |
| API Management and Governance | - API lifecycle management - Governance frameworks and best practices - API security policies and enforcement |
| Performance and Scalability | - Scaling Mule applications - High availability design patterns |
| Integration Architecture Strategy | - Designing enterprise integration architecture - System, process, and experience APIs - API-led connectivity principles |
| Security and Compliance | - Secure API exposure and threat protection - Authentication and authorization mechanisms |
| Data Integration and Transformation | - Batch vs real-time integration patterns - Data mapping and transformation strategies |
>> Detailed Mule-Arch-201 Study Dumps <<
Mule-Arch-201 certification can help you prove your strength and increase social competitiveness. Although it is not an easy thing for somebody to pass the exam, but our Mule-Arch-201 exam torrent can help aggressive people to achieve their goals. This is the reason why we need to recognize the importance of getting the test Mule-Arch-201 Certification. More qualified certification for our future employment has the effect to be reckoned with, only to have enough qualification certifications to prove their ability, can we win over rivals in the social competition.
NEW QUESTION # 72
What Mule application deployment scenario requires using Anypoint Platform Private Cloud Edition or Anypoint Platform for Pivotal Cloud Foundry?
Answer: D
Explanation:
Correct Answe r: When regulatory requirements mandate on-premises processing of EVERY data item, including meta-data.
*****************************************
We need NOT require to use Anypoint Platform PCE or PCF for the below. So these options are OUT.
>> We can make ALL applications highly available across multiple data centers using CloudHub too.
>> We can use Anypoint VPN and tunneling from CloudHub to connect to ALL backend systems in the application network that are deployed in the organization's intranet.
>> We can use Anypoint VPC and Firewall Rules to make ALL APIs private and NOT exposed to the public cloud.
Only valid reason in the given options that requires to use Anypoint Platform PCE/ PCF is - When regulatory requirements mandate on-premises processing of EVERY data item, including meta-data.
NEW QUESTION # 73
Refer to the exhibit.
Three business processes need to be implemented, and the implementations need to communicate with several different SaaS applications.
These processes are owned by separate (siloed) LOBs and are mainly independent of each other, but do share a few business entities. Each LOB has one development team and their own budget In this organizational context, what is the most effective approach to choose the API data models for the APIs that will implement these business processes with minimal redundancy of the data models?
A) Build several Bounded Context Data Models that align with coherent parts of the business processes and the definitions of associated business entities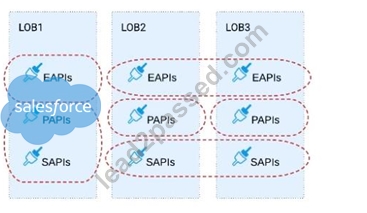
B) Build distinct data models for each API to follow established micro-services and Agile API-centric practices C) Build all API data models using XML schema to drive consistency and reuse across the organization D) Build one centralized Canonical Data Model (Enterprise Data Model) that unifies all the data types from all three business processes, ensuring the data model is consistent and non-redundant
Answer: C
Explanation:
Correct Answe r: Build several Bounded Context Data Models that align with coherent parts of the business processes and the definitions of associated business entities.
*****************************************
>> The options w.r.t building API data models using XML schema/ Agile API-centric practices are irrelevant to the scenario given in the question. So these two are INVALID.
>> Building EDM (Enterprise Data Model) is not feasible or right fit for this scenario as the teams and LOBs work in silo and they all have different initiatives, budget etc.. Building EDM needs intensive coordination among all the team which evidently seems not possible in this scenario.
So, the right fit for this scenario is to build several Bounded Context Data Models that align with coherent parts of the business processes and the definitions of associated business entities.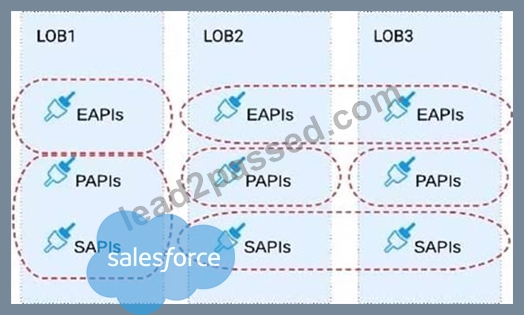
NEW QUESTION # 74
Several times a week, an API implementation shows several thousand requests per minute in an Anypoint Monitoring dashboard, Between these bursts, the dashboard shows between two and five requests per minute. The API implementation is running on Anypoint Runtime Fabric with two non-clustered replicas, reserved vCPU 1.0 and vCPU Limit 2.0.
An API consumer has complained about slow response time, and the dashboard shows the 99 percentile is greater than 120 seconds at the time of the complaint. It also shows greater than 90% CPU usage during these time periods.
In manual tests in the QA environment, the API consumer has consistently reproduced the slow response time and high CPU usage, and there were no other API requests at this time. In a brainstorming session, the engineering team has created several proposals to reduce the response time for requests.
Which proposal should be pursued first?
Answer: B
Explanation:
Scenario Analysis:
The API implementation is experiencing high CPU usage (over 90%) during bursts of requests, which correlates with slow response times, as indicated by a 99th percentile response time greater than 120 seconds.
The API implementation is running on Anypoint Runtime Fabric with two non-clustered replicas and has a reserved vCPU of 1.0 and a vCPU limit of 2.0.
The high CPU usage during bursts suggests that the current resources may not be sufficient to handle peak loads.
Evaluating the Options:
Option A (Correct Answer): Increasing the vCPU resources for each replica would provide more processing power to handle high traffic volumes, potentially reducing the response time during spikes. Since the CPU usage is consistently high during bursts, this option directly addresses the resource bottleneck.
Option B: Modifying the API client to split requests may reduce individual request load but could be complex to implement on the client side and may not fully address the high CPU issue.
Option C: Increasing the number of replicas could help distribute the load; however, with a high CPU load on each replica, adding more replicas without increasing CPU resources may not fully resolve the problem.
Option D: Throttling the client would reduce the number of requests, but this may not be acceptable if the client needs to maintain a high request rate. It also does not directly address the CPU limitations of the API implementation.
Conclusion:
Option A is the best choice as it addresses the root cause of high CPU usage by increasing the vCPU allocation, allowing the API to handle more requests efficiently. This should be pursued first before considering other options.
Refer to MuleSoft's documentation on Runtime Fabric and vCPU resource allocation for more details on optimizing API performance in high-demand environments.
NEW QUESTION # 75
A Rate Limiting policy is applied to an API implementation to protect the back-end system. Recently, there have been surges in demand that cause some API client POST requests to the API implementation to be rejected with policy-related errors, causing delays and complications to the API clients.
How should the API policies that are applied to the API implementation be changed to reduce the frequency of errors returned to API clients, while still protecting the back-end system?
Answer: C
Explanation:
When managing high traffic to an API, especially with POST requests, it is crucial to ensure the API's policies both protect the back-end systems and provide a smooth client experience. Here's the approach to reducing errors:
Rate Limiting Policy: This policy enforces a limit on the number of requests within a defined time period. However, rate limiting alone may cause clients to hit limits during demand surges, leading to errors.
Adding an SLA-based Spike Control Policy:
Spike Control is designed to handle sudden increases in traffic by smoothing out bursts of requests, which is particularly useful during high-demand periods.
By configuring SLA-based Spike Control, you can define thresholds for specific client tiers. For instance, premium clients might have higher limits or more flexibility in traffic bursts than standard clients.
Why Option D is Correct:
Keeping the Rate Limiting policy continues to provide baseline protection for the back-end.
Adding the SLA-based Spike Control policy allows for differentiated control, where requests are queued or delayed during bursts rather than outright rejected. This approach significantly reduces error responses to clients while still controlling overall traffic.
of Incorrect Options:
Option A (adding Client ID Enforcement) would not reduce errors related to traffic surges.
Option B (HTTP Caching) is not applicable as caching is generally ineffective for non-idempotent requests like POST.
Option C (only Spike Control without Rate Limiting) may leave the back-end system vulnerable to sustained high traffic levels, reducing protection.
Reference
For more information on configuring Rate Limiting and SLA-based Spike Control policies, refer to MuleSoft documentation on API Policies and Rate Limiting.
NEW QUESTION # 76
A retail company is using an Order API to accept new orders. The Order API uses a JMS queue to submit orders to a backend order management service. The normal load for orders is being handled using two (2) CloudHub workers, each configured with 0.2 vCore. The CPU load of each CloudHub worker normally runs well below 70%. However, several times during the year the Order API gets four times (4x) the average number of orders. This causes the CloudHub worker CPU load to exceed 90% and the order submission time to exceed 30 seconds. The cause, however, is NOT the backend order management service, which still responds fast enough to meet the response SLA for the Order API. What is the MOST resource-efficient way to configure the Mule application's CloudHub deployment to help the company cope with this performance challenge?
Answer: D
Explanation:
Correct Answe r: Use a horizontal CloudHub autoscaling policy that triggers on CPU utilization greater than 70%
*****************************************
The scenario in the question is very clearly stating that the usual traffic in the year is pretty well handled by the existing worker configuration with CPU running well below 70%. The problem occurs only "sometimes" occasionally when there is spike in the number of orders coming in.
So, based on above, We neither need to permanently increase the size of each worker nor need to permanently increase the number of workers. This is unnecessary as other than those "occasional" times the resources are idle and wasted.
We have two options left now. Either to use horizontal Cloudhub autoscaling policy to automatically increase the number of workers or to use vertical Cloudhub autoscaling policy to automatically increase the vCore size of each worker.
Here, we need to take two things into consideration:
1. CPU
2. Order Submission Rate to JMS Queue
>> From CPU perspective, both the options (horizontal and vertical scaling) solves the issue. Both helps to bring down the usage below 90%.
>> However, If we go with Vertical Scaling, then from Order Submission Rate perspective, as the application is still being load balanced with two workers only, there may not be much improvement in the incoming request processing rate and order submission rate to JMS queue. The throughput would be same as before. Only CPU utilization comes down.
>> But, if we go with Horizontal Scaling, it will spawn new workers and adds extra hand to increase the throughput as more workers are being load balanced now. This way we can address both CPU and Order Submission rate.
Hence, Horizontal CloudHub Autoscaling policy is the right and best answer.
NEW QUESTION # 77
......
Who don't want to be more successful and lead a better life? But it's not easy to become better. Our Mule-Arch-201 exam questions can give you some help. After using our Mule-Arch-201 study materials, you can pass the exam faster and you can also prove your strength. Of course, our Mule-Arch-201 Practice Braindumps can bring you more than that. You can free download the demos to take a look at the advantages of our Mule-Arch-201 training guide.
Mule-Arch-201 Trustworthy Dumps: https://www.lead2passed.com/Salesforce/Mule-Arch-201-practice-exam-dumps.html
DOWNLOAD the newest Lead2Passed Mule-Arch-201 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1_mu9kYMfH-rdffK1LKYYDvYaed-SOpVN