When you grasp the key points to attend the AI-500 exam, nothing will be difficult for you anymore. Our professional experts are good at compiling the AI-500 training guide with the most important information. They have been in this career for over ten years, and they know every detail about the AI-500 Exam no matter on the content but also on the displays. Believe in our AI-500 practice braindumps, and your success is 100% guaranteed!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Evaluate, optimize, and monitor multi-agent solutions | 20–25% | - Assess performance and reliability
|
| Topic 2: Develop multi-agent solutions in Azure | 30–35% | - Manage state and memory
|
| Topic 3: Secure, govern, and deploy multi-agent solutions | 20–25% | - Deploy and maintain solutions
|
| Topic 4: Architect multi-agent solutions | 15–20% | - Design workflow and tool integration
|
>> Valid Braindumps AI-500 Files <<
Each user's situation is different. AI-500 simulating exam will develop the most suitable learning plan for each user. We will contact the user to ensure that they fully understand the user's situation, including their own level, available learning time on AI-500 Training Questions. Our experts will fully consider the gradual progress of knowledge and create the most effective learning plan on the AI-500 exam questions for you.
NEW QUESTION # 43
You have a Microsoft Foundry multi-agent customer support solution. The solution includes an orchestrator that starts a single conversation trace when a user request arrives and can invoke two agents named Agent1 and Agent2 concurrently. Each agent can invoke Model Context Protocol (MCP)-hosted tools and dependent REST APIs.
The solution uses OpenTelemetry SDKs to emit logs, metrics, and traces via OTLP to an OpenTelemetry Collector. The solution emits the conversation ID, trace ID, and span ID for agent invocations, tool invocations, and external API calls.
You have a monitoring dashboard that includes:
* Latency
* Throughput
* Reliability
* Token usage
* Content safety triggers
* Time to First Token (TTFT)
Alert rules are configured for latency anomalies and tool invocation failures.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.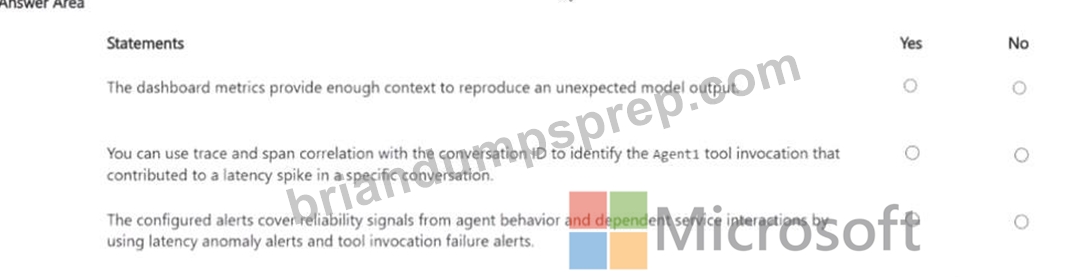
Answer:
Explanation: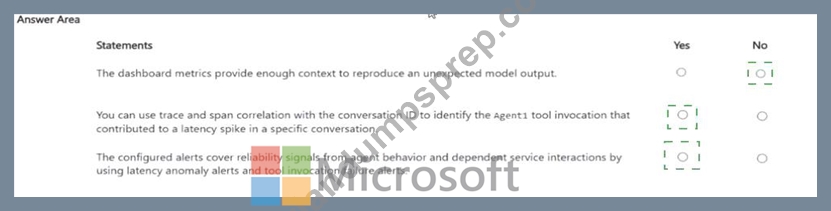
Explanation:
No / Yes / Yes
Aggregate dashboard metrics do not provide enough execution context to reproduce a specific unexpected model output, so the first statement is false. Reproduction normally requires detailed trace data such as model inputs/outputs, ordered agent spans, tool calls, and dependency results. The second statement is true because the solution emits conversation, trace, and span identifiers across agent, MCP tool, and REST API calls.
OpenTelemetry correlation can therefore isolate the Agent1 tool span that contributed to a latency spike in one conversation. The third statement is also true: latency-anomaly alerts and tool-invocation failure alerts cover important reliability signals from both agent execution and dependent service interactions. They are not the entire observability strategy, but they do address the reliability conditions described. The correct sequence is No, Yes, Yes. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - agent tracing concepts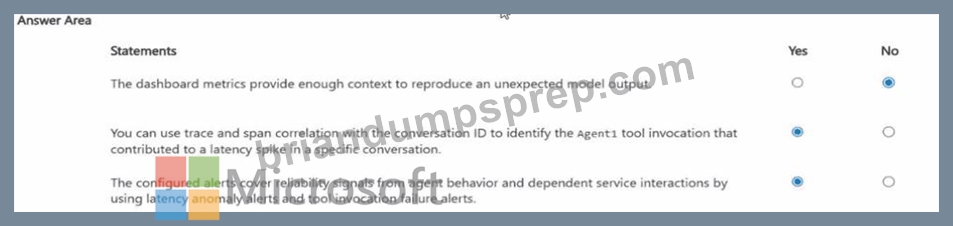
NEW QUESTION # 44
You have a Microsoft Foundry project that includes four independent analysis agents. Each agent invocation consumes 500 tokens per minute (TPM) from a Foundry deployment that has a TPM rate limit of 1,000.
After each agent completes, it writes 200 small records to Microsoft Dataverse. Running multiple agents simultaneously causes write bursts that result in HTTP 429 (Too Many Requests) responses.
You need to reduce the end-to-end task duration, while preventing provider and platform throttling. The solution must meet the following requirements:
* Keep as much agent parallelism as the TPM rate limit permits.
* Handle Dataverse throttling without sending premature retries.
How should you configure the orchestration? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.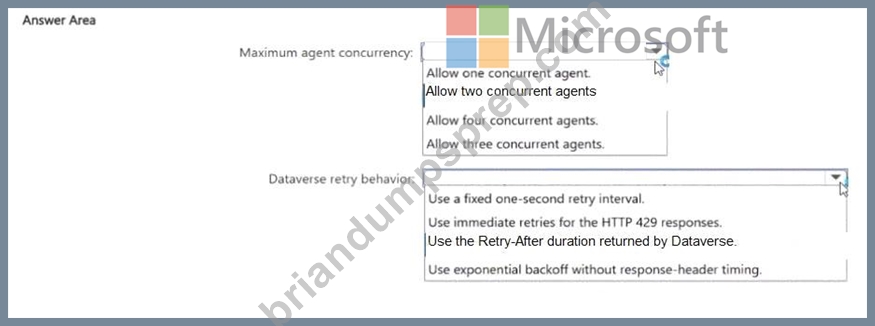
Answer:
Explanation: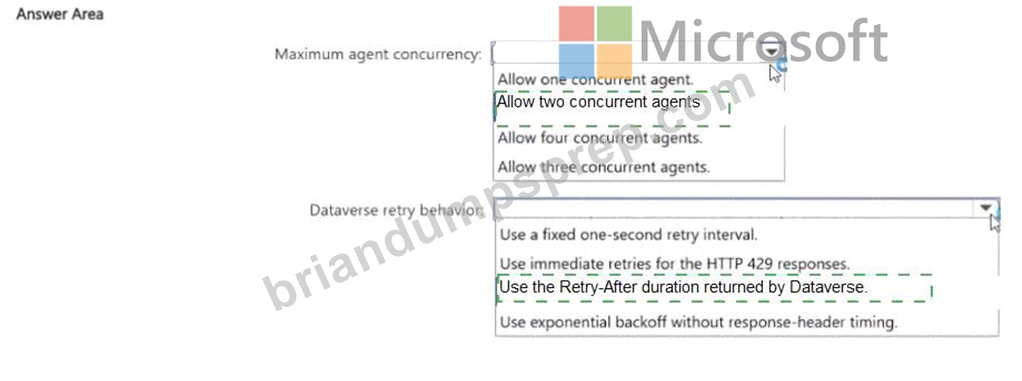
Explanation:
Maximum agent concurrency: Two agents; Dataverse retry behavior: Respect the Retry-After duration returned by Dataverse.
Each analysis agent consumes 500 TPM and the deployment permits 1,000 TPM, so at most two agents can run simultaneously without exceeding the stated model limit. Running only one wastes available parallelism; running three or four violates the limit. The separate Dataverse problem is HTTP 429 service-protection throttling. Microsoft Dataverse returns a `Retry-After` duration that tells clients how long to wait before retrying. Respecting that value prevents premature retries from worsening the overload condition. A fixed retry interval or immediate retry ignores the server ' s current capacity signal. The orchestration should therefore cap model-side concurrency at two and, after each agent finishes, pace Dataverse writes according to the returned retry guidance. This combination minimizes task duration while honoring both provider and platform throttling constraints. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Dataverse service protection API limits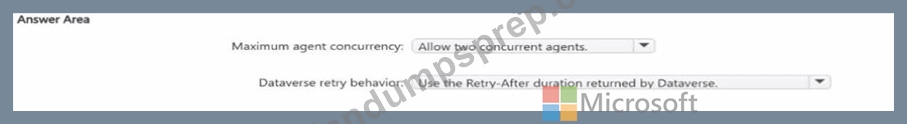
NEW QUESTION # 45
You have a Microsoft Foundry project that contains a coordinator agent for claims processing.
You have an existing fraud analysis agent hosted outside of Foundry. The agent exposes a standards-based HTTPS endpoint, publishes the supported s kills and media types, and requires authenticated requests.
You need to configure the coordinator agent to invoke the fraud analysis agent. The solution must meet the following requirements:
Use the interoperable invocation interface.
Use the published capability discovery contract.
Reuse stored authentication across versions of the coordinator agent.
How should you configure the integration? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.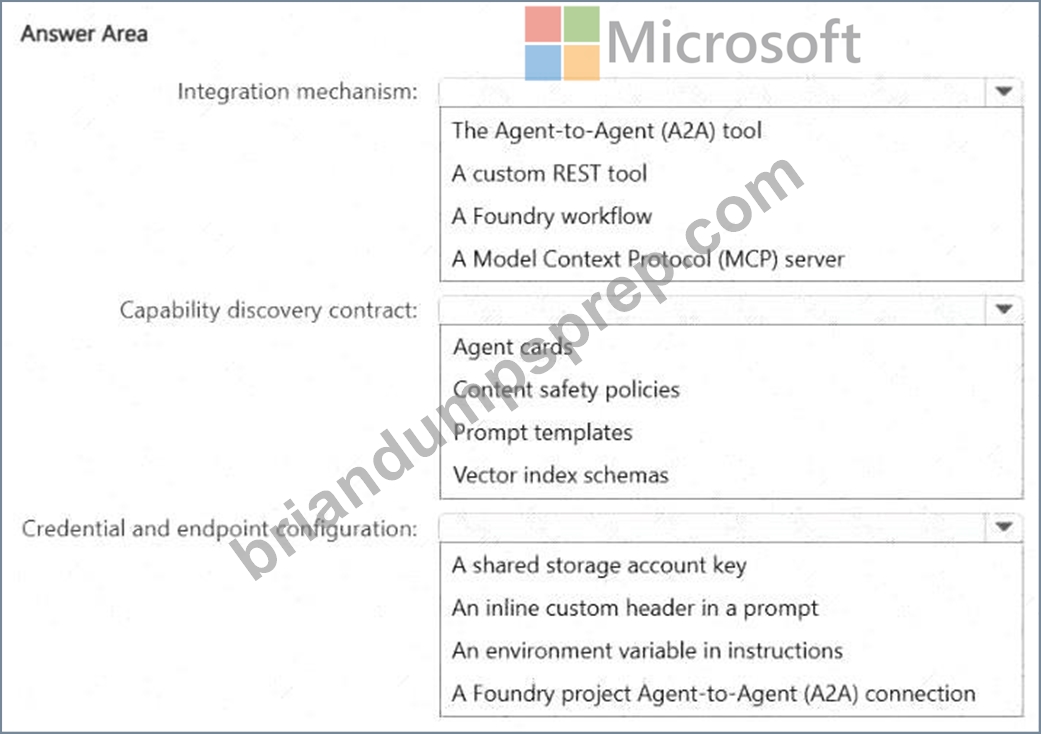
Answer:
Explanation: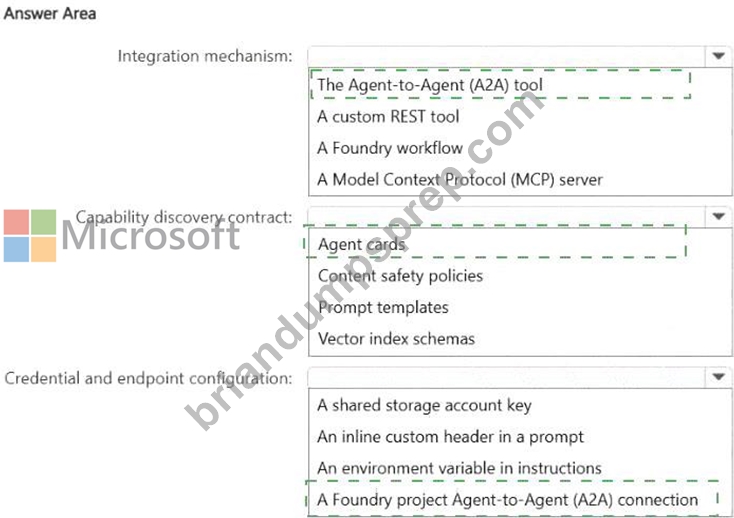
Explanation:
Integration mechanism: Agent-to-Agent (A2A) tool; Capability discovery contract: Agent cards; Credential and endpoint configuration: A Foundry project A2A connection.
The remote fraud service is an autonomous agent that exposes a standards-based HTTPS endpoint and publishes its skills and media types, which matches the Agent-to-Agent protocol rather than a conventional tool API. A2A uses an agent card as the capability-discovery contract, allowing the coordinator to discover supported skills, formats, and invocation details without coupling to the remote framework ' s implementation.
Microsoft Foundry project A2A connections store the remote endpoint and authentication configuration so credentials can be reused across coordinator-agent versions instead of being embedded separately in every version. Together, the A2A tool, agent card, and project connection satisfy interoperable invocation, capability discovery, and reusable authentication. This is the supported Microsoft architecture for calling an external A2A-compatible agent from a Foundry coordinator. The configuration should be kept in the project connection rather than prompt text so authentication remains centrally managed, auditable, and reusable as the coordinator evolves. This also avoids duplicating sensitive connection settings across agent versions.
Official Microsoft reference: Microsoft Foundry - enable Agent-to-Agent endpoint and authentication
NEW QUESTION # 46
You have a multi-agent solution in Microsoft Foundry. Every request begins with the same 1,800-token instruction block and Model Context Protocol (MCP) tool definitions, and then appends a unique user message.
Input-token costs and Time to First Token (TTFT) increase during peak hours.
You need to reduce the input-token costs and TTFT for requests that share common instructions and tool definitions. The solution must meet the following requirements:
Reuse cached work only when the common prefix matches exactly.
Generate a new completion for each user request.
Minimize application changes.
Which type of caching should you use?
Answer: B
Explanation:
Prompt caching is designed for requests that share a long, identical prefix but still require a new completion for the unique user input. Azure OpenAI prompt caching reuses computation for matching prompt prefixes, reducing the effective input cost and improving Time to First Token for supported models. The stable 1,800- token instruction and MCP tool-definition block is large enough to benefit from this mechanism, and the unique user message can remain at the end so each request still generates a fresh response. Response caching would reuse an old completion, which violates the requirement. Semantic caching matches similar meaning rather than exact prompt prefixes, and retrieval caching applies to knowledge retrieval rather than model prompt processing. Because prompt caching is handled automatically for supported deployments, it also minimizes application changes. Therefore D is correct. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Azure OpenAI - Prompt caching
NEW QUESTION # 47
You have a Microsoft Foundry multi-agent solution for loan applications. Each agent scores a full application independently and does NOT require output from other agents.
You need to recommend an orchestration pattern that meets the following requirements:
Produces one aggregated recommendation
Preserves independent scoring -
Minimizes end-to-end latency -
Minimize development effort -
What should you recommend?
Answer: B
Explanation:
The scoring agents do not depend on each other ' s output, so their work should be fanned out in parallel and aggregated afterward. Microsoft Agent Framework concurrent orchestration is intended for independent participants that can process the same input simultaneously. That minimizes end-to-end latency because completion time approaches the slowest individual scorer instead of the sum of all scorers. The concurrent workflow also provides a fan-in stage that can aggregate the separate scores into one recommendation without requiring a complex custom conversation protocol. Sequential orchestration wastes time by serializing independent work. Group chat and Magentic-style collaboration introduce unnecessary coordination and planning overhead when the agents simply need independent scoring. Therefore D, concurrent, is the simplest and fastest orchestration pattern. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Microsoft Agent Framework - Concurrent orchestration
NEW QUESTION # 48
......
Many candidates do not have actual combat experience, for the qualification examination is the first time to attend, so about how to get the test Microsoft certification didn't own a set of methods, and cost a lot of time to do something that has no value. With our AI-500 exam Practice, you will feel much relax for the advantages of high-efficiency and accurate positioning on the content and formats according to the candidates' interests and hobbies. Numerous grateful feedbacks form our loyal customers proved that we are the most popular vendor in this field to offer our AI-500 Preparation questions.
AI-500 Flexible Testing Engine: https://www.briandumpsprep.com/AI-500-prep-exam-braindumps.html