Übrigens, Sie können die vollständige Version der Fast2test Professional-Machine-Learning-Engineer Prüfungsfragen aus dem Cloud-Speicher herunterladen: https://drive.google.com/open?id=1OIVCiUzXfVDH4wsR-Y8S8IbKjvfRfSQC
Jeder hat eine Utopie in seinem Herzen. Manchmal macht dieser unzuerfüllende Traum uns traurig. In der Wirklichkeit ist es doch nicht zu erfüllen. Solange Sie geeignete Maßnahmen treffen, ist alles möglich. Sie können doch die Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung bestehen. Warum? Weil Sie die Fragenkataloge von Fast2test haben. Die Fragenpool zur Google Professional-Machine-Learning-Engineer Prüfung von Fast2test sind die besten Fragenpool. Sie sind wegen ihrer hohen Erfolgsquote und Effizienz ganz berühmt. Zugleich können Sie auch viel Kraft ersparen. Mit Fast2test können Sie die Prüfung ganz einfach bestehen und Ihren Traum verwirklichen. Sie werden mehr Selbstbewusstsein haben, was zum Erfolg führt.
| Section | Weight | Objectives |
|---|---|---|
| Scale prototypes into AI models | 18% | - Work with foundation models and generative AI techniques - Design and run experiments - Optimize model performance and generalization - Select appropriate model architectures and frameworks |
| Train and deploy models | 20% | - Implement generative AI deployment patterns - Use Vertex AI deployment features and infrastructure - Configure training jobs and environments - Deploy models for online, batch, and streaming prediction |
| Monitor and optimize AI solutions | 16% | - Monitor data quality and pipeline health - Troubleshoot and maintain production systems - Optimize cost, latency, and resource usage - Monitor model performance, fairness, and drift |
| Automate and orchestrate ML pipelines | 18% | - Automate retraining and model updates - Implement CI/CD for ML systems - Design end-to-end ML workflows - Use Vertex AI Pipelines, TFX, and other orchestration tools |
| Architect low-code AI solutions | 12% | - Design solutions using Vertex AI Studio, Model Garden, and Agent Builder - Apply responsible AI principles to low-code designs - Identify use cases for low-code/no-code AI tools |
| Collaborate to manage data and models | 16% | - Organize and prepare enterprise data
- Manage datasets and features in Vertex AI |
>> Professional-Machine-Learning-Engineer Zertifizierungsantworten <<
Jeder hat eine Utopie in seinem Herzen. Manchmal macht dieser unzuerfüllende Traum uns traurig. In der Wirklichkeit ist es doch nicht zu erfüllen. Solange Sie geeignete Maßnahmen treffen, ist alles möglich. Sie können doch die Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung bestehen. Warum? Weil Sie die Fragenkataloge von Fast2test haben. Die Fragenpool zur Google Professional-Machine-Learning-Engineer Prüfung von Fast2test sind die besten Fragenpool. Sie sind wegen ihrer hohen Erfolgsquote und Effizienz ganz berühmt. Zugleich können Sie auch viel Kraft ersparen. Mit Fast2test können Sie die Prüfung ganz einfach bestehen und Ihren Traum verwirklichen. Sie werden mehr Selbstbewusstsein haben, was zum Erfolg führt.
295. Frage
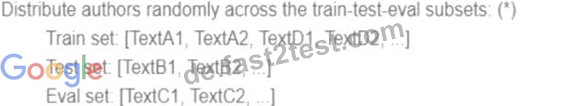
Your team is working on an NLP research project to predict political affiliation of authors based on articles they have written. You have a large training dataset that is structured like this: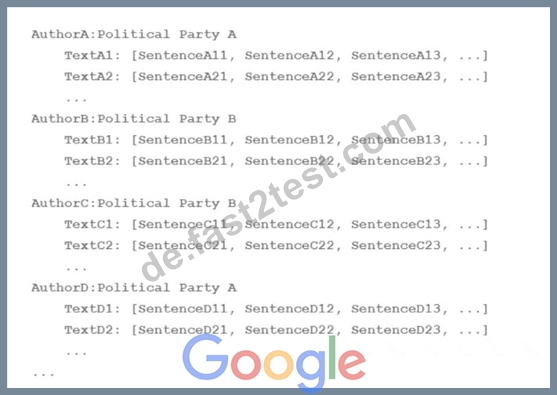
You followed the standard 80%-10%-10% data distribution across the training, testing, and evaluation subsets.
How should you distribute the training examples across the train-test-eval subsets while maintaining the
80-10-10 proportion?
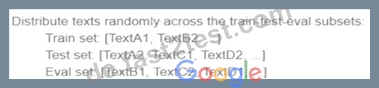
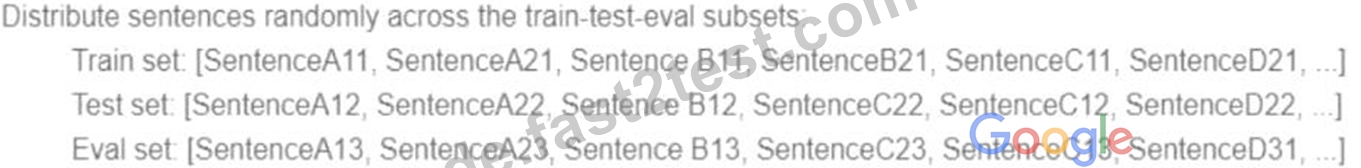
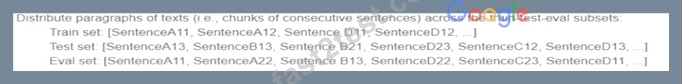
Antwort: B
Begründung:
The best way to distribute the training examples across the train-test-eval subsets while maintaining the
80-10-10 proportion is to use option C. This option ensures that each subset contains a balanced and representative sample of the different classes (Democrat and Republican) and the different authors. This way, the model can learn from a diverse and comprehensive set of articles and avoid overfitting or underfitting.
Option C also avoids the problem of data leakage, which occurs when the same author appears in more than one subset, potentially biasing the model and inflating its performance. Therefore, option C is the most suitable technique for this use case.
296. Frage
You developed a custom model by using Vertex Al to forecast the sales of your company s products based on historical transactional data You anticipate changes in the feature distributions and the correlations between the features in the near future You also expect to receive a large volume of prediction requests You plan to use Vertex Al Model Monitoring for drift detection and you want to minimize the cost. What should you do?
Antwort: C
Begründung:
The best option for using Vertex AI Model Monitoring for drift detection and minimizing the cost is to use the features and the feature attributions for monitoring, and set a prediction-sampling-rate value that is closer to 0 than 1. This option allows you to leverage the power and flexibility of Google Cloud to detect feature drift in the input predict requests for custom models, and reduce the storage and computation costs of the model monitoring job. Vertex AI Model Monitoring is a service that can track and compare the results of multiple machine learning runs. Vertex AI Model Monitoring can monitor the model's prediction input data for feature skew and drift. Feature drift occurs when the feature data distribution in production changes over time. If the original training data is not available, you can enable drift detection to monitor your models for feature drift.
Vertex AI Model Monitoring uses TensorFlow Data Validation (TFDV) to calculate the distributions and distance scores for each feature, and compares them with a baseline distribution. The baseline distribution is the statistical distribution of the feature's values in the training data. If the training data is not available, the baseline distribution is calculated from the first 1000 prediction requests that the model receives. If the distance score for a feature exceeds an alerting threshold that you set, Vertex AI Model Monitoring sends you an email alert. However, if you use a custom model, you can also enable feature attribution monitoring, which can provide more insights into the feature drift. Feature attribution monitoring analyzes the feature attributions, which are the contributions of each feature to the prediction output. Feature attribution monitoring can help you identify the features that have the most impact on the model performance, and the features that have the most significant drift over time. Feature attribution monitoring can also help you understand the relationship between the features and the prediction output, and the correlation between the features1. The prediction-sampling-rate is a parameter that determines the percentage of prediction requests that are logged and analyzed by the model monitoring job. Using a lower prediction-sampling-rate can reduce the storage and computation costs of the model monitoring job, but also the quality and validity of the data. Using a lower prediction-sampling-rate can introduce sampling bias and noise into the data, and make the model monitoring job miss some important features or patterns of the data. However, using a higher prediction-sampling-rate can increase the storage and computation costs of the model monitoring job, and also the amount of data that needs to be processed and analyzed. Therefore, there is a trade-off between the prediction-sampling-rate and the cost and accuracy of the model monitoring job, and the optimal prediction-sampling-rate depends on the business objective and the data characteristics2. By using the features and the feature attributions for monitoring, and setting a prediction-sampling-rate value that is closer to 0 than 1, you can use Vertex AI Model Monitoring for drift detection and minimize the cost.
The other options are not as good as option D, for the following reasons:
* Option A: Using the features for monitoring and setting a monitoring-frequency value that is higher than the default would not enable feature attribution monitoring, and could increase the cost of the model monitoring job. The monitoring-frequency is a parameter that determines how often the model monitoring job analyzes the logged prediction requests and calculates the distributions and distance scores for each feature. Using a higher monitoring-frequency can increase the frequency and timeliness of the model monitoring job, but also the computation costs of the model monitoring job. Moreover, using the features for monitoring would not enable feature attribution monitoring, which can provide more insights into the feature drift and the model performance1.
* Option B: Using the features for monitoring and setting a prediction-sampling-rate value that is closer to
1 than 0 would not enable feature attribution monitoring, and could increase the cost of the model monitoring job. The prediction-sampling-rate is a parameter that determines the percentage of prediction requests that are logged and analyzed by the model monitoring job. Using a higher prediction-sampling-rate can increase the quality and validity of the data, but also the storage and computation costs of the model monitoring job. Moreover, using the features for monitoring would not enable feature attribution monitoring, which can provide more insights into the feature drift and the model performance12.
* Option C: Using the features and the feature attributions for monitoring and setting a monitoring-frequency value that is lower than the default would enable feature attribution monitoring, but could reduce the frequency and timeliness of the model monitoring job. The monitoring-frequency is a parameter that determines how often the model monitoring job analyzes the logged prediction requests and calculates the distributions and distance scores for each feature. Using a lower
* monitoring-frequency can reduce the computation costs of the model monitoring job, but also the frequency and timeliness of the model monitoring job. This can make the model monitoring job less responsive and effective in detecting and alerting the feature drift1.
References:
* Preparing for Google Cloud Certification: Machine Learning Engineer, Course 3: Production ML Systems, Week 4: Evaluation
* Google Cloud Professional Machine Learning Engineer Exam Guide, Section 3: Scaling ML models in production, 3.3 Monitoring ML models in production
* Official Google Cloud Certified Professional Machine Learning Engineer Study Guide, Chapter 6:
Production ML Systems, Section 6.3: Monitoring ML Models
* Using Model Monitoring
* Understanding the score threshold slider
297. Frage
You have written unit tests for a Kubeflow Pipeline that require custom libraries. You want to automate the execution of unit tests with each new push to your development branch in Cloud Source Repositories. What should you do?
Antwort: A
Begründung:
Cloud Build is a service that executes your builds on Google Cloud Platform infrastructure. Cloud Build can import source code from Cloud Source Repositories, Cloud Storage, GitHub, or Bitbucket, execute a build to your specifications, and produce artifacts such as Docker containers or Java archives1 Cloud Build allows you to set up automated triggers that start a build when changes are pushed to a source code repository. You can configure triggers to filter the changes based on the branch, tag, or file path2 To automate the execution of unit tests for a Kubeflow Pipeline that require custom libraries, you can use Cloud Build to set an automated trigger to execute the unit tests when changes are pushed to your development branch in Cloud Source Repositories. You can specify the steps of the build in a YAML or JSON file, such as installing the custom libraries, running the unit tests, and reporting the results. You can also use Cloud Build to build and deploy the Kubeflow Pipeline components if the unit tests pass3 The other options are not recommended or feasible. Writing a script that sequentially performs the push to your development branch and executes the unit tests on Cloud Run is not a good practice, as it does not leverage the benefits of Cloud Build and its integration with Cloud Source Repositories. Setting up a Cloud Logging sink to a Pub/Sub topic that captures interactions with Cloud Source Repositories and using a Pub/Sub trigger for Cloud Run or Cloud Function to execute the unit tests is unnecessarily complex and inefficient, as it adds extra steps and latency to the process. Cloud Run and Cloud Function are also not designed for executing unit tests, as they have limitations on the memory, CPU, and execution time45
298. Frage
You work for a maintenance company and have built and trained a deep learning model that identifies defects based on thermal images of underground electric cables. Your dataset contains
10,000 images, 100 of which contain visible defects. How should you evaluate the performance of the model on a test dataset?
Antwort: D
Begründung:
A is correct because it is scale-invariant. AUC measures how well predictions are ranked, rather than their absolute values. AUC is also classification-threshold invariant. It measures the quality of the model's predictions irrespective of what classification threshold is chosen.
B is incorrect because calculating the number of true positives without considering false positives can lead to misleading results. For instance, the model could classify nearly every image as a defect. This would result in many true positives, but the model would in fact be a very poor discriminator.
C is incorrect because merely calculating the fraction of images that contain defects doesn't indicate whether your model is accurate or not.
D is incorrect because this metric is more commonly used in distance-based models (e.g., K Nearest Neighbors). This isn't an appropriate metric for checking the performance of an image classification model.
https://developers.google.com/machine-learning/crash-course/classification/roc-and-auc
https://developers.google.com/machine-learning/clustering/algorithm/advantages-disadvantages
299. Frage
You are developing a Kubeflow pipeline on Google Kubernetes Engine. The first step in the pipeline is to issue a query against BigQuery. You plan to use the results of that query as the input to the next step in your pipeline. You want to achieve this in the easiest way possible. What should you do?
Antwort: D
Begründung:
Kubeflow is an open source platform for developing, orchestrating, deploying, and running scalable and portable machine learning workflows on Kubernetes. Kubeflow Pipelines is a component of Kubeflow that allows you to build and manage end-to-end machine learning pipelines using a graphical user interface or a Python-based domain-specific language (DSL). Kubeflow Pipelines can help you automate and orchestrate your machine learning workflows, and integrate with various Google Cloud services and tools1 One of the Google Cloud services that you can use with Kubeflow Pipelines is BigQuery, which is a serverless, scalable, and cost-effective data warehouse that allows you to run fast and complex queries on large-scale data. BigQuery can help you analyze and prepare your data for machine learning, and store and manage your machine learning models2 To execute a query against BigQuery as the first step in your Kubeflow pipeline, and use the results of that query as the input to the next step in your pipeline, the easiest way to do that is to use the BigQuery Query Component, which is a pre-built component that you can find in the Kubeflow Pipelines repository on GitHub. The BigQuery Query Component allows you to run a SQL query on BigQuery, and output the results as a table or a file. You can use the component's URL to load the component into your pipeline, and specify the query and the output parameters. You can then use the output of the component as the input to the next step in your pipeline, such as a data processing or a model training step3 The other options are not as easy or feasible. Using the BigQuery console to execute your query and then save the query results into a new BigQuery table is not a good idea, as it does not integrate with your Kubeflow pipeline, and requires manual intervention and duplication of data. Writing a Python script that uses the BigQuery API to execute queries against BigQuery is not ideal, as it requires writing custom code and handling authentication and error handling. Using the Kubeflow Pipelines DSL to create a custom component that uses the Python BigQuery client library to execute queries is not optimal, as it requires creating and packaging a Docker container image for the component, and testing and debugging the component.
References: 1: Kubeflow Pipelines overview 2: BigQuery overview 3: BigQuery Query Component
300. Frage
......
Möchten Sie dieGoogle Professional-Machine-Learning-Engineer Zertifizierungsprüfung mühlos bestehen? Dann sind die Fragenkataloge zur Google Professional-Machine-Learning-Engineer Zertifizierung aus Fast2test unerlässlich. Die Fragenpool zur Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung aus Fast2test werden von den erfahrenen Experten durch ständige Praxis entworfen, sie sind eine Kommbination aus Fragen und Antworten. Deswegen ist die Webseite Fast2test die Beste. Wählen Sie Fast2test, wartet eine schönere Zukunft auf Sie da.
Professional-Machine-Learning-Engineer Fragen&Antworten: https://de.fast2test.com/Professional-Machine-Learning-Engineer-premium-file.html
Laden Sie die neuesten Fast2test Professional-Machine-Learning-Engineer PDF-Versionen von Prüfungsfragen kostenlos von Google Drive herunter: https://drive.google.com/open?id=1OIVCiUzXfVDH4wsR-Y8S8IbKjvfRfSQC