P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by ExamTorrent: https://drive.google.com/open?id=1P0XTjOE7bqKumLN3yP43jUaGJUg0mqPY
Our Databricks-Generative-AI-Engineer-Associate learning guide are developed in three versions which are the PDF, Software and APP online versions. The PDF version of Databricks-Generative-AI-Engineer-Associate training materials is convenient for you to print, the software version can provide practice test for you and the online version of our Databricks-Generative-AI-Engineer-Associate Study Materials is for you to read anywhere at any time. If you are hesitating about which version should you choose, you can download our Databricks-Generative-AI-Engineer-Associate free demo first to get a firsthand experience before you make any decision.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Databricks-Generative-AI-Engineer-Associate Actual Dump <<
The second format is web-based Databricks-Generative-AI-Engineer-Associate practice exam and can be accessed through browsers and candidates can take it online. The students don’t need to install or use any plugins or software to attempt the web-based practice exam. The third and last form is the Databricks Databricks-Generative-AI-Engineer-Associate desktop practice test software that can be used from Windows computers. Candidates that have Windows laptops or computers can take the Databricks-Generative-AI-Engineer-Associate practice exam efficiently.
NEW QUESTION # 68
A Generative AI Engineer is developing an agent system using a popular agent-authoring library. The agent comprises multiple parallel and sequential chains. The engineer encounters challenges as the agent fails at one of the steps, making it difficult to debug the root cause. They need to find an appropriate approach to research this issue and discover the cause of failure. Which approach do they choose?
Answer: C
Explanation:
For complex agentic systems (like those built with LangGraph or Autogen), standard logging is often insufficient because the "state" of the agent changes dynamically. MLflow Tracing is the designated Generative AI engineering standard for debugging these systems. Tracing provides a visual, hierarchical timeline of every call made during an agent's execution-including internal LLM reasoning, tool calls, and data transformations. When a step fails, the trace allows the engineer to click into that specific node to see the exact input sent to the LLM and the raw output received. This is much faster and more comprehensive than manually deconstructing the agent (D) or adding manual logs (C). While mlflow.evaluate (B) is useful for measuring performance across a whole dataset, it is not a tool for real-time debugging of a single execution failure.
NEW QUESTION # 69
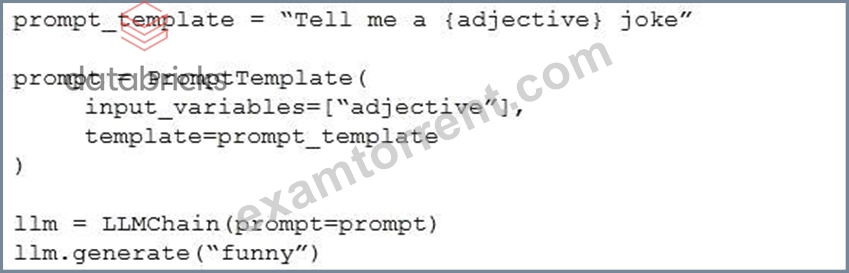
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.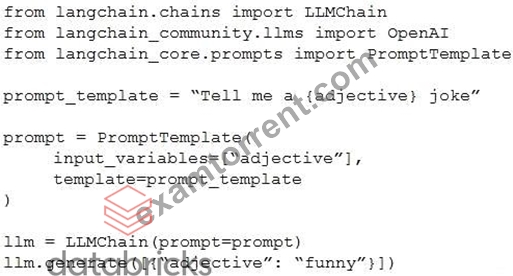
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
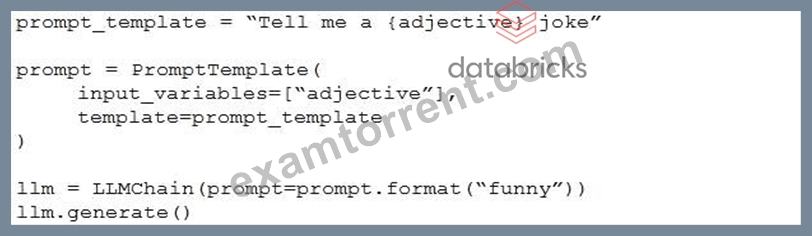
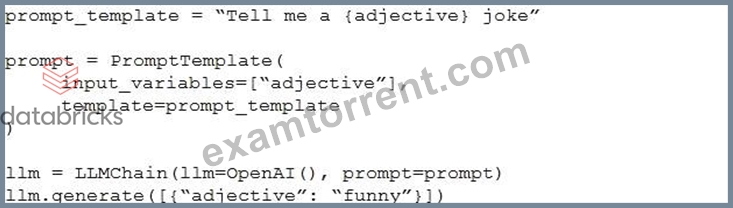
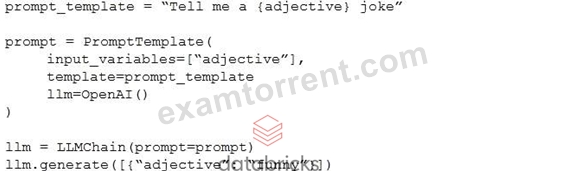
Answer: C
Explanation:
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here's a detailed breakdown of why Option C is the right choice and how it addresses the issue:
* Proper Initialization: In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
* Correct Use of Classes and Methods:
* The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
* The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
* The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
* Option A: Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
* Option B: Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
* Option D: Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain's architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
NEW QUESTION # 70
A Generative AI Engineer is tasked with deploying an application that takes advantage of a custom MLflow Pyfunc model to return some interim results.
How should they configure the endpoint to pass the secrets and credentials?
Answer: A
Explanation:
Context: Deploying an application that uses an MLflow Pyfunc model involves managing sensitive information such as secrets and credentials securely.
Explanation of Options:
* Option A: Use spark.conf.set(): While this method can pass configurations within Spark jobs, using it for secrets is not recommended because it may expose them in logs or Spark UI.
* Option B: Pass variables using the Databricks Feature Store API: The Feature Store API is designed for managing features for machine learning, not for handling secrets or credentials.
* Option C: Add credentials using environment variables: This is a common practice for managing credentials in a secure manner, as environment variables can be accessed securely by applications without exposing them in the codebase.
* Option D: Pass the secrets in plain text: This is highly insecure and not recommended, as it exposes sensitive information directly in the code.
Therefore,Option Cis the best method for securely passing secrets and credentials to an application, protecting them from exposure.
NEW QUESTION # 71
A Generative Al Engineer has created a RAG application to look up answers to questions about a series of fantasy novels that are being asked on the author's web forum. The fantasy novel texts are chunked and embedded into a vector store with metadata (page number, chapter number, book title), retrieved with the user' s query, and provided to an LLM for response generation. The Generative AI Engineer used their intuition to pick the chunking strategy and associated configurations but now wants to more methodically choose the best values.
Which TWO strategies should the Generative AI Engineer take to optimize their chunking strategy and parameters? (Choose two.)
Answer: A,C
Explanation:
To optimize a chunking strategy for a Retrieval-Augmented Generation (RAG) application, the Generative AI Engineer needs a structured approach to evaluating the chunking strategy, ensuring that the chosen configuration retrieves the most relevant information and leads to accurate and coherent LLM responses. Here
' s why C and E are the correct strategies:
Strategy C: Evaluation Metrics (Recall, NDCG)
* Define an evaluation metric : Common evaluation metrics such as recall, precision, or NDCG (Normalized Discounted Cumulative Gain) measure how well the retrieved chunks match the user ' s query and the expected response.
* Recall measures the proportion of relevant information retrieved.
* NDCG is often used when you want to account for both the relevance of retrieved chunks and the ranking or order in which they are retrieved.
* Experiment with chunking strategies : Adjusting chunking strategies based on text structure (e.g., splitting by paragraph, chapter, or a fixed number of tokens) allows the engineer to experiment with various ways of slicing the text. Some chunks may better align with the user ' s query than others.
* Evaluate performance : By using recall or NDCG, the engineer can methodically test various chunking strategies to identify which one yields the highest performance. This ensures that the chunking method provides the most relevant information when embedding and retrieving data from the vector store.
Strategy E: LLM-as-a-Judge Metric
* Use the LLM as an evaluator : After retrieving chunks, the LLM can be used to evaluate the quality of answers based on the chunks provided. This could be framed as a " judge " function, where the LLM compares how well a given chunk answers previous user queries.
* Optimize based on the LLM ' s judgment : By having the LLM assess previous answers and rate their relevance and accuracy, the engineer can collect feedback on how well different chunking configurations perform in real-world scenarios.
* This metric could be a qualitative judgment on how closely the retrieved information matches the user ' s intent.
* Tune chunking parameters : Based on the LLM ' s judgment, the engineer can adjust the chunk size or structure to better align with the LLM ' s responses, optimizing retrieval for future queries.
By combining these two approaches, the engineer ensures that the chunking strategy is systematically evaluated using both quantitative (recall/NDCG) and qualitative (LLM judgment) methods. This balanced optimization process results in improved retrieval relevance and, consequently, better response generation by the LLM.
NEW QUESTION # 72
A Generative AI Engineer is building a compound AI system for an organization. The goal is to automate the processing of incoming customer event reports against a coding system and corporate-guidelines documentation. The system must handle three distinct user-request types: answering questions from guidelines documents, extracting specific event codes from reviewers' notes, and routing ambiguous requests to the appropriate specialized handler. All three capabilities must operate under a single entry point that interprets user intent and delegates accordingly.
Which Agent Brick should serve as the top-level orchestrator in this architecture?
Answer: C
Explanation:
The Multi-Agent Supervisor is designed to coordinate specialized agents and tools behind a unified entry point. It interprets the incoming request, selects suitable capabilities, delegates work, and combines results when necessary. In this scenario, document questions can be handled by a knowledge-retrieval specialist, while event-code extraction can be assigned to a specialized extraction capability. The supervisor provides the coordination needed to select between those tasks and handle requests requiring multiple steps. A Knowledge Assistant's conversational interface does not itself make it the appropriate general-purpose orchestrator.
Adding vector indexes also does not establish specialized extraction and routing behavior. Although option A names the same component, its justification misses the central requirement: coordinated delegation across distinct capabilities. Databricks documentation
NEW QUESTION # 73
......
The advent of our Databricks-Generative-AI-Engineer-Associate study guide with three versions has helped more than 98 percent of exam candidates get the certificate successfully. Rather than insulating from the requirements of the Databricks-Generative-AI-Engineer-Associate real exam, our Databricks-Generative-AI-Engineer-Associate practice materials closely co-related with it. And their degree of customer’s satisfaction is escalating. Besides, many exam candidates are looking forward to the advent of new Databricks-Generative-AI-Engineer-Associate versions in the future.
Reliable Databricks-Generative-AI-Engineer-Associate Dumps Questions: https://www.examtorrent.com/Databricks-Generative-AI-Engineer-Associate-valid-vce-dumps.html
DOWNLOAD the newest ExamTorrent Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1P0XTjOE7bqKumLN3yP43jUaGJUg0mqPY