P.S. Free & New ARA-C01 dumps are available on Google Drive shared by ITCertMagic: https://drive.google.com/open?id=1evCUhutBiZaUBEMYLlg4IuXennqZue4p
I would like to find a different job, because I am tired of my job and present life. Do you have that idea? How to get a better job? Are you interested in IT industry? Do you want to prove yourself through IT? If you want to work in the IT field, it is essential to register IT certification exam and get the certificate. The main thing for you is to take IT certification exam that is accepted commonly which will help you to open a new journey. And you must be familiar with Snowflake ARA-C01 Certification test. To obtain the certificate will help you to find a better job. What? Do you have no confidence to take the exam? It doesn't matter that you can use our ITCertMagic dumps.
| Certification Vendor: | Snowflake |
|---|---|
| Exam Name: | SnowPro Advanced: Architect Certification Exam |
| Exam Number: | ARA-C01 |
| Available Languages: | English |
| Related Certifications: | SnowPro Core Certification |
| Exam Duration: | 115 minutes |
| Passing Score: | 750 (scaled score out of 1000) |
| Exam Price: | $375 USD |
| Real Exam Qty: | Approximately 65 |
| Exam Format: | Multiple choice, Multiple select |
| Certificate Validity Period: | 2 years |
| Recommended Training: | Snowflake Training & Certification Learning Path |
| Exam Registration: | Snowflake Certification Portal |
| Sample Questions: | Snowflake ARA-C01 Sample Questions |
| Exam Way: | Online proctored exam |
| Pre Condition: | SnowPro Core Certification is strongly recommended and often expected before attempting the Advanced Architect exam |
| Official Syllabus URL: | https://www.snowflake.com/certification/ |
>> New ARA-C01 Test Answers <<
Our ARA-C01 study tools not only provide all candidates with high pass rate study materials, but also provide them with good service. If you have some question or doubt about us or our products, you can contact us to solve it. The thoughtfulness of our ARA-C01 study guide services is insuperable. What we do surly contribute to the success of ARA-C01 practice materials.We all know that it is of great important to pass the ARA-C01 Exam and get the certification for someone who wants to find a good job in internet area. I will recommend our study materials to you. It can be said that our ARA-C01 test prep greatly facilitates users, so that users cannot leave their homes to know the latest information.
Snowflake ARA-C01 exam is intended for individuals who have significant experience in working with Snowflake technology, and who possess a strong understanding of the Snowflake platform, its features and capabilities, as well as the Snowflake architecture. ARA-C01 Exam Tests the candidate's knowledge of Snowflake's data warehousing, data processing, and data integration capabilities, as well as their ability to design and implement complex Snowflake solutions.
NEW QUESTION # 62
An Architect is troubleshooting a query with poor performance using the QUERY_HIST0RY function. The Architect observes that the COMPILATIONJHME is greater than the EXECUTIONJTIME.
What is the reason for this?
Answer: C
Explanation:
Compilation time is the time it takes for the optimizer to create an optimal query plan for the efficient execution of the query. It also involves some pruning of partition files, making the query execution efficient2 If the compilation time is greater than the execution time, it means that the optimizer spent more time analyzing the query than actually running it. This could indicate that the query has overly complex logic, such as multiple joins, subqueries, aggregations, or expressions. The complexity of the query could also affect the size and quality of the query plan, which could impact the performance of the query3 To reduce the compilation time, the Architect can try to simplify the query logic, use views or common table expressions (CTEs) to break down the query into smaller parts, or use hints to guide the optimizer. The Architect can also use the EXPLAIN command to examine the query plan and identify potential bottlenecks or inefficiencies4 Reference:
1: SnowPro Advanced: Architect | Study Guide 5
2: Snowflake Documentation | Query Profile Overview 6
3: Understanding Why Compilation Time in Snowflake Can Be Higher than Execution Time 7
4: Snowflake Documentation | Optimizing Query Performance 8
: SnowPro Advanced: Architect | Study Guide
: Query Profile Overview
: Understanding Why Compilation Time in Snowflake Can Be Higher than Execution Time
: Optimizing Query Performance
NEW QUESTION # 63
Database DB1 has schema S1 which has one table, T1.
DB1 --> S1 --> T1
The retention period of EG1 is set to 10 days.
The retention period of s: is set to 20 days.
The retention period of t: Is set to 30 days.
The user runs the following command:
Drop Database DB1;
What will the Time Travel retention period be for T1?
Answer: A
Explanation:
The Time Travel retention period for T1 will be 30 days, which is the retention period set at the table level.
The Time Travel retention period determines how long the historical data is preserved and accessible for an object after it is modified or dropped. The Time Travel retention period can be set at the account level, the database level, the schema level, or the table level. The retention period set at the lowest level of the hierarchy takes precedence over the higher levels. Therefore, the retention period set at the table level overrides the retention periods set at the schema level, the database level, or the account level. When the user drops the database DB1, the table T1 is also dropped, but the historical data is still preserved for 30 days, which is the retention period set at the table level. The user can use the UNDROP command to restore the table T1 within the 30-day period. The other options are incorrect because:
* 10 days is the retention period set at the database level, which is overridden by the table level.
* 20 days is the retention period set at the schema level, which is also overridden by the table level.
* 37 days is not a valid option, as it is not the retention period set at any level.
Understanding & Using Time Travel
AT | BEFORE
Snowflake Time Travel & Fail-safe
NEW QUESTION # 64
A retail company has over 3000 stores all using the same Point of Sale (POS) system. The company wants to deliver near real-time sales results to category managers. The stores operate in a variety of time zones and exhibit a dynamic range of transactions each minute, with some stores having higher sales volumes than others.
Sales results are provided in a uniform fashion using data engineered fields that will be calculated in a complex data pipeline. Calculations include exceptions, aggregations, and scoring using external functions interfaced to scoring algorithms. The source data for aggregations has over 100M rows.
Every minute, the POS sends all sales transactions files to a cloud storage location with a naming convention that includes store numbers and timestamps to identify the set of transactions contained in the files. The files are typically less than 10MB in size.
How can the near real-time results be provided to the category managers? (Select TWO).
Answer: A,E
Explanation:
To provide near real-time sales results to category managers, the Architect can use the following steps:
Create an external stage that references the cloud storage location where the POS sends the sales transactions files. The external stage should use the file format and encryption settings that match the source files2 Create a Snowpipe that loads the files from the external stage into a target table in Snowflake. The Snowpipe should be configured with AUTO_INGEST = true, which means that it will automatically detect and ingest new files as they arrive in the external stage. The Snowpipe should also use a copy option to purge the files from the external stage after loading, to avoid duplicate ingestion3 Create a stream on the target table that captures the INSERTS made by the Snowpipe. The stream should include the metadata columns that provide information about the file name, path, size, and last modified time. The stream should also have a retention period that matches the real-time analytics needs4 Create a task that runs a query on the stream to process the near real-time data. The query should use the stream metadata to extract the store number and timestamps from the file name and path, and perform the calculations for exceptions, aggregations, and scoring using external functions. The query should also output the results to another table or view that can be accessed by the category managers. The task should be scheduled to run at a frequency that matches the real-time analytics needs, such as every minute or every 5 minutes.
The other options are not optimal or feasible for providing near real-time results:
All files should be concatenated before ingestion into Snowflake to avoid micro-ingestion. This option is not recommended because it would introduce additional latency and complexity in the data pipeline. Concatenating files would require an external process or service that monitors the cloud storage location and performs the file merging operation. This would delay the ingestion of new files into Snowflake and increase the risk of data loss or corruption. Moreover, concatenating files would not avoid micro-ingestion, as Snowpipe would still ingest each concatenated file as a separate load.
An external scheduler should examine the contents of the cloud storage location and issue SnowSQL commands to process the data at a frequency that matches the real-time analytics needs. This option is not necessary because Snowpipe can automatically ingest new files from the external stage without requiring an external trigger or scheduler. Using an external scheduler would add more overhead and dependency to the data pipeline, and it would not guarantee near real-time ingestion, as it would depend on the polling interval and the availability of the external scheduler.
The copy into command with a task scheduled to run every second should be used to achieve the near-real time requirement. This option is not feasible because tasks cannot be scheduled to run every second in Snowflake. The minimum interval for tasks is one minute, and even that is not guaranteed, as tasks are subject to scheduling delays and concurrency limits. Moreover, using the copy into command with a task would not leverage the benefits of Snowpipe, such as automatic file detection, load balancing, and micro-partition optimization. Reference:
1: SnowPro Advanced: Architect | Study Guide
2: Snowflake Documentation | Creating Stages
3: Snowflake Documentation | Loading Data Using Snowpipe
4: Snowflake Documentation | Using Streams and Tasks for ELT
: Snowflake Documentation | Creating Tasks
: Snowflake Documentation | Best Practices for Loading Data
: Snowflake Documentation | Using the Snowpipe REST API
: Snowflake Documentation | Scheduling Tasks
: SnowPro Advanced: Architect | Study Guide
: Creating Stages
: Loading Data Using Snowpipe
: Using Streams and Tasks for ELT
: [Creating Tasks]
: [Best Practices for Loading Data]
: [Using the Snowpipe REST API]
: [Scheduling Tasks]
NEW QUESTION # 65
An Architect would like to save quarter-end financial results for the previous six years.
Which Snowflake feature can the Architect use to accomplish this?
Answer: A
Explanation:
Explanation
Zero-copy cloning is a Snowflake feature that can be used to save quarter-end financial results for the previous six years. Zero-copy cloning allows creating a copy of a database, schema, table, or view without duplicating the data or metadata. The clone shares the same data files as the original object, but tracks any changes made to the clone or the original separately. Zero-copy cloning can be usedto create snapshots of data at different points in time, such as quarter-end financial results, and preserve them for future analysis or comparison. Zero-copy cloning is fast, efficient, and does not consume any additional storage space unless the data is modified1.
References:
* Zero-Copy Cloning | Snowflake Documentation
NEW QUESTION # 66
An Architect wants to integrate Snowflake with a Git repository that requires authentication. What is the correct sequence of steps to be followed?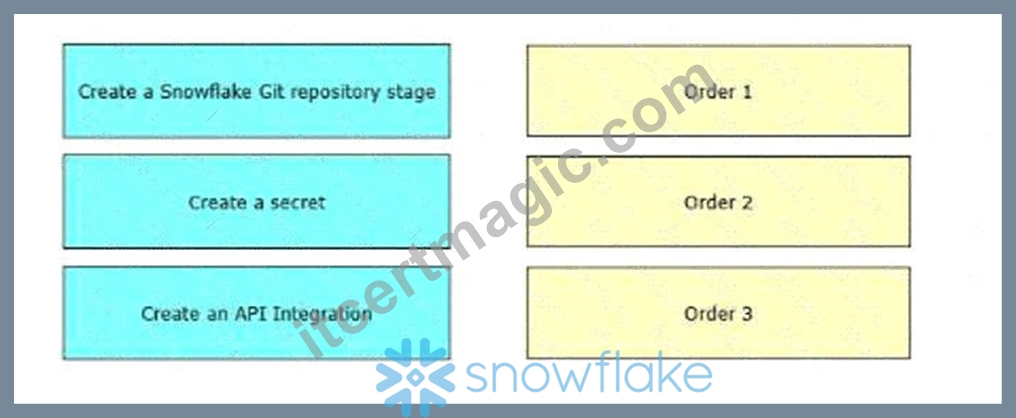
Answer:
Explanation: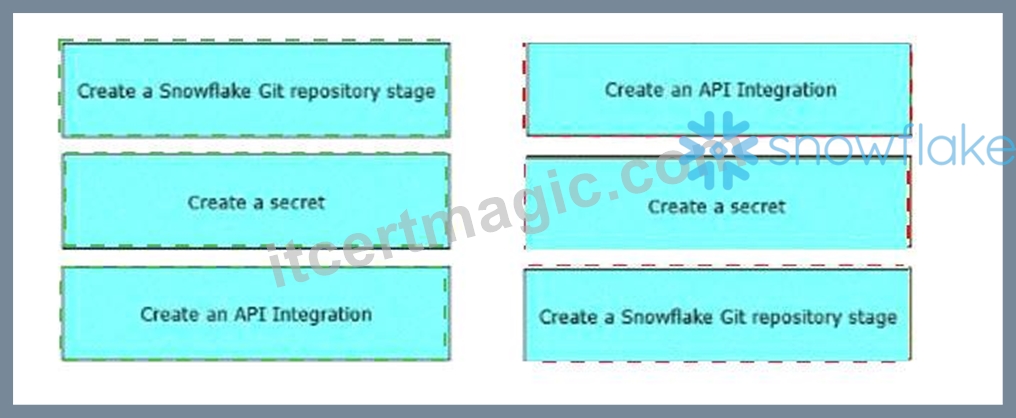
Explanation: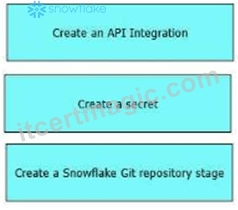
This question tests Snowflake's native Git integration setup pattern, which relies on Snowflake security objects to authenticate outbound access to an external Git provider. The correct sequence begins with creating an API integration because it defines and authorizes the external endpoint(s) Snowflake is allowed to communicate with. In Snowflake, integrations are the governance layer for external connectivity- administrators explicitly allow network destinations and control whether the integration is enabled, which is foundational before any credential object can be used.
Next, the Architect creates a secret to securely store the authentication material required by the Git provider (for example, a token or other supported credential). Secrets are designed for securely managing sensitive values and are referenced by other Snowflake objects without exposing the credential in plain text in SQL or configuration.
Finally, the Architect creates the Snowflake Git repository stage, which is the object that actually references the Git repo location and uses the configured integration and secret to authenticate and interact with the repository. Creating the stage last ensures all required prerequisites (allowed connectivity + stored credentials) exist and can be bound to the stage cleanly, aligning with Snowflake's documented dependency model for external integrations.
NEW QUESTION # 67
......
Reliable ARA-C01 Test Duration: https://www.itcertmagic.com/Snowflake/real-ARA-C01-exam-prep-dumps.html
What's more, part of that ITCertMagic ARA-C01 dumps now are free: https://drive.google.com/open?id=1evCUhutBiZaUBEMYLlg4IuXennqZue4p