2026 Latest TroytecDumps Databricks-Generative-AI-Engineer-Associate PDF Dumps and Databricks-Generative-AI-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1Nxw-ePY5J8NgTfKkWCsRV8cwpYwyuyVi
Our loyal customers give us strong support in the past ten years. Luckily, our Databricks-Generative-AI-Engineer-Associate learning materials never let them down. Our company is developing so fast and healthy. Up to now, we have made many achievements. Also, the Databricks-Generative-AI-Engineer-Associate study guide is always popular in the market. All in all, we will keep up with the development of the society. And we always keep updating our Databricks-Generative-AI-Engineer-Associate Practice Braindumps to the latest for our customers to download. Just buy our Databricks-Generative-AI-Engineer-Associate exam questions and you will find they are really good!
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Reliable Databricks-Generative-AI-Engineer-Associate Dumps Files <<
We are in a constant state of learning new knowledge, but also a process of constantly forgotten, we always learned then forget, how to solve this problem, the answer is to have a good memory method, our Databricks-Generative-AI-Engineer-Associate exam question will do well on this point. Our Databricks-Generative-AI-Engineer-Associate real exam materials have their own unique learning method, abandon the traditional rote learning, adopt diversified memory patterns, such as the combination of text and graphics memory method, to distinguish between the memory of knowledge. Our Databricks-Generative-AI-Engineer-Associate learning reference files are so scientific and reasonable that you can buy them safely.
NEW QUESTION # 17
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email: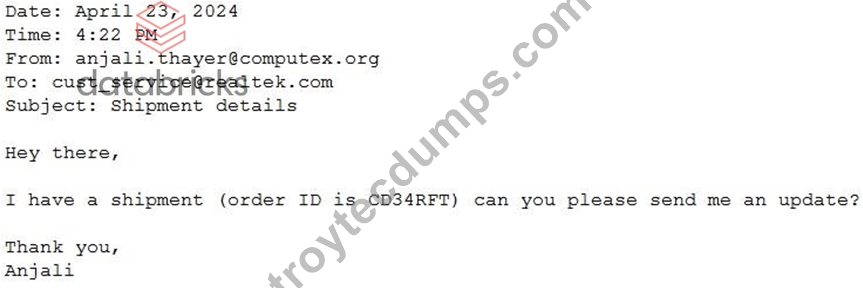
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
Answer: B
Explanation:
* Problem Context: The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM's responses.
* Explanation of Options:
Option A: Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
Option B: Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
Option C: Does not specify that the output should be in JSON format, thus not meeting the requirement.
Option D: While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore, Option B is optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
NEW QUESTION # 18
A Generative AI Engineer is building an LLM to generate article summaries in the form of a type of poem, such as a haiku, given the article content. However, the initial output from the LLM does not match the desired tone or style.
Which approach will NOT improve the LLM's response to achieve the desired response?
Answer: B
Explanation:
The task at hand is to improve the LLM's ability to generate poem-like article summaries with the desired tone and style. Using aneutralizerto normalize the tone and style of the underlying documents (option B) will not help improve the LLM's ability to generate the desired poetic style. Here's why:
* Neutralizing Underlying Documents:A neutralizer aims to reduce or standardize the tone of input data. However, this contradicts the goal, which is to generate text with aspecific tone and style(like haikus). Neutralizing the source documents will strip away the richness of the content, making it harder for the LLM to generate creative, stylistic outputs like poems.
* Why Other Options Improve Results:
* A (Explicit Instructions in the Prompt): Directly instructing the LLM to generate text in a specific tone and style helps align the output with the desired format (e.g., haikus). This is a common and effective technique in prompt engineering.
* C (Few-shot Examples): Providing examples of the desired output format helps the LLM understand the expected tone and structure, making it easier to generate similar outputs.
* D (Fine-tuning the LLM): Fine-tuning the model on a dataset that contains examples of the desired tone and style is a powerful way to improve the model's ability to generate outputs that match the target format.
Therefore, using a neutralizer (option B) isnotan effective method for achieving the goal of generating stylized poetic summaries.
NEW QUESTION # 19
A Generative Al Engineer is tasked with developing a RAG application that will help a small internal group of experts at their company answer specific questions, augmented by an internal knowledge base. They want the best possible quality in the answers, and neither latency nor throughput is a huge concern given that the user group is small and they're willing to wait for the best answer. The topics are sensitive in nature and the data is highly confidential and so, due to regulatory requirements, none of the information is allowed to be transmitted to third parties.
Which model meets all the Generative Al Engineer's needs in this situation?
Answer: C
Explanation:
* Problem Context: The Generative AI Engineer needs a model for a Retrieval-Augmented Generation (RAG) application that provides high-quality answers, where latency and throughput are not major concerns. The key factors are confidentiality and sensitivity of the data, as well as the requirement for all processing to be confined to internal resources without external data transmission.
* Explanation of Options:
Option A: Dolly 1.5B: This model does not typically support RAG applications as it's more focused on image generation tasks.
Option B: OpenAI GPT-4: While GPT-4 is powerful for generating responses, its standard deployment involves cloud-based processing, which could violate the confidentiality requirements due to external data transmission.
Option C: BGE-large: The BGE (Big Green Engine) large model is a suitable choice if it is configured to operate on-premises or within a secure internal environment that meets regulatory requirements. Assuming this setup, BGE-large can provide high-quality answers while ensuring that data is not transmitted to third parties, thus aligning with the project's sensitivity and confidentiality needs.
Option D: Llama2-70B: Similar to GPT-4, unless specifically set up for on-premises use, it generally relies on cloud-based services, which might risk confidential data exposure.
Given the sensitivity and confidentiality concerns, BGE-large is assumed to be configurable for secure internal use, making it the optimal choice for this scenario.
NEW QUESTION # 20
A Generative Al Engineer is using an LLM to classify species of edible mushrooms based on text descriptions of certain features. The model is returning accurate responses in testing and the Generative Al Engineer is confident they have the correct list of possible labels, but the output frequently contains additional reasoning in the answer when the Generative Al Engineer only wants to return the label with no additional text.
Which action should they take to elicit the desired behavior from this LLM?
Answer: A
Explanation:
The LLM classifies mushroom species accurately but includes unwanted reasoning text, and the engineer wants only the label. Let's assess how to control output format effectively.
Option A: Use few shot prompting to instruct the model on expected output format Few-shot prompting provides examples (e.g., input: description, output: label). It can work but requires crafting multiple examples, which is effort-intensive and less direct than a clear instruction.
Databricks Reference: "Few-shot prompting guides LLMs via examples, effective for format control but requires careful design" ("Generative AI Cookbook").
Option B: Use zero shot prompting to instruct the model on expected output format Zero-shot prompting relies on a single instruction (e.g., "Return only the label") without examples. It's simpler than few-shot but may not consistently enforce succinctness if the LLM's default behavior is verbose.
Databricks Reference: "Zero-shot prompting can specify output but may lack precision without examples" ("Building LLM Applications with Databricks").
Option C: Use zero shot chain-of-thought prompting to prevent a verbose output format Chain-of-Thought (CoT) encourages step-by-step reasoning, which increases verbosity-opposite to the desired outcome. This contradicts the goal of label-only output.
Databricks Reference: "CoT prompting enhances reasoning but often results in detailed responses" ("Databricks Generative AI Engineer Guide").
Option D: Use a system prompt to instruct the model to be succinct in its answer A system prompt (e.g., "Respond with only the species label, no additional text") sets a global instruction for the LLM's behavior. It's direct, reusable, and effective for controlling output style across queries.
Databricks Reference: "System prompts define LLM behavior consistently, ideal for enforcing concise outputs" ("Generative AI Cookbook," 2023).
Conclusion: Option D is the most effective and straightforward action, using a system prompt to enforce succinct, label-only responses, aligning with Databricks' best practices for output control.
NEW QUESTION # 21
A Generative AI Engineer is building a compound AI system for an organization. The goal is to automate the processing of incoming customer event reports against a coding system and corporate-guidelines documentation. The system must handle three distinct user-request types: answering questions from guidelines documents, extracting specific event codes from reviewers' notes, and routing ambiguous requests to the appropriate specialized handler. All three capabilities must operate under a single entry point that interprets user intent and delegates accordingly.
Which Agent Brick should serve as the top-level orchestrator in this architecture?
Answer: C
Explanation:
The Multi-Agent Supervisor is designed to coordinate specialized agents and tools behind a unified entry point. It interprets the incoming request, selects suitable capabilities, delegates work, and combines results when necessary. In this scenario, document questions can be handled by a knowledge-retrieval specialist, while event-code extraction can be assigned to a specialized extraction capability. The supervisor provides the coordination needed to select between those tasks and handle requests requiring multiple steps. A Knowledge Assistant's conversational interface does not itself make it the appropriate general-purpose orchestrator.
Adding vector indexes also does not establish specialized extraction and routing behavior. Although option A names the same component, its justification misses the central requirement: coordinated delegation across distinct capabilities. Databricks documentation
NEW QUESTION # 22
......
As we all know that if we get a certificate for the exam, we will have more advantages in the job market. We have Databricks-Generative-AI-Engineer-Associate study guide for you to get the certificate quickly. Besides, we are pass guarantee, if you indeed fail the exam, we will be money back guarantee. Databricks-Generative-AI-Engineer-Associate Study Guide of us obtain many good feedbacks from our customers. Free demo of Databricks-Generative-AI-Engineer-Associate exam dumps are provided by us, you can have a try before you buy them, so that you can know the mode of the Databricks-Generative-AI-Engineer-Associate learning materials.
Valid Databricks-Generative-AI-Engineer-Associate Test Simulator: https://www.troytecdumps.com/Databricks-Generative-AI-Engineer-Associate-troytec-exam-dumps.html
P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by TroytecDumps: https://drive.google.com/open?id=1Nxw-ePY5J8NgTfKkWCsRV8cwpYwyuyVi