
What's more, part of that Actual4dump Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1m9JyUggCpO0Y-fwJAdY_l872nAT8j4-6
Our AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) questions PDF version is great for busy candidates who like to learn on the go with their smartphones or tablets. The AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) dumps PDF format's portability making it ideal for on-the-go studying from any smart device. Studying in PDF format is convenient since it can be printed out and used as a hard copy if you do not have access to a smart device at the moment.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Security and Governance | 18% | - Ensure data encryption
|
| Topic 2: Data Ingestion and Transformation | 34% | - Transform and process data
|
| Topic 3: Data Operations and Support | 22% | - Automate data pipelines
|
| Topic 4: Data Store Management | 26% | - Understand data cataloging
|
>> Latest Data-Engineer-Associate Exam Experience <<
A good deal of researches has been made to figure out how to help different kinds of candidates to get Data-Engineer-Associate certification. We revise and update the Data-Engineer-Associate test torrent according to the changes of the syllabus and the latest developments in theory and practice. We base the Data-Engineer-Associate Certification Training on the test of recent years and the industry trends through rigorous analysis. Therefore, for your convenience, more choices are provided for you, we are pleased to suggest you to choose our Data-Engineer-Associate exam question for your exam.
NEW QUESTION # 224
A data engineer needs to join data from multiple sources to perform a one-time analysis job. The data is stored in Amazon DynamoDB, Amazon RDS, Amazon Redshift, and Amazon S3.
Which solution will meet this requirement MOST cost-effectively?
Answer: C
Explanation:
Amazon Athena Federated Query is a feature that allows you to query data from multiple sources using standard SQL. You can use Athena Federated Query to join data from Amazon DynamoDB, Amazon RDS, Amazon Redshift, and Amazon S3, as well as other data sources such as MongoDB, Apache HBase, and Apache Kafka1. Athena Federated Query is a serverless and interactive service, meaning you do not need to provision or manage any infrastructure, and you only pay for the amount of data scanned by your queries. Athena Federated Query is the most cost-effective solution for performing a one-time analysis job on data from multiple sources, as it eliminates the need to copy or move data, and allows you to query data directly from the source.
The other options are not as cost-effective as Athena Federated Query, as they involve additional steps or costs. Option A requires you to provision and pay for an Amazon EMR cluster, which can be expensive and time-consuming for a one-time job. Option B requires you to copy or move data from DynamoDB, RDS, and Redshift to S3, which can incur additional costs for data transfer and storage, and also introduce latency and complexity. Option D requires you to have an existing Redshift cluster, which can be costly and may not be necessary for a one-time job. Option D also does not support querying data from RDS directly, so you would need to use Redshift Federated Query to access RDS data, which adds another layer of complexity2. Reference:
Amazon Athena Federated Query
Redshift Spectrum vs Federated Query
NEW QUESTION # 225
A manufacturing company wants to collect data from sensors. A data engineer needs to implement a solution that ingests sensor data in near real time.
The solution must store the data to a persistent data store. The solution must store the data in nested JSON format. The company must have the ability to query from the data store with a latency of less than 10 milliseconds.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: C
NEW QUESTION # 226
A company needs to build a data lake in AWS. The company must provide row-level data access and column- level data access to specific teams. The teams will access the data by using Amazon Athena, Amazon Redshift Spectrum, and Apache Hive from Amazon EMR.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: A
Explanation:
Option D is the best solution to meet the requirements with the least operational overhead because AWS Lake Formation is a fully managed service that simplifies the process of building, securing, and managing data lakes. AWS Lake Formation allows you to define granular data access policies at the row and column level for different users and groups. AWS Lake Formation also integrates with Amazon Athena, Amazon Redshift Spectrum, and Apache Hive on Amazon EMR, enabling these services to access the data in the data lake through AWS Lake Formation.
Option A is not a good solution because S3 access policies cannot restrict data access by rows and columns.
S3 access policies are based on the identity and permissions of the requester, the bucket and object ownership, and the object prefix and tags. S3 access policies cannot enforce fine-grained data access control at the row and column level.
Option B is not a good solution because it involves using Apache Ranger and Apache Pig, which are not fully managed services and require additional configuration and maintenance. Apache Ranger is a framework that provides centralized security administration for data stored in Hadoop clusters, such as Amazon EMR.
Apache Ranger can enforce row-level and column-level access policies for Apache Hive tables. However, Apache Ranger is not a native AWS service and requires manual installation and configuration on Amazon EMR clusters. Apache Pig is a platform that allows you to analyze large data sets using a high-level scripting language called Pig Latin. Apache Pig can access data stored in Amazon S3 and process it using Apache Hive. However, Apache Pig is not a native AWS service and requires manual installation and configuration on Amazon EMR clusters.
Option C is not a good solution because Amazon Redshift is not a suitable service for data lake storage.
Amazon Redshift is a fully managed data warehouse service that allows you to run complex analytical queries using standard SQL. Amazon Redshift can enforce row-level and column-level access policies for different users and groups. However, Amazon Redshift is not designed to store and process large volumes of unstructured or semi-structured data, which are typical characteristics of data lakes. Amazon Redshift is also more expensive and less scalable than Amazon S3 for data lake storage.
AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide
What Is AWS Lake Formation? - AWS Lake Formation
Using AWS Lake Formation with Amazon Athena - AWS Lake Formation
Using AWS Lake Formation with Amazon Redshift Spectrum - AWS Lake Formation Using AWS Lake Formation with Apache Hive on Amazon EMR - AWS Lake Formation Using Bucket Policies and User Policies - Amazon Simple Storage Service Apache Ranger Apache Pig What Is Amazon Redshift? - Amazon Redshift
NEW QUESTION # 227
A data engineer maintains a materialized view that is based on an Amazon Redshift database. The view has a column named load_date that stores the date when each row was loaded.
The data engineer needs to reclaim database storage space by deleting all the rows from the materialized view.
Which command will reclaim the MOST database storage space?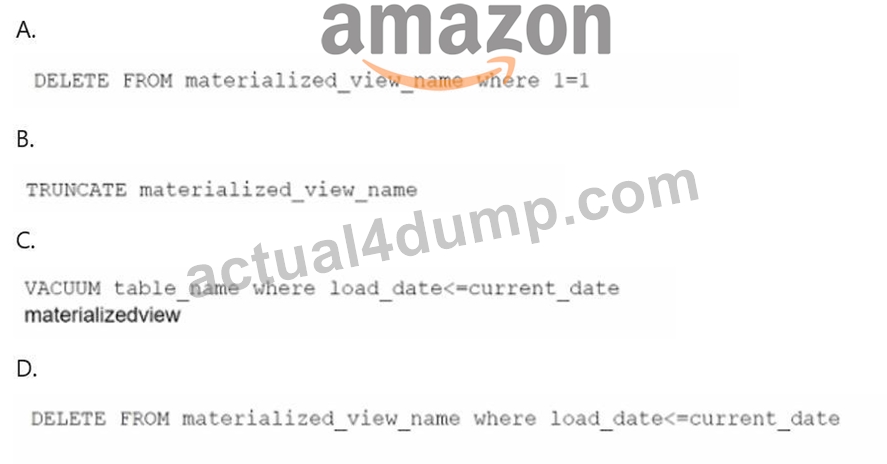
Answer: B
Explanation:
To reclaim the most storage space from a materialized view in Amazon Redshift, you should use a DELETE operation that removes all rows from the view. The most efficient way to remove all rows is to use a condition that always evaluates to true, such as 1=1. This will delete all rows without needing to evaluate each row individually based on specific column values like load_date.
Option A: DELETE FROM materialized_view_name WHERE 1=1;This statement will delete all rows in the materialized view and free up the space. Since materialized views in Redshift store precomputed data, performing a DELETE operation will remove all stored rows.
Other options either involve inappropriate SQL statements (e.g., VACUUM in option C is used for reclaiming storage space in tables, not materialized views), or they don't remove data effectively in the context of a materialized view (e.g., TRUNCATE cannot be used directly on a materialized view).
References:
Amazon Redshift Materialized Views Documentation
Deleting Data from Redshift
NEW QUESTION # 228
A retail company uses Amazon Aurora PostgreSQL to process and store live transactional dat a. The company uses an Amazon Redshift cluster for a data warehouse.
An extract, transform, and load (ETL) job runs every morning to update the Redshift cluster with new data from the PostgreSQL database. The company has grown rapidly and needs to cost optimize the Redshift cluster.
A data engineer needs to create a solution to archive historical data. The data engineer must be able to run analytics queries that effectively combine data from live transactional data in PostgreSQL, current data in Redshift, and archived historical data. The solution must keep only the most recent 15 months of data in Amazon Redshift to reduce costs.
Which combination of steps will meet these requirements? (Select TWO.)
Answer: D,E
Explanation:
The goal is to archive historical data from an Amazon Redshift data warehouse while combining live transactional data from Amazon Aurora PostgreSQL with current and historical data in a cost-efficient manner. The company wants to keep only the last 15 months of data in Redshift to reduce costs.
Option A: "Configure the Amazon Redshift Federated Query feature to query live transactional data that is in the PostgreSQL database." Redshift Federated Query allows querying live transactional data directly from Aurora PostgreSQL without having to move it into Redshift, thereby enabling seamless integration of the current data in Redshift and live data in PostgreSQL. This is a cost-effective approach, as it avoids unnecessary data duplication.
Option C: "Schedule a monthly job to copy data that is older than 15 months to Amazon S3 by using the UNLOAD command. Delete the old data from the Redshift cluster. Configure Amazon Redshift Spectrum to access historical data in Amazon S3." This option uses Amazon Redshift Spectrum, which enables Redshift to query data directly in S3 without moving it into Redshift. By unloading older data (older than 15 months) to S3, and then using Spectrum to access it, this approach reduces storage costs significantly while still allowing the data to be queried when necessary.
Option B (Redshift Spectrum for live PostgreSQL data) is not applicable, as Redshift Spectrum is intended for querying data in Amazon S3, not live transactional data in Aurora.
Option D (S3 Glacier Flexible Retrieval) is not suitable because Glacier is designed for long-term archival storage with infrequent access, and querying data in Glacier for analytics purposes would incur higher retrieval times and costs.
Option E (materialized views) would not meet the need to archive data or combine it from multiple sources; it is best suited for combining frequently accessed data already in Redshift.
Reference:
Amazon Redshift Federated Query
Amazon Redshift Spectrum Documentation
Amazon Redshift UNLOAD Command
NEW QUESTION # 229
......
Like the Web-based AWS Certified Data Engineer - Associate (DEA-C01) practice exam, the Desktop Data-Engineer-Associate practice test software of Actual4dump provides its valuable customers with Data-Engineer-Associate test questions which are very similar to the actual AWS Certified Data Engineer - Associate (DEA-C01) exam questions. There is no hustle. The AWS Certified Data Engineer - Associate (DEA-C01) Data-Engineer-Associate Practice Test material is updated and created after feedback from more than 90,000 professionals around the globe. A free demo of any AWS Certified Data Engineer - Associate (DEA-C01) exam dumps format will be provided by Actual4dump to the one who wants to assess before purchasing.
Data-Engineer-Associate Valid Exam Sims: https://www.actual4dump.com/Amazon/Data-Engineer-Associate-actualtests-dumps.html
What's more, part of that Actual4dump Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1m9JyUggCpO0Y-fwJAdY_l872nAT8j4-6