When you grasp the key points to attend the DP-750 exam, nothing will be difficult for you anymore. Our professional experts are good at compiling the DP-750 training guide with the most important information. They have been in this career for over ten years, and they know every detail about the DP-750 Exam no matter on the content but also on the displays. Believe in our DP-750 practice braindumps, and your success is 100% guaranteed!
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Prepare and process data | 30–35% | - Ingest and transform data
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
>> Examcollection Microsoft DP-750 Free Dumps <<
We believe that our test-orientated high-quality DP-750 exam questions would be the best choice for you, we sincerely hope all of our candidates can pass DP-750 exam, and enjoy the tremendous benefits of our DP-750 prep guide. The pass rate of our DP-750 exam questions is as high as 99% to 100%. Helping candidates to pass the DP-750 Exam has always been a virtue in our company’s culture, and you can connect with us through email at the process of purchasing and using, we would reply you as fast as we can.
NEW QUESTION # 17
You have an Azure Databricks workspace.
You have an Apache Spark Structured Streaming job named Job! that processes data continuously and fails periodically due to transient errors You need to ensure that Job! meets the following requirements
* Resumes processing from the point that Job1 failed
* Minimizes how long it takes to restart Job!
* Minimizes the costs to restart Job!
What should you do?
Answer: C
Explanation:
The correct answer is B - implement checkpointing.
A checkpoint is a durable record of the streaming job's progress written to ADLS Gen2 or DBFS after each successfully committed micro-batch. When the job restarts after a transient failure, it reads the checkpoint to find the last committed offset and resumes from that exact point - no data is reprocessed, no data is lost.
This satisfies all three requirements directly: checkpointing enables resumption from the failure point (not from the beginning), restart is fast because there's no replay overhead, and costs are minimised because no compute is wasted reprocessing records already handled.
Option A (decrease retry interval) makes the job retry sooner but doesn't control where it resumes from.
Option C (alert and manual restart) adds human latency and doesn't prevent reprocessing without a checkpoint. Option D (increase minimum nodes) reduces the likelihood of resource-related failures but increases cost and doesn't address the recovery behaviour itself.
Reference: https://learn.microsoft.com/en-us/azure/databricks/structured-streaming/query-recovery
NEW QUESTION # 18
What improves join performance for small lookup tables?
Answer: D
Explanation:
Broadcast joins send the small table to all worker nodes, avoiding expensive shuffling. This significantly improves performance. Shuffle and sort merge joins are heavier. Cartesian joins are inefficient and generally avoided.
NEW QUESTION # 19
Which SCD type should you use to support the planned data modeling changes? To answer, drag the appropriate types to the correct issues. Each type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.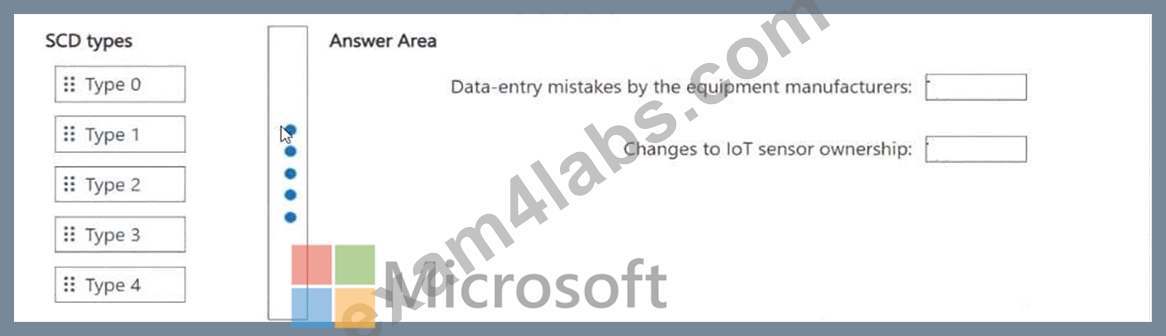
Answer:
Explanation: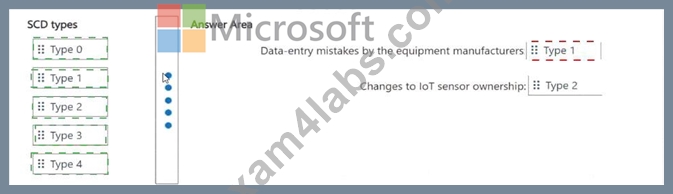
Explanation:
The correct mapping is SCD Type 1 for equipment metadata and SCD Type 2 for IoT sensor ownership history.
SCD Type 1 overwrites the existing record whenever an attribute changes - no history is kept. Contoso's requirement for equipment metadata (name, manufacturer, model, commissioning date) states 'historical values are NOT required,' which is the textbook definition of Type 1. A MERGE INTO with WHEN MATCHED THEN UPDATE handles this cleanly in Delta Lake.
SCD Type 2 creates a new row for each change, preserving the full history through effective-date or version columns. Contoso requires that 'analysts must track the full history of ownership' as sensors change hands over time - that full audit trail is only possible with Type 2. Type 3 (keeping just the previous value in an extra column) would lose earlier ownership records, so it doesn't satisfy the 'full history' requirement.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/merge
NEW QUESTION # 20
You have an Azure Databricks job named Job1 that contains an ingestion task named Task1 and transformation task named Task2. You need to ensure that if Task1 fails, the task retries automatically, and Task2 is prevented from running How should you configure Job1? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.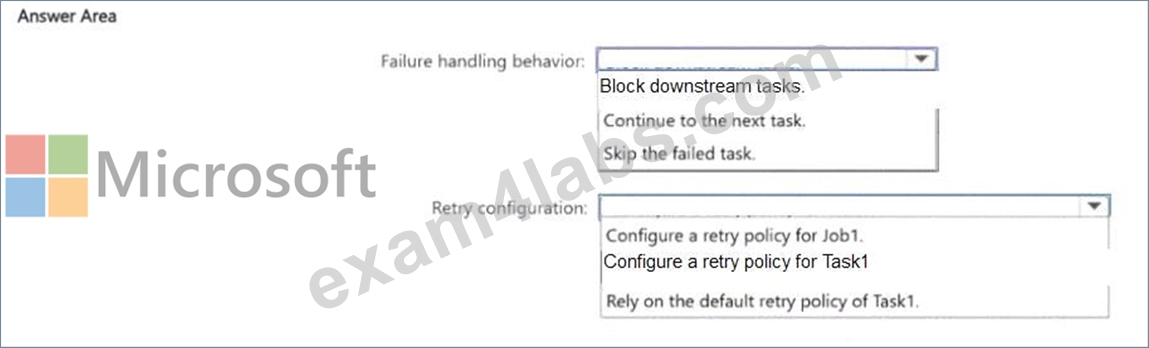
Answer:
Explanation: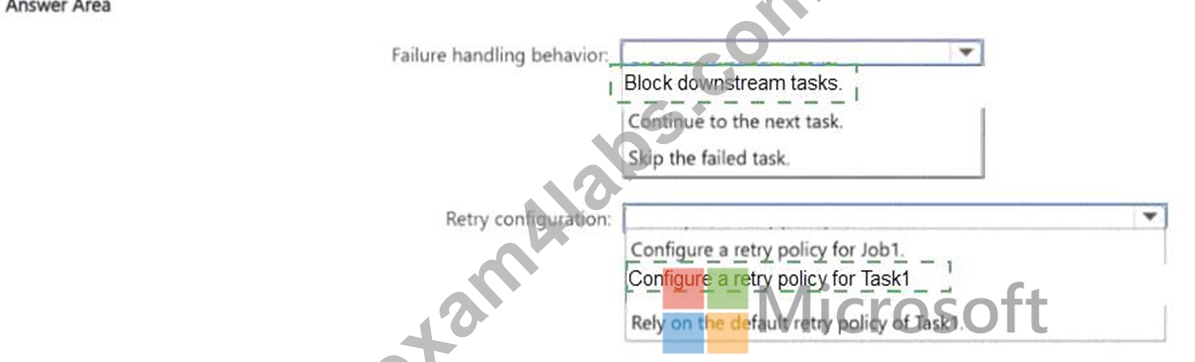
Explanation:
Two task-level settings solve this:
Task1 retry policy: configure Task1 with a maximum number of retries and a retry interval. When Task1 fails, Lakeflow Jobs automatically re-runs it up to the retry limit without any manual intervention. This handles transient infrastructure failures transparently.
Task2 run condition set to 'All succeeded' with Task1 as its dependency: this means Task2 only starts when Task1 has succeeded. If Task1 fails and exhausts all retries, Task2 remains blocked - it never runs on data from a failed upstream ingestion. The dependency is declared in Task2's 'Depends on' setting in the job configuration.
These two settings are independent and composable. Task1's retry policy gives it multiple chances to recover.
Task2's dependency and run condition ensure the downstream transformation only runs on clean, successfully ingested data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#task-retries
NEW QUESTION # 21
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes numerical data to a table named Table1 by using a data quality validation rule named rule1.
You need to modify rule1 to meet the following requirements:
Ensure that amount is always greater than 0.
Prevent an update to Table1 from being committed when data that violates rule1 is detected.
Which statement should you execute?
Answer: C
Explanation:
The correct answer is C - @dlt.expect_or_fail.
Lakeflow Spark Declarative Pipelines (SDP) offers three expectation decorators, each with a different violation response:
@dlt.expect - logs the violation as a metric but writes all records, including bad ones, to the table. Suitable for monitoring only.
@dlt.expect_or_drop - drops violating records and continues the pipeline. The table receives only clean rows, but the pipeline update commits successfully.
@dlt.expect_or_fail - fails the entire pipeline update when a violation is detected. The table update is never committed. This is the correct choice when data integrity is non-negotiable: 'Prevent an update to Table1 from being committed when data that violates rule1 is detected.'
@dlt.expect_all_or_drop takes a dictionary of rules and drops violating rows but still commits - it doesn't halt the pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
NEW QUESTION # 22
......
Taking practice exams teaches you time management so you can pass the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam. Exam4Labs's DP-750 practice exam makes an image of a real-based examination which is helpful for you to not feel much pressure when you are giving the final examination. You can give unlimited practice tests and improve yourself daily to achieve your desired destination.
DP-750 Valid Braindumps: https://www.exam4labs.com/DP-750-practice-torrent.html