BONUS!!! Download part of ExamTorrent Databricks-Certified-Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=1o53jhnzy95NfkdtwsLKaNz9MuIgt73l0
Generally speaking, passing the exam means a lot, if you pass the exam, your efforts and the money won’t be wasted. Databricks-Certified-Data-Engineer-Associate test materials can help you pass your exam just one time, otherwise we will give you full refund. Besides, Databricks-Certified-Data-Engineer-Associate training materials are high-quality, and we have received many good feedbacks from candidates. We also pass guarantee and money back guarantee if you fail to pass the exam. You can enjoy free update for one year for Databricks-Certified-Data-Engineer-Associate Exam Materials, and the update version will be sent to your email automatically.
| Section | Objectives |
|---|---|
| Productionizing Data Pipelines | - Scheduling and monitoring jobs - Pipeline deployment and operationalization - Databricks Workflows / Jobs orchestration |
| Data Ingestion and ELT Development | - ETL patterns and transformations - Data ingestion using Spark SQL and PySpark - Handling structured and semi-structured data |
| Data Processing and Transformations | - Apache Spark SQL operations (joins, aggregations, filtering) - User-defined functions (UDFs) - PySpark DataFrame transformations - Delta Lake fundamentals (tables, transactions, optimization) |
| Databricks Lakehouse Platform Fundamentals | - Workspace, architecture, and core platform concepts - Clusters, notebooks, and basic Databricks environment usage |
| Data Governance and Quality | - Unity Catalog basics - Data access control and governance - Data quality concepts and management |
>> Databricks-Certified-Data-Engineer-Associate Online Version <<
ExamTorrent examines it regularly for new updates so that you always get new Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) practice questions. Since it is a printable format, you can do a paper study. The Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) PDF Dumps document is accessible from every location at any time. This Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) software has a simple-to-use interface. By using the Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) practice exam software, you can evaluate your mistakes at the end of every take and overcome them. Our software helps you to get familiar with the format of the original Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) test.
NEW QUESTION # 236
Which of the following must be specified when creating a new Delta Live Tables pipeline?
Answer: C
Explanation:
Option E is the correct answer because it is the only mandatory requirement when creating a new Delta Live Tables pipeline. A pipeline is a data processing workflow that contains materialized views and streaming tables declared in Python or SQL source files. Delta Live Tables infers the dependencies between these tables and ensures updates occur in the correct order. To create a pipeline, you need to specify at least one notebook library to be executed, which contains the Delta Live Tables syntax. You can also specify multiple libraries of different languages within your pipeline. The other options are optional or not applicable for creating a pipeline. Option A is not required, but you can optionally provide a key-value pair configuration to customize the pipeline settings, such as the storage location, the target schema, the notifications, and the pipeline mode. Option B is not applicable, as the DBU/hour cost is determined by the cluster configuration, not the pipeline creation. Option C is not required, but you can optionally specify a storage location for the output data from the pipeline. If you leave it empty, the system uses a default location. Option D is not required, but you can optionally specify a location of a target database for the written data, either in the Hive metastore or the Unity Catalog.
Tutorial: Run your first Delta Live Tables pipeline, What is Delta Live Tables?, Create a pipeline, Pipeline configuration.
NEW QUESTION # 237
A data engineer needs to apply custom logic to identify employees with more than 5 years of experience in array column employees in table stores. The custom logic should create a new column exp_employees that is an array of all of the employees with more than 5 years of experience for each row. In order to apply this custom logic at scale, the data engineer wants to use the FILTER higher-order function.
Which of the following code blocks successfully completes this task?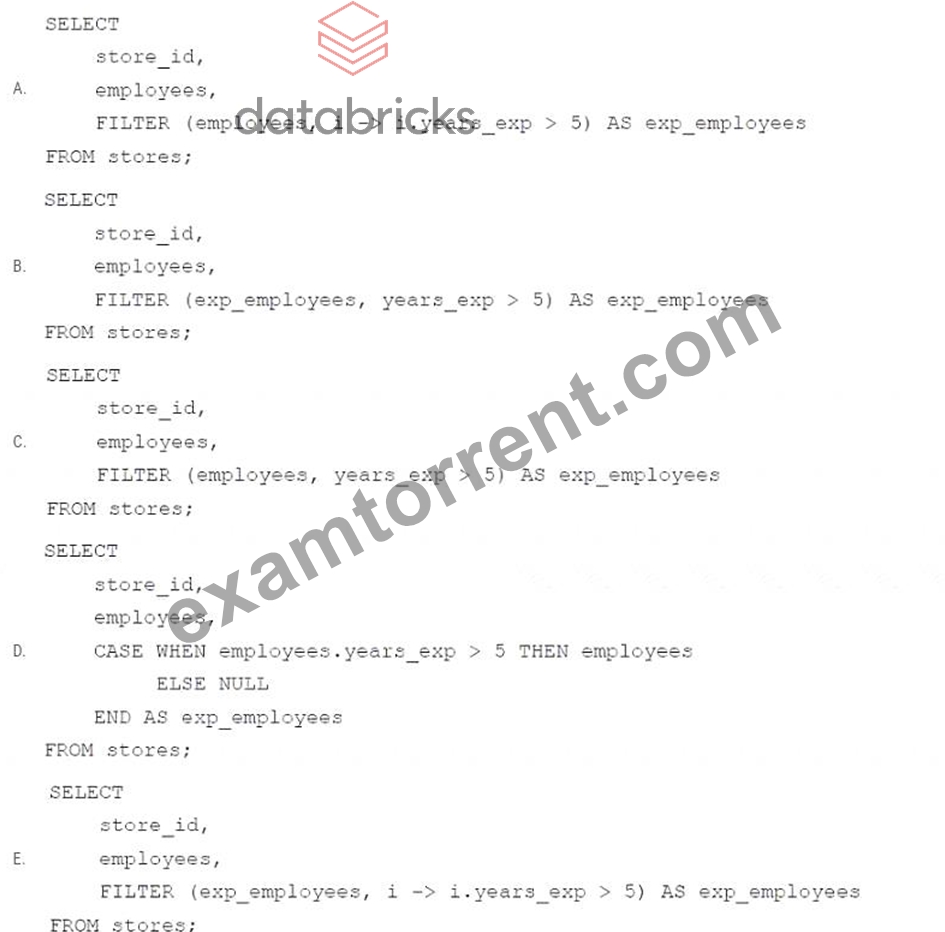
Answer: D
Explanation:
Option A is the correct answer because it uses the FILTER higher-order function correctly to filter out employees with more than 5 years of experience from the array column "employees". It applies a lambda function i -> i.years_exp > 5 that checks if the years of experience of each employee in the array is greater than 5. If this condition is met, the employee is included in the new array column "exp_employees".
References: The use of higher-order functions like FILTER can be referenced from Databricks documentation on Higher-Order Functions.
NEW QUESTION # 238
Which single Databricks CLI command deploys local bundle assets to the target workspace specified in the configuration file?
Answer: D
Explanation:
databricks bundle deploy deploys the local bundle files and resources to the target workspace defined in the bundle configuration.
NEW QUESTION # 239
Which of the following SQL keywords can be used to convert a table from a long format to a wide format?
Answer: E
Explanation:
The SQL keyword that can be used to convert a table from a long format to a wide format is PIVOT. The PIVOT clause is used to rotate the rows of a table into columns of a new table1. The PIVOT clause can aggregate the values of a column based on the distinct values of another column, and use those values as the column names of the new table1. The PIVOT clause can be useful for transforming data from a long format, where each row represents an observation with multiple attributes, to a wide format, where each row represents an observation with a single attribute and multiple values2. For example, the PIVOT clause can be used to convert a table that contains the sales of different products by different regions into a table that contains the sales of each product by each region as separate columns1.
The other options are not suitable for converting a table from a long format to a wide format. CONVERT is a function that can be used to change the data type of an expression3. WHERE is a clause that can be used to filter the rows of a table based on a condition4. TRANSFORM is a keyword that can be used to apply a user- defined function to a group of rows in a table5. SUM is a function that can be used to calculate the total of a numeric column.
1: PIVOT | Databricks on AWS
2: Reshaping Data - Long vs Wide Format | Databricks on AWS
3: CONVERT | Databricks on AWS
4: WHERE | Databricks on AWS
5: TRANSFORM | Databricks on AWS
[SUM | Databricks on AWS]
NEW QUESTION # 240
A data engineer needs to provide access to a group named manufacturing-team. The team needs privileges to create tables in the quality schema.
Which set of SQL commands will grant a group named manufacturing-team to create tables in a schema named production with the parent catalog named manufacturing with the least privileges?
Answer: A
Explanation:
To create a table within a schema, a principal must have CREATE TABLE on the schema, USE SCHEMA on that schema, and USE CATALOG on the parent catalog. This combination ensures the group has just enough privileges to create objects in that schema without excessive permissions like CREATE SCHEMA or CREATE CATALOG.
Reference Source: Databricks Unity Catalog Privilege Model - "Privileges Required to Create a Table."
NEW QUESTION # 241
......
Our Databricks-Certified-Data-Engineer-Associate exam preparation materials have a higher pass rate than products in the same industry. If you want to pass Databricks-Certified-Data-Engineer-Associate certification, then it is necessary to choose a product with a high pass rate. Our Databricks-Certified-Data-Engineer-Associate study materials guarantee the pass rate from professional knowledge, services, and flexible plan settings. The 99% pass rate is the proud result of our Databricks-Certified-Data-Engineer-Associate Study Materials. I believe that pass rate is also a big criterion for your choice of products, because your ultimate goal is to obtain Databricks-Certified-Data-Engineer-Associate certification.
Databricks-Certified-Data-Engineer-Associate Valid Vce Dumps: https://www.examtorrent.com/Databricks-Certified-Data-Engineer-Associate-valid-vce-dumps.html
2026 Latest ExamTorrent Databricks-Certified-Data-Engineer-Associate PDF Dumps and Databricks-Certified-Data-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1o53jhnzy95NfkdtwsLKaNz9MuIgt73l0