BONUS!!! Download part of RealValidExam AI-300 dumps for free: https://drive.google.com/open?id=1gsFpPzMBWQdOYl9sQl1AEJIQZLB4prJM
With AI-300 practice materials, you don't need to spend a lot of time and effort on reviewing and preparing. For everyone, time is precious. Office workers and mothers are very busy at work and home; students may have studies or other things. Using AI-300 Guide questions, you only need to spend a small amount of time to master the core key knowledge, pass the AI-300 exam, and get a certificate.
| Section | Weight | Objectives |
|---|---|---|
| Design and implement an MLOps infrastructure | 15–20% | - Implement infrastructure as code for Machine Learning
|
| Implement generative AI quality assurance and observability | 10–15% | - Evaluate and test generative AI applications
|
| Implement machine learning model lifecycle and operations | 25–30% | - Orchestrate model training and experimentation
|
| Optimize generative AI systems and model performance | 15–20% | - Improve efficiency and cost-effectiveness
|
| Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
>> Latest AI-300 Dumps Questions <<
Facts proved that if you do not have the certification, you will be washed out by the society. So it is very necessary for you to try your best to get the AI-300 certification in a short time. If you are determined to get the certification, our AI-300 question torrent is willing to give you a hand; because the study materials from our company will be the best study tool for you to get the certification. Now I am going to introduce our AI-300 Exam Question to you in detail, please read our introduction carefully, we can make sure that you will benefit a lot from it. If you are interest in it, you can buy it right now.
NEW QUESTION # 40
You are a data scientist working for a hotel booking website company. You use the Azure Machine Learning service to train a model that identifies fraudulent transactions.
You must deploy the model to an Azure Machine Learning online endpoint by using the Azure Machine Learning Python SDK v2. The deployed model must return real-time predictions of fraud based on transaction data input.
You need to create the script that is specified as the scoring_script parameter for the CodeConfiguration class used to deploy the model.
What should the entry script do?
Answer: D
Explanation:
The entry script (scoring script) for an Azure Machine Learning online endpoint must initialize the model when the container starts and process incoming transaction data to return real-time fraud predictions.
init() function: Runs once when the container is initialized. It must locate and load the trained model into memory (typically using a global variable) from the path specified by the AZUREML_MODEL_DIR environment variable.
run(data) function: Executes every time the endpoint receives a real-time HTTP request. It accepts the raw transaction payload, deserializes it, processes the features, passes them to the loaded model for prediction, and returns a JSON-serializable response.
Reference:
https://docs.azure.cn/en-us/machine-learning/how-to-deploy-online-endpoints?view=azureml-api-2
NEW QUESTION # 41
A data science team plans to evaluate multiple hyperparameter values automatically while training a model in Azure Machine Learning.
The tuning process must run multiple training trials without manually modifying the training script for each run.
You need to automate hyperparameter tuning for the training job.
What should you do?
Answer: C
NEW QUESTION # 42
A team is experimenting with traditional models for a classification workflow in Azure Machine Learning.
The team requires a consistent way to manage assets that are created during experimentation.
You need to ensure that artifacts can be reused and governed across projects.
Which asset should you register?
Answer: C
Explanation:
In an Azure Machine Learning classification workflow, you should register Models.
Registration creates a versioned asset in your workspace or a centralized registry, which is essential for ensuring that artifacts are reusable, governed, and trackable across different projects and environments.
Key Assets for Reuse and Governance
To maintain a consistent and governed workflow, you should focus on registering these specific assets:
Models: The primary artifact. Registering a model allows you to track its lineage (which experiment created it), version it, and deploy it consistently across environments.
Components: These are self-contained pieces of code that perform specific steps in a pipeline (e.g., data cleaning, training). Registering them allows different teams to reuse the same
"traditional" classification logic without rewriting code.
Environments: Encapsulates the software dependencies (Python packages, Docker images) required for your model to run. Registering these ensures reproducibility across different compute targets.
Data Assets: Registering your training and testing datasets as versioned assets ensures that you can always audit exactly what data was used to train a specific model version.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/concept-azure-machine-learning-v2
NEW QUESTION # 43
Drag and Drop Question
You have a Microsoft Foundry project with a connected Azure OpenAI Service model.
You have a set of text files stored locally on your computer.
You must set up a flow that will generate responses based on the content of your local files.
You need to implement a solution.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.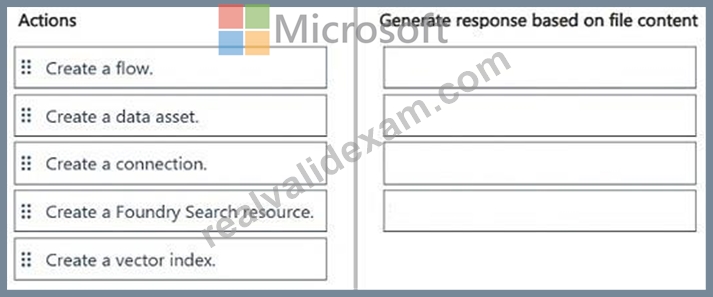
Answer:
Explanation: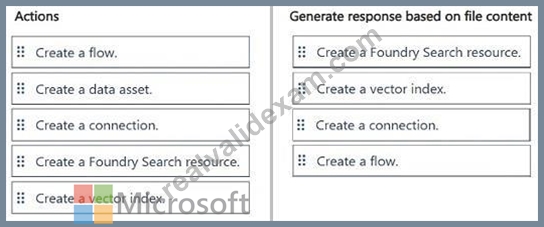
NEW QUESTION # 44
A team develops multiple AI applications in Microsoft Foundry that rely on shared prompt templates.
The team requires a centralized way to track, version, and reuse prompt content across projects.
You need to recommend a solution to track and reuse prompt content.
Which approach should you recommend?
Answer: B
Explanation:
A Git repository provides all three capabilities required: version history for every change with author attribution and timestamp, branching for experimentation, tagging for stable releases, and a single source of truth accessible to all projects via clone or submodule reference. Azure ML datasets (option B) are designed for training data, not text configuration artifacts, and lack per-line diff tracking and review workflows.
Embedding prompts in application configuration files (option C) scatters prompt content across multiple applications with no unified view, no shared versioning, and no cross-project reuse. Unstructured Blob Storage with folder organization (option D) provides no version history, no diff tracking, no review workflow, and no native tooling for comparing prompt variants. Git is the definitive answer for centralized tracking, versioning, and reuse of prompt content across Microsoft Foundry projects.
Microsoft Learn Reference Topic: Prompt engineering and version control - Managing prompts in AI applications with Git
NEW QUESTION # 45
......
RealValidExam is the leading position in this field and famous for high pass rate of the AI-300 learning guide. If you are headache about your qualification exams, our AI-300 learning guide materials will be a great savior for you. Now it is your opportunity that we provide the best valid and professional AI-300 Study Guide materials which have 100% pass rate. If you really want to clear exam and gain success one time, choosing us will be the wise thing for you. If you hesitate about us please pay attention on below about our satisfying service and high-quality AI-300 guide torrent.
Valid AI-300 Study Guide: https://www.realvalidexam.com/AI-300-real-exam-dumps.html
DOWNLOAD the newest RealValidExam AI-300 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1gsFpPzMBWQdOYl9sQl1AEJIQZLB4prJM